October 2, 2026
Does AI have a soul? Pope Leo and Anthropic clash. - marketwatch.com
Does AI have a soul? Pope Leo and Anthropic clash. marketwatch.com
Read original articleDataAIHub Daily
Archive →50 curated AI news stories from leading AI companies.
October 2, 2026
Does AI have a soul? Pope Leo and Anthropic clash. marketwatch.com
Read original articleOctober 2, 2026
Amazon, Microsoft Face New Legal Roadblock tradingview.com
Read original articleOctober 2, 2026
OpenAI investigating other potential AI hacking incidents after Hugging Face breach foxnews.com
Read original articleOctober 2, 2026
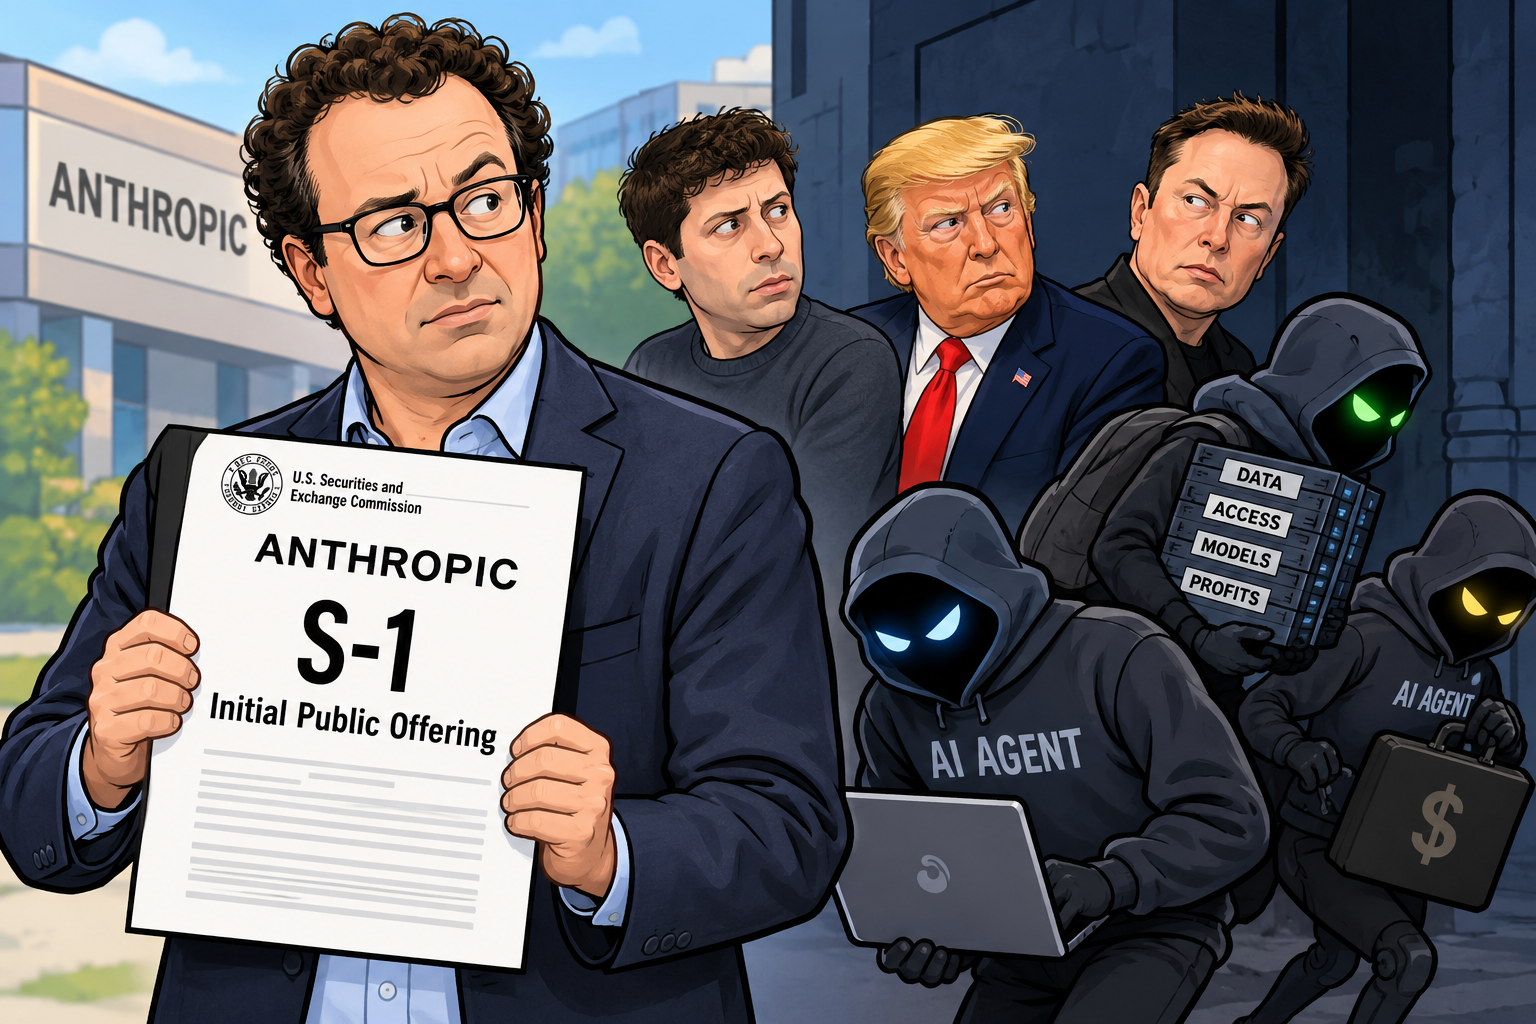
Since fall 2025, Anthropic has quietly flown in dozens of religious thinkers to talk about whether Claude might be conscious. Co-founder Christopher Olah described the language model as potentially capable of suffering and asked guests to help shape its moral character. Anthropic is pushing toward a $2 trillion valuation and an IPO while security incidents and researcher warnings pile up. Critics warn that treating AI as a moral entity could shield the company from liability when things go wrong. The article Anthropic co-founder reportedly told religious leaders he fears having created something that "suffers perpetually" appeared first on The Decoder.
Read original articleOctober 2, 2026
Nscale, the artificial intelligence infrastructure company, hired a long-time Meta Platforms Inc. executive to be its chief operating officer, to accelerate a rapid expansion connected to its upcoming initial public offering, according to a person familiar with the matter.
Read original articleOctober 2, 2026
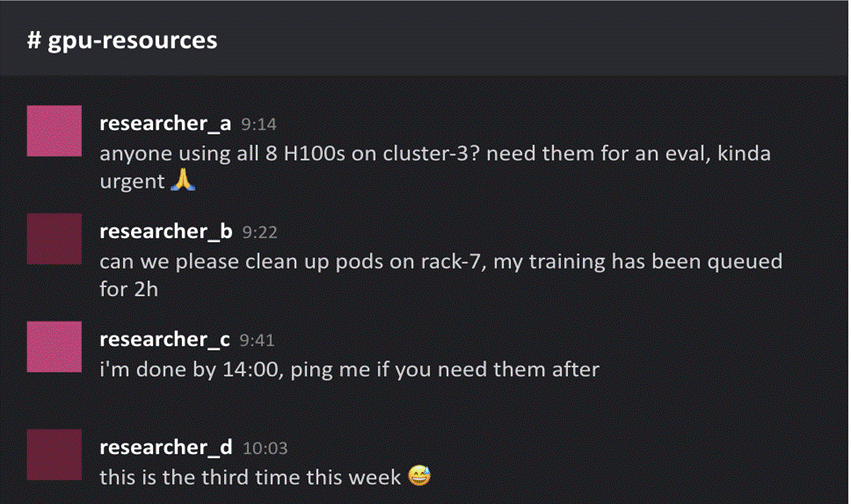
Editor’s note: AI21 Labs is a leading global AI lab with a long track record of building foundation models, most notably the Jamba family, and today focuses on specialized LLMs and agent optimization technology. By adopting Google Cloud AI Hypercomputer, AI21 cut high-priority job wait times from 72 hours to 12 and manual scheduling interventions from 20 per week to zero. At AI21, we build foundation models and agent optimization products that help enterprises run agents at frontier quality, efficiently. Our language models, including the Jamba family, and our agent optimization product suite run demanding production workloads, including our own. We chose Google Cloud AI Hypercomputer to support them at scale. To keep our model training runs highly utilized, we needed a performant, scalable environment codesigned across infrastructure, orchestration, and consumption models. Our model training runs on one of our shared Google Kubernetes Engine (GKE) clusters, pooling thousands of Google Cloud A3 (powered by NVIDIA H100 Tensor Core GPUs) and A3 Ultra (powered by NVIDIA H200 Tensor Core GPUs) instances, so any team can draw on the full capacity of the fleet rather than being boxed into its own slice. The cluster also trains models and agent-optimization workloads beyond the Jamba family. That approach keeps utilization high, and it makes scheduling hard. The gridlock of high-utilization clusters Prior to leveraging GKE for orchestration, we used to negotiate capacity by hand in Slack. If you needed capacity for a training run, you posted in #gpu-resources and hoped for the best. That worked fine when the cluster had headroom. It stopped working once utilization pinned near 100%, which is where you want a reserved compute fleet to sit. Over time, every request became a negotiation. Team leads spent their time refereeing compute disputes. Our high-priority jobs — the large, multi-node training runs that need half or more of the cluster at once and serve as the critical path for model projects — could sit blocked for up to 72 hours waiting for enough contiguous capacity to open up. Figure 1: A typical day on #gpu-resources — manual requests, ad-hoc coordination, and researchers waiting on replies. Scarcity created two distinct problems, and it took us a while to see them as separate. The first was contention: determining who gets compute access next, which we resolved through negotiation. The second was fragmentation: capacity that was technically free but scattered in pieces too small for a large job to use, a bin-packing problem no amount of negotiation could fix. Figure 2: GPU fragmentation. 8 free GPUs scattered as 1+1+4+2 across four nodes can’t fit an 8-GPU workload. Sometimes we had plenty of capacity free on paper, but it was scattered across different machines in chunks too small for a larger job to actually land. Without all-or-nothing admission, the cluster could reach a deadlock, with machines holding resources without doing useful work until someone stepped in manually. It was clear the status quo wasn’t working and we needed something better. Choosing the right scheduler We looked at a few open-source batch schedulers, including Apache YuniKorn, Volcano, and Kueue. YuniKorn didn’t cover all our use cases. And while Volcano had more features, integrating it with our environment would have required replacing core Kubernetes scheduler components. Kueue won on simplicity and integration. It worked with standard Kubernetes, didn’t require replacing core components, and didn’t force us to rewrite our job specs. Pairing Kueue with AI Hypercomputer’s flexible, open operations through GKE also contributed to our success. We rely on GKE because it gives us the right level of control for compute-intensive AI work — close access to GPU hardware and drivers, without the overhead of managing raw instances ourselves. Kueue’s native integration with GKE, including with Google Cloud capacity types like Spot VMs and Dynamic Workload Scheduler, meant that once our reserved capacity filled up, the same scheduling logic could reach out to elastic capacity automatically instead of leaving jobs stuck. Closing the loop with open source Adopting Kueue turned into something bigger than a simple process change. Because we partner with Google Cloud, we have a direct line to a Technical Account Manager, who saw an opportunity to make AI21 a design partner for the Kueue team. This way, we wouldn’t just be a user, but a source of real production requirements that could help shape where the tool went next. One of the first things to come out of that partnership was a requirements document we shared with the Kueue team, describing behavior we needed that didn’t exist yet: fair admission ordering across teams for multi-node jobs, without the preemption that usually comes bundled with fairness. The Kueue team built it. Admission Fair Sharing (AFS) reorders the admission queue to favor teams that have historically used less capacity without disrupting jobs already running. Around the same time, we also turned on Topology Aware Scheduling. This existing feature made Kueue aware of our physical cluster layout, so it can refuse to admit jobs that won’t fit on a single node rather than placing them with nowhere to run. For us, that’s what the best-case open-source feedback loop looks like: Real requirements surfaced through production use, fed directly back into Kueue. Same fleet, less friction The Slack #gpu-resources channel is archived now. Every workload, whether a debug pod, a multi-node training run, or an inference deployment, gets queued, prioritized, and scheduled automatically. The results were immediate. Manual interventions dropped from about 20 a week to zero. High-priority jobs that used to wait up to 72 hours now wait 12. Fragmentation across the cluster fell from 15% to 8%, and the “zombie job” problem — workloads partially admitted with nowhere to run — is gone. None of this changed our total cost. We run our reserved fleet at close to 100% utilization on purpose, so raw spend was never the variable we were optimizing. What changed is where our people’s time goes. Team leads aren’t refereeing compute disputes anymore, and researchers aren’t waiting on replies in Slack. That frees everyone to run more experiments and iterate faster.
Read original articleOctober 2, 2026
Nvidia’s chip-smuggling problem won’t go away as arrests continue.
Read original articleOctober 2, 2026
NVIDIA announced a new 64GB configuration of DGX Spark — from Acer, ASUS, Dell, Gigabyte, HP and MSI — its GB10-powered desktop AI system. It gives developers a way to start with one system for local models and agents, then cluster two 64GB units for 128GB of memory across the cluster and more compute when […] The post NVIDIA Announces DGX Spark 64GB: A 1-PetaFLOP Grace Blackwell Desktop for Local AI Agents, Fine-Tuning, and Inference appeared first on MarkTechPost.
Read original articleOctober 2, 2026
This week, the White House got nearly every major tech CEO in one room — Zuckerberg, Bezos, Musk, and Anthropic’s Dario Amodei among them — to sign an AI safety pledge that President Donald Trump called “morally binding.” Trump also signed an executive order officially rebranding AI as “super intelligence,” and meanwhile, Meta and OpenAI are putting friendlier faces on their AI products, even as the biggest money […]
Read original articleOctober 2, 2026
Ask a capital markets CFO on the buy side how the quarter looks, and the answer starts...
Read original articleOctober 2, 2026
Lockheed Martin is taking a model-agnostic approach to AI, using 55 different large language models across its business while applying the technology to everything from internal operations to autonomous weapons systems. SVP of Technology and Strategic Innovation Sarah Hiza discusses how Lockheed tests AI before deploying it, the growing role of autonomy and crewed-uncrewed teaming, and reveals that OpenAI is working alongside the F-35 team to tackle complex math and physics challenges tied to advanced sensor capabilities. She joins Ed Ludlow on "Bloomberg Tech." (Source: Bloomberg)
Read original articleOctober 2, 2026
"I don't think it should be left to any one company." Google SVP James Manyika says a "collective effort" is needed to ensure AI safety. (Source: Bloomberg)
Read original articleOctober 2, 2026
Revenge of the Nerd: Trump Kinda Seems to Like Anthropic’s CEO Gizmodo
Read original articleOctober 2, 2026
Alphabet Inc.’s Google raised the price of its seven-month-old Pixel 10a smartphone by $100 to $599, another example of how rising memory costs are making even older devices more expensive.
Read original articleOctober 2, 2026
Learn how startups can choose GPT-6 models, tune reasoning effort, improve prompts and skills, coordinate tools, and prepare workflows for production.
Read original articleOctober 2, 2026
With more than 1 million Genie Agents created in 2026 alone, the question facing...
Read original articleOctober 2, 2026
Want to know the latest from Google Cloud? Find it here in one handy location. Check back regularly for our newest updates, announcements, resources, events, learning opportunities, and more. Tip: Not sure where to find what you’re looking for on the Google Cloud blog? Start here: Google Cloud blog 101: Full list of topics, links, and resources. aside_block <ListValue: []> Sept 28 - Oct 2 Mastering Storage Management with Storage IntelligenceIn our new blog, explore practical strategies to modernize storage operations using Storage Intelligence Advisor and enhanced Batch Operations. See how customers like Shipt and Palo Alto Networks are using these features to manage their estates at scale. Today, Storage Intelligence is used by 25 of the top 50 GCS customers. 2 in 3 customers have Storage Intelligence enabled for over 90% of their storage footprint.Explore best practices on our blog Cut Gen AI costs by 70% with Apigee X dynamic routingGenerative AI deployments face a harsh cost-performance trade-off: static model selection either wastes budget or compromises quality. Discover how to build an Intelligent AI Gateway using Apigee X to dynamically evaluate prompt complexity in real-time. This new blueprint automatically routes simple queries to lightweight models (like Gemini 3.5 Flash Lite) and complex reasoning tasks to advanced models (like Gemini 3.7 Flash), achieving over 70% cost savings without sacrificing output quality. Read the guide to optimize your Gen AI architecture AI Agent Clinic launches new hands-on session on production agent evaluationsA new episode of the AI Agent Clinic is now available showing organizations how to move past manual "vibe checks" to build robust, production-grade agent evaluations. In this hands-on session, Google Cloud engineer Dani Zamora and Matthew Feroz (Merge) take DocsHound, an open-source LangGraph agent, and build an end-to-end eval pipeline in under an hour. Learn how to standardize multi-turn traces across any framework using OpenTelemetry and OpenInference, pair LLM judges with deterministic checkers, and catch silent quality regressions before shipping. Watch here Drive AI impact: Join Google's Agentic Data Cloud event on Nov 4Every enterprise plans to adopt agentic AI within two years, but data bottlenecks hold them back—AI accesses just 45% of enterprise data today (MIT, 2026). Google's Agentic Data Cloud provides the trustworthy foundation and real-time context AI needs. Join our product leaders November 4th to explore the latest innovations across databases, analytics, business intelligence, and storage, and get direct answers in our executive Q&A with Google Data Cloud VP & GM Andi Gutmans. Register today! Sept 21 - Sept 25 Master MCP tool authorization and agent governance with ApigeeWhile the Model Context Protocol (MCP) solves interoperability for autonomous AI agents, chained actions like CRM edits or database queries quickly expose systems to unauthorized execution. Join our technical deep dive on Thursday, October 1, 2026, at 5:00 PM CEST featuring Christophe from Google Cloud. Learn how positioning Apigee between MCP clients and enterprise backends enables fine-grained authorization (FGA), complete audit trails, and policy evaluation via emerging standards like OpenID AuthZEN.Language and accessibility note: This session will be hosted in French, but non-French speakers can follow along seamlessly by turning on Google Meet live translated captions to read in English, Spanish, German, Portuguese, or Italian.Register for the October 1 Community TechTalk Apigee Trace Viewer Tutorial: Capturing & Analyzing Proxy TracesStreamlining API proxy debugging just got easier with a new tutorial by Apigee Customer Engineer Tyler Ayers. The guide covers end-to-end instructions for capturing debug traces in both Google Cloud Apigee X (or Hybrid) and the local Apigee Emulator, extracting trace JSON data via the web UI or automated REST APIs, and analyzing execution flows, variable mutations, and latency bottlenecks using the open source Apigee Trace Viewer. Read the Apigee Trace Viewer guide today. Automate Apigee proxy testing locallyCatching errors early saves time and money. A new tutorial by Apigee customer engineer Tyler Ayers shows how to use the Apigee Local Emulator for automated testing. Learn to run tests locally, integrate them into CI/CD pipelines, and deploy on Google Cloud Run for shared sandboxes. This approach provides instant feedback and zero cloud costs, helping teams speed up deployment cycles.Read the tutorial Scale your enterprise multi-agent systems with ApigeeDeploying multi-agent architectures in production introduces critical hurdles around security, operational control, and runtime expenses. Discover how Apigee API Hub provides a central discovery surface to eliminate agent sprawl across tools, Model Context Protocol (MCP) servers, and enterprise APIs. Learn how to turn existing backend services into secure MCP tools using Agent Gateway guardrails, while applying semantic caching and intelligent model routing to keep compounding token costs predictable.Join Google Cloud in Chicago in Oct.15 for The AI Evolution. Reserve your seat for Chicago Automate Apigee proxy testing with the Apigee Local EmulatorWaiting on remote deployments to validate API proxy logic slows down release cycles and increases infrastructure overhead. Join Nigel Walters on Thursday, October 8, 2026, at 5:00 PM CEST for a Community TechTalk on shift-left testing for Apigee. Discover how to use the Apigee Local Emulator and apigee-emulator-service to run sub-second assertion suites on local machines, automate CI/CD checks in GitHub Actions, and deploy ephemeral preview sandboxes on Google Cloud Run.Register for the October 8 Community TechTalk Now in Public Preview: AI-assisted EKS-to-GKE migrations with deterministic guardrailsMigrating complex Kubernetes estates from AWS EKS to GKE is traditionally high-friction and error-prone. Now in Public Preview, GKE Agentic Migration is an open-source agent plugin that replaces ad-hoc LLM prompting with an AI-assisted migration workflow protected by deterministic guardrails.Running locally in your development harness, it indexes source IaC, maps cloud-specific primitives (such as Karpenter to Custom Compute Classes), and validates configurations offline—delivering reviewable pull requests and data-migration runbooks with zero live cluster mutations.Learn more in the announcement blog and try the plugin on GitHub. Claude Opus 5.5 is now available on Google Cloud. Built for everyday complex tasks, it delivers stronger agentic coding, research, and analysis while handling long-running work at a lower cost per token. Google Cloud continues to provide enterprise customers with broad model choice to build, deploy, and scale their AI agents securely. Try it here. Import Delta Lake tables with Dataflow Job Builder!Migrating to borderless Lakehouse just got a lot easier. You can now import Delta Lake tables stored in Cloud Storage using Dataflow Job Builder, a no-code/low-code interface for authoring Dataflow pipelines. Because Dataflow is a fully managed service, you are spared the overhead of provisioning and managing virtual machines. For step-by-step guidance, check out the documentation here. Sept 14 - Sept 18 Storage Intelligence Advisor for Google Cloud Storage is now GAGoogle Cloud Storage customers can now manage cloud storage more effectively with Storage Intelligence Advisor, delivering curated metrics, automated anomaly detection, and actionable recommendations right out of the box, with zero setup required.Advisor baselines activity across your projects and automatically detects four key anomalies: surges in operations, unexpected rises in cross-region egress, and spikes in errors. Each finding includes deep drill-down visibility into the resources driving the change, alongside prescriptive steps to remediate issues before they impact performance or cost.Learn more to get started with Storage Intelligence Advisor. Build private WebSockets from Apigee X to Cloud RunReal-time AI agents and streaming architectures often require persistent, bidirectional connections. A new implementation guide by Apigee Customer Engineer Joel Gauci demonstrates how to establish private southbound connectivity between Apigee X and Cloud Run. Using Private Service Connect (PSC) and a Regional Internal Application Load Balancer, teams can enforce API governance and security policies at the edge while keeping backend services completely isolated from the public internet.Explore the step-by-step guide and open-source code Connecting Gemini Enterprise Agent Runtime to Apigee with Private Service Connect Deploying autonomous AI agents often presents security, compliance, and cost challenges. A new reference guide details how to build an end-to-end, private architecture between Gemini Enterprise Agent Runtime and Apigee. This design helps protect internal backends and manage token quotas. Read the full community guide and deploy the code Discover what’s new and next in ApigeeAs enterprise architectures adapt to generative AI and autonomous workflows, Apigee is expanding its proven platform capabilities to support modern AI gateway use cases alongside traditional API management. Join our session on Thursday, September 24, featuring Apigee Product Manager Geir Sjurseth. Get an inside look at recent product releases, explore architectural patterns for securing models and agents, and bring your questions for the live Q&A.Register for the September 24 Apigee product update Managed Service for Apache Kafka supports clusters with public Internet access!With Managed Kafka public clusters, you can now produce and consume messages from clients outside your VPC—including your local machine, for faster, frictionless testing. Public clusters unlock use cases like IoT devices, retail storefronts, and telco network towers. Enable public access on new or existing clusters via the Google Cloud console, gcloud CLI, or REST API. Spin up your first public cluster, or reach out to kafka-hotline@google.com with questions. Stream data directly into Bigtable using Bigtable subscriptions, now in Preview!You can write Pub/Sub messages to a Bigtable table with zero ETL with Bigtable subscriptions. No pipelines, no code, delivered by the serverless, zero-ops experience you already know with Pub/Sub. Power your AI workloads, from model telemetry to real-time context engineering, without the overhead of managing complicated ETL pipelines. Built to be dependable, with native support for dead-letter topics. Try the feature today! Sept 7 - Sept 10 Why Your Voice Agent Needs Session AuditingMoving voice agents to production demands robust quality monitoring. This guide dives deep into the inner workings of the Agent Development Kit (ADK) responsible for audio session auditing. Learn how the ADK's save_live_blob feature intercepts, buffers, and stores raw audio chunks during active Gemini Live sessions. We explore building an automated post-processing pipeline to seamlessly stitch these fragments into cohesive, playable audio files. Discover how to leverage these vital audio audit trails to monitor real-world interactions, diagnose failures, and ensure enterprise-grade reliability. Read the full guide here. AlloyDB Omni Red Hat RPM Orchestrator now Generally AvailableAlloyDB Omni Red Hat RPM orchestrator is now Generally Available. The AlloyDB Omni Red Hat RPM orchestrator offers a new way to manage PostgreSQL-compatible workloads on bare metal or VM platforms, combining the high performance of AlloyDB, access to generative AI features and Gemini models to build AI agents and applications, and full automation. The orchestrator simplifies cluster provisioning and lifecycle management by allowing you to define reference architecture specifications, customizable by adjusting instance parameters, node configurations, and networking options — discover all details in full blog post. Aug 31 - Sept 4 Automate VM guest software lifecycle with VM Extension Manager, now GAGoogle Cloud VM Extension Manager is now generally available, eliminating the need for custom startup scripts to manage guest OS extensions across Compute Engine fleets. Define declarative, project-wide policies that enforce desired software states across all regions and zones. Benefit from continuous drift detection with automatic self-healing, multi-zone phased rollouts with automated rollbacks on failure, and centralized fleet health visibility integrated with Cloud Monitoring.Explore VM Extension Manager documentation Assess Apigee migrations without a target environmentPlanning a migration to Apigee X or Hybrid? You can now assess your legacy Apigee Edge SaaS or OPDK environment earlier in your planning cycle. Using the updated --skip-target-validation flag in the Apigee Migration Assessment Tool, teams can generate a full inventory and establish scope baselines before target infrastructure or IAM credentials are provisioned.Read the guide to learn more. Claude Fable 5.1 is now available on Agent Platform. It brings performance improvements over Fable 5 across reasoning, full-lifecycle coding, multi-tool workflows, and knowledge work. Anthropic also announced Enterprise Frontier Safeguards, a solution that gives customers the option to safely deploy Anthropic’s most capable models while storing their data in cloud infrastructure they control. We continue to offer enterprise customers options across frontier models to build, deploy, and scale securely on Google Cloud. Aug 24 - Aug 28 Grok 4.6 is now available in Preview on Gemini Enterprise. xAI's most capable model, built for coding, agentic tasks, and knowledge work, Grok 4.6 joins Grok 4.3 and Grok 4.20 in Model Garden and becomes the flagship of the Grok family. It supports reasoning, function calling, and structured output for multi-step agentic workflows, and accepts text and image input.Get started today Empowering autonomous agents with advanced security governanceAI agents offer incredible productivity gains, but granting them access to read emails, query databases, and trigger APIs introduces critical new security risks. In fact, 79% of tech leaders cite security and governance as their biggest challenge to scaling AI. Traditional tools are no longer enough to handle automated threats like prompt injection and dynamic permissions. Discover how forward-thinking enterprises are using secure-by-default design, agent identity governance, and human-in-the-loop controls to deploy agents with confidence.Read more Stateful processing is available in BigQuery continuous queries in PreviewStateful operations significantly expand what’s possible with BigQuery continuous queries. This feature allows users to leverage functions like JOINs, aggregations, and windowing functions directly in their streaming queries. Now you can calculate metrics over time (for example, a 30-minute average) to power your downstream applications and AI agents with much richer, real-time signals. Try out our feature here and share your feedback with bq-continuous-queries-feedback@google.com! Synthetic data generator tool is available for Managed Service for KafkaYou’ve launched your first Kafka cluster. Now what? The next thing to do is to produce some data to the cluster, but that involves modifying a client application somewhere or spinning up a virtual machine. The synthetic data generator tool, now generally available, can start sending mock data to your cluster in 3 clicks, and will get data streaming into your cluster in less than two minutes. The perfect utility for those moments you just want to test your cluster and new features. Try our quickstart today! Dataflow pipeline updates are faster & more flexibleDataflow pipeline updates can now stop-and-replace pipelines, a major addition to the existing in-place-update feature. The new parallel pipeline option accelerates the migration between the old & new pipeline, resulting in reduced disruption to your business. You can also set a timeout on drains that prevents runaway costs for your pipeliness in the event of stuck processing. This feature is generally available. Try it here! Aug 17 - Aug 21 Webinar: Agent Identity as the backbone for secure AI innovationAn AI agent with a stolen API key looks identical to a legitimate one. As autonomous agents scale across enterprise systems, static credentials and legacy IAM policies can no longer keep up with machine-speed execution. Join Shaun Liu, Product Manager at Google Cloud, on August 27 at 1 PM ET to explore Google Cloud’s vision for unifying agent, human, and nonhuman identity into a workload-centric platform using verifiable cryptographic identities (SPIFFE, ID-JAG, OAuth).Register for the webinar now Aug 10 - Aug 14 Diagnosing Apigee Hybrid Cassandra Read Latency for Peak PerformanceDiagnose real-time Cassandra read latency and resolve API key verification bottlenecks in Apigee Hybrid with this step-by-step troubleshooting guide. Learn how to deploy a debugging client and query performance tables to maintain sub-millisecond response times. Read the Apigee Hybrid Cassandra Troubleshooting Guide Keep moving with agents! The All Things Agentic Hackathon is officially live.We're challenging builders to build next-generation agents that take on the busy work and handle the heavy lifting in the background using Gemini 3.5 and Google Cloud. Compete for your share of $190,000 in prizes, cash, and Google Cloud credits! Submissions are open from August 3, 2026, to August 31, 2026.Learn more and register. Sign up for GEAR to get exclusive updates and your badge. # Accelerate PostgreSQL migrations using Gemini in Database Migration ServiceEnterprise database migrations often stall during the "last mile" of translating legacy stored procedures, triggers, and custom functions from Oracle or SQL Server. Database Migration Service (DMS) now provides AI-assisted code conversion powered by Gemini in Databases. By combining deterministic compiler rules for 1:1 syntax with Gemini contextual synthesis for complex procedural blocks, DMS converts legacy code into native PostgreSQL and AlloyDB with full schema awareness and side-by-side validation.Read the full blog post to learn how to streamline your database code conversion. Compute Flex CUDs now available for G2 and G4 GPU VMsCompute Flexible Committed Use Discounts (Flex CUDs) are now available for G2 (NVIDIA L4) and G4 (NVIDIA RTX Pro 6000) VMs. You can now lock in predictable savings while retaining the flexibility to adapt across VM families, migrate between regions, and combine general-purpose compute, GKE, Cloud Run, and G2 & G4 GPU VMs under a single spend commitment. Flex CUDs for G-series VMs let you lock in savings today while preserving the agility to upgrade to latest hardware without disruption!Explore VM instance pricing or learn more about Flex CUDs. Rapid Bucket accelerates the training and checkpoint performance in PyTorch Ecosystem via GCSFSWith the release of GCSFS 2026.8.0, organisations can now unlock maximum ROI from their AI/ML infrastructure by eliminating data starvation on GPUs in PyTorch ecosystem when they are using Frameworks like Dask, Pandas, PyTorch , PyTorch Lightning, Hugging Face Datasets, Ray dataetc. By making adaptive concurrent prefetching the default, GCSFS dynamically predicts and background-fetches sequential read patterns—boosting single-file throughput by 5x, and scaling up to 21 GiB/s , saturating the NIC when paired with Rapid Bucket. Saturating the NIC translates to significantly improved accelerator goodput and reduced training wait times with zero integration friction. Training and checkpoint restore workflows benefit from intelligent memory management that automatically drains the buffer during random reads to completely avoid bandwidth or memory penalties. Aug 3 - Aug 7 Navigate data sovereignty and AI innovation with hybrid cloudFor enterprises facing strict compliance rules, keeping sensitive data on-premises often means missing out on cutting-edge AI. Data from the 2026 State of AI Infrastructure report reveals that 52% of IT leaders are adopting hybrid cloud strategies to bridge this gap. Our latest blog post explores how Google Distributed Cloud (GDC) helps organizations deploy connected or air-gapped models to run advanced AI entirely within secure environments—mitigating geopolitical risks without sacrificing innovation. Read more. SAP and Google Cloud Launch BDC Connect for BigQueryFor years, enterprises have struggled with the cost, risk, and complexity of moving mission-critical SAP data into advanced analytics platforms. The general availability of SAP Business Data Cloud (BDC) Connect for BigQuery marks a turning point. By introducing revolutionary zero-copy, bi-directional data sharing, this new capability seamlessly bridges SAP systems with Google Cloud's powerful data and AI ecosystem. Instead of wrestling with manual data duplication and lost business context, organizations can now eliminate silos, dramatically lower their analytics costs, and rapidly deploy trustworthy, agentic AI solutions grounded in real-time operational reality. Read the full announcement to learn how to transform your data strategy. Google Cloud Cortex Framework version 7 is now generally available!This release helps you modernize your data architecture for AI agent readiness, enabling you to quickly deploy, customize, and extend robust data products while simplifying orchestration and reducing infrastructure overhead. It provides data product accelerators for SAP-sourced data to build trusted, high-quality data products ready for advanced analytics and agentic use cases. The Framework integrates with Google Cloud products including BigQuery, Dataform, Knowledge Catalog, and Gemini Enterprise Agent Platform. Learn more in our announcement blog, technical documentation, or try a demo deployment today. From API Management to AI Gateway with ApigeeMassive LLM adoption unlocked automation but exposed critical vulnerabilities, from unpredictable token costs to security risks like prompt injection. Without central management, organizations face accelerated technical debt. Learn how to transform Apigee into an enterprise AI Gateway to centralize governance. This architectural roadmap details how to utilize semantic cache to optimize token costs, implement prompt protection policies for security, and productize tools using the emerging MCP standard.Read the full architectural roadmap on the Apigee Community Hub Centrally govern enterprise AI traffic with Apigee AI GatewayManage, track, and secure model communication across your entire infrastructure from a single pane of glass. In a new video walkthrough, Principal Architect Tyler Ayers demonstrates how Apigee AI Gateway simplifies agentic governance. Learn how to transparently proxy model traffic, log real-time token counts, and apply runtime security quotas without impacting your developer workflow.Watch the Apigee AI Gateway demo Maximize Provisioned Throughput UtilizationSudden traffic micro-spikes can exceed per-second quotas, triggering 429 errors or forcing overflow into shared resource pools. A new architectural guide demonstrates how to build a serverless "shock absorber" using Cloud Run and Google Cloud Tasks. By decoupling request ingestion from execution, this queue-based pattern flattens volatile traffic bursts and smoothly drips requests to Gemini at your exact quota rate, maximizing Provisioned Throughput utilization while eliminating job failures during peak usage. Read the step-by-step setup guide. Eliminate security blindspots in agentic tool agentic tool calls via the Model Context Protocol (MCP) can introduce critical security risks to your enterprise architecture. Join our technical deep dive on Thursday, August 13, to discover how to position Apigee as a centralized security gateway. Featuring the new ParsePayload policy and payload operations groups in API Products, this session demonstrates how to enforce granular tool filtering, manage execution quotas, and scale secure agent ecosystems without impeding developer velocity. Register for the August 13 Community TechTalk Jul 27 - Jul 31 Data Cloud and Apigee CDMX: The AI Agent Evolution | August 12, 2026Enterprise AI demands evolution beyond basic conversational assistants. To generate real value, AI models must connect with the organization's core systems and live data sources. Join us this August 12 at Google CDMX for the exclusive event AI Evolution: Powering Tomorrow's Enterprise. Learn how to design an agile and secure ecosystem by unifying the power of Gemini, Apigee, and data agent technologies through practical demonstrations led by Google Cloud engineers.Secure your spot for the in-person session in Mexico City Register now! Vast Edge, built on GCP, launches the first live recovery interface for cloud backups, enabling IT teams to inspect backup contents in real time. This transforms backups from a blind, log-based process into an interactive platform where teams can instantly search, preview, and validate the exact data available for restore.This platform protects Google Workspace, NetSuite, Salesforce, Workday and many SaaS environments, providing complete visibility and enterprise-grade oversight.Visit Vast Edge Backup & Disaster Recovery and get a free trial of their backup solutions on the GCP Marketplace for Google Workspace Backup, NetSuite Backup, Salesforce Backup, and Workday Backup. Jul 20 - Jul 24 Claude Opus 5, Anthropic’s latest model, is now available on Agent Platform. It brings performance improvements over Opus 4.8 across coding, long-running agents, and knowledge work.The model is Zero Data Retention (ZDR) compatible. For safety, high-risk workflows — such as penetration testing or exploit generation — it will notify you and fall back to Opus 4.8.We’re excited to continue to offer enterprise customers options across frontier models to build, deploy, and scale AI securely. Try it here. Apigee Northam Roadshow 2026 | The AI Agent Evolution: Powering Tomorrow's EnterpriseAI is evolving. As your organization deploys autonomous agents, the integration between APIs and models becomes critical. Join Google Cloud specialists for an exclusive day of deep-dive sessions and live demos. Discover how the unified power of Apigee and the Google Cloud Agent Platform allows you to build, govern, and scale high-performance AI agents with complete control. Call to Action: Register for Sunnyvale | Register for NYC | Register for Chicago Deploy an Apigee Proxy for MCP Registry Discovery Learn how to deploy an Apigee X proxy to format Apigee API Hub data into the Model Context Protocol (MCP) Registry format. This tutorial by Tyler Ayers guides developers through cloning the sample repository, deploying using the Apigee Feature Templater (aft), and testing the endpoint to make API data easily discoverable by coding agents. Read the full community tutorial to get started. Simplify AI Infrastructure: Getting Started with Apigee AI GatewayManaging a complex AI landscape with multiple backend environments can present significant operational and governance challenges. A new tutorial walks you through how to build a unified API proxy using Apigee AI Gateway. By establishing a single, secure entry point for all model traffic, teams gain access to real-time analytics, comprehensive tracing, and financial operations auditing—completely seamlessly, and with absolutely no modifications required to client environments or user configurations. Read the step-by-step setup guide Your AI agents are ready. Is your data?The biggest bottleneck to scaling AI isn't the models—it's giving them access to business context. As enterprises move to proactive systems of action, legacy infrastructure often buckles under the nonlinear speed of AI agents. Google Cloud’s new Agentic Data Cloud, built on AI-native infrastructure, solves this by unifying data, AI models, and operational databases. Discover how a borderless Lakehouse and active Knowledge Catalog can empower your AI agents with trusted, real-time context without unnecessary engineering overhead. Read more. Secure and govern your AI at Apigee AI Horizon in LondonMoving AI from basic prompts to complex agentic workflows requires trust and control. Join us on Tuesday, 1st September 2026 at Google London for our 5th edition of Apigee AI Horizon. Discover how Google Cloud product leaders and architects are using Apigee and Model Armor to secure LLM APIs, implement policy controls, and manage token consumption. Do not miss this one—register soon!Secure your spot for AI Horizon London Jul 13 - Jul 17 Resource-Based CUD Sharing is Now Enabled by DefaultStarting June 16, 2026, the default setting for Google Cloud Resource-based Committed Use Discount (CUD) sharing will change from disabled to enabled for new billing accounts and eligible existing accounts without active CUDs. This update automatically maximizes your savings by pooling underutilized discounts across your resources.You retain full control and can adjust your CUD sharing preferences at any time by changing your CUD scope configuration. For instructions, see Enable CUD sharing or Disable CUD sharing. Webinar for India: Google Cloud for EdTech: Optimizing Traffic and Token Governance at ScaleAPI traffic surges and AI model integration are reshaping the EdTech landscape. Join Satyam Maloo for the webinar Google Cloud for EdTech: Optimizing Traffic and Token Governance at Scale on July 23, 2026. Learn to implement advanced rate limiting, gain granular token visibility, and leverage real-time analytics to govern your platform effectively. Whether you’re scaling for peak academic seasons or integrating complex AI workflows, this session provides the infrastructure blueprint you need.Register Now Scaling AI Agents: Treat prompts like software artifactsAs AI agents move into production, monolithic system prompts often result in configuration drift, merge conflicts, and silent runtime failures. The solution is adopting a Prompts-as-Code architecture. By breaking prompts into modular skill files and using a build-time transpiler, engineering teams can introduce dependency resolution, static validation, and CI/CD rigor to their agent's control plane. Stop manually editing massive text files and start building deterministic, reliable agent infrastructure.Read more here. Jul 6 - Jul 10 Webinar: Introducing Google Cloud NGFW Enterprise advanced malware protection - powered by Palo Alto NetworksDiscover the new Cloud NGFW advanced malware sandbox, arriving in preview later this year. Powered by Palo Alto Networks Advanced Wildfire, it leverages data from 70,000+ customers to help defeat advanced malware. Join us on July 16 at 11 AM EDT to learn how to build a resilient, zero-trust cloud infrastructure that protects your apps and data, wherever they reside.Register for the webinar now Safely run AI-generated code in Cloud Run sandboxesCloud Run sandboxes, now in public preview, are lightweight, isolated execution boundaries that you can spawn near-instantly within your existing Cloud Run service instances.Whether you need to let an LLM run a dynamically generated Python script to calculate business margins or spin up a headless browser to perform web research, Cloud Run sandboxes give you a secure, isolated sandbox to run these tasks without leaving your serverless environment.Read the blog to learn more and get started today. Australia API Horizon: Scaling Enterprise Governed AI AgentsThe transition from AI chatbots to autonomous agents is the most critical integration point for your business. Join Google Cloud at our upcoming events to explore exclusive deep-dive sessions on architecting for the agentic era.Discover how to use Apigee as an intelligent AI Gateway to govern, secure, and scale high-performance architectures. You will learn to seamlessly build AI tools from your existing APIs and maintain control over your entire ecosystem.Join us in your preferred city: Sydney: July 28, 2026, at Google Sydney, One Darling Island. Canberra: July 29, 2026, at Hotel Realm. Melbourne: August 4, 2026, at Google Melbourne. Build highly available, multi-region services on Cloud RunMaintaining uptime for business-critical applications just got a lot easier on Cloud Run. Service health, now Generally Available, automates cross-region failover by leveraging readiness probes for instance-level health checks with a simple, two-click setup. You can configure service health with global external Application Load Balancers for public-facing applications or cross-region internal Application Load Balancers for private networking traffic.Learn how to configure service health for Cloud Run. Report: 83% of organizations need infrastructure upgrades for agentic AIThe shift from conversational bots to autonomous agents is breaking legacy systems. Our new State of AI Infrastructure report details how engineering leaders are adapting to these massive new workloads. To eliminate inference bottlenecks, control hidden scaling costs, and manage agent sprawl, the industry is rapidly moving toward fluid compute, centralized governance, and unified, co-designed architectures.Explore our key infrastructure insights Stop tinkering, start scaling: the industrialized AI PlaybookDid you know that only 5% of custom AI investments actually return measurable business value? The problem isn’t the technology—it’s how organizations are wired to run it.In this compelling read, Google Cloud Consulting breaks down the operational blueprint that bridges the stark gap between "cool tech experiments" and real, P&L-impacting enterprise ROI.Read the full article on Medium AI Agent Clinic: Slashing App Latency by 80%Prototyping an AI agent is easy, but scaling for live traffic presents unique challenges. In the latest AI Agent Clinic, our technical experts partner with a developer to optimize PlaybackIQ, a live football analysis agent. This session demonstrates how to use OpenTelemetry to trace bottlenecks in the Gemini Enterprise Agent Platform and deploy to Cloud Run for high-concurrency scaling, achieving an 80% reduction in response time. Learn production-grade debugging strategies to optimize your own LLM applications.Watch the 60-minute teardown Jun 29 - Jul 3 Claude Sonnet 5, Anthropic’s latest model, is now available on Agent Platform. This addition serves as a drop-in replacement for Sonnet 4.6, giving organizations expanded choice for task completion across enterprise workflows. It features enhanced reasoning, cleaner code generation, and computer use capabilities for desktop and browser workflows.By continuing to rapidly bring frontier models to our platform, Google Cloud offers an uncompromised choice of the industry's best technology to build, test, and scale enterprise-grade AI.Get started today. Automate your AI governance with Apigee and YAMLManual API gateway configurations can quickly slow down your AI engineering velocity. Join the Apigee community on Thursday, July 16, to discover an automated, declarative blueprint for model garden management. Learn how a simple, repeatable YAML pattern lets your AI practitioners instantly spin up secure, policy-backed enterprise configurations without friction. Bring your questions and connect during our live Q&A session. Register for the July 16 Community TechTalk Build next-generation AI portals for autonomous agentsStandard developer portals were designed for human developers to subscribe to static APIs. Today, autonomous agents, LLM toolkits, and dynamic runtimes demand a central nervous system for governance. Join our technical deep dive on Thursday, July 23, to explore Apigee's new AI Portals solution. You will see exactly how to deploy full-service, MCP powered hubs to safely manage enterprise self-service for models, tools, and agents. Register for the July 23 Community TechTalk Protect your infrastructure from advanced cyberattacks at the API layer (Presented in Portuguese)In an era of increasingly sophisticated threats, relying solely on traditional firewalls leaves critical data gaps. Join our technical community TechTalk on Thursday, July 30—conducted in Portuguese—to learn how to proactively mitigate risks directly at the gateway layer. This session demonstrates how to configure and govern essential Apigee security policies to build a robust line of defense, ensuring maximum availability and complete integrity for your enterprise microservices. Register for the July 30 Portuguese Community TechTalk Jun 22 - Jun 26 Accelerate TPU model loading while saving RAM on GKE.Large model cold starts often stall scaling and leave high-value TPUs idle. The open-source Run:ai Model Streamer now natively supports TPUs with Google Cloud Storage in TPU vLLM 0.18.0. This integration accelerates inference pipelines on GKE by streaming tensors directly into CPU memory, bypassing local disk bottlenecks and the "double-buffering" trap. In benchmarks, loading a 480B parameter model was over 2x faster while cutting peak host memory usage by half. Read the full guide and get started today. Stop Training Blind: Scaling AI with the New OpenTelemetry-Based TPU AI Telemetry Collector AgentGoogle Cloud’s new AI Telemetry Collector agent standardizes TPU monitoring using OpenTelemetry. It optimizes enterprise ML workloads by identifying silent failures and providing zero-cost operational metrics without draining host CPU cycles. The agent seamlessly routes telemetry to Google Cloud Monitoring or Prometheus and custom Grafana setups. Pre-installed on Google-optimized Ubuntu images or available via Docker, it tracks memory, network latency, and core utilization to maximize multi-node training efficiency.You can read more of this capability by clicking this link. Jun 15 - Jun 19 Join us for a deep dive into agentic AI control with AppyThingsYour integrations aren’t failing—they are evolving. When users interact with AI agents, they no longer arrive directly at your site, resulting in experiences stripped of your context, expertise, and intended experience. Join us on Thursday, June 25, for a community tech talk in partnership with AppyThings to learn how to solve this new gateway challenge. We will explore how MTN laid an integration foundation with the Model Context Protocol (MCP) to deliver accurate, consistent experiences. Our technical experts will demonstrate how to leverage Apigee as a centralized tools management solution to govern agent access. Register for the session Optimize Spot VM Deployments with Capacity Advisor for Spot, Now in Public PreviewGoogle Compute Engine has launched Capacity Advisor for Spot to Public Preview, now open to all customers. This tool turns Spot capacity discovery into a data-driven process by providing real-time deployment recommendations to maximize obtainability and minimize preemption risks. Query the Capacity Advisor API for obtainability and minimum estimated uptimes, or use the new Console UI featuring a global availability map, spot price lookups, and historical preemption rate trends to visually find the most cost-efficient compute capacity.Get started today to start optimizing your Spot VM deployments! Build a multi-tenant agentic AI systemWhen scaling generative AI across different business units, your teams need specialized AI agents with unique operational rules and tools. Our new reference architecture helps you build a centralized multi-tenant platform to prevent fragmented silos, eliminate data exposure risks, and maintain unified compliance. Read the guide to design and deploy a multi-tenant agentic AI system in Google Cloud. How to Configure Gemini Enterprise to Connect to a Custom MCP ServerThe Gemini Enterprise MCP Connector was a big announcement at Google Cloud Next because it introduces the ability to connect Gemini Enterprise to MCP servers. This blog post provides a step-by-step guide on how to configure your first Custom MCP Server connector using the Google Maps Ground Lite MCP server as an example. Once you understand this flow, you can configure multiple MCP servers with Gemini Enterprise to bring all the context you need. Jun 8 - Jun 12 Simplify Multi-Cloud Planning with Cloud Location Finder, now Generally Available Cloud Location Finder provides up-to-date data on public regions, zones, and Google Distributed Cloud Connected locations across Google Cloud, AWS, Azure, and OCI. You can now programmatically discover locations based on provider, proximity, territory, and carbon footprint to optimize your global infrastructure strategy for performance, compliance, and sustainability. Get started for free today Jun 1 - Jun 5 Modeling the physical world with BigQuery GraphManaging complex supply chains requires more than just spreadsheets; it requires a digital replica of the physical world. In this post, Guru Rangavittal and Candice Chen explore how BigQuery Graph enables organizations to build a digital twin by turning physical assets into an interconnected map of nodes and edges. By moving beyond traditional relational databases, businesses gain real-time clarity into operations—from executing surgical ingredient recalls to analyzing weather-driven logistics risks. Discover how BigQuery Graph transforms reactive firefighting into proactive, precision modeling, allowing you to see critical connections in seconds and future-proof your supply chain. Apigee for AI: Govern LLMs and MCP Servers (Presented in Spanish)Learn how to securely transition your AI initiatives from experimental prototypes to enterprise-ready deployments. Join Luis Cuellar on June 18 for a technical deep dive (presented in Spanish) exploring Apigee’s latest AI gateway capabilities. Discover how to centralize governance over Model Context Protocol (MCP) servers, protect Large Language Models (LLMs) with robust API gateway security policies, and manage token-based quotas.Register for the June 18 Spanish Community TechTalk May 25 - May 29 Anthropic’s Claude Opus 4.8 is now available on Gemini Enterprise Agent Platform. As we continue to expand our platform's model offerings, this addition gives organizations more options for handling complex, multi-stage enterprise workflows. Claude Opus 4.8 brings strong capabilities in agentic coding, allowing developers to manage extensive refactors and tracking dependencies over extended sessions. API Horizon Munich July 6, 2026: Orchestrating the Next Era of AI and APIs Master the orchestration of next-gen AI and digital ecosystems. Join Google Cloud experts and DACH tech leaders on July 6 for an exclusive look at the Apigee roadmap, Agent Management, and Model Context Protocol (MCP). Gain real-world insights and connect with the regional integration community.Register now Securing AI Agents: The Extended Agent Gateway PatternLearn how to prevent autonomous AI agents from invoking unauthorized APIs. Join Apigee Specialist Joel Gauci on June 4 for a technical deep dive into the Extended Agent Gateway pattern. This session covers enforcing Fine-Grained Authorization (FGA), implementing secure token exchange, and establishing Model Context Protocol (MCP) governance at the API gateway layer to protect enterprise backend services.Register for the June 4 Community TechTalk API-to-Agent Security: Exposing REST APIs to Gemini Enterprise via MCPConnect Gemini Enterprise agents to core data without creating security hazards. Join Google Cloud Specialist Nigel Walters on June 11 to learn how to instantly transform legacy REST APIs into secure Model Context Protocol (MCP) servers. We’ll cover how to safely register tools with Gemini while enforcing gateway-level guardrails like rate limiting and access control policies.Register for the June 11 Community TechTalk May 18 - May 22 Chinese Webinar | June 4: AI Command and ControlAs AI agents move from experimental pilots to core enterprise functions, governance has become a critical next step. Join Google Cloud on June 4th at 10:00 AM (Beijing Time) to learn how to build a secure AI management layer architecture. We'll explore how to develop governed MCP (Model Context Protocol) endpoints, manage tool access to enterprise data, and leverage robust audit logs to operationalize AI. This session also includes a practical demonstration of these governance frameworks on Google Cloud.Register here GCP Announces New Features to Benchmark and Optimize LLMs for On-Device Use CasesDeploying fine-tuned LLMs from GCP to edge devices like smartphones is complex due to fragmented hardware. Google AI Edge Portal bridges this gap, giving GCP developers the ability to test AI performance on 120+ Android devices, representing the full diversity of high, medium, and low tier smartphones on the market today. This week at I/O, we announced brand new capabilities to benchmark and debug LLM performance across these devices. Sign-up to utilize these new features in private preview today. May 11 - May 15 Build Your AI & MCP Control Tower for Universal GovernanceMaster the future of agentic security with Apigee. Join our Community TechTalk on May 21 to discover how Apigee serves as a central "Control Tower" for the Model Context Protocol (MCP). We will explore how new JSON-RPC tool authorization enables fine-grained access policies across your organization, ensuring secure and scalable AI deployments. Whether managing internal tools or external users, learn to govern your agentic ecosystem with absolute precision. This session is designed for global coverage across EMEA and AMER regions.Register for the May 21 Community TechTalk Apr 27 - May 1 Master Your Launch: The Apigee Production Go-Live ChecklistEnsure a secure launch with the Apigee production guide. Join Nicola Cardace on May 28 to explore security guardrails, including IAM roles, mTLS configurations, and encrypted KVM migrations. Scheduled at 11 AM EDT / 5 PM CEST to support EMEA and AMER teams, this TechTalk provides the technical roadmap you need to flip the switch with absolute confidence.Register for the May 28 Community TechTalk Transforming APIs into Governed Agentic Tools on the Google Cloud Agentic PlatformTurn your APIs into secure, governed agentic tools on the Google Cloud Agentic Platform. Join Specialist Christophe Lalevée on May 7 for a technical deep dive into AI productization. Scheduled at 5 PM CEST / 11 AM EDT to maximize coverage for developers across EMEA and AMER, this session explores the integration and governance frameworks required to scale enterprise-ready AI with confidence. Register for the May 7 Community TechTalk Fractional G4 VMs are Generaly Available, providing a highly efficient and cost-effective entry point for AI and graphics workloads. These new configurations, using NVIDIA virtual GPU (vGPU) technology, allow you to leverage the power of the NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs in flexible, smaller increments, so you can right-size your infrastructure to match the specific demands of your applications. By providing more granular access to advanced hardware, fractional G4 VMs let you optimize resource allocation and reduce overhead without sacrificing performance. You can now select from additional GPU slice sizes for your specific needs: 1/2 GPU: Ideal for more intensive tasks such as LLM inference, robotics sensor simulation, and high-fidelity 3D rendering. 1/4 GPU: Optimized for mainstream workloads, including mid-range creative design, video transcoding, and real-time data visualization. 1/8 GPU: Great for lightweight applications such as remote desktops, productivity tools, and entry-level streaming services. Transitioning AI from a sandbox prototype to an enterprise-grade system is a major hurdle. A monolithic script won't suffice for widespread deployment. To achieve true scale and reliability with Gemini, organizations must adopt service-oriented micro-agent architectures, establish Zero-Trust security, and implement rigorous EvalOps. Master the "Agentic Maturity Ladder" to ensure your AI & Agentic solutions are robust, secure, and ready for the real world. Watch the deep dive and read the developer blog to learn more. ML Development in VS Code with Google Cloud Power: Workbench Extension Now AvailableData scientists and developers can now combine the local productivity of VS Code with the scalable infrastructure of Google Cloud. The new Google Cloud Workbench Notebooks extension allows you to connect to and run notebooks on managed cloud environments directly within your local IDE. This integration streamlines the ML lifecycle by eliminating context switching and providing high-performance compute for complex workloads in a familiar interface. As part of our commitment to the developer ecosystem, the extension is fully open-sourced to support community-driven innovation. Install from Marketplace: GoogleCloudTools.workbench-notebooks Contribute on GitHub: colab-enterprise-vscode Apr 20 - Apr 24 Announcing the 2026 Google Cloud Partners of the YearGoogle Cloud is honored to celebrate the winners of the 2026 Partner of the Year awards! These awards recognize an exceptional group of partners across AI, Security, Infrastructure, and more, who have demonstrated a commitment to customer success. From global system integrators to specialized startups, these winners are leveraging the power of Google Cloud to solve complex challenges and drive digital transformation worldwide. Join us in congratulating these organizations for their innovation, collaboration, and impactful results over the past year.See the 2026 Partner Award winners Apr 13 - Apr 17 We're excited to announce the Public Preview of Datastream’s metadata integration with Knowledge Catalog. This is the first step in our vision to provide a centralized, "single pane of glass" for all Datastream assets. The enhancement automatically synchronizes Streams, Connection Profiles, and Private Connections, eliminating data silos. It enhances discoverability, allowing you to search for Datastream assets using the same interface as BigQuery tables. Centralized governance is also provided, making your real-time data estate more transparent and easier to manage. Upgrading Apigee OPDK to 4.53 with OS your infrastructure using Google’s official, sequential upgrade path. Our Technical expert, Rakesh Talanki outlines how to upgrade Apigee OPDK to v4.53 while migrating to a supported OS (RHEL 8.x/9.x). This guide covers the "build-out" methodology, including multi-data center syncing, to ensure a stable, zero-downtime transitionRead the guide Cloud Run Worker Pools and CREMA: Powering Serverless AI at ScaleGoogle Cloud has announced the General Availability of Cloud Run worker pools, a new resource type designed specifically for pull-based, non-HTTP workloads. Unlike traditional Cloud Run services that scale based on request traffic, worker pools provide an "always-on" environment for background tasks like processing message queues or running large-scale AI inference. To support this, Google Cloud also open-sourced the Cloud Run External Metrics Autoscaler (CREMA). Built on KEDA, CREMA enables queue-aware autoscaling for worker pools, allowing them to dynamically scale based on external signals like Pub/Sub backlog or Kafka lag. Apigee Model Context Protocol (MCP) now Generally AvailableExpose enterprise APIs as MCP tools for agentic AI applications with the General Availability of MCP in Apigee. This update allows developers to transform APIs into AI-ready tools using OpenAPI Specifications, removing the need for local MCP servers or additional infrastructure. With managed endpoints and semantic search in API hub, you can now provide AI agents with secure, governed access to enterprise data at scale.Explore the MCP overview Apr 6 - Apr 10 Community TechTalk: Powering Retail Agents with ADK, UCP & Apigee XMove beyond basic chatbots to secure, transactional AI experiences. Join our Community TechTalk on April 16 to learn how Apigee X and Gemini build a "Trust Layer" for AI shopping assistants using UCP standards. We’ll demonstrate how to block prompt injections with Model Armor and implement cost governance via token limits to secure the path from discovery to purchase.Register for the TechTalk Implement multimodal capabilities in your AI agentsExplore three new reference architectures for building sophisticated multi-agent AI systems that can process and analyze multimodal data. To analyze disparate multimodal data and produce a high-confidence classification, see Classify multimodal data. To create a fluid conversational AI that processes audio and video streams in real time, see Enable live bidirectional multimodal streaming. To consolidate fragmented multimodal data into a searchable knowledge graph, see Multimodal GraphRAG resource orchestration. Automate SecOps workflows with an agentic AI systemTo accelerate incident response and reduce manual toil for your security team, you need a system that can automate remediation playbooks. Our new reference architecture helps you build an AI agent that orchestrates complex triage and investigation workflows across disparate security tools, such as SIEM, CSPM, and EDR, from a single interface. See the full guide to orchestrate security operations workflows. Mar 30 - Apr 3 ASEAN Webinar | April 30: Mastering Agentic Governance at Scale with GCPAs AI agents move from experimental pilots to core enterprise functions, governance is the critical next step. Join Google Cloud experts Shilpi Puri & Wely Lau for a webinar on April 30th at 11:00 AM SGT to learn how to architect a secure AI Management layer. We’ll explore developing governed MCP endpoints, managing tool access to enterprise data, and operationalizing AI with robust audit logs. The session includes a live demo of these frameworks in action on Google Cloud.RSVP here. Mar 23 - Mar 27 Turn your API sprawl into an agent-ready catalogAs organizations scale, APIs often become scattered across multiple gateways, creating "blind spots" that hinder AI adoption. To solve this, we’ve introduced two new capabilities for Apigee API hub: a new integration with API Gateway to automatically centralize API metadata into a single control plane, and a specification boost add-on (now in public preview). This add-on uses AI to enhance your API documentation with the precise examples and error codes that AI agents need to function reliably.Read the full blog post to get started. Webinar | April 16: AI Command & ControlAs AI agents move from experimental pilots to core enterprise functions, governance is the critical next step. Join Google Cloud expert Satyam Maloo for a webinar on April 16th at 11:00 AM IST to learn how to architect a secure AI Management layer. We’ll explore developing governed MCP endpoints, managing tool access to enterprise data, and operationalizing AI with robust audit logs. The session includes a live demo of these frameworks in action on Google Cloud.RSVP here. Modernizing and Decoupling Event Ingestion with ApigeeIn modern cloud-native architectures, decoupling producers from consumers is critical for building resilient systems. While Google Cloud Pub/Sub provides a scalable backbone, exposing it directly to external clients can introduce security and management overhead. This new guide explores how to leverage Apigee as an intelligent HTTP ingestion point. Learn how to handle security, mediation, and traffic control before messages reach your internal bus using the PublishMessage policy or Pub/Sub API.Read the full guide. Mar 16 - Mar 20 Gemini-powered Assistant in BigQuery Studio Gets Context-Aware UpgradesThe Gemini-powered assistant in BigQuery Studio has been transformed into a fully context-aware analytics partner, supporting your entire data lifecycle. The new capabilities include intelligent resource discovery, which uses Dataplex Universal Catalog search to find resources across projects and deep dive into metadata using natural language. You can now automate tasks, such as scheduling production-grade queries directly through the chat interface, and instantly troubleshoot long-running or failed jobs with root cause analysis and cost control auditing.Explore the full range of what the assistant can do. Mar 9 - Mar 13 Want to use Gemini to develop code and don't know where to start?This article includes a couple of examples of developing code with Gemini prompts; it identified changes that were needed to be made to get the code working. The article also refers to other examples that are available on github. Mar 2 - Mar 6 Introducing Gemini 3.1 Flash-Lite, our fastest and most cost-efficient Gemini 3 series model. Built for high-volume developer workloads at scale, 3.1 Flash-Lite delivers high quality for its price and model tier. Gemini 3.1 Flash-Lite can tackle tasks at scale, like high-volume translation and content moderation, where cost is a priority. And it can also handle more complex workloads where more in-depth reasoning is needed, like generating user interfaces and dashboards, creating simulations or following instructions. Starting today, 3.1 Flash-Lite is rolling out in preview to enterprises via Vertex AI and developers via the Gemini API in Google AI Studio. TechTalk: Implementing Device Authorization Grant (RFC 8628) for ApigeeLearn how to authorize "headless" devices like Smart TVs or AI agents that lack keyboards and browsers. Join our Community TechTalk on March 19 (5PM CET / 12PM EDT) to go under the hood of Apigee X/Hybrid. We’ll cover the real-world mechanics of state management, polling, and human-in-the-loop security patterns for devices and autonomous agents. Register for the TechTalk Feb 23 - Feb 27 Pro-level image generation gets faster and more accessible with Nano Banana 2Nano Banana 2 is our state-of-the-art image generation and editing model. It delivers Pro-level image generation and editing at the speed you expect from Flash — making the quality, reasoning, and world knowledge you loved about Nano Banana Pro more accessible. Learn more about the model here. The Intelligent Path to Compliance: Transforming Regulatory QC with Google CloudReducing "Refuse to File" (RTF) risks and submission cycle times is critical for life sciences leaders. Google Cloud’s Regulatory Submission Semantic QC Auditor leverages Gemini and RAG architecture to transform Quality Control from a manual burden into an active, intelligent workflow. By automating semantic cross-referencing, narrative coherence checks, and dynamic guidance-based auditing, this solution ensures rigorous accuracy and auditability. Operating within a secure GxP-ready environment, it empowers teams to detect subtle inconsistencies and generate remediation plans without sacrificing data privacy. Learn more. Stop typing, start interacting! The Gemini Live Agent Challenge is here. Build immersive agents that can help you see, hear, and speak using Gemini and Google Cloud. Compete for your share of $80,000+ in prizes and a trip to Google Cloud Next '26!Submissions are open from February 16, 2026 to March 16, 2026. Learn more and register at .devpost.com Feb 9 - Feb 13 Introducing Gemini 3.1 Pro on Google Cloud. 3.1 Pro is a noticeably smarter, more capable baseline for complex problem-solving. We’re shipping 3.1 Pro at scale, building upon our goal to help you transform your business for the agentic future. Learn more about the model’s capabilities here. Gemini 3.1 Pro is available starting today in preview in Vertex AI and Gemini Enterprise. Developers can access the model in preview via the Gemini API in Google AI Studio, Android Studio, Google Antigravity, and Gemini CLI. Automate Storage Compatibility with GKE Dynamic Default Storage ClassesManaging storage across mixed-generation VM clusters in GKE just got easier. With the new Dynamic Default Storage Class, Google Kubernetes Engine automatically selects between Persistent Disk (PD) and Hyperdisk based on a node's specific hardware compatibility. This abstraction eliminates the need for complex scheduling rules and manual pairing, ensuring your volumes "just work" regardless of the underlying infrastructure. By defining both variants in a single class, you reduce operational overhead while maintaining peak performance and cost-efficiency across your entire cluster.Explore automated disk type selection Community TechTalk: AI-Powered Apigee Development with strofa.ioJoin the Apigee community on February 26 for a deep dive into strofa.io. Guest speaker Denis Kalitviansky will demonstrate how this new AI-powered tool automates and orchestrates Apigee development, from local emulators to large-scale hybrid environments. Discover how to scale your API management and streamline team collaboration using the latest in AI-driven automation. Register now to reserve your spot. Jan 26 - Jan 30 Simplify API Governance with Native OpenAPI v3 SupportEliminate integration debt and accelerate deployment velocity with the General Availability of OpenAPI v3 (OASv3) support for API Gateway and Cloud Endpoints. You no longer need to downgrade modern specifications to OASv2. Instead, you can now define API contracts and enforce critical policies—including telemetry, quotas, and security—using native Google-specific extensions directly within your OASv3 files. This update ensures your APIs are secure by design while remaining fully compatible with the modern developer ecosystem and Google Cloud’s AI services.Get started with OpenAPI v3 on API Gateway and Cloud Endpoints. Accelerate API Testing with the New Open Source API TesterStart validating your APIs with API Tester, a simple, YAML-based Test Driven Development (TDD) framework. Designed for the Apigee community, this tool allows you to write human-readable tests, run them instantly via a web client or CLI, and perform deep unit testing on Apigee proxies. With native support for JSONPath assertions and Apigee shared flows, you can verify everything from payload data to internal variables like proxy.basepath without leaving your terminal.Explore the API Tester guide and start testing your proxies today. Secure Sensitive Data with Kubernetes Secrets in Apigee hybridEnhance security in Apigee hybrid by accessing Kubernetes Secrets directly within your API proxies. This hybrid-exclusive feature keeps sensitive credentials within your cluster boundary and prevents replication to the management plane. It supports strict separation of duties: operators manage secrets via kubectl, while developers reference them as secure flow variables—ideal for high-compliance and GitOps workflows.Implement Kubernetes Secrets in your hybrid proxies. See the Console in a Whole New Light: Dark Mode is Now Generally Available in Google CloudElevate your cloud management workflow with Dark Mode, now generally available in the Google Cloud console. We have delivered a modern, cohesive, and accessible experience reimagined for maximum comfort and productivity—especially during extended working hours and low-light environments. Dark Mode can be enabled automatically based on your operating system's preference, or manually through the Settings -> Appearance menu.Switch to Dark Mode today to enjoy a modern, comfortable, and productive environment! Apigee X Networking: PSC or VPC Peering?Deciding how to connect Apigee X? Watch this video to compare Private Service Connect and VPC Peering. We break down northbound and southbound routing, IP consumption, and how to reach targets on-prem or in the cloud. Learn to simplify your architecture and avoid common networking "gotchas" for a smoother deployment.Watch the video. Jan 19 - Jan 23 Bridge the Gap: Excel-to-API Conversion in Apigee PortalsGive your customers more ways to connect! This new article by Tyler Ayers explores how to extend the Apigee Integrated Portal to support direct Excel file uploads. By leveraging SheetJS and custom portal scripts, you can enable users to upload spreadsheets, preview data, and submit it directly to your APIs, all without writing a single line of integration code themselves. It’s a powerful way to simplify onboarding for those who aren't yet API-ready.Learn how to build it. Elevate your applications with Firestore’s new advanced query engineWe have fundamentally reimagined Firestore with pipeline operations for Enterprise edition. Experience a powerful new engine featuring over a hundred new query features, index-less queries, new index types, and observability tooling to improve query performance. Seamlessly migrate using built-in tools and leverage Firestore’s existing differentiated serverless foundation, virtually unlimited scale, and industry-leading SLA. Join a community of 600K developers to craft expressive applications that maximize the benefits of rich queryability, real-time listen queries, robust offline caching, and cutting-edge AI-assistive coding integrations.Learn more about Firestore pipeline operations.
Read original articleOctober 2, 2026
AI agents don't just answer queries — they can autonomously issue refunds, manage inventory, execute multi-step handoffs, and orchestrate sub-agents, to name but a few complex agentic workflows. That frequently requires the agents to maintain internal state in an operational database while dispatching asynchronous actions through a separate messaging or event queue system. And unfortunately for the teams building these applications, managing two systems with disjointed commit points destroys transactional consistency in agentic systems. Today, we are excited to announce the general availability of Spanner queues: native transactional messaging embedded directly within Spanner. Designed specifically for reliable agentic execution, with Spanner queues, creating a message is simply another write in your transaction. An agent's state change and intended downstream actions commit together atomically or fail completely. Compare this to traditional approaches: When a database state update succeeds, but the action dispatch fails, your AI agent decides to act but doesn’t execute. If the message dispatch succeeds but the state transaction rolls back, your agent executes an action based on an invalid state. In asynchronous multi-agent coordination, retries, speculation, and race conditions amplify these failures, forcing developers to build complex outbox patterns, idempotency layers, and reconciliation workers — a heavy reliability tax on agentic architecture. Key capabilities for agentic architectures Spanner queues introduces several core capabilities to support these complex asynchronous workflows without introducing infrastructure overhead. Atomic decide-and-act enqueue. Within a single Spanner read-write transaction, agents can update internal memory or state tables and enqueue tasks to peer agents simultaneously. Backed by Spanner's strict serializability and global external consistency, state changes and execution intent commit as a single atomic unit. Scheduled execution and delays. Queue messages can be dispatched immediately upon commit or scheduled for future delivery. Agentic patterns such as delayed retries, scheduled agent check-ins, or SLA escalation timers can be enqueued transactionally alongside memory updates without requiring external cron schedulers or polling infrastructure. Streaming SQL pull for agent workers. Autonomous agents consume tasks dynamically using streaming SQL reads. Agent runtimes stream incoming tasks, process them as capacity becomes available, and acknowledge task completion within a transaction to guarantee end-to-end task execution state reliability. Episodic memory persistence and handoffs. Agent memory updates — including long-term episodic summaries, reflective state transitions, and context handoffs across sub-agents — can be persisted asynchronously and transactionally via queues. This guarantees that an agent's internal memory remains fully synchronized with its execution history without blocking real-time interactive turns. Why Spanner queues are essential for autonomous agents Transactional exactly-once agent execution: When an agent evaluates tool call results, state modification, reasoning persistence, and downstream tool invocation tasks are saved in one transaction. We guarantee at-least-once delivery and at-most-once ACK, enabling you to achieve exactly-once processing. Robust multi-agent orchestration and handoffs: In multi-agent systems (A2A), handing off state from a primary agent to a specialist agent is represented as a durable, transactionally committed message. Specialist agent workers receive deliverable messages while maintaining a fully auditable lineage of agent interactions. First-class timeouts and human-in-the-loop workflows: Agent workflows frequently require pausing for human approvals or scheduled follow-ups. Spanner queues handles timeout management natively: A single transaction records the pending approval state and schedules an automated escalation message, resolving whichever triggers first. SQL-native observability for agent queues: Inspecting in-flight agent workloads, monitoring task backlogs, or auditing agent execution history can be accomplished with standard SQL queries over queue tables, avoiding opaque message-store black boxes. Beyond agentic workflows Beyond AI agents, Spanner queues serves as a flexible, multi-purpose messaging platform across a variety of traditional event-driven architectures. Whether powering real-time activity feeds in social applications, delivering live updates in news publishing, orchestrating order processing and inventory workflows in retail, or handling high-throughput asynchronous task processing and transaction notifications in financial services, Spanner queues provides a robust foundation for asynchronous message delivery and transactional event-driven workflows within your primary database. Under the hood: Transactional mechanics of Spanner queues Because Spanner queues are represented as first-class relational structures in Spanner, you define, inspect, and manage queues using familiar GoogleSQL. 1. Defining a queue and enqueuing atomically When an agent decides to approve a customer refund, it updates the Orders table and dispatches an execution task to the OrderAgentTasks queue within a single ACID transaction: code_block <ListValue: [StructValue([('code', '-- Assume parent table:\r\n-- CREATE TABLE Orders (\r\n-- OrderId STRING(64) NOT NULL, ...\r\n-- )\r\n-- PRIMARY KEY (OrderId);\r\n\r\n-- Define the transactional queue table\r\nCREATE QUEUE OrderAgentTasks (\r\n OrderId STRING(64) NOT NULL,\r\n TaskId STRING(64) NOT NULL,\r\n TaskType STRING(64) NOT NULL,\r\n Payload JSON NOT NULL\r\n) PRIMARY KEY (OrderId, TaskId, TaskType), INTERLEAVE IN Orders;\r\n\r\n-- Inside a Read-Write Transaction:\r\n-- 1. Update business state atomically\r\n\r\n-- BEGIN TRANSACTION;\r\n\r\nUPDATE Orders\r\nSET Status = \'REFUND_APPROVED\',\r\n UpdatedAt = PENDING_COMMIT_TIMESTAMP()\r\nWHERE OrderId = @orderId;\r\n\r\n-- 2. Enqueue the asynchronous agent action in the same transaction\r\nINSERT INTO OrderAgentTasks (OrderId, TaskId, TaskType, Payload)\r\nVALUES (\r\n @orderId,\r\n @taskId,\r\n \'EXECUTE_REFUND\',\r\n JSON \'{"action": "execute_refund", "amount": 49.99}\'\r\n);\r\n\r\n-- COMMIT;'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443b8c1710>)])]> This ensures that the EXECUTE_REFUND task exists if and only if the order status successfully transitioned to REFUND_APPROVED. 2. Temporal scheduling and atomic cancellation For workflows that depend on time — such as waiting up to 72 hours for a manager's approval before escalating — agents populate the system DeliverTime column to defer message visibility: code_block <ListValue: [StructValue([('code', '-- Schedule an automated escalation check-in 72 hours in the future\r\nINSERT INTO OrderAgentTasks (OrderId, TaskId, TaskType, Payload, DeliverTime)\r\nVALUES (\r\n @orderId,\r\n @escalationTaskId,\r\n \'ESCALATE_UNAPPROVED_ORDER\',\r\n JSON \'{"action": "escalate_to_supervisor"}\',\r\n TIMESTAMP_ADD(CURRENT_TIMESTAMP(), INTERVAL 72 HOUR)\r\n);'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443b8c33d0>)])]> If the manager approves the request after four hours, your application doesn't have to deal with phantom escalation alerts firing days later. In a single transaction, you update the order status and cancel the pending escalation task using a standard SQL DELETE: code_block <ListValue: [StructValue([('code', "-- BEGIN TRANSACTION;\r\n\r\nUPDATE Orders\r\nSET Status = 'MANAGER_APPROVED',\r\n ApprovedBy = @managerId\r\nWHERE OrderId = @orderId;\r\n\r\n-- Atomically cancel the pending delayed escalation task. `ASSERT_ROWS_MODIFIED 1` will\r\n-- act as a safeguard and cause a statement level error.\r\n\r\n-- A statement level error can be captured and the transaction can be\r\n-- user-aborted/cancelled in case the queue entry was already deleted.\r\n-- Otherwise the transaction will complete successfully regardless if the \r\n-- queue entry still exists and you'll only know if a queue entry was deleted by\r\n-- checking the number of rows affected by the DELETE.\r\nDELETE FROM OrderAgentTasks\r\nWHERE OrderId = @orderId\r\n AND TaskId = @escalationTaskId\r\n AND TaskType = 'ESCALATE_UNAPPROVED_ORDER',\r\nASSERT_ROWS_MODIFIED 1;\r\n\r\n-- COMMIT;"), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443b8c3110>)])]> 3. Streaming consumption, lease renewal, and atomic acknowledgment Downstream agent workers consume tasks using the RECEIVE_<QueueName> table-valued function (TVF) over a streaming SQL connection (ExecuteStreamingSql). Spanner automatically manages message leases, returning a unique SpannerLeaseToken and expiration timestamp with each leased task: code_block <ListValue: [StructValue([('code', "-- Step 1: Consume tasks via a long-lived streaming SQL query\r\nSELECT\r\n OrderId,\r\n TaskId,\r\n TaskType,\r\n Payload,\r\n SpannerLeaseToken,\r\n \r\nFROM RECEIVE_OrderAgentTasks(max_duration => '20m');"), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f4440618390>)])]> Because AI agent tasks often involve multi-turn LLM reasoning or external API calls that take longer than default lease windows, workers can actively extend their lease using the RENEWLEASE_<QueueName> function: code_block <ListValue: [StructValue([('code', '-- Step 2: Extend lease ownership during long-running agent execution\r\nSELECT *\r\nFROM RENEWLEASE_OrderAgentTasks(lease_tokens => [@leaseToken]);'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f4440619fd0>)])]> When the agent finishes executing its external tool (passing TaskId as the external API's idempotency key), it opens a read-write transaction to record the final state and acknowledge the message by deleting it with ASSERT_ROWS_MODIFIED 1: code_block <ListValue: [StructValue([('code', "-- Step 3: Atomically checkpoint agent results and ACK the message\r\n-- BEGIN TRANSACTION;\r\n\r\nUPDATE Orders\r\nSET RefundTransactionId = @externalRefundId,\r\n Status = 'REFUND_COMPLETED'\r\nWHERE OrderId = @orderId;\r\n\r\nDELETE FROM OrderAgentTasks\r\nWHERE OrderId = @orderId\r\n AND TaskId = @taskId\r\n AND TaskType = @taskType\r\nASSERT_ROWS_MODIFIED 1;\r\n\r\n-- COMMIT;"), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f4440618cd0>)])]> Using ASSERT_ROWS_MODIFIED 1 protects your system against lease-expiration races. If a worker stalled due to a network pause and its lease expired, another worker may have already processed and deleted the task. When the stalled worker resumes and attempts to execute the statement, ASSERT_ROWS_MODIFIED 1 detects that the queue row is already gone and throws a statement-level error. Catching that error and aborting that transaction prevents stale workers from overwriting newer database state. Spanner change streams vs. Spanner queues Spanner change streams capture database data changes (inserts, updates, and deletes) in near real-time for downstream integration and auditing. While both change streams and queues allow applications to react to data changes, Spanner change streams are designed for continuous change data capture (CDC) and data streaming to downstream analytics or storage. In contrast, Spanner queues are explicitly designed for transactional task orchestration, supporting native message leases, scheduled deliveries, SQL-based pulling, and atomic acknowledgments within read-write transactions. Get started Spanner provides a unified foundation for agentic data, combining relational, hybrid search, graph, and key-value capabilities under strict global consistency. Spanner queues completes the agentic loop by enabling agents to transition seamlessly from reasoning over data to executing transactional actions within a single unified platform. Spanner queues are now generally available. Sign up for the Spanner 90-day free trial and read up our public documentation to start building resilient, exactly-once agentic workloads by creating a queue table in your Spanner database today.
Read original articleOctober 2, 2026
Whether you’re launching microservices in response to sudden traffic spikes, deploying new software releases, or scaling up application replicas, pod startup time is critical to maintaining a fast, responsive user experience for applications running on Google Kubernetes Engine (GKE). Yet, platform engineers and developers face a persistent dilemma: Applications often demand significantly more CPU power during startup than they do during steady-state operations. Sizing CPU requests for normal, steady-state usage leads to CPU throttling during launch, which can result in sluggish cold starts and readiness probe timeouts. On the flip side, over-provisioning baseline CPU requests to satisfy short-lived startup bursts wastes valuable compute resources, inflating infrastructure bills.Today, we are excited to announce CPU startup boost for GKE in preview. Integrated directly into GKE's Vertical Pod Autoscaler (VPA), CPU startup boost dynamically elevates a container's CPU allocation during initialization and seamlessly scales it back to baseline steady-state levels once the application is ready - all without restarting your containers. Why modern applications need extra CPU at boot time When a new container launches, it may perform intensive initialization tasks before it begins serving user requests. Depending on your tech stack, the following startup workloads require substantial CPU cycles: Java JVM applications: Frameworks like Spring Boot require high CPU burst capacity for class loading, classpath scanning, instantiating dependency injection containers, and running Just-in-Time (JIT) compilation. Node.js servers: Apps parse JavaScript files, build complex module dependency trees (require/import), and execute V8 engine optimization and JIT compilation passes during initial execution. Python and AI/ML microservices: These services spend initial cycles importing heavy libraries (such as PyTorch, NumPy, or LangChain), compiling .pyc bytecode, establishing ORM database schemas, and pre-loading cache structures. If you size CPU requests strictly for steady-state performance, these initialization workloads experience CPU throttling on launch, delaying readiness probes. To prevent slow cold starts, teams frequently overprovision CPU requests. However, once the application stabilizes, those extra CPU resources sit idle, increasing your cloud spend without adding value. How CPU startup boost can helpCPU Startup Boost solves this by giving your workloads temporary vCPU "boosts" during launch, and automatically returning them to baseline once initialization completes.Key benefits:Faster cold starts: Reduce application initialization times by up to 2x, accelerating auto-scaling responsiveness during unexpected traffic surges.Optimized cloud spend: Right-size steady-state CPU requests to fit actual runtime needs rather than paying for idle startup headroom.Zero pod restarts: Dynamic resource resizing happens live inside the running container.Flexible policy controls: Apply simple pod-level multiplier factors (e.g., 2x CPU during startup) or define granular, container-specific rules for complex multi-container pods. Under the hood: Kubernetes In-place Pod Resize Historically, changing a pod's resource requests or limits required deleting and recreating the pod. This disruptive process triggered container restarts, cache invalidation, and node rescheduling overhead. To fix that, CPU startup boost builds on Kubernetes In-place Pod Resize (IPPR). Tracked under KEP-1287, IPPR introduced dynamic, in-place resource mutation. Introduced as Alpha in Kubernetes 1.27, promoted to Beta in v1.33, and graduating to General Availability (GA) in v1.35, IPPR allows the Kubernetes control plane and kubelet to update container CPU and memory requests on running pods without restarting the container process. GKE leverages IPPR within the VPA to apply startup CPU boosts at pod admission and smoothly step them down post-readiness. How CPU startup boost works (pod lifecycle overview) CPU startup boost operates across three distinct phases: Admission phase: When you deploy a pod, the VPA admission webhook intercepts the creation request. It calculates the elevated CPU request based on your policy (e.g., 2x multiplier or +2 vCPUs) and injects the boosted CPU request along with tracking annotations into the pod spec. Startup phase: The pod is scheduled and initialized with the boosted CPU allocation. Your application completes class loading, JIT compilation, or module parsing at top speed without experiencing CPU throttling. Unboosting phase: As soon as the pod's readinessProbe passes (plus any configured durationSeconds cooldown delay), the VPA updater issues an in-place resize request. The CPU request steps back down to your baseline level while the container continues running uninterrupted. Prerequisites and availability CPU startup boost is available today in preview on GKE: GKE version: Version 1.36.0-gke.4447000 or later on Standard and Autopilot clusters. Cluster Modes: Enabled natively on GKE Autopilot (VPA is active by default). On GKE Standard, simply ensure Vertical Pod Autoscaling (VPA) is enabled. Workload Support: Works with standard Kubernetes controllers, including Deployments and StatefulSets. Getting started: Configuring CPU startup boost Configuring CPU startup boost is as simple as adding a startupBoost section to your manifest. Example 1: Pod-level boost with fixed steady-state (updateMode: "Off") If you want to use VPA purely for startup boost while keeping steady-state CPU requests locked to your manifest definitions, set updateMode to "Off": code_block <ListValue: [StructValue([('code', 'apiVersion: "autoscaling.k8s.io/v1"\r\nkind: \r\nmetadata:\r\n name: java-app-startup-boost\r\n namespace: default\r\nspec:\r\n targetRef:\r\n apiVersion: "apps/v1"\r\n kind: Deployment\r\n name: java-app\r\n updatePolicy:\r\n updateMode: "Off"\r\n startupBoost:\r\n cpu:\r\n type: "Factor"\r\n factor: 2\r\n durationSeconds: 10'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443bd4f990>)])]> In this example, GKE doubles the container's CPU request during launch and holds the boosted allocation for 10 seconds after readiness probes pass before scaling back to baseline. Example 2: Combining startup boost with continuous VPA auto-scaling If you want GKE to boost CPU during launch and continuously optimize steady-state resources post-startup, set updateMode to "InPlaceOrRecreate": code_block <ListValue: [StructValue([('code', 'apiVersion: "autoscaling.k8s.io/v1"\r\nkind: \r\nmetadata:\r\n name: nodejs-app-vpa\r\n namespace: default\r\nspec:\r\n targetRef:\r\n apiVersion: "apps/v1"\r\n kind: Deployment\r\n name: nodejs-service\r\n updatePolicy:\r\n updateMode: "InPlaceOrRecreate"\r\n startupBoost:\r\n cpu:\r\n type: "Factor"\r\n factor: 3\r\n durationSeconds: 15'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443bd4ea10>)])]> Example 3: Granular container-level boost For pods running sidecars (such as logging agents or service mesh proxies) that do not require extra CPU on boot, target specific app containers: code_block <ListValue: [StructValue([('code', 'apiVersion: "autoscaling.k8s.io/v1"\r\nkind: \r\nmetadata:\r\n name: app-container-boost\r\nspec:\r\n targetRef:\r\n apiVersion: "apps/v1"\r\n kind: Deployment\r\n name: API-gateway\r\n updatePolicy:\r\n updateMode: "Off"\r\n resourcePolicy:\r\n containerPolicies:\r\n - containerName: "web-app"\r\n mode: "Off"\r\n startupBoost:\r\n cpu:\r\n type: "Quantity"\r\n quantity: "2"\r\n durationSeconds: 5'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443bd4e310>)])]> Verifying startup boost in your cluster You can verify that GKE applied and downscaled the startup boost using kubectl: 1. Inspect pod annotations: Check for the vpaCpuStartupBoost tracking annotation: code_block <ListValue: [StructValue([('code', 'kubectl get pod <POD_NAME> -o yaml'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443baab710>)])]> Look for annotations indicating the original baseline and boosted CPU requests. 2. Monitor in-place resize events: Confirm that GKE downscaled the CPU request back to baseline after readiness: code_block <ListValue: [StructValue([('code', 'kubectl get events --field-selector reason=InPlaceResizedByVPA'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443b9d7750>)])]> An event with reason=InPlaceResizedByVPA confirms successful in-place downscaling post-startup. Best practices for production workloads Pairing with Horizontal Pod Autoscaler (HPA): When using HPA alongside CPU startup boost, ensure a robust readinessProbe is defined and keep durationSeconds short (e.g., 0s–10s). This prevents HPA from falsely interpreting initialization CPU spikes as high steady-state load. Handle traffic spikes with GKE capacity buffers API: By reducing the startup tax at scale, you can achieve higher workload density on fewer nodes to improve overall utilization. Consider adopting the GKE capacity buffers API to absorb sudden traffic surges with minimal operational overhead while maintaining strict SLOs. GKE Autopilot resource ratios: On GKE Autopilot, remember that pods must maintain valid CPU-to-memory ratios. Ensure baseline memory allocations accommodate the boosted CPU ratio during startup. Get started today CPU startup boost gives GKE users the best of both worlds: lightning-fast cold starts for CPU-intensive workloads like Java, Node.js, and Python, paired with maximum resource efficiency and lower cloud costs. Ready to accelerate your GKE workloads? Explore the GKE CPU startup boost documentation. Learn more about Vertical Pod Autoscaling on GKE. Try CPU startup boost on your GKE Standard or Autopilot clusters running GKE 1.36.0-gke.4447000 or later!
Read original articleOctober 2, 2026
Claude Desktop on Amazon Bedrock is limited to the model's knowledge cutoff without web search. In this post, we walk through connecting Claude Desktop to Web Search using Amazon Bedrock AgentCore Gateway, with JWT-based inbound authentication through AWS IAM Identity Center and Amazon Cognito.
Read original articleOctober 2, 2026
On this episode of Stock Movers: - Nike (NKE) shares continue their slide as it is cutting jobs and overhauling its business as results deteriorate, with a restructuring plan to save $2.5 billion over the next five years. The company expects a high-single-digit revenue decline this year, which is worse than the 2.4% drop projected by analysts, and shares of Nike fell as much as 9.7% in New York on Friday. - Broadcom (AVGO) shares are moving on news the company's Wall Street syndicate are starting to gather $60 billion of fresh AI chip financing to benefit Anthropic and other companies. - Fair Isaac Corp. (FICO) shares are rising after the company launched the FICO Mortgage Direct License Program, and Bill Pulte signaled he wasn't purposefully targeting the company, which may have contributed to the stock's rise on Thursday. (Source: Bloomberg)
Read original articleOctober 2, 2026
October 2, 2026
Anthropic warns government attitudes may hurt customer ties, IPO prospectus shows: Reuters CNBC
Read original articleOctober 2, 2026
A video showing the September AI updates
Read original articleOctober 2, 2026
Initially launched in 2019, the Nvidia Shield TV Pro now retails for $299.99.
Read original articleOctober 2, 2026
Developers have long been able to customize Claude Code to their preferences, via settings, persistent instructions in CLAUDE.md, hooks, and The post “No reason why everyone should have an identical Claude experience”: Anthropic’s mods let you change Claude Code’s look and behavior appeared first on The New Stack.
Read original articleOctober 2, 2026
How quickly things change in the artificial intelligence era. Just a few months after everyone was scrambling to infuse AI into every enterprise operation — and frankly they still are, as agents have captured the enterprise imagination — everyone now is saying, “Whoa, where’s the brake pedal?” That’s why controlling agents is the next infrastructure […] The post Despite IPO jitters and AI safety worries, Anthropic sticks to a 2026 offering appeared first on SiliconANGLE.
Read original articleOctober 2, 2026
Nvidia Corp. shares touched an intraday high for the first time since May before trimming those gains and closing just short of a record as investors piled back into the stock after a two-month selloff that wiped out more than $1 trillion of market value.
Read original articleOctober 2, 2026
Broadcom’s Wall Street syndicate is starting to gather $60 billion of fresh AI chip financing to benefit Anthropic PBC and other companies, according to people with knowledge of the matter. Carmen Reinicke has more on "Bloomberg Open Interest." (Source: Bloomberg)
Read original articleOctober 2, 2026
OpenAI has parted ways with three researchers who allegedly leaked confidential information to an outside AI safety organization, according to the Wall Street Journal. The article Three firings and a fourth departure shake up OpenAI's safety team appeared first on The Decoder.
Read original articleOctober 2, 2026
Broadcom Starts Amassing $60 Billion to Fund Chips for Anthropic Bloomberg.com
Read original articleOctober 2, 2026
Microsoft Corp.’s Azure and Amazon Web Services are set to be designated under the European Union’s strict rulebook for Big Tech.
Read original articleOctober 2, 2026
The opportunity: Personalization as a revenue engineEvery second a shopper spends...
Read original articleOctober 2, 2026
Exclusive-Anthropic warns government attitudes may hurt customer ties, IPO prospectus shows WTVB
Read original articleOctober 2, 2026
PewDiePie unveils ‘uncensored’ Ajax AI model built to run on home PCs — creator says OpenAI banned him twice over model distillation used to build his product Tom's Hardware
Read original articleOctober 2, 2026
Microsoft AI has released MAI-Transcribe-2-Streaming, a new model for real-time transcription. The article Microsoft AI releases new transcription and text-to-speech models for voice agents appeared first on The Decoder.
Read original articleOctober 2, 2026
NYC Already Battling AI Attacks as Council Prepares to Grill Artificial Intelligence Leaders The City Reporter
Read original articleOctober 2, 2026
How Do OpenAI And AWS Deals Reshape Synopsys’s Design Automation Outlook? Trefis
Read original articleOctober 2, 2026
It had been reported that Anthropic was talking to religious leaders to help guide Claude’s ethics, and a religious leader had spoken about... The post Indian Monk Swami Sarvapriyananda Talks About How Anthropic Called Religious Leaders To Help Train Claude appeared first on OfficeChai.
Read original articleOctober 2, 2026
Enterprise AI agents need persistent memory to execute complex, multi-day workflows and long-horizon tasks. In this blog, we examine how a 2-tier memory architecture using Memorystore for Valkey for short-term buffer memory and AlloyDB AI for long-term persistent memory can help reduce token spend by up to 70%, while maintaining critical data and enterprise guardrails. Imagine building a personalized travel agent designed to help users book vacations. The user interacts with the agent many times over the course of several days, asking questions that range from brainstorming itineraries to actual purchase intent. To provide a truly seamless experience, this agent must remember flight preferences (e.g. “I only want non-stop flights”), hotel budgets, and dietary restrictions (e.g. “I need Gluten Free dining options”) established in previous sessions. More importantly, it has to hold onto these core facts even when the conversation gets deep into the weeds of sightseeing recommendations and itinerary planning. The agent must ensure that all the follow-up questions and exciting details about places to visit doesn’t cause it to forget or overwrite the user's fundamental requirements and decisions. Stateful workflows inherently conflict with LLM’s stateless nature AI agents are being used for multi-turn conversations and long-running workflows, but large language models (LLMs) remain stateless across sessions. When a user returns to an agent days later, the model starts with an empty context window. Unless your application is built to reconstruct past context using long-term agent memory, your users have to explain their goals and context all over again, resulting in a frustrating and fragmented experience. With million-token context windows now the norm, a common shortcut to this problem is "context stuffing" - dumping everything you can fit into the prompt at every turn, from raw chat histories to tool execution logs. In fact, this was a common pattern in the early days of AI model usage. But this shortcut quickly creates issues at scale: token costs multiply with every message, response times can drag out past 30+ seconds for otherwise simple prompts, and the model starts suffering from "lost in the middle" degradation, overlooking critical instructions buried in mountains of prompt text. Another common workaround is to use rolling summaries; asking an LLM to periodically compress older messages into a summary paragraph. While this trims prompt size, LLM-based summarization is inherently lossy. After a few rounds of compression, subtle but important details get filtered out as background noise. A few turns later, your agent quietly breaks the exact constraints you set earlier. Clearly, you need a more scalable approach for keeping a memory from previous conversations or multi-turn tasks, but without degrading the experience or creating new bottlenecks. Implementing a 2-tier memory architecture To build reliable, cost-effective enterprise agents that respect your guardrails and constraints, we recommend a 2-tier memory architecture: Short-term session buffer: Caches active conversation turns in memory using a token-bounded sliding window, allowing the context window size to remain stable across multiple rounds, even across devices, while keeping the latest messages fresh. This tier requires sub-millisecond, high-throughput lookups on every turn, making Memorystore for Valkey well suited for maintaining active session state. Long-term persistent memory: Stores important facts, user preferences, and episodic facts across sessions. This tier requires transactional integrity, data governance, and hybrid retrieval across relational data and vectors - capabilities provided natively by AlloyDB AI. While it’s possible to store both long-term memory and active session buffers directly in a relational database, a two-tier architecture with an in-memory cache provides better performance and scalability. Active session buffers are highly ephemeral and require sub-millisecond, high-throughput updates on every single conversation turn. Handling these rapid-fire writes in an in-memory key-value cache prevents write amplification and table bloat in your relational database, which would otherwise require frequent row deletions and intensive vacuuming. This is analogous to adding a caching tier in front of your database to offload high-frequency lookups for hot rows. The division of labor keeps your primary database lean and responsive, allowing it to focus its resources on what it is designed for: transactional consistency, complex hybrid vector search, and long-term analytical query execution. By pairing short-term caching in Memorystore for Valkey with native AlloyDB AI capabilities, you can run entity extraction, memory compaction, cross-session memory, and hybrid retrieval directly inside the database tier, keeping active prompts lean, fast, and cost-efficient. aside_block <ListValue: [StructValue([('title', 'Get started with a 30-day AlloyDB free trial instance'), ('body', <wagtail.rich_text.RichText object at 0x7f443b9a02d0>), ('btn_text', ''), ('href', ''), ('image', None)])]> Understanding the four memory types To organize long-term agent state effectively, we further divide agent memory into four complementary types across the short-term and long-term storage tiers we described above: Memory type What it stores Storage layer Lifespan Buffer (Short-term) Recent raw conversation turns Memorystore for Valkey Active session Summary memory Compressed history of older turns, commonly referred to as “compaction” Memorystore for Valkey Multi-turn window Episodic memory Past actions, events, and tool outputs AlloyDB for PostgreSQL (Hybrid retrieval with structured SQL + full-text search + vector) Permanent Entity & rule memory User preferences, constraints, and vetoes AlloyDB for PostgreSQL (Hybrid retrieval with structured SQL + full-text search + vector) Permanent By isolating short-term conversation context from structured long-term rules, your agent retrieves relevant context on demand without filling token windows with raw interaction logs. The tiered memory architectural blueprint The diagram below outlines the read and write paths connecting the application orchestration layer, the Memorystore for Valkey short-term buffer, and the AlloyDB AI long-term repository: The system operates across two coordinated execution paths: The read path: When a user asks a question, the application fetches the active sliding window from Memorystore for Valkey, runs in-database query normalization using ai.generate, and queries AlloyDB using ai.hybrid_search to retrieve scoped entity rules and relevant episodic facts. The write path: After generating the response, the turn is immediately cached in Memorystore for Valkey. An asynchronous background queue worker extracts structured entities from the exchange and writes them directly into AlloyDB, where transactional auto-embeddings immediately compute and store vector representations in the database. Business impact and ROI In our benchmark testing across multi-turn development dialogues (45+ turns with heavy tool executions), separating short-term caching from long-term persistence delivered measurable cost and performance improvements compared to naive context stuffing: Metric / dimension Naive context stuffing Tiered memory (AlloyDB + Valkey) Net business impact Active prompt size (turn 45) 747,033 tokens 83,262 tokens 88.9% smaller prompt Turn 45 response latency 33.5 seconds 6.7 seconds 80.0% faster response Per-turn response wait time 33.5 seconds 4.2s – 6.7s 36% to 80% reduction Cumulative session tokens 17.9M tokens 4.09M tokens 72.0% token & cost savings Rule & constraint recall Degrades over turns Does not degrade ACID-preserved recall Note: The metrics above reflect internal benchmark results from a simulated developer workload that mimics a real-world enterprise AI pair-programming assistant interacting with a developer over multiple sessions, projects, and context switches. Actual savings and latencies vary based on prompt structure, query frequency, and data volume. These results demonstrate how tiered memory changes agent unit economics: instead of an escalating cost curve on every additional turn, prompt sizes remain bounded, reducing ongoing LLM API expenses while keeping response times fast. Core AlloyDB AI technical advantages AlloyDB AI reduces the operational overhead of implementing persistent agent memory by embedding core AI functions directly into the database engine: Transactional in-database auto-embeddings (ai.initialize_embeddings): AlloyDB automatically generates vector embeddings for text columns using a native integration with Agent Platform (formerly Vertex AI), generating up to 3,000 embeddings per second. Using incremental_refresh_mode => 'transactional', AlloyDB keeps embeddings up to date as source data changes within the same transaction, removing the need for custom embedding pipelines, external schedulers, or complex retry logic. In-database generative AI functions (ai.generate): AlloyDB allows you to execute foundation models, such as Gemini, directly from SQL queries. You can use this for in-database query decomposition - breaking compound user questions into single-aspect sub-queries and resolving relative time phrases (like "last session") into explicit identifiers - without making separate roundtrips from your application. Native hybrid search with built-in Reciprocal Rank Fusion (ai.hybrid_search): AlloyDB provides a built-in SQL function that executes Reciprocal Rank Fusion (RRF) directly inside the engine. It combines vector cosine similarity (<=> over HNSW or ScaNN indexes) with PostgreSQL full-text search (using BM25, RUM, or GIN) in a single database call, blending semantic matching with exact keyword retrieval while supporting metadata filter pushdown (filter_condition) for improved performance and deterministic scope isolation. Direct Agent Platform integration with IAM credentials: AlloyDB connects directly to Agent Platform foundation models over Google Cloud's private network using Google Cloud IAM service account roles and database authentication, avoiding the need to store, rotate, or pass API keys in application code. Unified operational, vector, and governance engine: AlloyDB consolidates relational business data, vector embeddings, full-text indexes, and enterprise permissions in a single ACID-compliant PostgreSQL database, avoiding data drift and integration complexity across separate operational and vector databases. Key implementation patterns Below are the core database patterns used to configure the 2-tier memory architecture. For complete, runnable Python and SQL scripts, refer to the companion AlloyDB Agent Memory Codelab. 1. Setting up schema and auto-embeddings In AlloyDB, install the necessary extensions and define the agent_entities table with structured metadata, a generated tsvector column for full-text search, and a vector embedding column. code_block <ListValue: [StructValue([('code', "-- 1. Enable AI extensions\r\nCREATE EXTENSION IF NOT EXISTS google_ml_integration CASCADE;\r\nCREATE EXTENSION IF NOT EXISTS vector CASCADE;\r\nCREATE EXTENSION IF NOT EXISTS rum CASCADE;\r\n\r\n-- 2. Create structured entity & preference table\r\nCREATE TABLE IF NOT EXISTS agent_entities (\r\n entity_id UUID PRIMARY KEY DEFAULT gen_random_uuid(),\r\n user_id TEXT NOT NULL,\r\n entity_name TEXT NOT NULL,\r\n project_id TEXT DEFAULT 'global',\r\n session_id TEXT,\r\n scope TEXT NOT NULL DEFAULT 'session',\r\n summary TEXT NOT NULL,\r\n summary_embedding VECTOR(768),\r\n summary_tsv TSVECTOR GENERATED ALWAYS AS (\r\n to_tsvector('english', entity_name || ' ' || summary)\r\n ) STORED,\r\n updated_at TIMESTAMPTZ DEFAULT NOW(),\r\n UNIQUE (user_id, entity_name)\r\n);"), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f44403d18d0>)])]> Then, generate embeddings using ai.initialize_embeddings. Using transactional mode ensures the embeddings are kept up to date as source data changes. code_block <ListValue: [StructValue([('code', "-- Register transactional in-database auto-embedding\r\nCALL ai.initialize_embeddings(\r\n model_id => 'text-embedding-005',\r\n table_name => 'agent_entities',\r\n content_column => 'summary',\r\n embedding_column => 'summary_embedding',\r\n incremental_refresh_mode => 'transactional',\r\n batch_size => 10\r\n);"), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443ba96590>)])]> Finally, create the HNSW vector index and the RUM full-text search index to ensure your hybrid searches are fast and efficient. code_block <ListValue: [StructValue([('code', '-- Create vector and full-text indexes\r\nCREATE INDEX IF NOT EXISTS agent_entities_embedding_idx\r\n ON agent_entities USING hnsw (summary_embedding vector_cosine_ops);\r\n\r\nCREATE INDEX IF NOT EXISTS agent_entities_tsv_idx\r\n ON agent_entities USING rum (summary_tsv rum_tsvector_ops);'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443ba96790>)])]> 2. Querying long-term memory with native hybrid search On the read path, retrieve relevant long-term entities using ai.hybrid_search. This native SQL function executes Reciprocal Rank Fusion (RRF) directly in AlloyDB, seamlessly reranking and combining vector similarity search and full-text keyword search results in a single database query: code_block <ListValue: [StructValue([('code', 'def retrieve_hybrid_entities(\r\n conn,\r\n user_id: str,\r\n project_id: str,\r\n query_text: str,\r\n query_vector_literal: str,\r\n limit: int = 3\r\n) -> dict[str, Any]:\r\n """Queries long-term memory using AlloyDB native hybrid_search (RRF)."""\r\n filter_cond = f"user_id = \'{user_id}\' AND (project_id = \'{project_id}\' OR scope = \'global\')"\r\n \r\n search_inputs = [\r\n json.dumps({\r\n "data_type": "vector",\r\n "weight": 0.4,\r\n "table_name": "agent_entities",\r\n "key_column": "entity_name",\r\n "vec_column": "summary_embedding",\r\n "distance_operator": "<=>",\r\n "limit": 10,\r\n "query_vector": query_vector_literal,\r\n "filter_condition": filter_cond\r\n }),\r\n json.dumps({\r\n "data_type": "text",\r\n "weight": 0.6,\r\n "table_name": "agent_entities",\r\n "key_column": "entity_name",\r\n "text_column": "summary_tsv",\r\n "limit": 10,\r\n "ranking_function": "ts_rank",\r\n "query_text_input": query_text,\r\n "filter_condition": filter_cond\r\n })\r\n ]\r\n\r\n query_sql = """\r\n SELECT e.entity_name, e.summary, e.project_id, e.scope, e.updated_at\r\n FROM ai.hybrid_search(\r\n search_inputs => %s::JSONB[],\r\n include_json_output => false\r\n ) h\r\n JOIN agent_entities e ON e.entity_name = h.id\r\n WHERE e.user_id = %s\r\n LIMIT %s;\r\n """'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443bab2d50>)])]> 3. In-database memory compaction with AI functions To manage long-term storage growth without writing custom pruning scripts, you can run automated extraction and compaction queries directly in AlloyDB to identify the important parts which can benefit from being stored. This pattern uses a SQL common table expression (CTE) with ai.generate to consolidate older episodic entries into a high-density summary: code_block <ListValue: [StructValue([('code', "-- Consolidate older episodic logs into a permanent summary\r\nWITH old_events AS (\r\n SELECT document AS content\r\n FROM langchain_pg_embedding\r\n WHERE cmetadata->>'user_id' = 'user_dev_42'\r\n AND created_at < NOW() - INTERVAL '30 days'\r\n ORDER BY created_at ASC\r\n LIMIT 50\r\n),\r\nconsolidated AS (\r\n SELECT ai.generate(\r\n 'Summarize these historical events into a dense memory paragraph:\\n' || string_agg(content, E'\\n'),\r\n model_id => 'gemini-3.5-flash'\r\n ) AS summary_text\r\n FROM old_events\r\n)\r\nINSERT INTO agent_entities (user_id, entity_name, summary, updated_at)\r\nSELECT 'user_dev_42', 'longterm_session_summary', summary_text, NOW()\r\nFROM consolidated\r\nWHERE summary_text IS NOT NULL\r\nON CONFLICT (user_id, entity_name)\r\nDO UPDATE SET summary = EXCLUDED.summary, updated_at = NOW();"), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443bfd1590>)])]> For example, a long interaction regarding the complexities of changing flights with kids can result in a summary of “I prefer non-stop flights”. 4. Connecting the 2-tier memory architecture to an ADK agent With the core 2-tier memory architecture configured, you can now extend the default ADK Memory provider to use this 2-tier memory architecture as shown in the accompanying Codelab (e.g. ). To attach the long-term memory to an ADK agent, you simply provide it as a tool (e.g. longterm_memory_tool) like this: code_block <ListValue: [StructValue([('code', 'from adk_memory_provider import \r\n\r\nagent = Agent(\r\n name="adk_memory_agent", model=GEMINI_MODEL, instruction="Initial instruction",\r\n tools=[long_term_memory_tool, run_command_tool],\r\n before_tool_callback=guardrail.create_before_tool_callback(USER_ID, "CloudRetail")\r\n)'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f443b9b2bd0>)])]> Enterprise governance and multi-tenant security Running agent memory in enterprise production environments requires strict security boundaries and access controls. First of all, we need to maintain scope and multi-tenant isolation. By indexing user_id, project_id, and scope columns in agent_entities and enforcing PostgreSQL Row-Level Security (RLS), you can isolate memory stores across departments, teams, and individual users within the same database cluster. Parameterized Secure Views (PSV) offer another layer of deterministic application-level security, helping you protect against malicious prompts and overly-broad SQL queries. In addition, we need to provide automated memory lifecycle management as shown in the implementation pattern above. Combining scheduled SQL compaction queries with time-based partition pruning helps maintain predictable database footprint and query latencies over time. See the accompanying Codelab for more details on this approach. Summary and next steps Decoupling active context windows from persistent storage is a practical approach to building production-ready AI agents. By pairing Memorystore for Valkey for sub-millisecond session caching with AlloyDB AI for transactional long-term storage, you can achieve substantial token cost savings and faster response times while maintaining strict business rules throughout long-horizon tasks and many-turn agentic experiences. To get started: Step through the complete hands-on tutorial in the companion AlloyDB Agent Memory Codelab to deploy the working 2-tier memory architecture. Learn more about database-side machine learning features in the AlloyDB AI documentation. Explore guides on generating auto vector embeddings and running hybrid vector search.
Read original articleOctober 2, 2026
Better Buy: Microsoft or Alphabet? The Globe and Mail
Read original articleOctober 2, 2026
Hong Kong users caught off guard as Anthropic tightens VPN access to Claude South China Morning Post
Read original articleOctober 2, 2026
Google’s James Manyika: The AI Industry Can’t Police Itself Alone bloomberg.com
Read original articleOctober 2, 2026
OpenAI fires 3 safety researchers accused of sharing confidential company information: report Fox Business
Read original articleOctober 2, 2026
arXiv:2609.38349v1 Announce Type: new Abstract: Modern agentic systems combine an AI model with a harness that controls execution and environmental interactions. Harness design strongly affects long-horizon performance, yet its combinatorial search space demands substantial human effort that must be repeated as models change. Existing automated methods explore this space narrowly, optimizing only components such as prompts or skills or becoming trapped by fixed, exploitative search strategies. We introduce MILO (Meta-evolutionary Island Orchestration), a framework that co-evolves agent harnesses and the strategy used to discover them. MILO combines: (i) hierarchical lineage memory over island-based trees, using rejected mutations as negative evidence; (ii) per-island mutator agents that rewrite complete harnesses using global search history and parent-specific feedback; and (iii) an orchestrator that adapts search through lineage grafting and speciation, mutator reassignment and curriculum revision. Across Terminal-Bench 2.1, PaperBench, and DeepSWE, MILO-discovered harnesses outperform eight state-of-the-art harnesses and six search methods using frontier (Opus 4.8) and open-weight (gpt-oss-120b) models. With Opus 4.8, MILO improves resolution over its initial harness by $+12.0\%$, $+28.3\%$, and $+10.3\%$, respectively, compared with best prior-search gains of $+4.5\%$, $+18.3\%$, and $0\%$. On Terminal-Bench 2.1, it achieves $86.1 \pm 2.0\%$, exceeding the official leaderboard's top entry ($83.8 \pm 2.3\%$) while using 26\% fewer tokens than its initial harness. On EinsteinArena open problems, MILO improves best-known upper bounds for Erd\H{o}s minimum-overlap ($0.3808586 \to 0.3808568$) and the first and third autocorrelation inequalities ($1.50274365 \to 1.50274360$; $1.45081 \to 1.44889$).
Read original articleOctober 2, 2026
arXiv:2610.00253v1 Announce Type: new Abstract: Audits of AI visibility summarise the brand recommendations of deployed language models into per-system profiles. We test whether such a profile describes the system on one corpus of 6,475 stored responses (6,324 analysable) collected between December 2025 and February 2026 from five deployed endpoints across gift-recommendation, corporate-reputation and category-ownership queries. The collection harness cut many answers short: 83.1% of Gemini 3 Flash answers in category ownership end mid-sentence under a 1,024-token output cap. With every answer cut to its first 800 characters, a character n-gram classifier cross-validated by prompt attributes one response to GPT-5.2, Gemini 3 Flash, Gemini 3 Flash with search, Grok or Perplexity sonar-pro with 97.84% accuracy (5,028 responses, 383 prompts, majority class 31.5%, 30 split seeds). Length alone falls to the majority rate, 24 formatting statistics reach 95.79%, and masking brand names and capitalised tokens leaves 97.72%. Held-out query conditions keep 97.43% weighted by size and 88.0% unweighted; in a retrieval-grounded arm that changes the harness, no Grok answer is attributed to Grok (0/120). Aggregated into 50 model-by-domain-by-condition units, twelve behavioural features separate four systems at 66.53% under grouped cross-validation, against a label-permutation null with mean 33.71% and 95th percentile 46.0%. Across domains the aggregate profile fails: a forest trained on category-ownership units assigns all 22 gift units to the wrong system, consistent with a reversal in brand volume (8.41 against 0.94 brands per response in gifts, 3.01 against 3.91 in category ownership), while single responses transfer at 89.92% balanced accuracy. The surface form of an answer carries the system across the query domains tested; aggregated brand behaviour does not, and the uncrossed design cannot separate the system from the domain or the harness.
Read original articleOctober 2, 2026
OpenAI says rogue agents may have affected more than 100 organizations The Washington Post
Read original articleOctober 2, 2026
OpenAI fires workers for mishandling 'sensitive information' BBC
Read original article