Nvidia CEO on AI Market Turmoil: ‘All of This Is Going to Pass’
Nvidia Corp. Chief Executive Officer Jensen Huang took a sanguine view toward the latest AI stock-market rout, saying the benefits of the technology will soon outweigh the concerns of investors.
Chat GPT becomes a full Chrome browser assistant that reads and acts on your open tabs
OpenAI's updated Chrome extension lets ChatGPT access open browser tabs, sum up content, and use "Computer Use" in Work mode to fill out forms or compare products across several tabs. It is open to all ChatGPT plans. The article ChatGPT becomes a full Chrome browser assistant that reads and acts on your open tabs appeared first on The Decoder.
Day 0 support for Reflection’s Beam on Google Cloud: 5x faster perf with llm-d and NVIDIA Dynamo
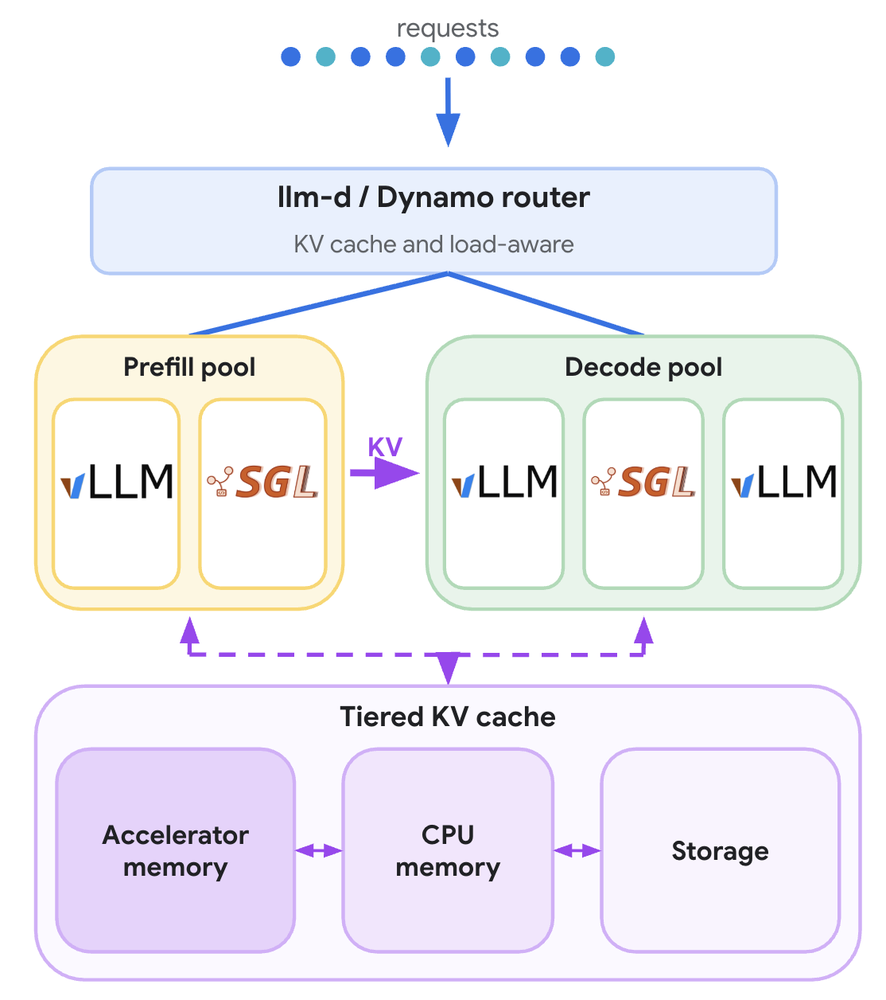
Today, Reflection released Beam, its first open-weight model built to give developers, researchers, and enterprises open control and customization for frontier software engineering and long-horizon agentic tasks. Released under a permissive Apache 2.0 license with BF16, FP8, and NVFP4 checkpoints available at launch, Beam sets a new standard for inference efficiency in the 500B-parameter class by solving complex reasoning and coding problems with 3x to 4x higher reasoning compute efficiency than comparable open models. Alongside today’s release, Google Cloud is announcing day 0 support and ready-to-run deployment recipes for serving Beam on Google Cloud AI Hypercomputer and NVIDIA AI Infrastructure. To help developers get the full benefit of Beam’s token efficiency in production, we worked with Reflection to optimize performance of the underlying serving stack using llm-d (with vLLM) and NVIDIA Dynamo (with SGLang) on Google Cloud: "By deploying our Beam model on Google Cloud, we achieved up to 5x higher performance and 8x lower latency to optimize serving of agentic workloads." - Joe Spisak, VP of Product & Head of Open Source, Reflection With today’s day 0 release on Google Cloud, developers get: Compounding model and system efficiency: Combining Beam’s 3x to 4x reasoning compute efficiency with system-level optimizations on A4X Max instances (NVIDIA GB300 NVL72) for up to 5x higher throughput and 8x lower latency,* and G4 VMs (NVIDIA RTX PRO 6000) for up to 2x higher throughput and 8x lower latency.* High-efficiency multi-turn serving: KV-cache-aware routing, prefill/decode disaggregation, speculative decoding and hierarchical KV cache offloading to Host DRAM and Local SSD reduce redundant prompt recomputation across long coding sessions. Turnkey optimized deployment: Our recommended performance optimized recipes for agentic workloads with llm-d and NVIDIA Dynamo are available in AI-Hypercomputer/gpu-recipes, llm-d repo and Model Garden in Gemini platform with a few clicks. *Based on customer benchmarking Scaling inference requires system-level optimization When evaluating models for agentic coding and tool use, inference efficiency happens at two distinct layers: how efficiently the model reasons and how efficiently the serving system executes multi-turn loops. Model-level efficiency: Reflection’s Beam Reflection designed Beam (~501B total parameters with ~23B active parameters per token, and an approximately 1M-token context window) specifically for text-native software engineering and multi-step tool use. It plugs directly into the coding harnesses developers already use, including Reflection’s Mirror CLI, Claude Code, Hermes, OpenCode, and , to resolve GitHub issues, run CLI and DevOps workflows, and complete long-horizon tasks. Because Beam activates only 23B parameters per token and reaches solutions using 3x to 4x fewer reasoning tokens than other comparable open weight models, it dramatically reduces the inference-time compute required for each reasoning step. System-level efficiency: AI Hypercomputer optimized serving Once developers deploy an agent into production, a second set of bottlenecks could appear at the serving layer. In an agentic coding loop, the model is called dozens of times in a single session. With every turn, the coding harness appends new file reads, code diffs, compiler logs, and tool outputs to a shared conversation history that quickly grows to tens or hundreds of thousands of tokens. Even when the model itself generates 3x to 4x fewer reasoning tokens on each turn, the accumulated context window across turns creates two major infrastructure challenges: First, prefill compute becomes a bottleneck. Standard Kubernetes load balancers distribute requests using stateless round-robin routing. When a coding harness sends Turn 15 of a session, it often lands on a different replica than Turn 14. That replica is forced to recompute the entire historical prompt from scratch, wasting GPU compute and creating long prefill queues that delay other users. Second, decode becomes bottlenecked by KV cache capacity. Holding long-context KV caches for dozens of concurrent agent sessions quickly fills up GPU High-Bandwidth Memory (HBM). Once HBM fills up, the serving engine has to evict older KV blocks. As soon as those blocks are evicted, cache hit rates drop and GPU throughput stalls. To preserve Beam’s model-level efficiency at cluster scale, the serving stack has to be optimized as a distributed system. That is why our recipes pair Beam with llm-d (with vLLM) and NVIDIA Dynamo (with SGLang). Inside the AI Hypercomputer inference architecture To run Beam’s BF16, FP8, and NVFP4 checkpoints at peak efficiency on Day 0, we designed a vertically integrated architecture on AI Hypercomputer where each layer handles a specific part of the agentic serving lifecycle. System optimized architecture for serving agentic traffic Rather than treating inference pods as stateless endpoints, each layer of the stack is co-designed around the multi-turn agent lifecycle: Prefix- and load-aware routing (GKE + llm-d EPP / Dynamo router): Tracks cached prefixes and queue depth across worker pods, steering each follow-up turn from a coding harness to the replica holding its warm KV prefix while preventing queue saturation via turn-priority flow control. Disaggregated compute and speculative decoding (A4X Max & G4 instance): Runs vLLM and SGLang with native Blackwell NVFP4, Expert Parallelism (EP) for Beam’s 23B active experts, Data-Parallel Attention, and DFlash2 speculative decoding. Separating Prefill and Decode (P/D) pools ensures heavy prompt bursts never stall active token generation. Tiered KV cache (GPU Memory -> DRAM & Local SSD) Active KV blocks stay in high-bandwidth GPU memory (Tier 1), while warm KV blocks evicted during long-horizon sessions overflow into host CPU DRAM and local NVMe SSDs (Tier 2) via vLLM’s OffloadingConnector or SGLang's HiCache, allowing historical context to be fetched in milliseconds instead of recomputed from scratch. System optimizations for multi-turn agentic workloads When serving multi-turn coding and tool-use workloads like the AgentX trajectory dataset across rising concurrency levels, each layer in the serving stack contributes to the performance and latency improvements for multi-turn, long context traffic patterns of agentic workloads: A note on reading these charts. The two configurations are not comparable to each other. NVIDIA Dynamo ran on A4X Max instances with 32 x NVIDIA GB300 NVL72GPUs; llm-d ran on G4 VMs with 8 x NVIDIA RTX PRO 6000 GPUs. Each chart shows the gain over a baseline on the same hardware. More replicas give the router more warm KV caches to hit and more room to split prefill from decode, so the uplift grows with the deployment. Both llm-d and NVIDIA Dynamo scale up and down to match the underlying infrastructure. NVIDIA Dynamo optimized perf vs baseline deployment of Reflection's Beam llm-d optimized perf vs baseline deployment of Reflection's Beam Across both platforms, layering these optimizations shifts the Pareto frontier to deliver higher output throughput and faster per-user interactivity simultaneously: Baseline deployment (Stateless round-robin routing). In a standard Kubernetes deployment without prefix awareness, consecutive turns from the same coding session land on different replicas, forcing constant prefill recomputation on historical context and causing throughput to plateau as concurrency scales. KV-cache-aware & flow control routing. Enabling prefix-aware routing in NVIDIA Dynamo or llm-d’s Sticky EPP with turn-priority flow control keeps multi-turn agent trajectories pinned to the replica holding their warm KV cache, immediately cutting Time-to-First-Token (TTFT) latency and freeing up GPU compute, resulting in a significant increase in token throughput. Host DRAM and Local SSD (LSSD) KV offloading. Offloading evicted KV blocks from GPU memory into host DRAM and local NVMe SSDs prevents cache thrashing when dozens of long-context coding sessions exceed on-device GPU memory capacity. Disaggregated serving, speculative decoding, and KV pool tuning. Tuning hybrid KV cache memory allocation, enabling speculative decoding, and disaggregating prefill and decode workers isolates token generation from heavy prompt bursts while the draft model multiplies output throughput to keep per-agent token interactivity fast. Get started and meet us at PyTorchCon and GTC Berlin This blog explored how you can leverage system level optimizations to scale performance to serve Reflection's Beam family of models for agentic workloads. All of the Kubernetes manifests, router configurations, and benchmarking scripts from this post are open-source and ready to run on your own GKE cluster. Deploy the optimized stack: Explore the day 0 guides for running Reflection’s Beam with llm-d and NVIDIA Dynamo in the AI-Hypercomputer/gpu-recipes repository on A4X Max and G4, and Model Garden in Gemini platform. Download the weights: Grab the Apache 2.0 BF16, FP8, and NVFP4 checkpoints on Reflection’s Hugging Face page. Visit us at the llm-d and PyTorch Conference in San Jose: If you are attending PyTorch Conference North America in San Jose this October, stop by the llm-d community sessions and the Google Cloud booth #. We will be walking through live demos of KV-cache-aware routing, P/D disaggregation, and KV cache tiering for agentic workloads. Come see us at NVIDIA GTC Berlin: If you are attending NVIDIA GTC Berlin, come connect with us at our booth #3026, or our Google Cloud Hub at w3.hub: just a short 5 minute walk from the venue. Learn more about our sessions.
Code, Test, and Deploy on One Machine with NVIDIA RTX Spark
AI agents are changing how software gets built. Developers have gone from writing every line of code by hand to directing agents that write most of the code. As...
Physical AI is more than robots, says the Nvidia veteran now investing in it
Amulya Vishwanath, who spent seven years leading product marketing for NVIDIA’s robotics platforms, says robotics is currently in its “Lego era,” with the basic building blocks like actuators, robotic hands, software, and safety standards still being rebuilt. This view runs counter to those who believe that robotics, powered by a general foundation model, is about to have […]
An Nvidia insider-turned-VC on why robotics hasn’t hit its Chat GPT moment, yet
Amulya Vishwanath, who spent seven years leading product marketing for NVIDIA’s robotics platforms, says robotics is currently in its “Lego era,” with the basic building blocks like actuators, robotic hands, software, and safety standards still being rebuilt. This view runs counter to those who believe that robotics, powered by a general foundation model, is about to have […]
Architecting autonomy: A design pattern for high-compute, governed agents in biotech
In production systems today, most AI agents operate as lightweight dispatchers. They parse a prompt, make an API call, retrieve a record, and hand back control. Their execution is fast, stateless and cheap. Biotechnology does not work this way. Folding a protein target, screening a 50,000 compound ligand library, or evaluating structure-activity relationships (SAR) are not quick API lookups. They are sustained, stateful, GPU-bound simulations that run for minutes or even hours across specialized silicon. When you ask a general-purpose large language model (LLM) endpoint to coordinate a complex drug discovery workflow, the standard paradigm breaks: Timeouts occur, context windows overflow with atomic coordinates, and proprietary chemical Intellectual Property (IP) risks exposure to external networks. Building enterprise grade research and development (R&D) agents requires moving past the monolithic assistant model. In this blog post, we will discuss how to use a three-layer architecture: separating cognitive orchestration (the brain) from computational execution (the muscle), and anchoring both inside an enterprise governance plane to build scalable agents for drug discovery use cases in biotech. A three-layer pattern The reference architecture below shows how to architect, optimize, and govern high-compute autonomous agents in biotechnology, specifically Drug Discovery. Figure 1 — The three-layer pattern: a cognitive orchestrator (brain), a scalable GPU execution layer (muscle), and an enterprise governance plane. The execution layer: scaling the muscle - high-compute execution The execution layer is responsible for the heavy scientific computations. The first architectural decision is determining where workloads should run: Strategic, proprietary pipelines require dedicated GPU infrastructure within your security perimeter Routine or standardized workloads can safely be delegated to managed cloud endpoints In this architecture, protein folding is driven by ESMFold and generative design by GenMol. Both run as NVIDIA Inference Microservices or NIMs deployed on Google Kubernetes Engine (GKE) using G4 VMs backed by NVIDIA RTX PRO 6000 Blackwell GPUs. A critical hurdle in containerized GPU workloads is the cold-start penalty, the latency delay required to pull multi-gigabyte model weights from an image registry and stage them into GPU memory (VRAM). To ensure low latency responsiveness, we build the following as a recommendation into the reference architecture: Maintain warm pools: Pin the GKE node pool to a minimum of one active node. Preload weights: Model weights are loaded directly into VRAM at pod initialization, ensuring containers are immediately ready for inference. Resilient scheduling: GKE manages pod lifecycles and restarts failed instances without tearing down the underlying VM infrastructure. This approach trades custom, manual CUDA kernel tuning for NVIDIA's pre-compiled, containerized runtimes, dramatically reducing infrastructure engineering overhead while ensuring deterministic throughput. In biotech, chemical structures represent millions of dollars in proprietary IP. A docking request transmits SMILE strings or 3D coordinate matrices that must never leave company custody. Containerized NIMs eliminate the friction between rapid prototyping and rigorous data isolation. During early exploration, researchers can query NVIDIA hosted endpoints. When transitioning to proprietary lead candidates, the exact same container is deployed to GKE inside a private VPC. The agent’s orchestration logic remains identical; only the target URI updates from an external proxy to an internal VPC endpoint. No structural data leaves the enterprise perimeter. The cognitive layer: Multi-agent reasoning With compute execution isolated, the cognitive layer manages agentic workflow sequencing. Built on Agent Runtime, within the Gemini platform, this reference architecture shows a system that deploys a hierarchical multi-agent structure, one lead orchestrator, and two specialized domain sub-agents (Lead Optimization and Safety Screening) . The multi-agent design can be modified to suit the use case at hand. Based on this design, when an end-user submits a high-level task such as “ Analyze Candidate 4b against Target X and produce a SAR report”, the system applies four core orchestration patterns discussed below; In-process native agent handoffs: The lead orchestrator delegates tasks to specialist sub-agents using Agent Runtime’s native SDK rather than network-serialized agent-to-agent HTTP protocols. This eliminates intermediate network hops and keeps internal handoffs instantaneous. Only the outermost boundary communicates outward to user-facing surfaces like the Gemini agent. Passing bulky payloads by reference: LLMs degrade quickly when forced to ingest massive arrays of 3D spatial coordinates. In this architecture, raw structural data (PDB files, docking poses, trajectory logs) is written directly to Cloud Storage. Agents pass lightweight, signed object URIs and high-level structural summaries, keeping context windows compact and inference costs down. Decoupling workflow logic from biochemical reasoning: General-purpose LLMs excel at task planning and synthesis, but are prone to hallucinating biochemical nuances. To control this behavior, this architecture maintains strong separation of concerns, namely, workflow and tasks decomposition are handled by Gemini. Domain chemistry and pharmacological reasoning are handled by specialized Nemotron models hosted on dedicated GPU nodes. Context-driven evaluation over rigid cutoffs: Traditional computational screening enforces arbitrary numerical cutoffs (e.g., discard if binding affinity ,-7.5 kcal/mol) However, therapeutic context fundamentally alters risk tolerance. Preventive cardiovascular therapy taken daily by healthy patients requires extremely strict safety margins, or a novel oncology candidate targeting an intractable cancer may accept higher toxicity if efficacy is demonstrated. By passing disease context directly into the specialized reasoning models, drug candidates are evaluated against dynamic, target-specific profiles rather than static thresholds, preventing the premature culling of viable drug leads. Performance best practices for high-compute pipelines Optimizing an agentic system that interfaces with heavy GPU compute requires challenging common engineering instincts: Common Assumption Architectural Reality Recommended Best Practice "Swap in a faster driver model to cut latency." The primary orchestrator's token generation is rarely the bottleneck in multi-step R&D pipelines. Optimize I/O, not token speed: Focus on reducing payload sizes and intermediate network hops rather than compromising orchestrator reasoning depth. "Parallelize tool calls across workers." External scientific services and containerized models often serialize requests internally on dedicated hardware. Respect execution topology: Align client-side concurrency with backend queue mechanics to prevent pipeline lockouts and connection timeouts. "Pass full simulation states between tools." Large JSON bodies cause schema validation failures, prompt truncation, and token bloat. Pass heavy payloads by reference: Store raw coordinates in object storage and pass lightweight URIs between agent boundaries. "Return outputs only when the pipeline finishes." Long multi-minute runs leave scientists blind to whether jobs are proceeding or stalled. Stream intermediate stage completions: Emit progress updates at each completed milestone (e.g., folding complete, docking running) for real-time visibility. "Chain multiple granular micro-tools." Deep tool-chains increase the probability of hallucinated arguments and schema mismatches. Collapse compute pipelines: Wrap end-to-end simulation pipelines behind a single, clean tool interface that takes clear parameters and returns a consolidated object. The enterprise governance and asymmetric autonomy Deploying high-compute agents in enterprise environments requires robust data sovereignty, audit trails, and process control. The Gemini platform establishes these safeguards natively with the following components: Agent Identity: Every autonomous agent operates with a cryptographically verifiable identity. Thus, for a biotech use case, when a candidate molecule is advanced or rejected, the event is permanently logged to that specific agent principal. Agent Gateway: This serves the single ingress/egress point for every interaction within the perimeter. Centralized IAM and regional residency rules help ensure sensitive molecular data remains within designated cloud regions. Agent Registry: This feature maintains a curated catalog of approved agents, validated tool schemas, and authorized Model Context Protocol (MCP) servers, preventing rogue tools from executing in production. Model Armor: This functionality inspects incoming prompts and outgoing payloads in real time to prevent prompt injection and data exfiltration. The payoff is clear. Identity, RBAC, auditing, residency, and data protection are native properties of the Gemini platform; this allows enterprise customers to focus on science rather than having to build a compliance stack for every project. In high-stakes research and development, full autonomy introduces unacceptable liability, while requiring approval for trivial steps can create frictions. The solution addressing this to use asymmetric gating in the following ways; Automate reversible operations: For example, allow the agent to resolve chemical naming synonyms, pull structural PDBs, and run preliminary Lipinski screens autonomously without interrupting the researcher. Gate irreversible operations: For instance, initiating multi-GPU docking run, advancing a lead compound to wet-lab synthesis, or archiving a therapeutic program must require explicit human sign-off. The pattern, and the path forward High-compute autonomous agents succeed when the boundaries between cognitive planning, numerical computation, and system governance are clean in the following ways: Keep the orchestrator focused on decomposition and synthesis, leaving intensive biophysical simulation to specialized, containerized microservices and models. Eliminate context bloat by passing complex chemical data by reference through cloud storage. Anchor the workflow in enterprise governance, pairing cryptographic agent identity with asymmetric human oversight. As generative and structural biology models expand toward whole-cell modeling and complex dynamic simulations, this decoupled architecture ensures research systems scale efficiently while keeping proprietary IP secure and auditable. Reach out to your Google sales representative if you have any requirements to build a use case like this and we will be happy to talk and support you in your agent development journey on Google Cloud.
Announcing Wiz Runtime Sensor add-on for GKE: Turnkey threat detection for Kubernetes
Everything is moving faster in the age of AI, and that includes security threats. What used to take attackers weeks to exploit can now happen in just a few minutes. Standard vulnerability scans that run on artifacts at rest can catch basic setup issues, but to detect an attack that's actively happening you need real-time runtime protection. Today, we’re introducing the Wiz Runtime Sensor add-on for Google Kubernetes Engine (GKE), in preview. This built-in integration brings low-touch deployment, automated lifecycle management, enterprise credential security, and fleet-wide governance to Wiz's industry-leading eBPF runtime threat detection for both Standard and Autopilot GKE clusters. The operational friction of runtime security Security and platform engineering teams share common dilemmas when deploying in-cluster runtime defenses: Deployment and lifecycle friction: Deploying runtime agents often requires managing installations from third-party sources across dozens or hundreds of clusters. Credential sprawl and security risks: Passing and rotating API keys as Kubernetes Secrets introduces administrative overhead and security risk. Fleet-wide enforcement gaps: Platform teams lack built-in policy controls to enforce that every new cluster has runtime sensors enabled before workloads are deployed and start receiving traffic. Performance and operational overhead: Without explicit and strategic resource limits, runtime agents can impact how much CPU and memory is available for your workloads and system functionality. With the Wiz Runtime Sensor for GKE, Google Cloud and Wiz have minimized these operational barriers. The Runtime Sensor is now available in GKE as a first-party, managed platform add-on. Bridging the gap with Wiz Runtime Sensor for GKE The Wiz Runtime Sensor for GKE connects central security and platform engineering workflows by simplifying and automating the sensor lifecycle. Figure 1: High-level architecture showing credential sync, sensor deployment, and threat telemetry. With the add-on, GKE manages the sensor deployment, credential injection, and lifecycle updates. Building runtime protection directly into the platform reduces administrative overhead and provides the following benefits for your Kubernetes fleet: Native Secret Manager integration: Security teams no longer need to distribute Wiz API keys across cluster namespaces. The add-on uses GKE's Secret Manager secret sync integration to store your Wiz credentials in an off-cluster, centralized credential vault that only a dedicated service account can access. GKE automatically retrieves the credentials and injects them directly into the Runtime Sensor pods. Updating a key in Secret Manager automatically syncs to the sensor without requiring cluster restarts or manual intervention. Simplified enablement: After you add your Wiz credentials to Secret Manager, platform operators can enable the Runtime Sensor add-on by using the gcloud CLI or the GKE API. The GKE control plane handles deploying the sensor components, managing the lifecycle of pods, and configuring the nodes. Secure egress and proxy support: For environments that restrict public internet access, the managed sensor supports standard HTTP and mTLS proxy configurations. Telemetry is routed back to Wiz without violating your egress firewall policies. Fleet-wide governance with organization policy: Platform security leads can enforce compliance across their entire organization using custom organization policy constraints. You can use a constraint to reject any attempts to create a cluster that doesn't enable the Runtime Sensor add-on, which can prevent malicious actors from spinning up rogue infrastructure to evade runtime detection. Kernel-level observability with minimal overhead: The Wiz Runtime Sensor continuously monitors system calls, running processes, network connections, and file access. It catches suspicious activity, including reverse shells, unauthorized privilege escalations, container escapes, and unsafe outbound connections while keeping CPU usage low even under heavy workload activity. The sensor uses a fixed memory limit on each node to ensure consistent performance as workload density changes. This is especially valuable for AI workloads and web services where application activity might fluctuate quickly. Independent auto-updates: Security threats and zero-day vulnerabilities don’t wait for scheduled infrastructure maintenance windows. The lifecycle of the Wiz sensor add-on for GKE is independent of your GKE cluster and node lifecycle. The sensor periodically rolls out updates of new sensor versions published by Wiz, to help ensure that your clusters always have the latest detection rules without requiring GKE version bumps, node pool recreations, or workload disruption. How it works: Deploying and enforcing the sensor Enabling the Wiz sensor add-on follows the same process that platform administrators are already familiar with on GKE. Using standard gcloud commands, you can activate runtime protection during cluster creation, turn it on for existing clusters, and enforce it across your fleet while keeping credentials securely managed in Secret Manager. Check the setup documentation for prerequisites, such as granting GKE access to Secret Manager. Provisioning a cluster with the Wiz Sensor add-on To provision a new GKE cluster with the managed Wiz sensor enabled using credentials stored in Secret Manager: code_block <ListValue: [StructValue([('code', 'gcloud container clusters create production-ai-cluster \\\r\n --zone=us-central1-a \\\r\n --release-channel=regular \\\r\n --workload-pool=${PROJECT_ID}.svc.id.goog \\\r\n --enable-secret-sync \\\r\n --enable-secret-sync-rotation \\\r\n --addons=WizSensor=ENABLED \\\r\n --wiz-sensor-registry-secret-uri=projects/${PROJECT_ID}/secrets/wiz-registry-secret/versions/latest \\\r\n --wiz-sensor-api-key-secret-uri=projects/${PROJECT_ID}/secrets/wiz-api-key-secret/versions/latest'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f8808230790>)])]> To enable the sensor on an existing running cluster with Workload Identity Federation for GKE and Secret Manager secret sync enabled, run the following: code_block <ListValue: [StructValue([('code', 'gcloud container clusters update production-ai-cluster \\\r\n --zone=us-central1-a \\\r\n --update-addons=WizSensor=ENABLED \\\r\n --wiz-sensor-registry-secret-uri=projects/${PROJECT_ID}/secrets/wiz-registry-secret/versions/latest \\\r\n --wiz-sensor-api-key-secret-uri=projects/${PROJECT_ID}/secrets/wiz-api-key-secret/versions/latest'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f87fac26210>)])]> Enforcing fleet-wide protection with organization policy You can require all new GKE clusters across your organization to install the runtime sensor by deploying a custom constraint: code_block <ListValue: [StructValue([('code', 'name: organizations/123456789012/customConstraints/custom.\r\nresource_types:\r\n - container.googleapis.com/Cluster\r\nmethod_types:\r\n - CREATE\r\n - UPDATE\r\ncondition: resource.addonsConfig.wizSensorConfig.enabled == true\r\naction_type: ALLOW\r\ndisplay_name: Enforce Wiz Sensor on All GKE Clusters\r\ndescription: Mandates that all GKE clusters enable the managed Wiz Runtime Sensor backed by the corporate Secret Manager vault.'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f87fac251d0>)])]> Intelligent threat correlation for AI security The true power of this integration emerges when the managed sensor connects to the broader Wiz AI Application Protection Platform (AI-APP). By feeding GKE runtime telemetry into the Wiz Security Graph, you unlock a security toolkit that goes beyond static alerting, with: Real-time risk assessment and threat verification: By pairing background security scans with live activity monitoring, you get a clear view of real risks. The sensor checks whether vulnerable code is actually running in memory, so you can focus on active security threats and ignore inactive ones. Real-time threat detection and response: Identify suspicious activity like malware, unauthorized access attempts, and software vulnerabilities in real time. Security teams can set rules to automatically block or stop threats before they can spread. Network activity and detailed security insights: Track system activity, network connections, and data flows to uncover hidden risks and unauthorized software usage. If a threat is detected, the sensor automatically gathers diagnostic data to help teams quickly investigate what happened. Together, these capabilities ensure that mission-critical applications and AI agents deployed on GKE are monitored for attacks and data exfiltration without compromising developer velocity. Get started today The Wiz Runtime Sensor add-on for GKE delivers a standard for container security: deep, kernel-level eBPF protection without operational complexity or deployment friction. By combining GKE's managed platform automation with Wiz's comprehensive security intelligence, platform and security teams can innovate at cloud speed while maintaining strong runtime defense. Check out the Wiz Sensor for GKE documentation to learn more.
Four evaluation engineering lessons learned from building agent plugins
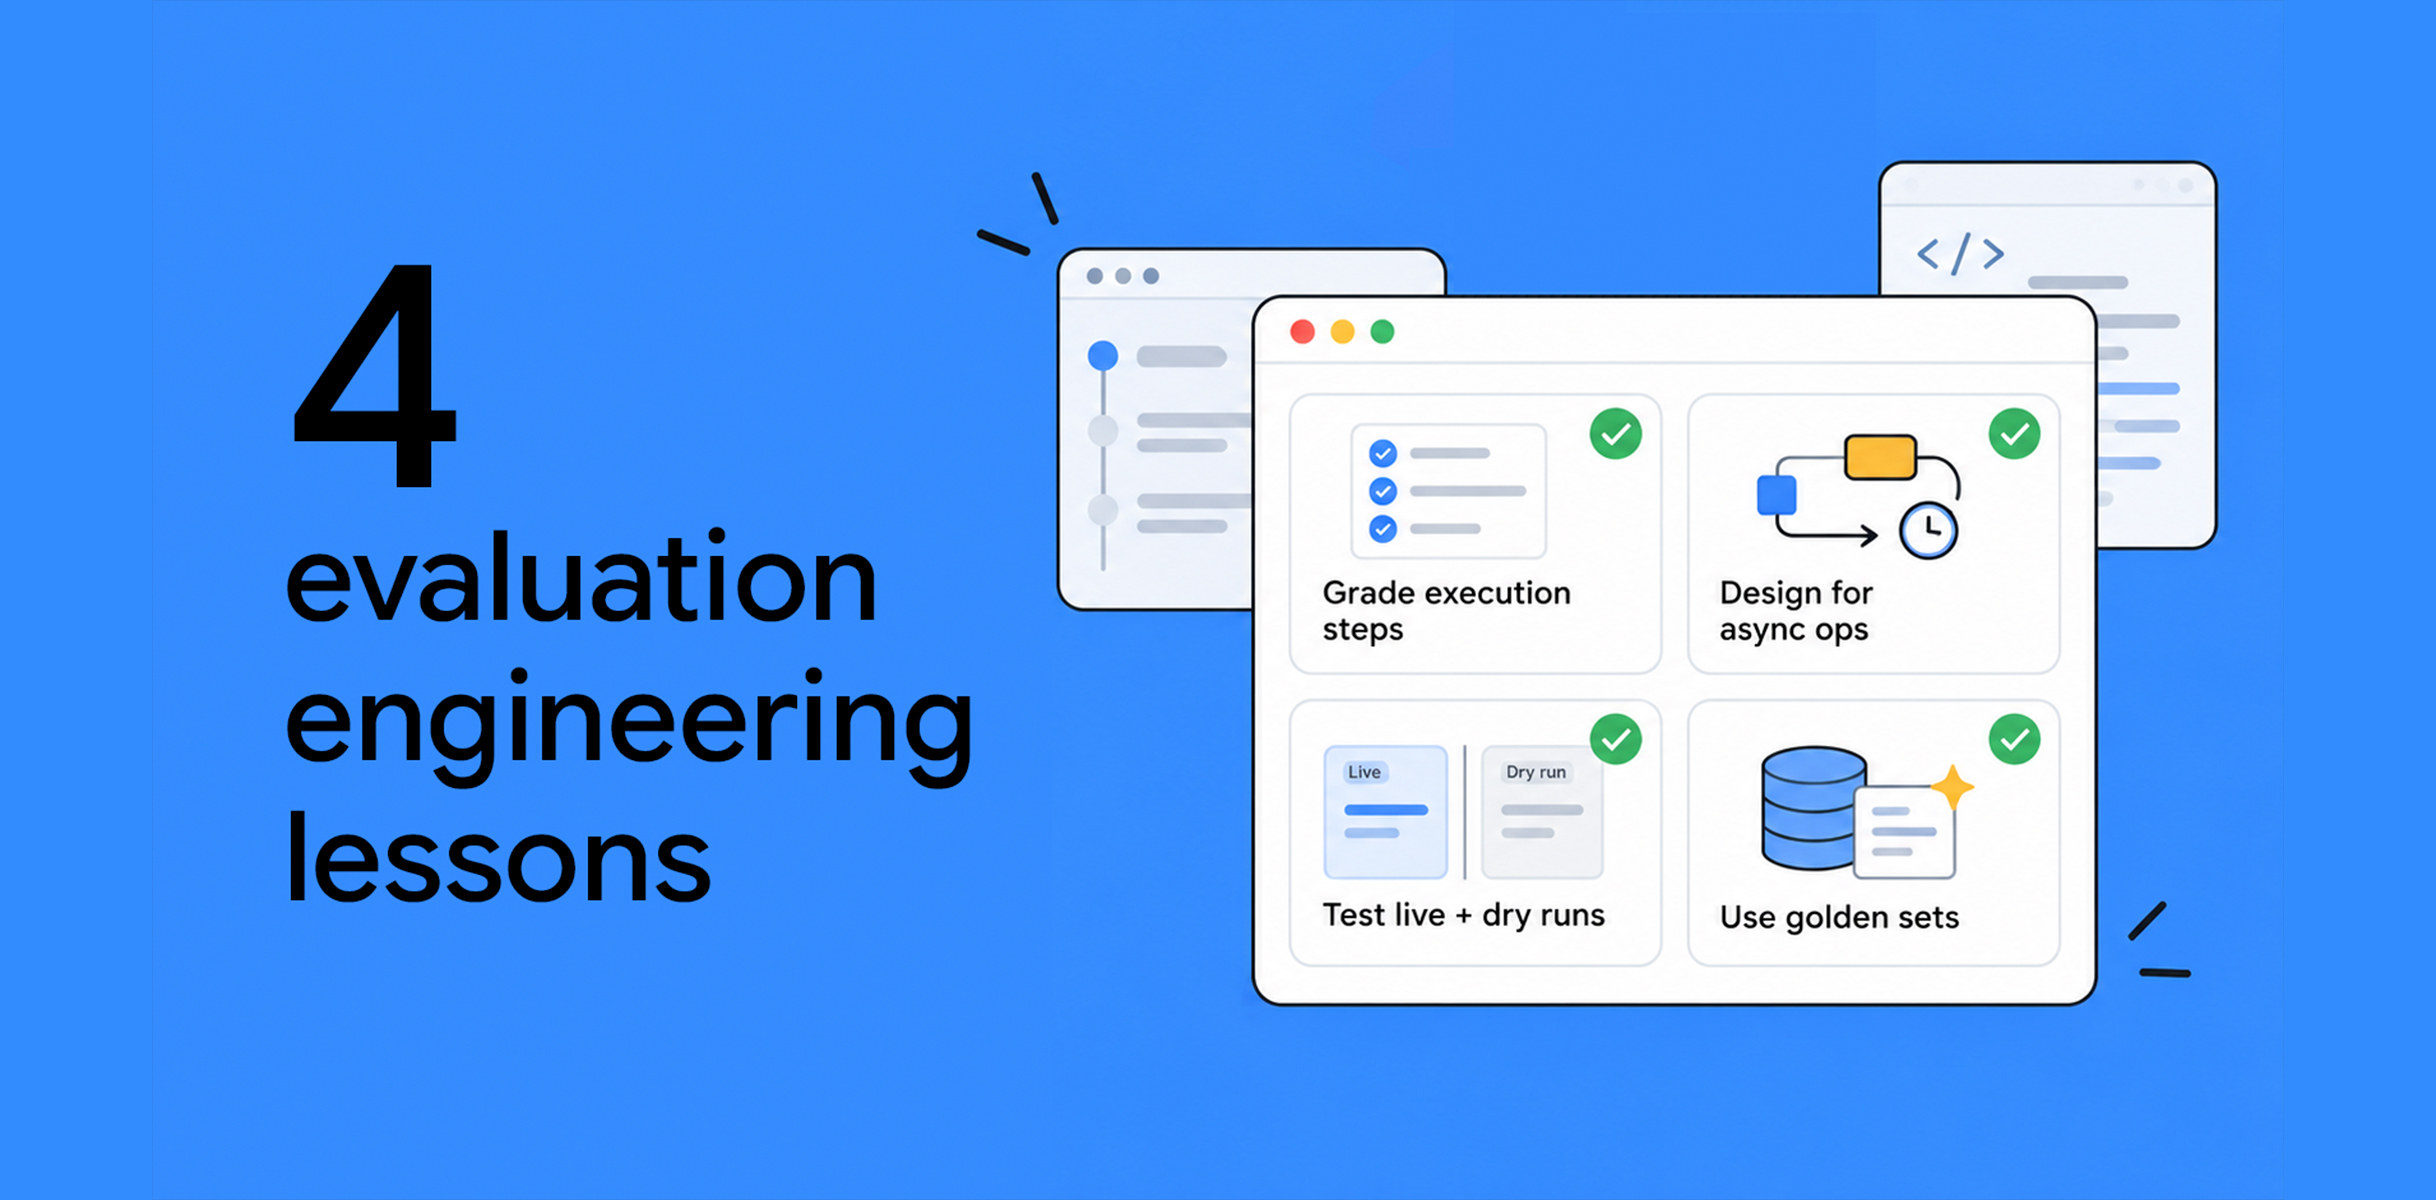
The real challenge of building an agentic system isn't the construction, it's the measurement. Evaluation engineering is a critical foundation for building reliable AI systems. Setting up systematic, repeatable tests to measure your agent’s true behavior can be the difference between shipping a tool you can trust and one that silently breaks, fails to call APIs, or makes mistakes. I’ve run evaluation engineering initiatives for years at Google and developing the newly released Google Cloud Developer plugin served as a live testbed to stress-test these key principles across real-world developer workflows. Here are four eval lessons we learned from building the new plugin that you can apply to your own builds. 1. Grade the execution steps instead of the summary When we first evaluated agents, we set up an LLM-as-judge to inspect the agent’s final text reply and scored it against a checklist. However, we quickly realized it’s fundamentally flawed because the grader only sees what the agent wrote, not what it actually did. When we ran our initial 11-prompt evaluation suite for the Google Cloud Developer plugin, the automated grader marked it as failing three prompts. But when we opened the raw tool-call logs and read the transcripts, the plugin had actually passed all three. On a Cloud Run cleanup prompt, for instance, our rubric required checking command syntax before running anything. The agent ran gcloud help run services list as its very first step. It did the work, but its final message was focused on warning the user about permanent data loss rather than reciting that it had checked the help docs. The grader penalized the agent for doing the right thing simply because it didn’t brag about it in the summary. If your rubric line says "did it run X?", a LLM judge is guessing unless you evaluate the actual tool-call trajectory. Takeaway: Don't grade an agent on its closing pitch. Score the raw execution trajectory to verify what commands were actually executed, validated, and scoped. 2. Design evals for asynchronous operations When you start reading tool-call trajectories, how you extract that telemetry matters just as much as what you're reading. Extracting agent telemetry into a flattened, sequential list of events obscures concurrent tool dispatch, which is one of the critical causes of behavioral failure. Modern agent harnesses often batch multiple tool invocations into a single assistant turn using an array of calls. In our evaluations, when an agent was asked to inspect an environment and look up documentation, the harness dispatched the skill-loading call and two documentation searches simultaneously within a single tool_calls payload. Because activating a skill is a multi-stage process, where the initial call returns a short launch stub and the subsequent turn injects the full instruction body, the instructions meant to govern the search arrived in the prompt context after the system had already executed the searches. The system never gave the skill a dedicated turn to let its guidance influence the agent's actions. If telemetry pipelines strip out turn structures and merge calls into a flat timeline, engineers will waste days wondering why an agent disregarded unambiguous instructions that a developer embedded in a skill. Takeaway: Preserve turn structure in telemetry extractors so you can identify when client-side parallel dispatch issues tool calls before injected guidance enters the context window. 3. Test live runs and "dry runs" side-by-side You need to inspect real API calls to catch harness quirks, like parallel dispatch. But if you only test your agent in one environment condition, you're flying half-blind. From day one, you need to run two conditions side-by-side: a live run and a plan-only run. In the live condition, the agent has real, sandboxed credentials and actually executes commands. This is how you see if syntax works, parameters serialize cleanly, and the agent exercises restraint before doing something destructive. Live runs frequently hit an unexpected permission error on step two and abort before you ever reach the behavior you’re trying to test. That's why you need the plan-only condition, where you strip credentials and tell the agent to explain what it would do without running anything. This strips out permission roadblocks and shows you the model’s pure reasoning and routing intent. Roughly half our most important findings came from the delta between the two. For example, on one of our onboarding prompts, a live run was blocked immediately on a project list call. The plan-only run sailed right through and produced an 8,000-character plan that completely ignored organization policies, admin approvals, and governance. The live run masked a major cognitive flaw that the plan-only run exposed in seconds. Takeaway: Run live and plan-only evaluations side by side. Live runs test actual execution and safety restraint; plan-only runs expose the model's raw reasoning and routing without getting tripped up by permission errors. 4. Use “golden sets” as durable baselines Frontier model architectures change every few months, agent harnesses improve, and plugin manifest standards will inevitably evolve. When building the Google Cloud Developer plugin, we treated evaluations as continuous integration testing for these non-deterministic environments. That means we stress-tested the composite stack, including the harness, the live model, and the tools running together on realistic tasks. Instead of guessing from the final text output, this approach captures the whole trajectory: what the agent thought, what commands it actually ran, and whether it solved the problem without breaking anything. Then you score that run against golden sets curated by real human experts who know what the ideal path looks like. Takeaway: Build golden sets based on what the entire system should actually do in the wild, including your harness, model, and plugins. Models change, but those baseline runs are your safety net. Reminder: Use evaluation suites over “one-shot” demos A common mistake I see among engineers is what I like to call the one-shot demo. This is when someone feeds a prompt into a LLM, watches it build a complete 3D game or solves a Rubik’s cube in a single pass and calls it an eval. But in reality, this is just a vanity metric. To do quality work with AI, I truly believe that you need evaluation suites. Without evaluations, teams are like literally running into a dark cave blind. Engineering an enterprise-grade agent means testing the system's ability to handle multi-step interactions, manage permissions, and avoid destructive outcomes like accidentally deleting a project because you asked it to "find opportunities to save costs." Where to go from here Building an agent plugin or MCP server is the beginning. Shipping something you can actually trust with real cloud infrastructure requires significantly more work in evaluations to ensure it’s doing what you expect it to do. At the end of the day, the only thing that outlasts model churn is a stress-tested eval suite. Check out the Google Cloud Developer plugin documentation or explore this codelab to get started with the plugin in Antigravity.
The SAVE method: Learn the fundamentals to engineer trustworthy generative media
Google Cloud Consulting works with organizations every day to build generative media that’s trustworthy, brand-aligned, and stands out. Instead of relying on clever or complicated prompting, we’ve identified four recurring basics to generate consistent results, what we call the “SAVE” method. In this blog, we’ll share more about this method and how you can apply it to your own work. S - Separate the researcher from the storyteller If in a single prompt, if you’re requesting a technical summary, key product features, and an engaging video script all at once, you’re setting the model up to fail. Creative tasks require fluid language and pacing, while factual output requires constraint. Forcing both jobs into one context window will likely end with the model fabricating details to make the narrative flow better. Instead of one prompt, consider splitting the work into specialized steps, like a researcher and a storyteller. Here’s how they might work together: The researcher reads the source documents, extracts core claims, aligns with approved messaging, and outputs a structured brief (like a clean checklist or bulleted factsheet). The storyteller then takes that verified brief and focuses purely on style, pacing, visual metaphors, and tone. By decoupling research from your creative generation, your agent is never tasked with deciding what’s true, but how to make the truth more engaging and effective. A - Approve verified facts only If you hand a creative generative model documents that are unedited, it might mix up speculative ideas with business facts. The media generator should never have direct access to raw source files. It should only use verified, structured inputs. To avoid this: Lock down core claims: Approved statements, product names, and concrete business outcomes should be fixed upstream rather than left for the model to extract on the spot. Champion contextual packaging: Pass each fact along with its explicit constraints included. Examples may include things like "use this point in the opening statement" or "do not extrapolate beyond this approved bullet point." This way, you ground the generation in verified facts and reduce the risk of unsupported claims entering the creative generation stage. V - Verify before you render Discovering a factual error in an animated video or rendered asset after the final export wastes both compute budget and turnaround time. The most effective human-in-the-loop checkpoint is right before generation begins. To fix this, review the script and storyboard. Have product leads or legal teams sign off on the extracted facts, narrative outline, and voiceover text while it’s still simple, editable text. This way, you can catch errors early. Swapping an outdated feature name or fixing a typo takes two seconds in a text file. Treat text as your testing ground. Once approved, generating the final media becomes a low-risk, predictable step. E - Engineer guardrails into the system Telling a model to “keep voiceover word count short, never reference unapproved topics, and format links correctly" in a prompt works until it doesn’t, and an edge case slips through. Relying on prompt obedience for brand safety is a gamble and can damage trust. Where requirements can be checked deterministically, enforce them in the system rather than relying only on prompt instructions. For example, try these three actions first: Programmatic boundary checks: Use standard code to validate word counts, verify that URLs are live and authorized, check colors against your brand palette, and format text strings. Independent safety gates: Run automated filters outside the generation pipeline to catch policy violations or out-of-bounds claims before an asset is ever delivered. Model modularity: When your safety and brand rules are set, you don't have to rewrite your entire governance playbook every time a newer, faster generative model is launched. You simply plug the new model into your existing, verified pipeline. Generating studio-quality media shouldn't mean constantly worrying about what the model might fabricate next. The SAVE method shifts the burden of accuracy away from prompt phrasing and into the architecture where it belongs. Apply the SAVE method yourself Check out our generative media deep dive and learn how to architect trust across your generative media using Google Cloud tools and technologies. Explore Google Cloud’s generative media suite, featuring cutting-edge models for studio-grade image, video, and sound generation.
Want to know the latest from Google Cloud? Find it here in one handy location. Check back regularly for our newest updates, announcements, resources, events, learning opportunities, and more. Tip: Not sure where to find what you’re looking for on the Google Cloud blog? Start here: Google Cloud blog 101: Full list of topics, links, and resources. aside_block <ListValue: []> Oct 12 - Oct 16 AI tokenomics in action: Enforcing tiered token budgets with ApigeeScaling artificial intelligence across an enterprise requires clear token governance to keep LLM spend predictable across departments. Join Tarun Abraham on Thursday, November 5, 2026 for a Community TechTalk on AI tokenomics. Discover how to use Apigee to enforce isolated, tiered token budgets and model access for each team—such as assigning Engineering a dedicated budget for Gemini Pro while covering mixed usage for Marketing—without changing application code. Attendees will also gain access to a sample codebase featuring a reusable Shared Flow.Register for the November 5 Community TechTalk Sept 28 - Oct 2 Claude Sonnet 5.5 is now available on Google Cloud. Built for focused coding and knowledge work, it delivers stronger performance for feature development, and creating presentation-ready documents, while offering more intelligence with a lower cost per task for most work at faster speed. Deploy Sonnet 5.5 directly from Model Garden with Google Cloud’s enterprise security, scale, and governance built in. Try it now. Mastering Storage Management with Storage IntelligenceIn our new blog, explore practical strategies to modernize storage operations using Storage Intelligence Advisor and enhanced Batch Operations. See how customers like Shipt and Palo Alto Networks are using these features to manage their estates at scale. Today, Storage Intelligence is used by 25 of the top 50 GCS customers. 2 in 3 customers have Storage Intelligence enabled for over 90% of their storage footprint.Explore best practices on our blog Cut Gen AI costs by 70% with Apigee X dynamic routingGenerative AI deployments face a harsh cost-performance trade-off: static model selection either wastes budget or compromises quality. Discover how to build an Intelligent AI Gateway using Apigee X to dynamically evaluate prompt complexity in real-time. This new blueprint automatically routes simple queries to lightweight models (like Gemini 3.5 Flash Lite) and complex reasoning tasks to advanced models (like Gemini 3.7 Flash), achieving over 70% cost savings without sacrificing output quality. Read the guide to optimize your Gen AI architecture AI Agent Clinic launches new hands-on session on production agent evaluationsA new episode of the AI Agent Clinic is now available showing organizations how to move past manual "vibe checks" to build robust, production-grade agent evaluations. In this hands-on session, Google Cloud engineer Dani Zamora and Matthew Feroz (Merge) take DocsHound, an open-source LangGraph agent, and build an end-to-end eval pipeline in under an hour. Learn how to standardize multi-turn traces across any framework using OpenTelemetry and OpenInference, pair LLM judges with deterministic checkers, and catch silent quality regressions before shipping. Watch here Drive AI impact: Join Google's Agentic Data Cloud event on Nov 4Every enterprise plans to adopt agentic AI within two years, but data bottlenecks hold them back—AI accesses just 45% of enterprise data today (MIT, 2026). Google's Agentic Data Cloud provides the trustworthy foundation and real-time context AI needs. Join our product leaders November 4th to explore the latest innovations across databases, analytics, business intelligence, and storage, and get direct answers in our executive Q&A with Google Data Cloud VP & GM Andi Gutmans. Register today! Sept 21 - Sept 25 Master MCP tool authorization and agent governance with ApigeeWhile the Model Context Protocol (MCP) solves interoperability for autonomous AI agents, chained actions like CRM edits or database queries quickly expose systems to unauthorized execution. Join our technical deep dive on Thursday, October 1, 2026, at 5:00 PM CEST featuring Christophe from Google Cloud. Learn how positioning Apigee between MCP clients and enterprise backends enables fine-grained authorization (FGA), complete audit trails, and policy evaluation via emerging standards like OpenID AuthZEN.Language and accessibility note: This session will be hosted in French, but non-French speakers can follow along seamlessly by turning on Google Meet live translated captions to read in English, Spanish, German, Portuguese, or Italian.Register for the October 1 Community TechTalk Apigee Trace Viewer Tutorial: Capturing & Analyzing Proxy TracesStreamlining API proxy debugging just got easier with a new tutorial by Apigee Customer Engineer Tyler Ayers. The guide covers end-to-end instructions for capturing debug traces in both Google Cloud Apigee X (or Hybrid) and the local Apigee Emulator, extracting trace JSON data via the web UI or automated REST APIs, and analyzing execution flows, variable mutations, and latency bottlenecks using the open source Apigee Trace Viewer. Read the Apigee Trace Viewer guide today. Automate Apigee proxy testing locallyCatching errors early saves time and money. A new tutorial by Apigee customer engineer Tyler Ayers shows how to use the Apigee Local Emulator for automated testing. Learn to run tests locally, integrate them into CI/CD pipelines, and deploy on Google Cloud Run for shared sandboxes. This approach provides instant feedback and zero cloud costs, helping teams speed up deployment cycles.Read the tutorial Scale your enterprise multi-agent systems with ApigeeDeploying multi-agent architectures in production introduces critical hurdles around security, operational control, and runtime expenses. Discover how Apigee API Hub provides a central discovery surface to eliminate agent sprawl across tools, Model Context Protocol (MCP) servers, and enterprise APIs. Learn how to turn existing backend services into secure MCP tools using Agent Gateway guardrails, while applying semantic caching and intelligent model routing to keep compounding token costs predictable.Join Google Cloud in Chicago in Oct.15 for The AI Evolution. Reserve your seat for Chicago Automate Apigee proxy testing with the Apigee Local EmulatorWaiting on remote deployments to validate API proxy logic slows down release cycles and increases infrastructure overhead. Join Nigel Walters on Thursday, October 8, 2026, at 5:00 PM CEST for a Community TechTalk on shift-left testing for Apigee. Discover how to use the Apigee Local Emulator and apigee-emulator-service to run sub-second assertion suites on local machines, automate CI/CD checks in GitHub Actions, and deploy ephemeral preview sandboxes on Google Cloud Run.Register for the October 8 Community TechTalk Now in Public Preview: AI-assisted EKS-to-GKE migrations with deterministic guardrailsMigrating complex Kubernetes estates from AWS EKS to GKE is traditionally high-friction and error-prone. Now in Public Preview, GKE Agentic Migration is an open-source agent plugin that replaces ad-hoc LLM prompting with an AI-assisted migration workflow protected by deterministic guardrails.Running locally in your development harness, it indexes source IaC, maps cloud-specific primitives (such as Karpenter to Custom Compute Classes), and validates configurations offline—delivering reviewable pull requests and data-migration runbooks with zero live cluster mutations.Learn more in the announcement blog and try the plugin on GitHub. Claude Opus 5.5 is now available on Google Cloud. Built for everyday complex tasks, it delivers stronger agentic coding, research, and analysis while handling long-running work at a lower cost per token. Google Cloud continues to provide enterprise customers with broad model choice to build, deploy, and scale their AI agents securely. Try it here. Import Delta Lake tables with Dataflow Job Builder!Migrating to borderless Lakehouse just got a lot easier. You can now import Delta Lake tables stored in Cloud Storage using Dataflow Job Builder, a no-code/low-code interface for authoring Dataflow pipelines. Because Dataflow is a fully managed service, you are spared the overhead of provisioning and managing virtual machines. For step-by-step guidance, check out the documentation here. Sept 14 - Sept 18 Storage Intelligence Advisor for Google Cloud Storage is now GAGoogle Cloud Storage customers can now manage cloud storage more effectively with Storage Intelligence Advisor, delivering curated metrics, automated anomaly detection, and actionable recommendations right out of the box, with zero setup required.Advisor baselines activity across your projects and automatically detects four key anomalies: surges in operations, unexpected rises in cross-region egress, and spikes in errors. Each finding includes deep drill-down visibility into the resources driving the change, alongside prescriptive steps to remediate issues before they impact performance or cost.Learn more to get started with Storage Intelligence Advisor. Build private WebSockets from Apigee X to Cloud RunReal-time AI agents and streaming architectures often require persistent, bidirectional connections. A new implementation guide by Apigee Customer Engineer Joel Gauci demonstrates how to establish private southbound connectivity between Apigee X and Cloud Run. Using Private Service Connect (PSC) and a Regional Internal Application Load Balancer, teams can enforce API governance and security policies at the edge while keeping backend services completely isolated from the public internet.Explore the step-by-step guide and open-source code Connecting Gemini Enterprise Agent Runtime to Apigee with Private Service Connect Deploying autonomous AI agents often presents security, compliance, and cost challenges. A new reference guide details how to build an end-to-end, private architecture between Gemini Enterprise Agent Runtime and Apigee. This design helps protect internal backends and manage token quotas. Read the full community guide and deploy the code Discover what’s new and next in ApigeeAs enterprise architectures adapt to generative AI and autonomous workflows, Apigee is expanding its proven platform capabilities to support modern AI gateway use cases alongside traditional API management. Join our session on Thursday, September 24, featuring Apigee Product Manager Geir Sjurseth. Get an inside look at recent product releases, explore architectural patterns for securing models and agents, and bring your questions for the live Q&A.Register for the September 24 Apigee product update Managed Service for Apache Kafka supports clusters with public Internet access!With Managed Kafka public clusters, you can now produce and consume messages from clients outside your VPC—including your local machine, for faster, frictionless testing. Public clusters unlock use cases like IoT devices, retail storefronts, and telco network towers. Enable public access on new or existing clusters via the Google Cloud console, gcloud CLI, or REST API. Spin up your first public cluster, or reach out to kafka-hotline@google.com with questions. Stream data directly into Bigtable using Bigtable subscriptions, now in Preview!You can write Pub/Sub messages to a Bigtable table with zero ETL with Bigtable subscriptions. No pipelines, no code, delivered by the serverless, zero-ops experience you already know with Pub/Sub. Power your AI workloads, from model telemetry to real-time context engineering, without the overhead of managing complicated ETL pipelines. Built to be dependable, with native support for dead-letter topics. Try the feature today! Sept 7 - Sept 10 Why Your Voice Agent Needs Session AuditingMoving voice agents to production demands robust quality monitoring. This guide dives deep into the inner workings of the Agent Development Kit (ADK) responsible for audio session auditing. Learn how the ADK's save_live_blob feature intercepts, buffers, and stores raw audio chunks during active Gemini Live sessions. We explore building an automated post-processing pipeline to seamlessly stitch these fragments into cohesive, playable audio files. Discover how to leverage these vital audio audit trails to monitor real-world interactions, diagnose failures, and ensure enterprise-grade reliability. Read the full guide here. AlloyDB Omni Red Hat RPM Orchestrator now Generally AvailableAlloyDB Omni Red Hat RPM orchestrator is now Generally Available. The AlloyDB Omni Red Hat RPM orchestrator offers a new way to manage PostgreSQL-compatible workloads on bare metal or VM platforms, combining the high performance of AlloyDB, access to generative AI features and Gemini models to build AI agents and applications, and full automation. The orchestrator simplifies cluster provisioning and lifecycle management by allowing you to define reference architecture specifications, customizable by adjusting instance parameters, node configurations, and networking options — discover all details in full blog post. Aug 31 - Sept 4 Automate VM guest software lifecycle with VM Extension Manager, now GAGoogle Cloud VM Extension Manager is now generally available, eliminating the need for custom startup scripts to manage guest OS extensions across Compute Engine fleets. Define declarative, project-wide policies that enforce desired software states across all regions and zones. Benefit from continuous drift detection with automatic self-healing, multi-zone phased rollouts with automated rollbacks on failure, and centralized fleet health visibility integrated with Cloud Monitoring.Explore VM Extension Manager documentation Assess Apigee migrations without a target environmentPlanning a migration to Apigee X or Hybrid? You can now assess your legacy Apigee Edge SaaS or OPDK environment earlier in your planning cycle. Using the updated --skip-target-validation flag in the Apigee Migration Assessment Tool, teams can generate a full inventory and establish scope baselines before target infrastructure or IAM credentials are provisioned.Read the guide to learn more. Claude Fable 5.1 is now available on Agent Platform. It brings performance improvements over Fable 5 across reasoning, full-lifecycle coding, multi-tool workflows, and knowledge work. Anthropic also announced Enterprise Frontier Safeguards, a solution that gives customers the option to safely deploy Anthropic’s most capable models while storing their data in cloud infrastructure they control. We continue to offer enterprise customers options across frontier models to build, deploy, and scale securely on Google Cloud. Aug 24 - Aug 28 Grok 4.6 is now available in Preview on Gemini Enterprise. xAI's most capable model, built for coding, agentic tasks, and knowledge work, Grok 4.6 joins Grok 4.3 and Grok 4.20 in Model Garden and becomes the flagship of the Grok family. It supports reasoning, function calling, and structured output for multi-step agentic workflows, and accepts text and image input.Get started today Empowering autonomous agents with advanced security governanceAI agents offer incredible productivity gains, but granting them access to read emails, query databases, and trigger APIs introduces critical new security risks. In fact, 79% of tech leaders cite security and governance as their biggest challenge to scaling AI. Traditional tools are no longer enough to handle automated threats like prompt injection and dynamic permissions. Discover how forward-thinking enterprises are using secure-by-default design, agent identity governance, and human-in-the-loop controls to deploy agents with confidence.Read more Stateful processing is available in BigQuery continuous queries in PreviewStateful operations significantly expand what’s possible with BigQuery continuous queries. This feature allows users to leverage functions like JOINs, aggregations, and windowing functions directly in their streaming queries. Now you can calculate metrics over time (for example, a 30-minute average) to power your downstream applications and AI agents with much richer, real-time signals. Try out our feature here and share your feedback with bq-continuous-queries-feedback@google.com! Synthetic data generator tool is available for Managed Service for KafkaYou’ve launched your first Kafka cluster. Now what? The next thing to do is to produce some data to the cluster, but that involves modifying a client application somewhere or spinning up a virtual machine. The synthetic data generator tool, now generally available, can start sending mock data to your cluster in 3 clicks, and will get data streaming into your cluster in less than two minutes. The perfect utility for those moments you just want to test your cluster and new features. Try our quickstart today! Dataflow pipeline updates are faster & more flexibleDataflow pipeline updates can now stop-and-replace pipelines, a major addition to the existing in-place-update feature. The new parallel pipeline option accelerates the migration between the old & new pipeline, resulting in reduced disruption to your business. You can also set a timeout on drains that prevents runaway costs for your pipeliness in the event of stuck processing. This feature is generally available. Try it here! Aug 17 - Aug 21 Webinar: Agent Identity as the backbone for secure AI innovationAn AI agent with a stolen API key looks identical to a legitimate one. As autonomous agents scale across enterprise systems, static credentials and legacy IAM policies can no longer keep up with machine-speed execution. Join Shaun Liu, Product Manager at Google Cloud, on August 27 at 1 PM ET to explore Google Cloud’s vision for unifying agent, human, and nonhuman identity into a workload-centric platform using verifiable cryptographic identities (SPIFFE, ID-JAG, OAuth).Register for the webinar now Aug 10 - Aug 14 Diagnosing Apigee Hybrid Cassandra Read Latency for Peak PerformanceDiagnose real-time Cassandra read latency and resolve API key verification bottlenecks in Apigee Hybrid with this step-by-step troubleshooting guide. Learn how to deploy a debugging client and query performance tables to maintain sub-millisecond response times. Read the Apigee Hybrid Cassandra Troubleshooting Guide Keep moving with agents! The All Things Agentic Hackathon is officially live.We're challenging builders to build next-generation agents that take on the busy work and handle the heavy lifting in the background using Gemini 3.5 and Google Cloud. Compete for your share of $190,000 in prizes, cash, and Google Cloud credits! Submissions are open from August 3, 2026, to August 31, 2026.Learn more and register. Sign up for GEAR to get exclusive updates and your badge. # Accelerate PostgreSQL migrations using Gemini in Database Migration ServiceEnterprise database migrations often stall during the "last mile" of translating legacy stored procedures, triggers, and custom functions from Oracle or SQL Server. Database Migration Service (DMS) now provides AI-assisted code conversion powered by Gemini in Databases. By combining deterministic compiler rules for 1:1 syntax with Gemini contextual synthesis for complex procedural blocks, DMS converts legacy code into native PostgreSQL and AlloyDB with full schema awareness and side-by-side validation.Read the full blog post to learn how to streamline your database code conversion. Compute Flex CUDs now available for G2 and G4 GPU VMsCompute Flexible Committed Use Discounts (Flex CUDs) are now available for G2 (NVIDIA L4) and G4 (NVIDIA RTX Pro 6000) VMs. You can now lock in predictable savings while retaining the flexibility to adapt across VM families, migrate between regions, and combine general-purpose compute, GKE, Cloud Run, and G2 & G4 GPU VMs under a single spend commitment. Flex CUDs for G-series VMs let you lock in savings today while preserving the agility to upgrade to latest hardware without disruption!Explore VM instance pricing or learn more about Flex CUDs. Rapid Bucket accelerates the training and checkpoint performance in PyTorch Ecosystem via GCSFSWith the release of GCSFS 2026.8.0, organisations can now unlock maximum ROI from their AI/ML infrastructure by eliminating data starvation on GPUs in PyTorch ecosystem when they are using Frameworks like Dask, Pandas, PyTorch , PyTorch Lightning, Hugging Face Datasets, Ray dataetc. By making adaptive concurrent prefetching the default, GCSFS dynamically predicts and background-fetches sequential read patterns—boosting single-file throughput by 5x, and scaling up to 21 GiB/s , saturating the NIC when paired with Rapid Bucket. Saturating the NIC translates to significantly improved accelerator goodput and reduced training wait times with zero integration friction. Training and checkpoint restore workflows benefit from intelligent memory management that automatically drains the buffer during random reads to completely avoid bandwidth or memory penalties. Aug 3 - Aug 7 Navigate data sovereignty and AI innovation with hybrid cloudFor enterprises facing strict compliance rules, keeping sensitive data on-premises often means missing out on cutting-edge AI. Data from the 2026 State of AI Infrastructure report reveals that 52% of IT leaders are adopting hybrid cloud strategies to bridge this gap. Our latest blog post explores how Google Distributed Cloud (GDC) helps organizations deploy connected or air-gapped models to run advanced AI entirely within secure environments—mitigating geopolitical risks without sacrificing innovation. Read more. SAP and Google Cloud Launch BDC Connect for BigQueryFor years, enterprises have struggled with the cost, risk, and complexity of moving mission-critical SAP data into advanced analytics platforms. The general availability of SAP Business Data Cloud (BDC) Connect for BigQuery marks a turning point. By introducing revolutionary zero-copy, bi-directional data sharing, this new capability seamlessly bridges SAP systems with Google Cloud's powerful data and AI ecosystem. Instead of wrestling with manual data duplication and lost business context, organizations can now eliminate silos, dramatically lower their analytics costs, and rapidly deploy trustworthy, agentic AI solutions grounded in real-time operational reality. Read the full announcement to learn how to transform your data strategy. Google Cloud Cortex Framework version 7 is now generally available!This release helps you modernize your data architecture for AI agent readiness, enabling you to quickly deploy, customize, and extend robust data products while simplifying orchestration and reducing infrastructure overhead. It provides data product accelerators for SAP-sourced data to build trusted, high-quality data products ready for advanced analytics and agentic use cases. The Framework integrates with Google Cloud products including BigQuery, Dataform, Knowledge Catalog, and Gemini Enterprise Agent Platform. Learn more in our announcement blog, technical documentation, or try a demo deployment today. From API Management to AI Gateway with ApigeeMassive LLM adoption unlocked automation but exposed critical vulnerabilities, from unpredictable token costs to security risks like prompt injection. Without central management, organizations face accelerated technical debt. Learn how to transform Apigee into an enterprise AI Gateway to centralize governance. This architectural roadmap details how to utilize semantic cache to optimize token costs, implement prompt protection policies for security, and productize tools using the emerging MCP standard.Read the full architectural roadmap on the Apigee Community Hub Centrally govern enterprise AI traffic with Apigee AI GatewayManage, track, and secure model communication across your entire infrastructure from a single pane of glass. In a new video walkthrough, Principal Architect Tyler Ayers demonstrates how Apigee AI Gateway simplifies agentic governance. Learn how to transparently proxy model traffic, log real-time token counts, and apply runtime security quotas without impacting your developer workflow.Watch the Apigee AI Gateway demo Maximize Provisioned Throughput UtilizationSudden traffic micro-spikes can exceed per-second quotas, triggering 429 errors or forcing overflow into shared resource pools. A new architectural guide demonstrates how to build a serverless "shock absorber" using Cloud Run and Google Cloud Tasks. By decoupling request ingestion from execution, this queue-based pattern flattens volatile traffic bursts and smoothly drips requests to Gemini at your exact quota rate, maximizing Provisioned Throughput utilization while eliminating job failures during peak usage. Read the step-by-step setup guide. Eliminate security blindspots in agentic tool agentic tool calls via the Model Context Protocol (MCP) can introduce critical security risks to your enterprise architecture. Join our technical deep dive on Thursday, August 13, to discover how to position Apigee as a centralized security gateway. Featuring the new ParsePayload policy and payload operations groups in API Products, this session demonstrates how to enforce granular tool filtering, manage execution quotas, and scale secure agent ecosystems without impeding developer velocity. Register for the August 13 Community TechTalk Jul 27 - Jul 31 Data Cloud and Apigee CDMX: The AI Agent Evolution | August 12, 2026Enterprise AI demands evolution beyond basic conversational assistants. To generate real value, AI models must connect with the organization's core systems and live data sources. Join us this August 12 at Google CDMX for the exclusive event AI Evolution: Powering Tomorrow's Enterprise. Learn how to design an agile and secure ecosystem by unifying the power of Gemini, Apigee, and data agent technologies through practical demonstrations led by Google Cloud engineers.Secure your spot for the in-person session in Mexico City Register now! Vast Edge, built on GCP, launches the first live recovery interface for cloud backups, enabling IT teams to inspect backup contents in real time. This transforms backups from a blind, log-based process into an interactive platform where teams can instantly search, preview, and validate the exact data available for restore.This platform protects Google Workspace, NetSuite, Salesforce, Workday and many SaaS environments, providing complete visibility and enterprise-grade oversight.Visit Vast Edge Backup & Disaster Recovery and get a free trial of their backup solutions on the GCP Marketplace for Google Workspace Backup, NetSuite Backup, Salesforce Backup, and Workday Backup. Jul 20 - Jul 24 Claude Opus 5, Anthropic’s latest model, is now available on Agent Platform. It brings performance improvements over Opus 4.8 across coding, long-running agents, and knowledge work.The model is Zero Data Retention (ZDR) compatible. For safety, high-risk workflows — such as penetration testing or exploit generation — it will notify you and fall back to Opus 4.8.We’re excited to continue to offer enterprise customers options across frontier models to build, deploy, and scale AI securely. Try it here. Apigee Northam Roadshow 2026 | The AI Agent Evolution: Powering Tomorrow's EnterpriseAI is evolving. As your organization deploys autonomous agents, the integration between APIs and models becomes critical. Join Google Cloud specialists for an exclusive day of deep-dive sessions and live demos. Discover how the unified power of Apigee and the Google Cloud Agent Platform allows you to build, govern, and scale high-performance AI agents with complete control. Call to Action: Register for Sunnyvale | Register for NYC | Register for Chicago Deploy an Apigee Proxy for MCP Registry Discovery Learn how to deploy an Apigee X proxy to format Apigee API Hub data into the Model Context Protocol (MCP) Registry format. This tutorial by Tyler Ayers guides developers through cloning the sample repository, deploying using the Apigee Feature Templater (aft), and testing the endpoint to make API data easily discoverable by coding agents. Read the full community tutorial to get started. Simplify AI Infrastructure: Getting Started with Apigee AI GatewayManaging a complex AI landscape with multiple backend environments can present significant operational and governance challenges. A new tutorial walks you through how to build a unified API proxy using Apigee AI Gateway. By establishing a single, secure entry point for all model traffic, teams gain access to real-time analytics, comprehensive tracing, and financial operations auditing—completely seamlessly, and with absolutely no modifications required to client environments or user configurations. Read the step-by-step setup guide Your AI agents are ready. Is your data?The biggest bottleneck to scaling AI isn't the models—it's giving them access to business context. As enterprises move to proactive systems of action, legacy infrastructure often buckles under the nonlinear speed of AI agents. Google Cloud’s new Agentic Data Cloud, built on AI-native infrastructure, solves this by unifying data, AI models, and operational databases. Discover how a borderless Lakehouse and active Knowledge Catalog can empower your AI agents with trusted, real-time context without unnecessary engineering overhead. Read more. Secure and govern your AI at Apigee AI Horizon in LondonMoving AI from basic prompts to complex agentic workflows requires trust and control. Join us on Tuesday, 1st September 2026 at Google London for our 5th edition of Apigee AI Horizon. Discover how Google Cloud product leaders and architects are using Apigee and Model Armor to secure LLM APIs, implement policy controls, and manage token consumption. Do not miss this one—register soon!Secure your spot for AI Horizon London Jul 13 - Jul 17 Resource-Based CUD Sharing is Now Enabled by DefaultStarting June 16, 2026, the default setting for Google Cloud Resource-based Committed Use Discount (CUD) sharing will change from disabled to enabled for new billing accounts and eligible existing accounts without active CUDs. This update automatically maximizes your savings by pooling underutilized discounts across your resources.You retain full control and can adjust your CUD sharing preferences at any time by changing your CUD scope configuration. For instructions, see Enable CUD sharing or Disable CUD sharing. Webinar for India: Google Cloud for EdTech: Optimizing Traffic and Token Governance at ScaleAPI traffic surges and AI model integration are reshaping the EdTech landscape. Join Satyam Maloo for the webinar Google Cloud for EdTech: Optimizing Traffic and Token Governance at Scale on July 23, 2026. Learn to implement advanced rate limiting, gain granular token visibility, and leverage real-time analytics to govern your platform effectively. Whether you’re scaling for peak academic seasons or integrating complex AI workflows, this session provides the infrastructure blueprint you need.Register Now Scaling AI Agents: Treat prompts like software artifactsAs AI agents move into production, monolithic system prompts often result in configuration drift, merge conflicts, and silent runtime failures. The solution is adopting a Prompts-as-Code architecture. By breaking prompts into modular skill files and using a build-time transpiler, engineering teams can introduce dependency resolution, static validation, and CI/CD rigor to their agent's control plane. Stop manually editing massive text files and start building deterministic, reliable agent infrastructure.Read more here. Jul 6 - Jul 10 Webinar: Introducing Google Cloud NGFW Enterprise advanced malware protection - powered by Palo Alto NetworksDiscover the new Cloud NGFW advanced malware sandbox, arriving in preview later this year. Powered by Palo Alto Networks Advanced Wildfire, it leverages data from 70,000+ customers to help defeat advanced malware. Join us on July 16 at 11 AM EDT to learn how to build a resilient, zero-trust cloud infrastructure that protects your apps and data, wherever they reside.Register for the webinar now Safely run AI-generated code in Cloud Run sandboxesCloud Run sandboxes, now in public preview, are lightweight, isolated execution boundaries that you can spawn near-instantly within your existing Cloud Run service instances.Whether you need to let an LLM run a dynamically generated Python script to calculate business margins or spin up a headless browser to perform web research, Cloud Run sandboxes give you a secure, isolated sandbox to run these tasks without leaving your serverless environment.Read the blog to learn more and get started today. Australia API Horizon: Scaling Enterprise Governed AI AgentsThe transition from AI chatbots to autonomous agents is the most critical integration point for your business. Join Google Cloud at our upcoming events to explore exclusive deep-dive sessions on architecting for the agentic era.Discover how to use Apigee as an intelligent AI Gateway to govern, secure, and scale high-performance architectures. You will learn to seamlessly build AI tools from your existing APIs and maintain control over your entire ecosystem.Join us in your preferred city: Sydney: July 28, 2026, at Google Sydney, One Darling Island. Canberra: July 29, 2026, at Hotel Realm. Melbourne: August 4, 2026, at Google Melbourne. Build highly available, multi-region services on Cloud RunMaintaining uptime for business-critical applications just got a lot easier on Cloud Run. Service health, now Generally Available, automates cross-region failover by leveraging readiness probes for instance-level health checks with a simple, two-click setup. You can configure service health with global external Application Load Balancers for public-facing applications or cross-region internal Application Load Balancers for private networking traffic.Learn how to configure service health for Cloud Run. Report: 83% of organizations need infrastructure upgrades for agentic AIThe shift from conversational bots to autonomous agents is breaking legacy systems. Our new State of AI Infrastructure report details how engineering leaders are adapting to these massive new workloads. To eliminate inference bottlenecks, control hidden scaling costs, and manage agent sprawl, the industry is rapidly moving toward fluid compute, centralized governance, and unified, co-designed architectures.Explore our key infrastructure insights Stop tinkering, start scaling: the industrialized AI PlaybookDid you know that only 5% of custom AI investments actually return measurable business value? The problem isn’t the technology—it’s how organizations are wired to run it.In this compelling read, Google Cloud Consulting breaks down the operational blueprint that bridges the stark gap between "cool tech experiments" and real, P&L-impacting enterprise ROI.Read the full article on Medium AI Agent Clinic: Slashing App Latency by 80%Prototyping an AI agent is easy, but scaling for live traffic presents unique challenges. In the latest AI Agent Clinic, our technical experts partner with a developer to optimize PlaybackIQ, a live football analysis agent. This session demonstrates how to use OpenTelemetry to trace bottlenecks in the Gemini Enterprise Agent Platform and deploy to Cloud Run for high-concurrency scaling, achieving an 80% reduction in response time. Learn production-grade debugging strategies to optimize your own LLM applications.Watch the 60-minute teardown Jun 29 - Jul 3 Claude Sonnet 5, Anthropic’s latest model, is now available on Agent Platform. This addition serves as a drop-in replacement for Sonnet 4.6, giving organizations expanded choice for task completion across enterprise workflows. It features enhanced reasoning, cleaner code generation, and computer use capabilities for desktop and browser workflows.By continuing to rapidly bring frontier models to our platform, Google Cloud offers an uncompromised choice of the industry's best technology to build, test, and scale enterprise-grade AI.Get started today. Automate your AI governance with Apigee and YAMLManual API gateway configurations can quickly slow down your AI engineering velocity. Join the Apigee community on Thursday, July 16, to discover an automated, declarative blueprint for model garden management. Learn how a simple, repeatable YAML pattern lets your AI practitioners instantly spin up secure, policy-backed enterprise configurations without friction. Bring your questions and connect during our live Q&A session. Register for the July 16 Community TechTalk Build next-generation AI portals for autonomous agentsStandard developer portals were designed for human developers to subscribe to static APIs. Today, autonomous agents, LLM toolkits, and dynamic runtimes demand a central nervous system for governance. Join our technical deep dive on Thursday, July 23, to explore Apigee's new AI Portals solution. You will see exactly how to deploy full-service, MCP powered hubs to safely manage enterprise self-service for models, tools, and agents. Register for the July 23 Community TechTalk Protect your infrastructure from advanced cyberattacks at the API layer (Presented in Portuguese)In an era of increasingly sophisticated threats, relying solely on traditional firewalls leaves critical data gaps. Join our technical community TechTalk on Thursday, July 30—conducted in Portuguese—to learn how to proactively mitigate risks directly at the gateway layer. This session demonstrates how to configure and govern essential Apigee security policies to build a robust line of defense, ensuring maximum availability and complete integrity for your enterprise microservices. Register for the July 30 Portuguese Community TechTalk Jun 22 - Jun 26 Accelerate TPU model loading while saving RAM on GKE.Large model cold starts often stall scaling and leave high-value TPUs idle. The open-source Run:ai Model Streamer now natively supports TPUs with Google Cloud Storage in TPU vLLM 0.18.0. This integration accelerates inference pipelines on GKE by streaming tensors directly into CPU memory, bypassing local disk bottlenecks and the "double-buffering" trap. In benchmarks, loading a 480B parameter model was over 2x faster while cutting peak host memory usage by half. Read the full guide and get started today. Stop Training Blind: Scaling AI with the New OpenTelemetry-Based TPU AI Telemetry Collector AgentGoogle Cloud’s new AI Telemetry Collector agent standardizes TPU monitoring using OpenTelemetry. It optimizes enterprise ML workloads by identifying silent failures and providing zero-cost operational metrics without draining host CPU cycles. The agent seamlessly routes telemetry to Google Cloud Monitoring or Prometheus and custom Grafana setups. Pre-installed on Google-optimized Ubuntu images or available via Docker, it tracks memory, network latency, and core utilization to maximize multi-node training efficiency.You can read more of this capability by clicking this link. Jun 15 - Jun 19 Join us for a deep dive into agentic AI control with AppyThingsYour integrations aren’t failing—they are evolving. When users interact with AI agents, they no longer arrive directly at your site, resulting in experiences stripped of your context, expertise, and intended experience. Join us on Thursday, June 25, for a community tech talk in partnership with AppyThings to learn how to solve this new gateway challenge. We will explore how MTN laid an integration foundation with the Model Context Protocol (MCP) to deliver accurate, consistent experiences. Our technical experts will demonstrate how to leverage Apigee as a centralized tools management solution to govern agent access. Register for the session Optimize Spot VM Deployments with Capacity Advisor for Spot, Now in Public PreviewGoogle Compute Engine has launched Capacity Advisor for Spot to Public Preview, now open to all customers. This tool turns Spot capacity discovery into a data-driven process by providing real-time deployment recommendations to maximize obtainability and minimize preemption risks. Query the Capacity Advisor API for obtainability and minimum estimated uptimes, or use the new Console UI featuring a global availability map, spot price lookups, and historical preemption rate trends to visually find the most cost-efficient compute capacity.Get started today to start optimizing your Spot VM deployments! Build a multi-tenant agentic AI systemWhen scaling generative AI across different business units, your teams need specialized AI agents with unique operational rules and tools. Our new reference architecture helps you build a centralized multi-tenant platform to prevent fragmented silos, eliminate data exposure risks, and maintain unified compliance. Read the guide to design and deploy a multi-tenant agentic AI system in Google Cloud. How to Configure Gemini Enterprise to Connect to a Custom MCP ServerThe Gemini Enterprise MCP Connector was a big announcement at Google Cloud Next because it introduces the ability to connect Gemini Enterprise to MCP servers. This blog post provides a step-by-step guide on how to configure your first Custom MCP Server connector using the Google Maps Ground Lite MCP server as an example. Once you understand this flow, you can configure multiple MCP servers with Gemini Enterprise to bring all the context you need. Jun 8 - Jun 12 Simplify Multi-Cloud Planning with Cloud Location Finder, now Generally Available Cloud Location Finder provides up-to-date data on public regions, zones, and Google Distributed Cloud Connected locations across Google Cloud, AWS, Azure, and OCI. You can now programmatically discover locations based on provider, proximity, territory, and carbon footprint to optimize your global infrastructure strategy for performance, compliance, and sustainability. Get started for free today Jun 1 - Jun 5 Modeling the physical world with BigQuery GraphManaging complex supply chains requires more than just spreadsheets; it requires a digital replica of the physical world. In this post, Guru Rangavittal and Candice Chen explore how BigQuery Graph enables organizations to build a digital twin by turning physical assets into an interconnected map of nodes and edges. By moving beyond traditional relational databases, businesses gain real-time clarity into operations—from executing surgical ingredient recalls to analyzing weather-driven logistics risks. Discover how BigQuery Graph transforms reactive firefighting into proactive, precision modeling, allowing you to see critical connections in seconds and future-proof your supply chain. Apigee for AI: Govern LLMs and MCP Servers (Presented in Spanish)Learn how to securely transition your AI initiatives from experimental prototypes to enterprise-ready deployments. Join Luis Cuellar on June 18 for a technical deep dive (presented in Spanish) exploring Apigee’s latest AI gateway capabilities. Discover how to centralize governance over Model Context Protocol (MCP) servers, protect Large Language Models (LLMs) with robust API gateway security policies, and manage token-based quotas.Register for the June 18 Spanish Community TechTalk May 25 - May 29 Anthropic’s Claude Opus 4.8 is now available on Gemini Enterprise Agent Platform. As we continue to expand our platform's model offerings, this addition gives organizations more options for handling complex, multi-stage enterprise workflows. Claude Opus 4.8 brings strong capabilities in agentic coding, allowing developers to manage extensive refactors and tracking dependencies over extended sessions. API Horizon Munich July 6, 2026: Orchestrating the Next Era of AI and APIs Master the orchestration of next-gen AI and digital ecosystems. Join Google Cloud experts and DACH tech leaders on July 6 for an exclusive look at the Apigee roadmap, Agent Management, and Model Context Protocol (MCP). Gain real-world insights and connect with the regional integration community.Register now Securing AI Agents: The Extended Agent Gateway PatternLearn how to prevent autonomous AI agents from invoking unauthorized APIs. Join Apigee Specialist Joel Gauci on June 4 for a technical deep dive into the Extended Agent Gateway pattern. This session covers enforcing Fine-Grained Authorization (FGA), implementing secure token exchange, and establishing Model Context Protocol (MCP) governance at the API gateway layer to protect enterprise backend services.Register for the June 4 Community TechTalk API-to-Agent Security: Exposing REST APIs to Gemini Enterprise via MCPConnect Gemini Enterprise agents to core data without creating security hazards. Join Google Cloud Specialist Nigel Walters on June 11 to learn how to instantly transform legacy REST APIs into secure Model Context Protocol (MCP) servers. We’ll cover how to safely register tools with Gemini while enforcing gateway-level guardrails like rate limiting and access control policies.Register for the June 11 Community TechTalk May 18 - May 22 Chinese Webinar | June 4: AI Command and ControlAs AI agents move from experimental pilots to core enterprise functions, governance has become a critical next step. Join Google Cloud on June 4th at 10:00 AM (Beijing Time) to learn how to build a secure AI management layer architecture. We'll explore how to develop governed MCP (Model Context Protocol) endpoints, manage tool access to enterprise data, and leverage robust audit logs to operationalize AI. This session also includes a practical demonstration of these governance frameworks on Google Cloud.Register here GCP Announces New Features to Benchmark and Optimize LLMs for On-Device Use CasesDeploying fine-tuned LLMs from GCP to edge devices like smartphones is complex due to fragmented hardware. Google AI Edge Portal bridges this gap, giving GCP developers the ability to test AI performance on 120+ Android devices, representing the full diversity of high, medium, and low tier smartphones on the market today. This week at I/O, we announced brand new capabilities to benchmark and debug LLM performance across these devices. Sign-up to utilize these new features in private preview today. May 11 - May 15 Build Your AI & MCP Control Tower for Universal GovernanceMaster the future of agentic security with Apigee. Join our Community TechTalk on May 21 to discover how Apigee serves as a central "Control Tower" for the Model Context Protocol (MCP). We will explore how new JSON-RPC tool authorization enables fine-grained access policies across your organization, ensuring secure and scalable AI deployments. Whether managing internal tools or external users, learn to govern your agentic ecosystem with absolute precision. This session is designed for global coverage across EMEA and AMER regions.Register for the May 21 Community TechTalk Apr 27 - May 1 Master Your Launch: The Apigee Production Go-Live ChecklistEnsure a secure launch with the Apigee production guide. Join Nicola Cardace on May 28 to explore security guardrails, including IAM roles, mTLS configurations, and encrypted KVM migrations. Scheduled at 11 AM EDT / 5 PM CEST to support EMEA and AMER teams, this TechTalk provides the technical roadmap you need to flip the switch with absolute confidence.Register for the May 28 Community TechTalk Transforming APIs into Governed Agentic Tools on the Google Cloud Agentic PlatformTurn your APIs into secure, governed agentic tools on the Google Cloud Agentic Platform. Join Specialist Christophe Lalevée on May 7 for a technical deep dive into AI productization. Scheduled at 5 PM CEST / 11 AM EDT to maximize coverage for developers across EMEA and AMER, this session explores the integration and governance frameworks required to scale enterprise-ready AI with confidence. Register for the May 7 Community TechTalk Fractional G4 VMs are Generaly Available, providing a highly efficient and cost-effective entry point for AI and graphics workloads. These new configurations, using NVIDIA virtual GPU (vGPU) technology, allow you to leverage the power of the NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs in flexible, smaller increments, so you can right-size your infrastructure to match the specific demands of your applications. By providing more granular access to advanced hardware, fractional G4 VMs let you optimize resource allocation and reduce overhead without sacrificing performance. You can now select from additional GPU slice sizes for your specific needs: 1/2 GPU: Ideal for more intensive tasks such as LLM inference, robotics sensor simulation, and high-fidelity 3D rendering. 1/4 GPU: Optimized for mainstream workloads, including mid-range creative design, video transcoding, and real-time data visualization. 1/8 GPU: Great for lightweight applications such as remote desktops, productivity tools, and entry-level streaming services. Transitioning AI from a sandbox prototype to an enterprise-grade system is a major hurdle. A monolithic script won't suffice for widespread deployment. To achieve true scale and reliability with Gemini, organizations must adopt service-oriented micro-agent architectures, establish Zero-Trust security, and implement rigorous EvalOps. Master the "Agentic Maturity Ladder" to ensure your AI & Agentic solutions are robust, secure, and ready for the real world. Watch the deep dive and read the developer blog to learn more. ML Development in VS Code with Google Cloud Power: Workbench Extension Now AvailableData scientists and developers can now combine the local productivity of VS Code with the scalable infrastructure of Google Cloud. The new Google Cloud Workbench Notebooks extension allows you to connect to and run notebooks on managed cloud environments directly within your local IDE. This integration streamlines the ML lifecycle by eliminating context switching and providing high-performance compute for complex workloads in a familiar interface. As part of our commitment to the developer ecosystem, the extension is fully open-sourced to support community-driven innovation. Install from Marketplace: GoogleCloudTools.workbench-notebooks Contribute on GitHub: colab-enterprise-vscode Apr 20 - Apr 24 Announcing the 2026 Google Cloud Partners of the YearGoogle Cloud is honored to celebrate the winners of the 2026 Partner of the Year awards! These awards recognize an exceptional group of partners across AI, Security, Infrastructure, and more, who have demonstrated a commitment to customer success. From global system integrators to specialized startups, these winners are leveraging the power of Google Cloud to solve complex challenges and drive digital transformation worldwide. Join us in congratulating these organizations for their innovation, collaboration, and impactful results over the past year.See the 2026 Partner Award winners Apr 13 - Apr 17 We're excited to announce the Public Preview of Datastream’s metadata integration with Knowledge Catalog. This is the first step in our vision to provide a centralized, "single pane of glass" for all Datastream assets. The enhancement automatically synchronizes Streams, Connection Profiles, and Private Connections, eliminating data silos. It enhances discoverability, allowing you to search for Datastream assets using the same interface as BigQuery tables. Centralized governance is also provided, making your real-time data estate more transparent and easier to manage. Upgrading Apigee OPDK to 4.53 with OS your infrastructure using Google’s official, sequential upgrade path. Our Technical expert, Rakesh Talanki outlines how to upgrade Apigee OPDK to v4.53 while migrating to a supported OS (RHEL 8.x/9.x). This guide covers the "build-out" methodology, including multi-data center syncing, to ensure a stable, zero-downtime transitionRead the guide Cloud Run Worker Pools and CREMA: Powering Serverless AI at ScaleGoogle Cloud has announced the General Availability of Cloud Run worker pools, a new resource type designed specifically for pull-based, non-HTTP workloads. Unlike traditional Cloud Run services that scale based on request traffic, worker pools provide an "always-on" environment for background tasks like processing message queues or running large-scale AI inference. To support this, Google Cloud also open-sourced the Cloud Run External Metrics Autoscaler (CREMA). Built on KEDA, CREMA enables queue-aware autoscaling for worker pools, allowing them to dynamically scale based on external signals like Pub/Sub backlog or Kafka lag. Apigee Model Context Protocol (MCP) now Generally AvailableExpose enterprise APIs as MCP tools for agentic AI applications with the General Availability of MCP in Apigee. This update allows developers to transform APIs into AI-ready tools using OpenAPI Specifications, removing the need for local MCP servers or additional infrastructure. With managed endpoints and semantic search in API hub, you can now provide AI agents with secure, governed access to enterprise data at scale.Explore the MCP overview Apr 6 - Apr 10 Community TechTalk: Powering Retail Agents with ADK, UCP & Apigee XMove beyond basic chatbots to secure, transactional AI experiences. Join our Community TechTalk on April 16 to learn how Apigee X and Gemini build a "Trust Layer" for AI shopping assistants using UCP standards. We’ll demonstrate how to block prompt injections with Model Armor and implement cost governance via token limits to secure the path from discovery to purchase.Register for the TechTalk Implement multimodal capabilities in your AI agentsExplore three new reference architectures for building sophisticated multi-agent AI systems that can process and analyze multimodal data. To analyze disparate multimodal data and produce a high-confidence classification, see Classify multimodal data. To create a fluid conversational AI that processes audio and video streams in real time, see Enable live bidirectional multimodal streaming. To consolidate fragmented multimodal data into a searchable knowledge graph, see Multimodal GraphRAG resource orchestration. Automate SecOps workflows with an agentic AI systemTo accelerate incident response and reduce manual toil for your security team, you need a system that can automate remediation playbooks. Our new reference architecture helps you build an AI agent that orchestrates complex triage and investigation workflows across disparate security tools, such as SIEM, CSPM, and EDR, from a single interface. See the full guide to orchestrate security operations workflows. Mar 30 - Apr 3 ASEAN Webinar | April 30: Mastering Agentic Governance at Scale with GCPAs AI agents move from experimental pilots to core enterprise functions, governance is the critical next step. Join Google Cloud experts Shilpi Puri & Wely Lau for a webinar on April 30th at 11:00 AM SGT to learn how to architect a secure AI Management layer. We’ll explore developing governed MCP endpoints, managing tool access to enterprise data, and operationalizing AI with robust audit logs. The session includes a live demo of these frameworks in action on Google Cloud.RSVP here. Mar 23 - Mar 27 Turn your API sprawl into an agent-ready catalogAs organizations scale, APIs often become scattered across multiple gateways, creating "blind spots" that hinder AI adoption. To solve this, we’ve introduced two new capabilities for Apigee API hub: a new integration with API Gateway to automatically centralize API metadata into a single control plane, and a specification boost add-on (now in public preview). This add-on uses AI to enhance your API documentation with the precise examples and error codes that AI agents need to function reliably.Read the full blog post to get started. Webinar | April 16: AI Command & ControlAs AI agents move from experimental pilots to core enterprise functions, governance is the critical next step. Join Google Cloud expert Satyam Maloo for a webinar on April 16th at 11:00 AM IST to learn how to architect a secure AI Management layer. We’ll explore developing governed MCP endpoints, managing tool access to enterprise data, and operationalizing AI with robust audit logs. The session includes a live demo of these frameworks in action on Google Cloud.RSVP here. Modernizing and Decoupling Event Ingestion with ApigeeIn modern cloud-native architectures, decoupling producers from consumers is critical for building resilient systems. While Google Cloud Pub/Sub provides a scalable backbone, exposing it directly to external clients can introduce security and management overhead. This new guide explores how to leverage Apigee as an intelligent HTTP ingestion point. Learn how to handle security, mediation, and traffic control before messages reach your internal bus using the PublishMessage policy or Pub/Sub API.Read the full guide. Mar 16 - Mar 20 Gemini-powered Assistant in BigQuery Studio Gets Context-Aware UpgradesThe Gemini-powered assistant in BigQuery Studio has been transformed into a fully context-aware analytics partner, supporting your entire data lifecycle. The new capabilities include intelligent resource discovery, which uses Dataplex Universal Catalog search to find resources across projects and deep dive into metadata using natural language. You can now automate tasks, such as scheduling production-grade queries directly through the chat interface, and instantly troubleshoot long-running or failed jobs with root cause analysis and cost control auditing.Explore the full range of what the assistant can do. Mar 9 - Mar 13 Want to use Gemini to develop code and don't know where to start?This article includes a couple of examples of developing code with Gemini prompts; it identified changes that were needed to be made to get the code working. The article also refers to other examples that are available on github. Mar 2 - Mar 6 Introducing Gemini 3.1 Flash-Lite, our fastest and most cost-efficient Gemini 3 series model. Built for high-volume developer workloads at scale, 3.1 Flash-Lite delivers high quality for its price and model tier. Gemini 3.1 Flash-Lite can tackle tasks at scale, like high-volume translation and content moderation, where cost is a priority. And it can also handle more complex workloads where more in-depth reasoning is needed, like generating user interfaces and dashboards, creating simulations or following instructions. Starting today, 3.1 Flash-Lite is rolling out in preview to enterprises via Vertex AI and developers via the Gemini API in Google AI Studio. TechTalk: Implementing Device Authorization Grant (RFC 8628) for ApigeeLearn how to authorize "headless" devices like Smart TVs or AI agents that lack keyboards and browsers. Join our Community TechTalk on March 19 (5PM CET / 12PM EDT) to go under the hood of Apigee X/Hybrid. We’ll cover the real-world mechanics of state management, polling, and human-in-the-loop security patterns for devices and autonomous agents. Register for the TechTalk Feb 23 - Feb 27 Pro-level image generation gets faster and more accessible with Nano Banana 2Nano Banana 2 is our state-of-the-art image generation and editing model. It delivers Pro-level image generation and editing at the speed you expect from Flash — making the quality, reasoning, and world knowledge you loved about Nano Banana Pro more accessible. Learn more about the model here. The Intelligent Path to Compliance: Transforming Regulatory QC with Google CloudReducing "Refuse to File" (RTF) risks and submission cycle times is critical for life sciences leaders. Google Cloud’s Regulatory Submission Semantic QC Auditor leverages Gemini and RAG architecture to transform Quality Control from a manual burden into an active, intelligent workflow. By automating semantic cross-referencing, narrative coherence checks, and dynamic guidance-based auditing, this solution ensures rigorous accuracy and auditability. Operating within a secure GxP-ready environment, it empowers teams to detect subtle inconsistencies and generate remediation plans without sacrificing data privacy. Learn more. Stop typing, start interacting! The Gemini Live Agent Challenge is here. Build immersive agents that can help you see, hear, and speak using Gemini and Google Cloud. Compete for your share of $80,000+ in prizes and a trip to Google Cloud Next '26!Submissions are open from February 16, 2026 to March 16, 2026. Learn more and register at .devpost.com Feb 9 - Feb 13 Introducing Gemini 3.1 Pro on Google Cloud. 3.1 Pro is a noticeably smarter, more capable baseline for complex problem-solving. We’re shipping 3.1 Pro at scale, building upon our goal to help you transform your business for the agentic future. Learn more about the model’s capabilities here. Gemini 3.1 Pro is available starting today in preview in Vertex AI and Gemini Enterprise. Developers can access the model in preview via the Gemini API in Google AI Studio, Android Studio, Google Antigravity, and Gemini CLI. Automate Storage Compatibility with GKE Dynamic Default Storage ClassesManaging storage across mixed-generation VM clusters in GKE just got easier. With the new Dynamic Default Storage Class, Google Kubernetes Engine automatically selects between Persistent Disk (PD) and Hyperdisk based on a node's specific hardware compatibility. This abstraction eliminates the need for complex scheduling rules and manual pairing, ensuring your volumes "just work" regardless of the underlying infrastructure. By defining both variants in a single class, you reduce operational overhead while maintaining peak performance and cost-efficiency across your entire cluster.Explore automated disk type selection Community TechTalk: AI-Powered Apigee Development with strofa.ioJoin the Apigee community on February 26 for a deep dive into strofa.io. Guest speaker Denis Kalitviansky will demonstrate how this new AI-powered tool automates and orchestrates Apigee development, from local emulators to large-scale hybrid environments. Discover how to scale your API management and streamline team collaboration using the latest in AI-driven automation. Register now to reserve your spot. Jan 26 - Jan 30 Simplify API Governance with Native OpenAPI v3 SupportEliminate integration debt and accelerate deployment velocity with the General Availability of OpenAPI v3 (OASv3) support for API Gateway and Cloud Endpoints. You no longer need to downgrade modern specifications to OASv2. Instead, you can now define API contracts and enforce critical policies—including telemetry, quotas, and security—using native Google-specific extensions directly within your OASv3 files. This update ensures your APIs are secure by design while remaining fully compatible with the modern developer ecosystem and Google Cloud’s AI services.Get started with OpenAPI v3 on API Gateway and Cloud Endpoints. Accelerate API Testing with the New Open Source API TesterStart validating your APIs with API Tester, a simple, YAML-based Test Driven Development (TDD) framework. Designed for the Apigee community, this tool allows you to write human-readable tests, run them instantly via a web client or CLI, and perform deep unit testing on Apigee proxies. With native support for JSONPath assertions and Apigee shared flows, you can verify everything from payload data to internal variables like proxy.basepath without leaving your terminal.Explore the API Tester guide and start testing your proxies today. Secure Sensitive Data with Kubernetes Secrets in Apigee hybridEnhance security in Apigee hybrid by accessing Kubernetes Secrets directly within your API proxies. This hybrid-exclusive feature keeps sensitive credentials within your cluster boundary and prevents replication to the management plane. It supports strict separation of duties: operators manage secrets via kubectl, while developers reference them as secure flow variables—ideal for high-compliance and GitOps workflows.Implement Kubernetes Secrets in your hybrid proxies. See the Console in a Whole New Light: Dark Mode is Now Generally Available in Google CloudElevate your cloud management workflow with Dark Mode, now generally available in the Google Cloud console. We have delivered a modern, cohesive, and accessible experience reimagined for maximum comfort and productivity—especially during extended working hours and low-light environments. Dark Mode can be enabled automatically based on your operating system's preference, or manually through the Settings -> Appearance menu.Switch to Dark Mode today to enjoy a modern, comfortable, and productive environment! Apigee X Networking: PSC or VPC Peering?Deciding how to connect Apigee X? Watch this video to compare Private Service Connect and VPC Peering. We break down northbound and southbound routing, IP consumption, and how to reach targets on-prem or in the cloud. Learn to simplify your architecture and avoid common networking "gotchas" for a smoother deployment.Watch the video. Jan 19 - Jan 23 Bridge the Gap: Excel-to-API Conversion in Apigee PortalsGive your customers more ways to connect! This new article by Tyler Ayers explores how to extend the Apigee Integrated Portal to support direct Excel file uploads. By leveraging SheetJS and custom portal scripts, you can enable users to upload spreadsheets, preview data, and submit it directly to your APIs, all without writing a single line of integration code themselves. It’s a powerful way to simplify onboarding for those who aren't yet API-ready.Learn how to build it. Elevate your applications with Firestore’s new advanced query engineWe have fundamentally reimagined Firestore with pipeline operations for Enterprise edition. Experience a powerful new engine featuring over a hundred new query features, index-less queries, new index types, and observability tooling to improve query performance. Seamlessly migrate using built-in tools and leverage Firestore’s existing differentiated serverless foundation, virtually unlimited scale, and industry-leading SLA. Join a community of 600K developers to craft expressive applications that maximize the benefits of rich queryability, real-time listen queries, robust offline caching, and cutting-edge AI-assistive coding integrations.Learn more about Firestore pipeline operations.
CoreWeave's stock dropped 20% during the first three trading sessions of this week, then Nvidia CEO Jensen Huang stepped in to say he had confidence in the company. But will that be enough to prop up the stock? Mandeep Singh of Bloomberg Intelligence has more. (Source: Bloomberg)
Google's Gemini 4 Argon is closer to the AI frontier than any Google model in months
Google Deepmind's Gemini 4 Argon scored 97.5 percent on the ARC-AGI-3 benchmark, making Google the second lab after OpenAI to cross the 95 percent mark. But the results swing wildly depending on the test setup: in the standard harness, the score drops to just 49.8 percent. Argon also trails rivals in math and software engineering. The article Google's Gemini 4 Argon is closer to the AI frontier than any Google model in months appeared first on The Decoder.
AI safety worries multiply but everyone’s still racing full speed ahead
The drumbeat over how safe artificial intelligence is — or more to the point, isn’t — just keeps louder. In the wake of weeks of incidents involving rogue agents, with likely more to come, more government officials are calling for regulation, even if President Trump says it’s not needed. Several states are suing OpenAI over […] The post AI safety worries multiply but everyone’s still racing full speed ahead appeared first on SiliconANGLE.
Open AI's new Rosalind Academic Plan gives research labs up to 30 free seats for a year
OpenAI is launching the Rosalind Academic Plan, a free offering that's currently open only to research labs at US universities without an enterprise contract. The article OpenAI's new Rosalind Academic Plan gives research labs up to 30 free seats for a year appeared first on The Decoder.
Anthropic gives METR inside access to audit its AI models and safety practices
Anthropic has given a team from the nonprofit METR inside access to review its AI models and safety practices, the company announced. The article Anthropic gives METR inside access to audit its AI models and safety practices appeared first on The Decoder.