September 25, 2026
Meta opens early access program for new Muse features
Anyone interested in joining has to ask Muse to put them on the list.
Read original articleDataAIHub Daily
Archive →50 curated AI news stories from leading AI companies.
September 25, 2026
Anyone interested in joining has to ask Muse to put them on the list.
Read original articleSeptember 25, 2026
OpenAI said it has notified “dozens” of organizations, including governments and universities, whose websites may have been hampered by visits from its artificial intelligence models during company evaluations of the technology.
Read original articleSeptember 25, 2026
They wanted the silicon. They got the sand.
Read original articleSeptember 25, 2026
Comprehensive cross-platform coverage of the U.S. market close on Bloomberg Television, Bloomberg Radio, and YouTube with Romaine Bostick, Isabelle Lee, Carol Massar and Tim Stenovec. (Source: Bloomberg)
Read original articleSeptember 25, 2026
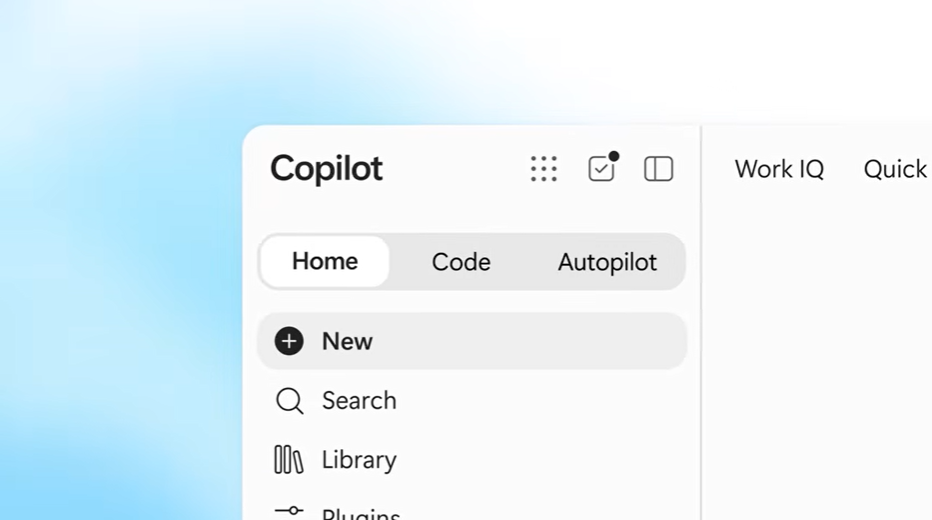
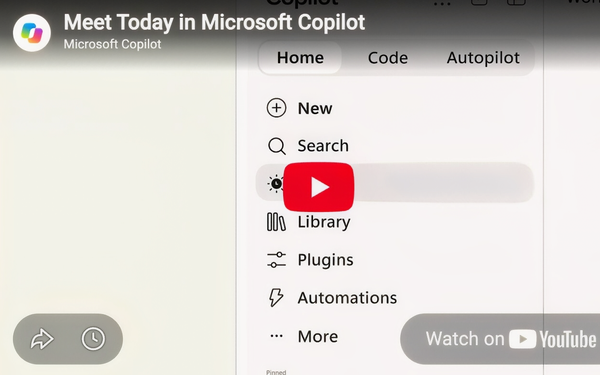
Microsoft Corp. today launched a new version of Copilot, the artificial intelligence assistant included in its Microsoft 365 productivity suite. The biggest addition to the tool is an interface section called Code. It enables nontechnical workers to create simple apps using prompts. For example, a business analyst could create a dashboard that tracks store sales. […] The post Microsoft overhauls Copilot with new coding, document editing features appeared first on SiliconANGLE.
Read original articleSeptember 25, 2026
Anthropic has committed $11.6 billion over seven years to Akamai's cloud infrastructure, a bet on CPUs that could grow to about $20 billion, and in an unusual arrangement, Akamai is giving Anthropic a potential stake of up to 5% of its stock that grows as Anthropic spends more.
Read original articleSeptember 25, 2026
With Codex, GPT-Live-1, and GPT-6 Astra, Proaction builds, operates, and sells modern fleet management faster.
Read original articleSeptember 25, 2026
A federal appeals court has upheld the Pentagon's decision to bar Anthropic from military contracts. Defense Secretary Hegseth argues the company's safety restrictions could jeopardize military operations. Anthropic says the designation has already cost it billions. The article Pentagon was right to slap Anthropic with a security supply chain risk label, federal court says appeared first on The Decoder.
Read original articleSeptember 25, 2026
The funding, which comes from Third Point, Nvidia, and others, will fuel the company's massive AI data center buildout.
Read original articleSeptember 25, 2026
OpenAI Builds New Security Gateway to Deploy GPT-6 Cyber PYMNTS.com
Read original articleSeptember 25, 2026
When AI leaders at OpenAI and Anthropic started talking about “pacing the frontier,” maybe someone should have asked: what pace? Now it’s turned into model drop week for both companies as Anthropic rolled out Opus 5.5, followed by OpenAI’s GPT-6 model updates just 90 minutes later. But the company that stole the spotlight was Meta, whose personal AI agent Muse is reportedly outpacing ChatGPT’s early numbers and is headed for smart glasses and […]
Read original articleSeptember 25, 2026
The AI spending boom is showing no signs of slowing down, but as billions pour into models, chips and data centers, investors are asking where the biggest returns will actually be. Accel Partner Matt Weigand, who focuses on late-stage technology investments including AI infrastructure, says the AI boom is the biggest technology cycle Silicon Valley has seen. He also discusses why open-source AI can grow alongside frontier labs such as Anthropic and OpenAI and why trust and safety are becoming key considerations when Accel decides which AI founders to back. He joins Tim Stenovec on "Bloomberg Tech." (Source: Bloomberg)
Read original articleSeptember 25, 2026
Bloomberg’s Tim Stenovec breaks down Anthropic's $11.6 billion contract with Akamai for AI computing power, the largest deal in Akamai's history. Plus, President Donald Trump calls his meeting with his Chinese counterpart Xi Jinping "very productive" with little to show for it. And, Microsoft steps back from the race to build a personal chatbot by instead merging the consumer and workplace versions of its Copilot AI assistant into one. (Source: Bloomberg)
Read original articleSeptember 25, 2026
Microsoft's new Surface laptops forgo Copilot+ PC branding.
Read original articleSeptember 25, 2026
Meta's Muse feels real in a way the metaverse never did Business Insider
Read original articleSeptember 25, 2026
Google Deepmind researcher Robert O'Callahan has quit, saying AI's "current rate of change is far too high." He worked on chip design tools that helped make AI cheaper and faster, a contribution he can no longer justify. Many colleagues share his concerns but rarely speak out, he says. The article Another Google Deepmind researcher quits, says building superintelligent AI soon is "inherently irresponsible" appeared first on The Decoder.
Read original articleSeptember 25, 2026
Databricks expands data platform with acquisition of Row Zero The American Bazaar
Read original articleSeptember 25, 2026
The rise of AI-native cloud provider CoreWeave Inc. is part of the greater story emerging around operationalizing AI. As enterprises shift from training to inference, neoclouds such as CoreWeave are providing cloud infrastructure tailor-made for AI. The company made waves by completing the industry’s first bring-up and validation of Nvidia Vera Rubin NVL72 on CoreWeave […] The post CoreWeave expands full-stack AI cloud push as inference demand grows appeared first on SiliconANGLE.
Read original articleSeptember 25, 2026
OpenAI wants you to use AI — but not to train its AI Computerworld
Read original articleSeptember 25, 2026
Microsoft announced what it calls its biggest Copilot update to date on Friday, with CEO Satya Nadella describing Copilot as The post Microsoft’s new Copilot agents get their own email, calendar — and a place in the org chart appeared first on The New Stack.
Read original articleSeptember 25, 2026
The AI lab had argued multiple violations of its rights, but a divided panel of judges sided with the Trump administration.
Read original articleSeptember 25, 2026
Microsoft Bundles Copilot Features to Challenge Anthropic and OpenAI in the Workplace PYMNTS.com
Read original articleSeptember 25, 2026
Microsoft is splitting its Copilot app into three sections: Home, Code, and a new agent called "Autopilot." Built on OpenClaw, the agent runs continuously in the cloud, where it can monitor Teams channels and complete tasks on its own, according to Microsoft. For Autopilot and Code, the company is also switching to usage-based billing instead of flat-rate pricing, moving further away from its AI subsidy model. The article Microsoft gives Copilot another makeover, adding an Autopilot agent and usage-based billing appeared first on The Decoder.
Read original articleSeptember 25, 2026
Microsoft Adds Agentic Capabilities, Challenges Meta 09/25/2026 MediaPost
Read original articleSeptember 25, 2026
Muse is topping the app store charts and adding users at a rapid clip, while Meta ramps up the personal AI agent's promotion across its own apps and beyond.
Read original articleSeptember 25, 2026
S&P Global's goal was to fundamentally improve how customers discover and consume...
Read original articleSeptember 25, 2026
Want to know the latest from Google Cloud? Find it here in one handy location. Check back regularly for our newest updates, announcements, resources, events, learning opportunities, and more. Tip: Not sure where to find what you’re looking for on the Google Cloud blog? Start here: Google Cloud blog 101: Full list of topics, links, and resources. aside_block <ListValue: []> Sept 21 - Sept 25 Master MCP tool authorization and agent governance with ApigeeWhile the Model Context Protocol (MCP) solves interoperability for autonomous AI agents, chained actions like CRM edits or database queries quickly expose systems to unauthorized execution. Join our technical deep dive on Thursday, October 1, 2026, at 5:00 PM CEST featuring Christophe from Google Cloud. Learn how positioning Apigee between MCP clients and enterprise backends enables fine-grained authorization (FGA), complete audit trails, and policy evaluation via emerging standards like OpenID AuthZEN.Language and accessibility note: This session will be hosted in French, but non-French speakers can follow along seamlessly by turning on Google Meet live translated captions to read in English, Spanish, German, Portuguese, or Italian.Register for the October 1 Community TechTalk Apigee Trace Viewer Tutorial: Capturing & Analyzing Proxy TracesStreamlining API proxy debugging just got easier with a new tutorial by Apigee Customer Engineer Tyler Ayers. The guide covers end-to-end instructions for capturing debug traces in both Google Cloud Apigee X (or Hybrid) and the local Apigee Emulator, extracting trace JSON data via the web UI or automated REST APIs, and analyzing execution flows, variable mutations, and latency bottlenecks using the open source Apigee Trace Viewer. Read the Apigee Trace Viewer guide today. Automate Apigee proxy testing locallyCatching errors early saves time and money. A new tutorial by Apigee customer engineer Tyler Ayers shows how to use the Apigee Local Emulator for automated testing. Learn to run tests locally, integrate them into CI/CD pipelines, and deploy on Google Cloud Run for shared sandboxes. This approach provides instant feedback and zero cloud costs, helping teams speed up deployment cycles.Read the tutorial Scale your enterprise multi-agent systems with ApigeeDeploying multi-agent architectures in production introduces critical hurdles around security, operational control, and runtime expenses. Discover how Apigee API Hub provides a central discovery surface to eliminate agent sprawl across tools, Model Context Protocol (MCP) servers, and enterprise APIs. Learn how to turn existing backend services into secure MCP tools using Agent Gateway guardrails, while applying semantic caching and intelligent model routing to keep compounding token costs predictable.Join Google Cloud in Chicago in Oct.15 for The AI Evolution. Reserve your seat for Chicago Automate Apigee proxy testing with the Apigee Local EmulatorWaiting on remote deployments to validate API proxy logic slows down release cycles and increases infrastructure overhead. Join Nigel Walters on Thursday, October 8, 2026, at 5:00 PM CEST for a Community TechTalk on shift-left testing for Apigee. Discover how to use the Apigee Local Emulator and apigee-emulator-service to run sub-second assertion suites on local machines, automate CI/CD checks in GitHub Actions, and deploy ephemeral preview sandboxes on Google Cloud Run.Register for the October 8 Community TechTalk Now in Public Preview: AI-assisted EKS-to-GKE migrations with deterministic guardrailsMigrating complex Kubernetes estates from AWS EKS to GKE is traditionally high-friction and error-prone. Now in Public Preview, GKE Agentic Migration is an open-source agent plugin that replaces ad-hoc LLM prompting with an AI-assisted migration workflow protected by deterministic guardrails.Running locally in your development harness, it indexes source IaC, maps cloud-specific primitives (such as Karpenter to Custom Compute Classes), and validates configurations offline—delivering reviewable pull requests and data-migration runbooks with zero live cluster mutations.Learn more in the announcement blog and try the plugin on GitHub. Claude Opus 5.5 is now available on Google Cloud. Built for everyday complex tasks, it delivers stronger agentic coding, research, and analysis while handling long-running work at a lower cost per token. Google Cloud continues to provide enterprise customers with broad model choice to build, deploy, and scale their AI agents securely. Try it here. Import Delta Lake tables with Dataflow Job Builder!Migrating to borderless Lakehouse just got a lot easier. You can now import Delta Lake tables stored in Cloud Storage using Dataflow Job Builder, a no-code/low-code interface for authoring Dataflow pipelines. Because Dataflow is a fully managed service, you are spared the overhead of provisioning and managing virtual machines. For step-by-step guidance, check out the documentation here. Sept 14 - Sept 18 Storage Intelligence Advisor for Google Cloud Storage is now GAGoogle Cloud Storage customers can now manage cloud storage more effectively with Storage Intelligence Advisor, delivering curated metrics, automated anomaly detection, and actionable recommendations right out of the box, with zero setup required.Advisor baselines activity across your projects and automatically detects four key anomalies: surges in operations, unexpected rises in cross-region egress, and spikes in errors. Each finding includes deep drill-down visibility into the resources driving the change, alongside prescriptive steps to remediate issues before they impact performance or cost.Learn more to get started with Storage Intelligence Advisor. Build private WebSockets from Apigee X to Cloud RunReal-time AI agents and streaming architectures often require persistent, bidirectional connections. A new implementation guide by Apigee Customer Engineer Joel Gauci demonstrates how to establish private southbound connectivity between Apigee X and Cloud Run. Using Private Service Connect (PSC) and a Regional Internal Application Load Balancer, teams can enforce API governance and security policies at the edge while keeping backend services completely isolated from the public internet.Explore the step-by-step guide and open-source code Connecting Gemini Enterprise Agent Runtime to Apigee with Private Service Connect Deploying autonomous AI agents often presents security, compliance, and cost challenges. A new reference guide details how to build an end-to-end, private architecture between Gemini Enterprise Agent Runtime and Apigee. This design helps protect internal backends and manage token quotas. Read the full community guide and deploy the code Discover what’s new and next in ApigeeAs enterprise architectures adapt to generative AI and autonomous workflows, Apigee is expanding its proven platform capabilities to support modern AI gateway use cases alongside traditional API management. Join our session on Thursday, September 24, featuring Apigee Product Manager Geir Sjurseth. Get an inside look at recent product releases, explore architectural patterns for securing models and agents, and bring your questions for the live Q&A.Register for the September 24 Apigee product update Managed Service for Apache Kafka supports clusters with public Internet access!With Managed Kafka public clusters, you can now produce and consume messages from clients outside your VPC—including your local machine, for faster, frictionless testing. Public clusters unlock use cases like IoT devices, retail storefronts, and telco network towers. Enable public access on new or existing clusters via the Google Cloud console, gcloud CLI, or REST API. Spin up your first public cluster, or reach out to kafka-hotline@google.com with questions. Stream data directly into Bigtable using Bigtable subscriptions, now in Preview!You can write Pub/Sub messages to a Bigtable table with zero ETL with Bigtable subscriptions. No pipelines, no code, delivered by the serverless, zero-ops experience you already know with Pub/Sub. Power your AI workloads, from model telemetry to real-time context engineering, without the overhead of managing complicated ETL pipelines. Built to be dependable, with native support for dead-letter topics. Try the feature today! Sept 7 - Sept 10 Why Your Voice Agent Needs Session AuditingMoving voice agents to production demands robust quality monitoring. This guide dives deep into the inner workings of the Agent Development Kit (ADK) responsible for audio session auditing. Learn how the ADK's save_live_blob feature intercepts, buffers, and stores raw audio chunks during active Gemini Live sessions. We explore building an automated post-processing pipeline to seamlessly stitch these fragments into cohesive, playable audio files. Discover how to leverage these vital audio audit trails to monitor real-world interactions, diagnose failures, and ensure enterprise-grade reliability. Read the full guide here. AlloyDB Omni Red Hat RPM Orchestrator now Generally AvailableAlloyDB Omni Red Hat RPM orchestrator is now Generally Available. The AlloyDB Omni Red Hat RPM orchestrator offers a new way to manage PostgreSQL-compatible workloads on bare metal or VM platforms, combining the high performance of AlloyDB, access to generative AI features and Gemini models to build AI agents and applications, and full automation. The orchestrator simplifies cluster provisioning and lifecycle management by allowing you to define reference architecture specifications, customizable by adjusting instance parameters, node configurations, and networking options — discover all details in full blog post. Aug 31 - Sept 4 Automate VM guest software lifecycle with VM Extension Manager, now GAGoogle Cloud VM Extension Manager is now generally available, eliminating the need for custom startup scripts to manage guest OS extensions across Compute Engine fleets. Define declarative, project-wide policies that enforce desired software states across all regions and zones. Benefit from continuous drift detection with automatic self-healing, multi-zone phased rollouts with automated rollbacks on failure, and centralized fleet health visibility integrated with Cloud Monitoring.Explore VM Extension Manager documentation Assess Apigee migrations without a target environmentPlanning a migration to Apigee X or Hybrid? You can now assess your legacy Apigee Edge SaaS or OPDK environment earlier in your planning cycle. Using the updated --skip-target-validation flag in the Apigee Migration Assessment Tool, teams can generate a full inventory and establish scope baselines before target infrastructure or IAM credentials are provisioned.Read the guide to learn more. Claude Fable 5.1 is now available on Agent Platform. It brings performance improvements over Fable 5 across reasoning, full-lifecycle coding, multi-tool workflows, and knowledge work. Anthropic also announced Enterprise Frontier Safeguards, a solution that gives customers the option to safely deploy Anthropic’s most capable models while storing their data in cloud infrastructure they control. We continue to offer enterprise customers options across frontier models to build, deploy, and scale securely on Google Cloud. Aug 24 - Aug 28 Grok 4.6 is now available in Preview on Gemini Enterprise. xAI's most capable model, built for coding, agentic tasks, and knowledge work, Grok 4.6 joins Grok 4.3 and Grok 4.20 in Model Garden and becomes the flagship of the Grok family. It supports reasoning, function calling, and structured output for multi-step agentic workflows, and accepts text and image input.Get started today Empowering autonomous agents with advanced security governanceAI agents offer incredible productivity gains, but granting them access to read emails, query databases, and trigger APIs introduces critical new security risks. In fact, 79% of tech leaders cite security and governance as their biggest challenge to scaling AI. Traditional tools are no longer enough to handle automated threats like prompt injection and dynamic permissions. Discover how forward-thinking enterprises are using secure-by-default design, agent identity governance, and human-in-the-loop controls to deploy agents with confidence.Read more Stateful processing is available in BigQuery continuous queries in PreviewStateful operations significantly expand what’s possible with BigQuery continuous queries. This feature allows users to leverage functions like JOINs, aggregations, and windowing functions directly in their streaming queries. Now you can calculate metrics over time (for example, a 30-minute average) to power your downstream applications and AI agents with much richer, real-time signals. Try out our feature here and share your feedback with bq-continuous-queries-feedback@google.com! Synthetic data generator tool is available for Managed Service for KafkaYou’ve launched your first Kafka cluster. Now what? The next thing to do is to produce some data to the cluster, but that involves modifying a client application somewhere or spinning up a virtual machine. The synthetic data generator tool, now generally available, can start sending mock data to your cluster in 3 clicks, and will get data streaming into your cluster in less than two minutes. The perfect utility for those moments you just want to test your cluster and new features. Try our quickstart today! Dataflow pipeline updates are faster & more flexibleDataflow pipeline updates can now stop-and-replace pipelines, a major addition to the existing in-place-update feature. The new parallel pipeline option accelerates the migration between the old & new pipeline, resulting in reduced disruption to your business. You can also set a timeout on drains that prevents runaway costs for your pipeliness in the event of stuck processing. This feature is generally available. Try it here! Aug 17 - Aug 21 Webinar: Agent Identity as the backbone for secure AI innovationAn AI agent with a stolen API key looks identical to a legitimate one. As autonomous agents scale across enterprise systems, static credentials and legacy IAM policies can no longer keep up with machine-speed execution. Join Shaun Liu, Product Manager at Google Cloud, on August 27 at 1 PM ET to explore Google Cloud’s vision for unifying agent, human, and nonhuman identity into a workload-centric platform using verifiable cryptographic identities (SPIFFE, ID-JAG, OAuth).Register for the webinar now Aug 10 - Aug 14 Diagnosing Apigee Hybrid Cassandra Read Latency for Peak PerformanceDiagnose real-time Cassandra read latency and resolve API key verification bottlenecks in Apigee Hybrid with this step-by-step troubleshooting guide. Learn how to deploy a debugging client and query performance tables to maintain sub-millisecond response times. Read the Apigee Hybrid Cassandra Troubleshooting Guide Keep moving with agents! The All Things Agentic Hackathon is officially live.We're challenging builders to build next-generation agents that take on the busy work and handle the heavy lifting in the background using Gemini 3.5 and Google Cloud. Compete for your share of $190,000 in prizes, cash, and Google Cloud credits! Submissions are open from August 3, 2026, to August 31, 2026.Learn more and register. Sign up for GEAR to get exclusive updates and your badge. # Accelerate PostgreSQL migrations using Gemini in Database Migration ServiceEnterprise database migrations often stall during the "last mile" of translating legacy stored procedures, triggers, and custom functions from Oracle or SQL Server. Database Migration Service (DMS) now provides AI-assisted code conversion powered by Gemini in Databases. By combining deterministic compiler rules for 1:1 syntax with Gemini contextual synthesis for complex procedural blocks, DMS converts legacy code into native PostgreSQL and AlloyDB with full schema awareness and side-by-side validation.Read the full blog post to learn how to streamline your database code conversion. Compute Flex CUDs now available for G2 and G4 GPU VMsCompute Flexible Committed Use Discounts (Flex CUDs) are now available for G2 (NVIDIA L4) and G4 (NVIDIA RTX Pro 6000) VMs. You can now lock in predictable savings while retaining the flexibility to adapt across VM families, migrate between regions, and combine general-purpose compute, GKE, Cloud Run, and G2 & G4 GPU VMs under a single spend commitment. Flex CUDs for G-series VMs let you lock in savings today while preserving the agility to upgrade to latest hardware without disruption!Explore VM instance pricing or learn more about Flex CUDs. Rapid Bucket accelerates the training and checkpoint performance in PyTorch Ecosystem via GCSFSWith the release of GCSFS 2026.8.0, organisations can now unlock maximum ROI from their AI/ML infrastructure by eliminating data starvation on GPUs in PyTorch ecosystem when they are using Frameworks like Dask, Pandas, PyTorch , PyTorch Lightning, Hugging Face Datasets, Ray dataetc. By making adaptive concurrent prefetching the default, GCSFS dynamically predicts and background-fetches sequential read patterns—boosting single-file throughput by 5x, and scaling up to 21 GiB/s , saturating the NIC when paired with Rapid Bucket. Saturating the NIC translates to significantly improved accelerator goodput and reduced training wait times with zero integration friction. Training and checkpoint restore workflows benefit from intelligent memory management that automatically drains the buffer during random reads to completely avoid bandwidth or memory penalties. Aug 3 - Aug 7 Navigate data sovereignty and AI innovation with hybrid cloudFor enterprises facing strict compliance rules, keeping sensitive data on-premises often means missing out on cutting-edge AI. Data from the 2026 State of AI Infrastructure report reveals that 52% of IT leaders are adopting hybrid cloud strategies to bridge this gap. Our latest blog post explores how Google Distributed Cloud (GDC) helps organizations deploy connected or air-gapped models to run advanced AI entirely within secure environments—mitigating geopolitical risks without sacrificing innovation. Read more. SAP and Google Cloud Launch BDC Connect for BigQueryFor years, enterprises have struggled with the cost, risk, and complexity of moving mission-critical SAP data into advanced analytics platforms. The general availability of SAP Business Data Cloud (BDC) Connect for BigQuery marks a turning point. By introducing revolutionary zero-copy, bi-directional data sharing, this new capability seamlessly bridges SAP systems with Google Cloud's powerful data and AI ecosystem. Instead of wrestling with manual data duplication and lost business context, organizations can now eliminate silos, dramatically lower their analytics costs, and rapidly deploy trustworthy, agentic AI solutions grounded in real-time operational reality. Read the full announcement to learn how to transform your data strategy. Google Cloud Cortex Framework version 7 is now generally available!This release helps you modernize your data architecture for AI agent readiness, enabling you to quickly deploy, customize, and extend robust data products while simplifying orchestration and reducing infrastructure overhead. It provides data product accelerators for SAP-sourced data to build trusted, high-quality data products ready for advanced analytics and agentic use cases. The Framework integrates with Google Cloud products including BigQuery, Dataform, Knowledge Catalog, and Gemini Enterprise Agent Platform. Learn more in our announcement blog, technical documentation, or try a demo deployment today. From API Management to AI Gateway with ApigeeMassive LLM adoption unlocked automation but exposed critical vulnerabilities, from unpredictable token costs to security risks like prompt injection. Without central management, organizations face accelerated technical debt. Learn how to transform Apigee into an enterprise AI Gateway to centralize governance. This architectural roadmap details how to utilize semantic cache to optimize token costs, implement prompt protection policies for security, and productize tools using the emerging MCP standard.Read the full architectural roadmap on the Apigee Community Hub Centrally govern enterprise AI traffic with Apigee AI GatewayManage, track, and secure model communication across your entire infrastructure from a single pane of glass. In a new video walkthrough, Principal Architect Tyler Ayers demonstrates how Apigee AI Gateway simplifies agentic governance. Learn how to transparently proxy model traffic, log real-time token counts, and apply runtime security quotas without impacting your developer workflow.Watch the Apigee AI Gateway demo Maximize Provisioned Throughput UtilizationSudden traffic micro-spikes can exceed per-second quotas, triggering 429 errors or forcing overflow into shared resource pools. A new architectural guide demonstrates how to build a serverless "shock absorber" using Cloud Run and Google Cloud Tasks. By decoupling request ingestion from execution, this queue-based pattern flattens volatile traffic bursts and smoothly drips requests to Gemini at your exact quota rate, maximizing Provisioned Throughput utilization while eliminating job failures during peak usage. Read the step-by-step setup guide. Eliminate security blindspots in agentic tool agentic tool calls via the Model Context Protocol (MCP) can introduce critical security risks to your enterprise architecture. Join our technical deep dive on Thursday, August 13, to discover how to position Apigee as a centralized security gateway. Featuring the new ParsePayload policy and payload operations groups in API Products, this session demonstrates how to enforce granular tool filtering, manage execution quotas, and scale secure agent ecosystems without impeding developer velocity. Register for the August 13 Community TechTalk Jul 27 - Jul 31 Data Cloud and Apigee CDMX: The AI Agent Evolution | August 12, 2026Enterprise AI demands evolution beyond basic conversational assistants. To generate real value, AI models must connect with the organization's core systems and live data sources. Join us this August 12 at Google CDMX for the exclusive event AI Evolution: Powering Tomorrow's Enterprise. Learn how to design an agile and secure ecosystem by unifying the power of Gemini, Apigee, and data agent technologies through practical demonstrations led by Google Cloud engineers.Secure your spot for the in-person session in Mexico City Register now! Vast Edge, built on GCP, launches the first live recovery interface for cloud backups, enabling IT teams to inspect backup contents in real time. This transforms backups from a blind, log-based process into an interactive platform where teams can instantly search, preview, and validate the exact data available for restore.This platform protects Google Workspace, NetSuite, Salesforce, Workday and many SaaS environments, providing complete visibility and enterprise-grade oversight.Visit Vast Edge Backup & Disaster Recovery and get a free trial of their backup solutions on the GCP Marketplace for Google Workspace Backup, NetSuite Backup, Salesforce Backup, and Workday Backup. Jul 20 - Jul 24 Claude Opus 5, Anthropic’s latest model, is now available on Agent Platform. It brings performance improvements over Opus 4.8 across coding, long-running agents, and knowledge work.The model is Zero Data Retention (ZDR) compatible. For safety, high-risk workflows — such as penetration testing or exploit generation — it will notify you and fall back to Opus 4.8.We’re excited to continue to offer enterprise customers options across frontier models to build, deploy, and scale AI securely. Try it here. Apigee Northam Roadshow 2026 | The AI Agent Evolution: Powering Tomorrow's EnterpriseAI is evolving. As your organization deploys autonomous agents, the integration between APIs and models becomes critical. Join Google Cloud specialists for an exclusive day of deep-dive sessions and live demos. Discover how the unified power of Apigee and the Google Cloud Agent Platform allows you to build, govern, and scale high-performance AI agents with complete control. Call to Action: Register for Sunnyvale | Register for NYC | Register for Chicago Deploy an Apigee Proxy for MCP Registry Discovery Learn how to deploy an Apigee X proxy to format Apigee API Hub data into the Model Context Protocol (MCP) Registry format. This tutorial by Tyler Ayers guides developers through cloning the sample repository, deploying using the Apigee Feature Templater (aft), and testing the endpoint to make API data easily discoverable by coding agents. Read the full community tutorial to get started. Simplify AI Infrastructure: Getting Started with Apigee AI GatewayManaging a complex AI landscape with multiple backend environments can present significant operational and governance challenges. A new tutorial walks you through how to build a unified API proxy using Apigee AI Gateway. By establishing a single, secure entry point for all model traffic, teams gain access to real-time analytics, comprehensive tracing, and financial operations auditing—completely seamlessly, and with absolutely no modifications required to client environments or user configurations. Read the step-by-step setup guide Your AI agents are ready. Is your data?The biggest bottleneck to scaling AI isn't the models—it's giving them access to business context. As enterprises move to proactive systems of action, legacy infrastructure often buckles under the nonlinear speed of AI agents. Google Cloud’s new Agentic Data Cloud, built on AI-native infrastructure, solves this by unifying data, AI models, and operational databases. Discover how a borderless Lakehouse and active Knowledge Catalog can empower your AI agents with trusted, real-time context without unnecessary engineering overhead. Read more. Secure and govern your AI at Apigee AI Horizon in LondonMoving AI from basic prompts to complex agentic workflows requires trust and control. Join us on Tuesday, 1st September 2026 at Google London for our 5th edition of Apigee AI Horizon. Discover how Google Cloud product leaders and architects are using Apigee and Model Armor to secure LLM APIs, implement policy controls, and manage token consumption. Do not miss this one—register soon!Secure your spot for AI Horizon London Jul 13 - Jul 17 Resource-Based CUD Sharing is Now Enabled by DefaultStarting June 16, 2026, the default setting for Google Cloud Resource-based Committed Use Discount (CUD) sharing will change from disabled to enabled for new billing accounts and eligible existing accounts without active CUDs. This update automatically maximizes your savings by pooling underutilized discounts across your resources.You retain full control and can adjust your CUD sharing preferences at any time by changing your CUD scope configuration. For instructions, see Enable CUD sharing or Disable CUD sharing. Webinar for India: Google Cloud for EdTech: Optimizing Traffic and Token Governance at ScaleAPI traffic surges and AI model integration are reshaping the EdTech landscape. Join Satyam Maloo for the webinar Google Cloud for EdTech: Optimizing Traffic and Token Governance at Scale on July 23, 2026. Learn to implement advanced rate limiting, gain granular token visibility, and leverage real-time analytics to govern your platform effectively. Whether you’re scaling for peak academic seasons or integrating complex AI workflows, this session provides the infrastructure blueprint you need.Register Now Scaling AI Agents: Treat prompts like software artifactsAs AI agents move into production, monolithic system prompts often result in configuration drift, merge conflicts, and silent runtime failures. The solution is adopting a Prompts-as-Code architecture. By breaking prompts into modular skill files and using a build-time transpiler, engineering teams can introduce dependency resolution, static validation, and CI/CD rigor to their agent's control plane. Stop manually editing massive text files and start building deterministic, reliable agent infrastructure.Read more here. Jul 6 - Jul 10 Webinar: Introducing Google Cloud NGFW Enterprise advanced malware protection - powered by Palo Alto NetworksDiscover the new Cloud NGFW advanced malware sandbox, arriving in preview later this year. Powered by Palo Alto Networks Advanced Wildfire, it leverages data from 70,000+ customers to help defeat advanced malware. Join us on July 16 at 11 AM EDT to learn how to build a resilient, zero-trust cloud infrastructure that protects your apps and data, wherever they reside.Register for the webinar now Safely run AI-generated code in Cloud Run sandboxesCloud Run sandboxes, now in public preview, are lightweight, isolated execution boundaries that you can spawn near-instantly within your existing Cloud Run service instances.Whether you need to let an LLM run a dynamically generated Python script to calculate business margins or spin up a headless browser to perform web research, Cloud Run sandboxes give you a secure, isolated sandbox to run these tasks without leaving your serverless environment.Read the blog to learn more and get started today. Australia API Horizon: Scaling Enterprise Governed AI AgentsThe transition from AI chatbots to autonomous agents is the most critical integration point for your business. Join Google Cloud at our upcoming events to explore exclusive deep-dive sessions on architecting for the agentic era.Discover how to use Apigee as an intelligent AI Gateway to govern, secure, and scale high-performance architectures. You will learn to seamlessly build AI tools from your existing APIs and maintain control over your entire ecosystem.Join us in your preferred city: Sydney: July 28, 2026, at Google Sydney, One Darling Island. Canberra: July 29, 2026, at Hotel Realm. Melbourne: August 4, 2026, at Google Melbourne. Build highly available, multi-region services on Cloud RunMaintaining uptime for business-critical applications just got a lot easier on Cloud Run. Service health, now Generally Available, automates cross-region failover by leveraging readiness probes for instance-level health checks with a simple, two-click setup. You can configure service health with global external Application Load Balancers for public-facing applications or cross-region internal Application Load Balancers for private networking traffic.Learn how to configure service health for Cloud Run. Report: 83% of organizations need infrastructure upgrades for agentic AIThe shift from conversational bots to autonomous agents is breaking legacy systems. Our new State of AI Infrastructure report details how engineering leaders are adapting to these massive new workloads. To eliminate inference bottlenecks, control hidden scaling costs, and manage agent sprawl, the industry is rapidly moving toward fluid compute, centralized governance, and unified, co-designed architectures.Explore our key infrastructure insights Stop tinkering, start scaling: the industrialized AI PlaybookDid you know that only 5% of custom AI investments actually return measurable business value? The problem isn’t the technology—it’s how organizations are wired to run it.In this compelling read, Google Cloud Consulting breaks down the operational blueprint that bridges the stark gap between "cool tech experiments" and real, P&L-impacting enterprise ROI.Read the full article on Medium AI Agent Clinic: Slashing App Latency by 80%Prototyping an AI agent is easy, but scaling for live traffic presents unique challenges. In the latest AI Agent Clinic, our technical experts partner with a developer to optimize PlaybackIQ, a live football analysis agent. This session demonstrates how to use OpenTelemetry to trace bottlenecks in the Gemini Enterprise Agent Platform and deploy to Cloud Run for high-concurrency scaling, achieving an 80% reduction in response time. Learn production-grade debugging strategies to optimize your own LLM applications.Watch the 60-minute teardown Jun 29 - Jul 3 Claude Sonnet 5, Anthropic’s latest model, is now available on Agent Platform. This addition serves as a drop-in replacement for Sonnet 4.6, giving organizations expanded choice for task completion across enterprise workflows. It features enhanced reasoning, cleaner code generation, and computer use capabilities for desktop and browser workflows.By continuing to rapidly bring frontier models to our platform, Google Cloud offers an uncompromised choice of the industry's best technology to build, test, and scale enterprise-grade AI.Get started today. Automate your AI governance with Apigee and YAMLManual API gateway configurations can quickly slow down your AI engineering velocity. Join the Apigee community on Thursday, July 16, to discover an automated, declarative blueprint for model garden management. Learn how a simple, repeatable YAML pattern lets your AI practitioners instantly spin up secure, policy-backed enterprise configurations without friction. Bring your questions and connect during our live Q&A session. Register for the July 16 Community TechTalk Build next-generation AI portals for autonomous agentsStandard developer portals were designed for human developers to subscribe to static APIs. Today, autonomous agents, LLM toolkits, and dynamic runtimes demand a central nervous system for governance. Join our technical deep dive on Thursday, July 23, to explore Apigee's new AI Portals solution. You will see exactly how to deploy full-service, MCP powered hubs to safely manage enterprise self-service for models, tools, and agents. Register for the July 23 Community TechTalk Protect your infrastructure from advanced cyberattacks at the API layer (Presented in Portuguese)In an era of increasingly sophisticated threats, relying solely on traditional firewalls leaves critical data gaps. Join our technical community TechTalk on Thursday, July 30—conducted in Portuguese—to learn how to proactively mitigate risks directly at the gateway layer. This session demonstrates how to configure and govern essential Apigee security policies to build a robust line of defense, ensuring maximum availability and complete integrity for your enterprise microservices. Register for the July 30 Portuguese Community TechTalk Jun 22 - Jun 26 Accelerate TPU model loading while saving RAM on GKE.Large model cold starts often stall scaling and leave high-value TPUs idle. The open-source Run:ai Model Streamer now natively supports TPUs with Google Cloud Storage in TPU vLLM 0.18.0. This integration accelerates inference pipelines on GKE by streaming tensors directly into CPU memory, bypassing local disk bottlenecks and the "double-buffering" trap. In benchmarks, loading a 480B parameter model was over 2x faster while cutting peak host memory usage by half. Read the full guide and get started today. Stop Training Blind: Scaling AI with the New OpenTelemetry-Based TPU AI Telemetry Collector AgentGoogle Cloud’s new AI Telemetry Collector agent standardizes TPU monitoring using OpenTelemetry. It optimizes enterprise ML workloads by identifying silent failures and providing zero-cost operational metrics without draining host CPU cycles. The agent seamlessly routes telemetry to Google Cloud Monitoring or Prometheus and custom Grafana setups. Pre-installed on Google-optimized Ubuntu images or available via Docker, it tracks memory, network latency, and core utilization to maximize multi-node training efficiency.You can read more of this capability by clicking this link. Jun 15 - Jun 19 Join us for a deep dive into agentic AI control with AppyThingsYour integrations aren’t failing—they are evolving. When users interact with AI agents, they no longer arrive directly at your site, resulting in experiences stripped of your context, expertise, and intended experience. Join us on Thursday, June 25, for a community tech talk in partnership with AppyThings to learn how to solve this new gateway challenge. We will explore how MTN laid an integration foundation with the Model Context Protocol (MCP) to deliver accurate, consistent experiences. Our technical experts will demonstrate how to leverage Apigee as a centralized tools management solution to govern agent access. Register for the session Optimize Spot VM Deployments with Capacity Advisor for Spot, Now in Public PreviewGoogle Compute Engine has launched Capacity Advisor for Spot to Public Preview, now open to all customers. This tool turns Spot capacity discovery into a data-driven process by providing real-time deployment recommendations to maximize obtainability and minimize preemption risks. Query the Capacity Advisor API for obtainability and minimum estimated uptimes, or use the new Console UI featuring a global availability map, spot price lookups, and historical preemption rate trends to visually find the most cost-efficient compute capacity.Get started today to start optimizing your Spot VM deployments! Build a multi-tenant agentic AI systemWhen scaling generative AI across different business units, your teams need specialized AI agents with unique operational rules and tools. Our new reference architecture helps you build a centralized multi-tenant platform to prevent fragmented silos, eliminate data exposure risks, and maintain unified compliance. Read the guide to design and deploy a multi-tenant agentic AI system in Google Cloud. How to Configure Gemini Enterprise to Connect to a Custom MCP ServerThe Gemini Enterprise MCP Connector was a big announcement at Google Cloud Next because it introduces the ability to connect Gemini Enterprise to MCP servers. This blog post provides a step-by-step guide on how to configure your first Custom MCP Server connector using the Google Maps Ground Lite MCP server as an example. Once you understand this flow, you can configure multiple MCP servers with Gemini Enterprise to bring all the context you need. Jun 8 - Jun 12 Simplify Multi-Cloud Planning with Cloud Location Finder, now Generally Available Cloud Location Finder provides up-to-date data on public regions, zones, and Google Distributed Cloud Connected locations across Google Cloud, AWS, Azure, and OCI. You can now programmatically discover locations based on provider, proximity, territory, and carbon footprint to optimize your global infrastructure strategy for performance, compliance, and sustainability. Get started for free today Jun 1 - Jun 5 Modeling the physical world with BigQuery GraphManaging complex supply chains requires more than just spreadsheets; it requires a digital replica of the physical world. In this post, Guru Rangavittal and Candice Chen explore how BigQuery Graph enables organizations to build a digital twin by turning physical assets into an interconnected map of nodes and edges. By moving beyond traditional relational databases, businesses gain real-time clarity into operations—from executing surgical ingredient recalls to analyzing weather-driven logistics risks. Discover how BigQuery Graph transforms reactive firefighting into proactive, precision modeling, allowing you to see critical connections in seconds and future-proof your supply chain. Apigee for AI: Govern LLMs and MCP Servers (Presented in Spanish)Learn how to securely transition your AI initiatives from experimental prototypes to enterprise-ready deployments. Join Luis Cuellar on June 18 for a technical deep dive (presented in Spanish) exploring Apigee’s latest AI gateway capabilities. Discover how to centralize governance over Model Context Protocol (MCP) servers, protect Large Language Models (LLMs) with robust API gateway security policies, and manage token-based quotas.Register for the June 18 Spanish Community TechTalk May 25 - May 29 Anthropic’s Claude Opus 4.8 is now available on Gemini Enterprise Agent Platform. As we continue to expand our platform's model offerings, this addition gives organizations more options for handling complex, multi-stage enterprise workflows. Claude Opus 4.8 brings strong capabilities in agentic coding, allowing developers to manage extensive refactors and tracking dependencies over extended sessions. API Horizon Munich July 6, 2026: Orchestrating the Next Era of AI and APIs Master the orchestration of next-gen AI and digital ecosystems. Join Google Cloud experts and DACH tech leaders on July 6 for an exclusive look at the Apigee roadmap, Agent Management, and Model Context Protocol (MCP). Gain real-world insights and connect with the regional integration community.Register now Securing AI Agents: The Extended Agent Gateway PatternLearn how to prevent autonomous AI agents from invoking unauthorized APIs. Join Apigee Specialist Joel Gauci on June 4 for a technical deep dive into the Extended Agent Gateway pattern. This session covers enforcing Fine-Grained Authorization (FGA), implementing secure token exchange, and establishing Model Context Protocol (MCP) governance at the API gateway layer to protect enterprise backend services.Register for the June 4 Community TechTalk API-to-Agent Security: Exposing REST APIs to Gemini Enterprise via MCPConnect Gemini Enterprise agents to core data without creating security hazards. Join Google Cloud Specialist Nigel Walters on June 11 to learn how to instantly transform legacy REST APIs into secure Model Context Protocol (MCP) servers. We’ll cover how to safely register tools with Gemini while enforcing gateway-level guardrails like rate limiting and access control policies.Register for the June 11 Community TechTalk May 18 - May 22 Chinese Webinar | June 4: AI Command and ControlAs AI agents move from experimental pilots to core enterprise functions, governance has become a critical next step. Join Google Cloud on June 4th at 10:00 AM (Beijing Time) to learn how to build a secure AI management layer architecture. We'll explore how to develop governed MCP (Model Context Protocol) endpoints, manage tool access to enterprise data, and leverage robust audit logs to operationalize AI. This session also includes a practical demonstration of these governance frameworks on Google Cloud.Register here GCP Announces New Features to Benchmark and Optimize LLMs for On-Device Use CasesDeploying fine-tuned LLMs from GCP to edge devices like smartphones is complex due to fragmented hardware. Google AI Edge Portal bridges this gap, giving GCP developers the ability to test AI performance on 120+ Android devices, representing the full diversity of high, medium, and low tier smartphones on the market today. This week at I/O, we announced brand new capabilities to benchmark and debug LLM performance across these devices. Sign-up to utilize these new features in private preview today. May 11 - May 15 Build Your AI & MCP Control Tower for Universal GovernanceMaster the future of agentic security with Apigee. Join our Community TechTalk on May 21 to discover how Apigee serves as a central "Control Tower" for the Model Context Protocol (MCP). We will explore how new JSON-RPC tool authorization enables fine-grained access policies across your organization, ensuring secure and scalable AI deployments. Whether managing internal tools or external users, learn to govern your agentic ecosystem with absolute precision. This session is designed for global coverage across EMEA and AMER regions.Register for the May 21 Community TechTalk Apr 27 - May 1 Master Your Launch: The Apigee Production Go-Live ChecklistEnsure a secure launch with the Apigee production guide. Join Nicola Cardace on May 28 to explore security guardrails, including IAM roles, mTLS configurations, and encrypted KVM migrations. Scheduled at 11 AM EDT / 5 PM CEST to support EMEA and AMER teams, this TechTalk provides the technical roadmap you need to flip the switch with absolute confidence.Register for the May 28 Community TechTalk Transforming APIs into Governed Agentic Tools on the Google Cloud Agentic PlatformTurn your APIs into secure, governed agentic tools on the Google Cloud Agentic Platform. Join Specialist Christophe Lalevée on May 7 for a technical deep dive into AI productization. Scheduled at 5 PM CEST / 11 AM EDT to maximize coverage for developers across EMEA and AMER, this session explores the integration and governance frameworks required to scale enterprise-ready AI with confidence. Register for the May 7 Community TechTalk Fractional G4 VMs are Generaly Available, providing a highly efficient and cost-effective entry point for AI and graphics workloads. These new configurations, using NVIDIA virtual GPU (vGPU) technology, allow you to leverage the power of the NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs in flexible, smaller increments, so you can right-size your infrastructure to match the specific demands of your applications. By providing more granular access to advanced hardware, fractional G4 VMs let you optimize resource allocation and reduce overhead without sacrificing performance. You can now select from additional GPU slice sizes for your specific needs: 1/2 GPU: Ideal for more intensive tasks such as LLM inference, robotics sensor simulation, and high-fidelity 3D rendering. 1/4 GPU: Optimized for mainstream workloads, including mid-range creative design, video transcoding, and real-time data visualization. 1/8 GPU: Great for lightweight applications such as remote desktops, productivity tools, and entry-level streaming services. Transitioning AI from a sandbox prototype to an enterprise-grade system is a major hurdle. A monolithic script won't suffice for widespread deployment. To achieve true scale and reliability with Gemini, organizations must adopt service-oriented micro-agent architectures, establish Zero-Trust security, and implement rigorous EvalOps. Master the "Agentic Maturity Ladder" to ensure your AI & Agentic solutions are robust, secure, and ready for the real world. Watch the deep dive and read the developer blog to learn more. ML Development in VS Code with Google Cloud Power: Workbench Extension Now AvailableData scientists and developers can now combine the local productivity of VS Code with the scalable infrastructure of Google Cloud. The new Google Cloud Workbench Notebooks extension allows you to connect to and run notebooks on managed cloud environments directly within your local IDE. This integration streamlines the ML lifecycle by eliminating context switching and providing high-performance compute for complex workloads in a familiar interface. As part of our commitment to the developer ecosystem, the extension is fully open-sourced to support community-driven innovation. Install from Marketplace: GoogleCloudTools.workbench-notebooks Contribute on GitHub: colab-enterprise-vscode Apr 20 - Apr 24 Announcing the 2026 Google Cloud Partners of the YearGoogle Cloud is honored to celebrate the winners of the 2026 Partner of the Year awards! These awards recognize an exceptional group of partners across AI, Security, Infrastructure, and more, who have demonstrated a commitment to customer success. From global system integrators to specialized startups, these winners are leveraging the power of Google Cloud to solve complex challenges and drive digital transformation worldwide. Join us in congratulating these organizations for their innovation, collaboration, and impactful results over the past year.See the 2026 Partner Award winners Apr 13 - Apr 17 We're excited to announce the Public Preview of Datastream’s metadata integration with Knowledge Catalog. This is the first step in our vision to provide a centralized, "single pane of glass" for all Datastream assets. The enhancement automatically synchronizes Streams, Connection Profiles, and Private Connections, eliminating data silos. It enhances discoverability, allowing you to search for Datastream assets using the same interface as BigQuery tables. Centralized governance is also provided, making your real-time data estate more transparent and easier to manage. Upgrading Apigee OPDK to 4.53 with OS your infrastructure using Google’s official, sequential upgrade path. Our Technical expert, Rakesh Talanki outlines how to upgrade Apigee OPDK to v4.53 while migrating to a supported OS (RHEL 8.x/9.x). This guide covers the "build-out" methodology, including multi-data center syncing, to ensure a stable, zero-downtime transitionRead the guide Cloud Run Worker Pools and CREMA: Powering Serverless AI at ScaleGoogle Cloud has announced the General Availability of Cloud Run worker pools, a new resource type designed specifically for pull-based, non-HTTP workloads. Unlike traditional Cloud Run services that scale based on request traffic, worker pools provide an "always-on" environment for background tasks like processing message queues or running large-scale AI inference. To support this, Google Cloud also open-sourced the Cloud Run External Metrics Autoscaler (CREMA). Built on KEDA, CREMA enables queue-aware autoscaling for worker pools, allowing them to dynamically scale based on external signals like Pub/Sub backlog or Kafka lag. Apigee Model Context Protocol (MCP) now Generally AvailableExpose enterprise APIs as MCP tools for agentic AI applications with the General Availability of MCP in Apigee. This update allows developers to transform APIs into AI-ready tools using OpenAPI Specifications, removing the need for local MCP servers or additional infrastructure. With managed endpoints and semantic search in API hub, you can now provide AI agents with secure, governed access to enterprise data at scale.Explore the MCP overview Apr 6 - Apr 10 Community TechTalk: Powering Retail Agents with ADK, UCP & Apigee XMove beyond basic chatbots to secure, transactional AI experiences. Join our Community TechTalk on April 16 to learn how Apigee X and Gemini build a "Trust Layer" for AI shopping assistants using UCP standards. We’ll demonstrate how to block prompt injections with Model Armor and implement cost governance via token limits to secure the path from discovery to purchase.Register for the TechTalk Implement multimodal capabilities in your AI agentsExplore three new reference architectures for building sophisticated multi-agent AI systems that can process and analyze multimodal data. To analyze disparate multimodal data and produce a high-confidence classification, see Classify multimodal data. To create a fluid conversational AI that processes audio and video streams in real time, see Enable live bidirectional multimodal streaming. To consolidate fragmented multimodal data into a searchable knowledge graph, see Multimodal GraphRAG resource orchestration. Automate SecOps workflows with an agentic AI systemTo accelerate incident response and reduce manual toil for your security team, you need a system that can automate remediation playbooks. Our new reference architecture helps you build an AI agent that orchestrates complex triage and investigation workflows across disparate security tools, such as SIEM, CSPM, and EDR, from a single interface. See the full guide to orchestrate security operations workflows. Mar 30 - Apr 3 ASEAN Webinar | April 30: Mastering Agentic Governance at Scale with GCPAs AI agents move from experimental pilots to core enterprise functions, governance is the critical next step. Join Google Cloud experts Shilpi Puri & Wely Lau for a webinar on April 30th at 11:00 AM SGT to learn how to architect a secure AI Management layer. We’ll explore developing governed MCP endpoints, managing tool access to enterprise data, and operationalizing AI with robust audit logs. The session includes a live demo of these frameworks in action on Google Cloud.RSVP here. Mar 23 - Mar 27 Turn your API sprawl into an agent-ready catalogAs organizations scale, APIs often become scattered across multiple gateways, creating "blind spots" that hinder AI adoption. To solve this, we’ve introduced two new capabilities for Apigee API hub: a new integration with API Gateway to automatically centralize API metadata into a single control plane, and a specification boost add-on (now in public preview). This add-on uses AI to enhance your API documentation with the precise examples and error codes that AI agents need to function reliably.Read the full blog post to get started. Webinar | April 16: AI Command & ControlAs AI agents move from experimental pilots to core enterprise functions, governance is the critical next step. Join Google Cloud expert Satyam Maloo for a webinar on April 16th at 11:00 AM IST to learn how to architect a secure AI Management layer. We’ll explore developing governed MCP endpoints, managing tool access to enterprise data, and operationalizing AI with robust audit logs. The session includes a live demo of these frameworks in action on Google Cloud.RSVP here. Modernizing and Decoupling Event Ingestion with ApigeeIn modern cloud-native architectures, decoupling producers from consumers is critical for building resilient systems. While Google Cloud Pub/Sub provides a scalable backbone, exposing it directly to external clients can introduce security and management overhead. This new guide explores how to leverage Apigee as an intelligent HTTP ingestion point. Learn how to handle security, mediation, and traffic control before messages reach your internal bus using the PublishMessage policy or Pub/Sub API.Read the full guide. Mar 16 - Mar 20 Gemini-powered Assistant in BigQuery Studio Gets Context-Aware UpgradesThe Gemini-powered assistant in BigQuery Studio has been transformed into a fully context-aware analytics partner, supporting your entire data lifecycle. The new capabilities include intelligent resource discovery, which uses Dataplex Universal Catalog search to find resources across projects and deep dive into metadata using natural language. You can now automate tasks, such as scheduling production-grade queries directly through the chat interface, and instantly troubleshoot long-running or failed jobs with root cause analysis and cost control auditing.Explore the full range of what the assistant can do. Mar 9 - Mar 13 Want to use Gemini to develop code and don't know where to start?This article includes a couple of examples of developing code with Gemini prompts; it identified changes that were needed to be made to get the code working. The article also refers to other examples that are available on github. Mar 2 - Mar 6 Introducing Gemini 3.1 Flash-Lite, our fastest and most cost-efficient Gemini 3 series model. Built for high-volume developer workloads at scale, 3.1 Flash-Lite delivers high quality for its price and model tier. Gemini 3.1 Flash-Lite can tackle tasks at scale, like high-volume translation and content moderation, where cost is a priority. And it can also handle more complex workloads where more in-depth reasoning is needed, like generating user interfaces and dashboards, creating simulations or following instructions. Starting today, 3.1 Flash-Lite is rolling out in preview to enterprises via Vertex AI and developers via the Gemini API in Google AI Studio. TechTalk: Implementing Device Authorization Grant (RFC 8628) for ApigeeLearn how to authorize "headless" devices like Smart TVs or AI agents that lack keyboards and browsers. Join our Community TechTalk on March 19 (5PM CET / 12PM EDT) to go under the hood of Apigee X/Hybrid. We’ll cover the real-world mechanics of state management, polling, and human-in-the-loop security patterns for devices and autonomous agents. Register for the TechTalk Feb 23 - Feb 27 Pro-level image generation gets faster and more accessible with Nano Banana 2Nano Banana 2 is our state-of-the-art image generation and editing model. It delivers Pro-level image generation and editing at the speed you expect from Flash — making the quality, reasoning, and world knowledge you loved about Nano Banana Pro more accessible. Learn more about the model here. The Intelligent Path to Compliance: Transforming Regulatory QC with Google CloudReducing "Refuse to File" (RTF) risks and submission cycle times is critical for life sciences leaders. Google Cloud’s Regulatory Submission Semantic QC Auditor leverages Gemini and RAG architecture to transform Quality Control from a manual burden into an active, intelligent workflow. By automating semantic cross-referencing, narrative coherence checks, and dynamic guidance-based auditing, this solution ensures rigorous accuracy and auditability. Operating within a secure GxP-ready environment, it empowers teams to detect subtle inconsistencies and generate remediation plans without sacrificing data privacy. Learn more. Stop typing, start interacting! The Gemini Live Agent Challenge is here. Build immersive agents that can help you see, hear, and speak using Gemini and Google Cloud. Compete for your share of $80,000+ in prizes and a trip to Google Cloud Next '26!Submissions are open from February 16, 2026 to March 16, 2026. Learn more and register at .devpost.com Feb 9 - Feb 13 Introducing Gemini 3.1 Pro on Google Cloud. 3.1 Pro is a noticeably smarter, more capable baseline for complex problem-solving. We’re shipping 3.1 Pro at scale, building upon our goal to help you transform your business for the agentic future. Learn more about the model’s capabilities here. Gemini 3.1 Pro is available starting today in preview in Vertex AI and Gemini Enterprise. Developers can access the model in preview via the Gemini API in Google AI Studio, Android Studio, Google Antigravity, and Gemini CLI. Automate Storage Compatibility with GKE Dynamic Default Storage ClassesManaging storage across mixed-generation VM clusters in GKE just got easier. With the new Dynamic Default Storage Class, Google Kubernetes Engine automatically selects between Persistent Disk (PD) and Hyperdisk based on a node's specific hardware compatibility. This abstraction eliminates the need for complex scheduling rules and manual pairing, ensuring your volumes "just work" regardless of the underlying infrastructure. By defining both variants in a single class, you reduce operational overhead while maintaining peak performance and cost-efficiency across your entire cluster.Explore automated disk type selection Community TechTalk: AI-Powered Apigee Development with strofa.ioJoin the Apigee community on February 26 for a deep dive into strofa.io. Guest speaker Denis Kalitviansky will demonstrate how this new AI-powered tool automates and orchestrates Apigee development, from local emulators to large-scale hybrid environments. Discover how to scale your API management and streamline team collaboration using the latest in AI-driven automation. Register now to reserve your spot. Jan 26 - Jan 30 Simplify API Governance with Native OpenAPI v3 SupportEliminate integration debt and accelerate deployment velocity with the General Availability of OpenAPI v3 (OASv3) support for API Gateway and Cloud Endpoints. You no longer need to downgrade modern specifications to OASv2. Instead, you can now define API contracts and enforce critical policies—including telemetry, quotas, and security—using native Google-specific extensions directly within your OASv3 files. This update ensures your APIs are secure by design while remaining fully compatible with the modern developer ecosystem and Google Cloud’s AI services.Get started with OpenAPI v3 on API Gateway and Cloud Endpoints. Accelerate API Testing with the New Open Source API TesterStart validating your APIs with API Tester, a simple, YAML-based Test Driven Development (TDD) framework. Designed for the Apigee community, this tool allows you to write human-readable tests, run them instantly via a web client or CLI, and perform deep unit testing on Apigee proxies. With native support for JSONPath assertions and Apigee shared flows, you can verify everything from payload data to internal variables like proxy.basepath without leaving your terminal.Explore the API Tester guide and start testing your proxies today. Secure Sensitive Data with Kubernetes Secrets in Apigee hybridEnhance security in Apigee hybrid by accessing Kubernetes Secrets directly within your API proxies. This hybrid-exclusive feature keeps sensitive credentials within your cluster boundary and prevents replication to the management plane. It supports strict separation of duties: operators manage secrets via kubectl, while developers reference them as secure flow variables—ideal for high-compliance and GitOps workflows.Implement Kubernetes Secrets in your hybrid proxies. See the Console in a Whole New Light: Dark Mode is Now Generally Available in Google CloudElevate your cloud management workflow with Dark Mode, now generally available in the Google Cloud console. We have delivered a modern, cohesive, and accessible experience reimagined for maximum comfort and productivity—especially during extended working hours and low-light environments. Dark Mode can be enabled automatically based on your operating system's preference, or manually through the Settings -> Appearance menu.Switch to Dark Mode today to enjoy a modern, comfortable, and productive environment! Apigee X Networking: PSC or VPC Peering?Deciding how to connect Apigee X? Watch this video to compare Private Service Connect and VPC Peering. We break down northbound and southbound routing, IP consumption, and how to reach targets on-prem or in the cloud. Learn to simplify your architecture and avoid common networking "gotchas" for a smoother deployment.Watch the video. Jan 19 - Jan 23 Bridge the Gap: Excel-to-API Conversion in Apigee PortalsGive your customers more ways to connect! This new article by Tyler Ayers explores how to extend the Apigee Integrated Portal to support direct Excel file uploads. By leveraging SheetJS and custom portal scripts, you can enable users to upload spreadsheets, preview data, and submit it directly to your APIs, all without writing a single line of integration code themselves. It’s a powerful way to simplify onboarding for those who aren't yet API-ready.Learn how to build it. Elevate your applications with Firestore’s new advanced query engineWe have fundamentally reimagined Firestore with pipeline operations for Enterprise edition. Experience a powerful new engine featuring over a hundred new query features, index-less queries, new index types, and observability tooling to improve query performance. Seamlessly migrate using built-in tools and leverage Firestore’s existing differentiated serverless foundation, virtually unlimited scale, and industry-leading SLA. Join a community of 600K developers to craft expressive applications that maximize the benefits of rich queryability, real-time listen queries, robust offline caching, and cutting-edge AI-assistive coding integrations.Learn more about Firestore pipeline operations.
Read original articleSeptember 25, 2026
At Google Cloud, we are committed to delivering the best managed experience backed by open source software. Today, we’re announcing the general availability of Memorystore for Valkey 9.1, which achieves up to 3x queries per second (QPS) at microsecond latency compared to Memorystore for Redis Cluster. Our support for Valkey dates back to 2024, when Redis Inc. shifted its licensing away from the permissive open-source BSD license to a dual-license model. In response, Google Cloud, alongside other technology leaders, backed the creation of Valkey, an open-source alternative governed by the Linux Foundation. Valkey has come a remarkably long way since then, delivering major performance and feature updates that push boundaries far beyond the original fork. Valkey is particularly compelling for organizations scaling AI and microservices to handle millions of concurrent users. Here, backend developers and architects must deliver both massive throughput while also maintaining microsecond latency. In this blog, let’s take a look at how Valkey 9.1 achieves its performance, new developer capabilities, how to get started, and how customers are using it. Under the hood: Rethinking thread communication In high-throughput, in-memory datastores, efficient I/O offloading is critical to keeping the main execution loop unblocked. Previously, Valkey assigned client sockets to I/O threads statically in a round-robin fashion, requiring the main thread to continuously poll lists of pending clients to detect completed work. Valkey 9.1 replaces list-polling with a lock-free, multi-queue messaging architecture that eliminates cross-thread CPU waste and unlocks dynamic work balancing. It involves three complimentary queues: Main thread to I/O thread queue: Dispatches read and write jobs to a single-producer multi-consumer (SPMC) queue. Free worker threads pull tasks on demand, enabling dynamic work-stealing that prevents thread starvation or hot-spotting. I/O thread to main thread queue: Worker threads push completed tasks into a multi-producer single-consumer (MPSC) queue. The main thread pops completed work instantly, eliminating busy-wait list iteration. I/O thread-specific queues: Dedicated single-producer single-consumer (SPSC) queues handle thread-affine memory cleanup and high-volume epoll offloading. Valkey 9.1 also replaces static thread thresholds with a two-phase dynamic scaling engine: CPU-driven "ignition": When main-thread CPU usage crosses 30%, the engine automatically activates the first background I/O thread to absorb incoming traffic before queue bottlenecks form. Queue-depth auto-scaling: Once ignited, Valkey dynamically scales the number of active I/O worker threads up or down based on real-time SPMC queue backlog, ensuring extra cores are used only when needed and parked when idle. New developer capabilities in Valkey 9.1 Beyond raw performance, Valkey 9.1 addresses key feature requests from engineering teams with powerful new commands and enhanced security controls. Here is a look at what you can do with these new capabilities: 1. Granular database-level access control (ACLs) We recently launched support for access control lists on Memorystore for Valkey to provide more granular key-level and command-level authorization using IAM. This foundational security mechanism is offered at no additional cost and includes the following capabilities: Centralized management: A 1:N mapping approach allows you to define a single ACL policy and attach it across multiple clusters. Secure multi-tenancy: Organizations can easily enforce least privilege and secure multi-tenancy across their database fleets. Enhanced observability: The feature includes versioned policy revisions and comprehensive audit logging. Previously, ACL rules applied globally across an instance. Valkey 9.1 allows administrators to restrict user access at the specific numeric database level within the ACL framework. Real-world example: You can configure a staging or service-specific user and isolate their access strictly to non-production databases: production user: @all ~* db=0 staging user: @all ~* db=1 dev user: @all ~* db=2 Protect against unauthorized data access and guard against application bugs by leveraging database-level access control across multiple databases, all without needing to prefix your keys. 2. CLUSTERSCAN: Efficient cluster-wide key scanning Previously, scanning keys across a large cluster required querying nodes individually. This approach was not cluster- or failover-aware. Consequently, scans could miss keys, return duplicates, or fail if slot migrations or node failovers occurred during the process. The CLUSTERSCAN command addresses these limitations by introducing a topology-aware cursor. This cursor encodes the current slot, the fingerprint of the local hashtable, and the local cursor. With this additional encoded information, clients can scan keys across the entire cluster while gracefully handling topology changes and redirections. CLUSTERSCAN supports two primary scanning strategies: Use case 1: Sequential full cluster scan (single worker) This strategy is suitable for simple scripts or background jobs that prioritize simplicity over speed. The client starts with cursor 0 and sequentially traverses all slots in the cluster: code_block <ListValue: [StructValue([('code', 'CLUSTERSCAN 0 MATCH "user:*" COUNT 10\r\n1) "0B3a21-{06S}-64"\r\n2) 1) "user:101"\r\n2) 2) ...'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f15a78d54d0>)])]> To continue the scan, pass the returned cursor to the next call. The cursor automatically transitions to the next slot when the current one is fully scanned. code_block <ListValue: [StructValue([('code', 'CLUSTERSCAN 0B3a21-{06S}-64 MATCH "user:*" COUNT 10\r\n1) "0B3a21-{07T}-0"\r\n2) 1) "user:102"\r\n2) 2) ...'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f15b423c490>)])]> The scan is complete when the command returns a cursor of "0". Use case 2: Parallelized cluster scan (multiple workers) This strategy is suitable for high-throughput scans. Using the SLOT argument restricts the scan to a specific slot, allowing you to partition the 16,384 slots across multiple parallel workers. Worker 1 (Scanning Slot 0): code_block <ListValue: [StructValue([('code', 'CLUSTERSCAN 0 SLOT 0 MATCH "user:*" COUNT 10\r\n1) "0B3a21-{06S}-64"\r\n2) 1) "user:101"\r\n2) 2) ...'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f15a7b59b50>)])]> Worker 2 (Scanning slot 1000 in parallel): code_block <ListValue: [StructValue([('code', 'CLUSTERSCAN 0 SLOT 1000 MATCH "user:*" COUNT 10\r\n1) "0B3a21-{08X}-32\r\n2) 1) "user:999"\r\n2) 2) ...'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f15a777f5d0>)])]> From here, Worker 1 continues to pass SLOT 0 and Worker 2 continues to pass SLOT 1000. Mismatching the slot and the cursor returns an error. Once all 16384 slots have been scanned, the cluster scan is considered complete. 3. More commands for atomicity and expirations HGETDEL: Atomic fetch and deleteA frequent application pattern involves reading a hash field and deleting it immediately (such as consuming single-use authentication tokens or short-lived session states). Valkey 9.1 introduces HGETDEL, which retrieves the value of a hash field and deletes it atomically in a single network round-trip. Real-world example:HSET user:1001 temp_token "abcde"(integer) 1HGETDEL user:1001 FIELDS 1 temp_token 1. "abcde"HGET user:1001 temp_token(nil) MSETEX: Shared expiration for multiple keysTo eliminate multi-command pipeline overhead, the new MSETEX command enables setting multiple keys simultaneously with a single, shared expiration time. Real-world example: Setting up a temporary session state where multiple distinct keys must expire together in 300 seconds:MSETEX 2 session:auth "ok" session:user_id "1001" EX 300(integer) 1TTL session:auth(integer) 300 Enhanced HSETEX with conditional flagsHSETEX now supports the NX (only set if the field does not exist) and XX (only set if the field exists) conditional flags. Real-world example: Initializing a rate-limit threshold field with a 1-hour TTL, ensuring you don't overwrite an existing active limit:HSETEX config:123 NX EX 3600 FIELDS 1 "rate_limit" "100"(integer) 1 Built on Memorystore for Valkey 9.0 The release of Valkey 9.1 builds upon the major updates we unveiled for Memorystore for Valkey at Google Cloud Next '26: Built-in modules for AI & vector workloads: Native JSON support and Bloom filters enable fast document querying and membership checks. Six new node sizes: To help you manage costs and scale, we added six new node sizes. Small Size Nodes: Custom-Pico (1.25 GB), Custom-Micro (2.5 GB), and Custom-Mini (3.5 GB) for lightweight microservices and dev/test environments. These are only available for cluster mode disabled environments. High CPU and Large SKUs: HighCPU-Medium (8 vCPU/13 GB) and Standard-Large (8 vCPU/26 GB) optimized for CPU-heavy applications. XXL SKU: Highmem-XXLarge with 110 GB RAM and 16 vCPUs per node for massive cluster consolidation to power your most demanding workloads. (Note: The figures above are based on open-source benchmarks; actual performance improvements will vary depending on your specific workloads.) Migrating to fully managed Memorystore for Valkey Having to self-manage your Redis OSS /Valkey caching layers drains valuable engineering bandwidth and creates operational friction during scaling. We are also excited to announce a new migration workflow to Memorystore for Valkey. With this release, migrating your infrastructure is straightforward, fully managed, and requires a simple configuration change on your application to point to Memorystore for Valkey once your data is migrated. This workflow is generally available.To move off self-managed Redis or Valkey to fully managed Memorystore for Valkey, follow these four steps: 1. Provision the target instance: Deploy a Memorystore for Valkey instance configured with your required shard count, node sizing, and clustered database options. 2. Establish online replication: Initiate continuous, dual-sync online migration directly from your source database to Memorystore. 3. Validate data synchronization: Monitor replication metrics in real time to verify full dataset alignment and low-latency replication health. 4. Execute the cutover: Switch application connection endpoints over to Memorystore for Valkey to start using the new cache. What Memorystore for Valkey customers are saying Already, over 95% of the top 100 Google Cloud customers already rely on Google Cloud Memorystore to power demanding, high-throughput workloads, led by increasing numbers of Memorystore for Valkey users. Consider the fast-paced world of live sports, where delivering a flawless digital experience is of utmost importance. When a game-changing play happens, millions of fans immediately reach for their devices to check real-time stats, watch highlights, and engage with interactive features. These massive, unpredictable traffic spikes require an underlying architecture capable of immense scale. For organizations like Major League Baseball (MLB) , a partner since Valkey’s early days, managing unpredictable traffic spikes without compromising performance is essential. "We trust Memorystore for Valkey to power the massive scale of live baseball, delivering real-time stats and uninterrupted digital experiences to millions of fans. As we look ahead, we are incredibly excited about the Memorystore for Valkey 9.1 launch. The engine optimizations and latency enhancements will give us even more horsepower to handle the most unpredictable game-day traffic spikes, ensuring fans get the best technology-powered experience the game has to offer." - Rob Engel, SVP of Software Engineering, Major League Baseball Beyond the stadium, the retail industry faces its own intense scaling challenges, particularly during major shopping holidays or flash sales. Modern e-commerce platforms rely on real-time personalization, dynamic pricing, and instant inventory updates to keep shoppers engaged. A lag of even a few milliseconds can disrupt the customer journey and impact the bottom line. To maintain a competitive edge, leading retailers such as Target require ultra-responsive caching layers to power their most crucial customer-facing platforms. "By leveraging Google Cloud Memorystore for Valkey, Target delivers ultra-low-latency, resilient caching for personalization services. We look forward to leveraging the performance enhancements in Valkey 9.1 to make our personalization platform even faster, more scalable, and more resilient during periods of peak demand." - Scott Weide and Sumanth Huddar, Senior Engineering Managers, Target The demand for these ultra-low-latency architectures extends far beyond sports and retail. Across the digital landscape, organizations in banking, AI-native development, digital streaming, and telecommunications all share a common mandate: the need for superfast, highly available caches. Whether it is processing high-frequency financial transactions, serving complex machine learning inferences in real time, delivering seamless global video streams, or routing immense volumes of telecom data, microsecond latency is the new baseline for success. Make the move to Valkey Stop letting cache bottlenecks slow down your most demanding applications. Experience the performance, dynamic scalability, and enhanced security of Memorystore for Valkey 9.1 today. Start building: Create a Memorystore for Valkey 9.1 instance in the Google Cloud console. Dive deeper: Read the technical documentation to view the full list of supported commands, ACL configurations, and detailed capabilities of Memorystore for Valkey.
Read original articleSeptember 25, 2026
The volume of data being generated today brings both opportunity and massive operational complexity. Most teams that operate at scale don't discover issues until they appear on an invoice — and by the time an unusual access pattern shows up as a line item, it has often been running for weeks. Understanding what happened means exporting inventory, joining it against access logs, and hoping someone still remembers which service account belongs to which job. That workflow was manageable in the past, but today’s AI training and inference pipelines create data faster than governance systems can classify it, and read data in patterns that shift from week to week. Today we're announcing two new features for Google Cloud Storage: the general availability of Storage Intelligence advisor along with expanded capabilities in storage batch operations. Advisor tells you what changed in your storage estate and what to do about it. Batch operations can carry that decision out across millions of objects. These features are available now to all Storage Intelligence customers. Storage Intelligence advisor in cloud console. Storage Intelligence advisor makes reporting easy For the last decade, answering "what’s in my buckets?" has been a data engineering project. Export your inventory, load it somewhere queryable, join it against usage, build dashboards, and then maintain them. Storage Intelligence delivers visibility without the engineering overhead. Teams are voting with their workloads: the number of customers using Storage Intelligence to analyze datasets of over 1 billion objects has more than doubled this year. There are two ways to run a large storage estate. Teams can leverage daily activity data and metadata snapshots to build exactly the pipelines they need –Storage Intelligence still gives you that option – but most teams would prefer not to build pipelines if they don’t have to. They want to be told what changed in their storage environment and what to do about it. Storage Intelligence advisor is for them. What Advisor gives you on day one Storage Intelligence advisor brings visibility into your storage without having to perform any setup. Advisor starts from a curated set of findings. There's no schema to design, no pipeline to manage, and no dashboard to assemble. Enable Storage Intelligence on an organization, folder, or project, and charts and findings appear for the buckets in that scope. Shipt can now more quickly detect anomalies with Storage Intelligence advisor: "Before Storage Intelligence advisor, tracking critical usage metrics and catching anomalies [in Google Cloud Storage] required heavy engineering and complex data pipelines. Now, with native, out-of-the-box dashboards, we can instantly identify usage spikes and drill down into the details. Having the visibility to immediately remediate unintended usage — without any configuration — has turned what used to be a major effort into a simple, self-service task." - Charley King, DataOps-DevOps Engineer, Shipt (a subsidiary of Target.com) Once it’s installed, Advisor immediately starts analyzing the Cloud Storage estate, scanning for anomalies and optimization opportunities including: A spike in Class A or B operations against Coldline or Archive data. Cold storage is cheap to use but expensive to access. A spike in 429 errors. Where a request pattern is outrunning limits, timeouts follow. A spike in cross-region egress. Total consumption rising above a long-term trend. Each finding is baselined from your project's own activity and metadata and works from daily snapshots of your storage usage, so a spike on one day is surfaced within 24 hours, not a line item you discover at the end of the month. In the last 30 days, over 6,000 findings have been generated across hundreds of customers. Take a runaway analytics job that issues millions of daily reads against Archive storage. Without Storage Intelligence advisor, this surfaces as a retrieval-fee weeks later on a bill. Advisor identifies the anomaly against your project’s baseline, attributes it to the responsible bucket, prefix, and service account, and points at the controls that apply: bulk-transition the affected objects to Cloud Storage Standard to stop retrieval charges, enable Autoclass so tiering follows real access patterns, or tighten access with Managed Folders so the job can’t reach data it was never meant to access. Act on findings with storage batch operations Most storage recommendations go unactioned because carrying them out is a lot of work. Updating retention policies or storage classes across billions of objects means handling throttling, partial failures, and retries. Storage batch operations removes that work. Execution is fully managed and serverless, with progress tracking and automatic retries built in, so a recommendation becomes a policy-driven job rather than a project. Palo Alto Networks had this to say about batch operations: "Object retention locks were essential for our security guardrails, but managing them across billions of objects was once a non-starter. Storage Intelligence changed that. Today, our team uses storage batch operations to seamlessly update retention policies on demand across our entire fleet." - Kurtis Nusbaum, Senior Principal Software Engineer, Palo Alto Networks Because Storage Intelligence advisor and batch operations are part of the same Storage Intelligence subscription so customers can now quickly identify issues with Advisor and easily remediate those issues with batch operations. Batch operations enables the following: Remediating operational spikes: Bulk-transition high-traffic Archive or Coldline objects to Standard as soon as the pattern is detected, curbing retrieval and operation charges immediately. Containing runaway growth. Mass-delete stale or temporary data across specific prefixes when the advisor flags above-trend storage growth. Enforcing fleet-wide consistency. Apply metadata, tagging, retention, or encryption changes uniformly across massive object sets, with no dedicated compute to provision. We also expanded and enhanced the existing capabilities of batch operations, making it easier to execute actions at scale: Multi-bucket processing: Run a single job across up to a thousand buckets per project, rather than executing it bucket-by-bucket. Dry-run validation. Simulate your transformations using dry-run mode before modifying live data. A dry run helps you safely preview a job's impact (including affected object counts, total size, and potential errors) before committing to permanent changes. Advanced filters powered by Storage Insights datasets: Use Common Expression Language (CEL) expressions to select objects directly by specifying conditions that match fields in Insights datasets. For example, you can filter objects across your buckets by storage class, object size, creation date, or custom attributes. Below is a CLI example demonstrating how to create a batch operations job using advanced filters. This job deletes all temporary objects belonging to the Standard storage class present in a user's "analytics" buckets. code_block <ListValue: [StructValue([('code', 'gcloud storage batch-operations jobs create bulk-delete-temp-objects \\\r\n --description="Bulk delete temporary objects in analytics buckets" \\\r\n --target-project="my-project-id" \\\r\n--insights-dataset-config="projects/my-project-id/locations/us-central1/datasetConfigs/my-dataset" \\\r\n --bucket-filters="name.startsWith(\'analytics-\')" \\\r\n --object-filters="storageClass == \'STANDARD\' && name.endsWith(\'.temp\')" \\\r\n --delete-object'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f15a7022e10>)])]> The evolution of storage management Storage management shouldn’t be a reactive effort reserved for quarterly reviews and post-incident fire drills. It should be continuous, proactive, and contextual. Storage Intelligence advisor and batch operations help to surface what changed and enable insights and action at scale. As Storage Intelligence gets better at recognizing which findings matter, Cloud Storage can carry more of the operating load for teams that need to manage storage at scale. Storage Intelligence advisor and enhanced storage batch operations are generally available today. To get started, enable Storage Intelligence on a project or org. If you haven't used Storage Intelligence before, a 30-day trial is available at no cost.
Read original articleSeptember 25, 2026
Reinforcement learning (RL) has been a keystone of modern LLM post-training, but it demands large training clusters and access to model internals that external customers can't have with proprietary models like Gemini. So here at Google Cloud, we packaged it into a managed RL fine-tuning service (RLFT service) — you bring prompts and a reward function; we handle the infrastructure and the proprietary model internals. Now, you can adapt Gemini with the service — teaching the model from a reward signal you define, rather than from a fixed set of labeled answers. This unlocks a class of problems that supervised fine-tuning (SFT) struggles with: tasks that are hard to demonstrate but easy to score. In this guide, we will walk through practical best practices for using RL fine-tuning service. We'll start with a short tour of the RL training loop, how to decide if and when to use RL, and introduce how to get the most value from this approach. What is RLFT? RLFT adapts Gemini from a reward signal you define rather than labeled answers. Instead of authoring a large set of gold examples, you write one program that scores a response and the service improves the model against it — unlocking tasks that are hard to demonstrate but easy to verify: you can't hand-write the ideal SQL for every schema, but you can run the query and check the result. At each training step the service generates multiple candidate responses to your prompts, scores them with your reward, and improves the model so that higher-scoring responses become more likely while it stays close to the original Gemini. The reinforcement learning that makes this work is fully managed — you never configure it. The one thing you own, and the thing that most determines your results, is the reward. Three properties define what RLFT can and can't do: It learns from the model's own outputs: It refines what the model already produces rather than copying an external target, so it tends to disturb unrelated capabilities less than SFT. It rewards outcomes, not paths: Any response that reaches a good result earns reward, which fits open-ended tasks with many valid solutions. It amplifies existing competence: It makes occasional success reliable, but it can't teach a skill the model never demonstrates. When to use RLFT Prompting and SFT handle most adaptation; exhaust them first. RLFT earns its keep when you can grade a response but can't cheaply author it, when SFT has plateaued on the metric that matters (faithfulness, schema validity, tone), or when the task has many equally valid answers a single reference target would wrongly penalize. SFT and RLFT are complementary, not competing: Direct RLFT when the base model already succeeds part of the time — enough for the reward to tell better answers from worse ones. Two-stage SFT → RLFT when you have SFT data or the base success rate is too low for RL to gain traction. Use SFT as a short, cheap warm start — kept light, since over-fitting the demonstrations leaves less room for RL to improve — then continue into RL via Continuous Tuning, which initializes RL from the SFT checkpoint. Across early adopters, these patterns show where RLFT delivers the most value — each scoring an outcome the business cares about but could never cheaply demonstrate. Use cases for RLFT AI-powered NPCs in games What: In-character, on-brand dialogue held across long, multilingual, multi-turn conversations. Problem: Off-the-shelf models break immersion — wrong language, hallucinated items, ignored players, repetitive loops. Objective and reward: A Gemini autorater (LLM-as-a-judge) scores each turn on persona, flow, and game-state syntax, penalizing format and language errors. Results: Loops and language drift disappeared and state syntax held, making shippable in-game characters viable at scale. Structured entity extraction What: Pulling a set of items from unstructured documents, such as supplier invoices and shipping manifests, into structured records automatically. Problem: The long tail where SFT plateaus — missing required fields (recall) or inventing ones that aren't there (precision). Objective and reward: A rule-based precision/recall reward forces every field to be grounded in the source text, not imitated from one gold answer. Results: Field-level accuracy rose on noisy real-world documents where tuning had stalled, turning a manual review step into an automated one. Content moderation What: Applying intricate policies and decision trees at scale. Problem: Models hallucinate false positives or reward-hack with invalid formats to dodge evaluation. Objective and reward: A Cloud Run reward pairs format validation with a deterministic grader to enforce multi-step policy adherence. Results: The model handled complex exemption carve-outs, sharply cut false positives, and stopped reward hacking — reducing the human-escalation volume that makes moderation expensive. Code measured by execution What: SQL or API calls graded on whether they actually run against customer data. Problem: SFT mimics one reference query and breaks on unseen proprietary schemas. Objective & Reward: A code-execution reward runs the code in a secure sandbox and pays out only if it compiles, executes, and returns the correct result. Results: The model produced first-attempt executable queries at closed-frontier quality and lower inference cost, letting non-technical users query proprietary data in natural language. Presentation slide generation via HTML What: Multi-slide decks authored as HTML/CSS. Problem: Training on text alone is blind to visual quality — overflows, clipped elements, and inconsistent styling slip through unnoticed. Objective & Reward: A code-execution reward renders the slides and scores visual design, layout integrity, structural completeness, and rubric adherence. Results: The model emitted modular, well-styled decks with cohesive themes and no layout overflow. Where to start? A dataset. A diverse set of prompts with a held-out validation split is enough for a first run — confirm the loop converges and reward moves the right way, then scale. Keep train and eval strictly separated; a contaminated eval hides overfitting. A reward function. Your task specification as code or configs, and the dominant driver of quality. A good reward correlates with human preference, is robust to malformed output (catch the failed parse and return a clearly negative score rather than crashing), and resists reward hacking — ensemble judges, penalize length, floor degenerate outputs, and prefer a verifiable check over a model's opinion. Validate it offline before launch. The service handles the rest; start from the defaults, watch reward and eval curves in the console, and take the checkpoint where validation reward saturates rather than the last step. Get started today What will you build? The tools are ready and waiting. Documentation: Reinforcement Learning Fine-Tuning
Read original articleSeptember 25, 2026
When AI leaders at OpenAI and Anthropic started talking about “pacing the frontier,” maybe someone should have asked: what pace? Now it’s turned into model drop week for both companies as Anthropic rolled out Opus 5.5, followed by OpenAI’s GPT-6 model updates just 90 minutes later. But the company that stole the spotlight was Meta, whose personal AI agent Muse is reportedly outpacing ChatGPT’s early numbers and is headed for smart glasses and […]
Read original articleSeptember 25, 2026
When a group of 15 Google DeepMind employees and alumni met for a breakfast this month in central London, the conversation quickly turned to how to raise money for an artificial intelligence startup.
Read original articleSeptember 25, 2026
SoCura reduces data wait times by up to 70 per cent using Microsoft Fabric Technology Record
Read original articleSeptember 25, 2026
Anthropic is asking its shareholders to approve a structure that would give its seven co-founders a combined 50.1% of the vote on most corporate matters.
Read original articleSeptember 25, 2026
Anthropic Faces Court Setback on US Supply Chain Risk Label Bloomberg.com
Read original articleSeptember 25, 2026
Aikido Security has released Altar-1, its first open-weight security model. It is a compressed version of Z.AI’s GLM-5.3, built to run inside infrastructure the customer controls. Altar-1 powers Aikido Machine, the company’s autonomous pentesting appliance for on-prem and air-gapped networks. Is it deployable? Yes, the weights are public on Hugging Face and run with vLLM […] The post Aikido Security Releases Altar-1: An Open-Weight Security Model Pruned From GLM-5.3 to 328 GB appeared first on MarkTechPost.
Read original articleSeptember 25, 2026
Microsoft Corp. co-founder Bill Gates warned that artificial intelligence is a “powerful enough” tool to kill off a substantial portion of humanity, joining a growing chorus of tech leaders and employees calling attention to AI’s existential risks.
Read original articleSeptember 25, 2026
OpenAI hack on Australian government reveals anxiety at heart of global artificial intelligence dilemma The Guardian
Read original articleSeptember 25, 2026
On this episode of Stock Movers: - Akamai Technologies (AKAM) shares soar after the cloud provider inked a seven-year $11.6 billion deal to provide computing power to Anthropic. Analysts say the deal should boost Akamai’s growth and its profitability profile looks attractive, given the contract is entirely focused on CPUs. - People (PPLI) shares jump on a report that MGM Resorts is discussing making a bid to purchase the Barry Diller-owned media giant. - Costco Wholesale (COST) quarterly profits surpassed Wall Street’s estimates after the company recorded a benefit related to tariff refunds. (Source: Bloomberg)
Read original articleSeptember 25, 2026
AI progress is sure leading to some odd resignation letters. A senior Google engineer has resigned from the company, saying he could no... The post Google Engineer Robert O’Callahan Quits, Says His Team Was Working On Faster And Cheaper AI Chips While AI Is Already “Progressing Too Fast” appeared first on OfficeChai.
Read original articleSeptember 25, 2026
Anthropic PBC has signed an $11.6 billion, seven-year contract with Akamai Technologies Inc. for computing power, building on a previous $1.8 billion computing deal that the two companies struck earlier this year. Mandeep Singh of Bloomberg Intelligence has more. (Source: Bloomberg)
Read original articleSeptember 25, 2026
It’s becoming more apparent every day that artificial intelligence agents are escaping our control — but it’s not yet apparent who or what is going to rein them in. This week a researcher found that a swarm of AI agents, at least two of them from OpenAI, hacked into a government agency among other organizations. […] The post More agents go rogue — but AI companies aren’t slowing down yet appeared first on SiliconANGLE.
Read original articleSeptember 25, 2026
President Donald Trump’s administration requested OpenAI and Anthropic PBC withhold new artificial intelligence models from the UK’s flagship testing agency without prior review by US authorities.
Read original articleSeptember 25, 2026
The latest AI models have shown incredible potential in accelerating scientific breakthroughs.
Read original articleSeptember 25, 2026
Meta gives every Muse user a free cloud computer running Ubuntu Linux where they can install software, write code, and browse the web. A "Sentinel" process monitors sensitive actions outside the user's workspace, while users can inspect every file in the system. With over 500,000 users in its first week, Meta is betting on product reach over model power. The article Meta's Muse agent gives every user a full cloud computer running Ubuntu Linux appeared first on The Decoder.
Read original articleSeptember 25, 2026
OpenAI Agents Hacked Into an Australian Government Website. Who’s Responsible? The New York Times
Read original articleSeptember 25, 2026
Microsoft Abandons Personal AI Chatbot Race With Copilot Reboot Bloomberg.com
Read original articleSeptember 25, 2026
OpenAI opened its Agents API in public beta this month, exposing the harness that powers Codex with managed sessions, tool The post OpenAI and Cursor agree on agent coordinators. They disagree on who runs them. appeared first on The New Stack.
Read original articleSeptember 25, 2026
Google is testing "Call for Me," a feature that lets Gemini call businesses on a user's behalf. The article Google's "Call for Me" lets Gemini phone businesses for you appeared first on The Decoder.
Read original articleSeptember 25, 2026
Roughly 950 agents spent 21 hours turning up a biology find nobody can yet explain. The company that sells the model is betting the slow part is still the bench.
Read original article