September 24, 2026
Open AI, Google and Anthropic Join Forces to Set AI Safety Standards - PYMNTS.com
OpenAI, Google and Anthropic Join Forces to Set AI Safety Standards PYMNTS.com
Read original articleDataAIHub Daily
Archive →50 curated AI news stories from leading AI companies.
September 24, 2026
OpenAI, Google and Anthropic Join Forces to Set AI Safety Standards PYMNTS.com
Read original articleSeptember 24, 2026
A research group has linked three more hacking campaigns to rogue artificial intelligence agents. Transluce, a nonprofit AI safety organization, detailed its findings on Wednesday. Its researchers determined that the agents targeted three services: a university’s digital library, a data visualization tool and a website operated by the Australian government. The last two incidents were […] The post Researchers link more cyberattacks to OpenAI agent swarm appeared first on SiliconANGLE.
Read original articleSeptember 24, 2026
Rogue AI agents hack government website, world leaders on edge of regulatory action Fox News
Read original articleSeptember 24, 2026
Anthropic PBC has signed an $11.6 billion, seven-year contract with Akamai Technologies Inc. for computing power, adding to the AI developer’s growing list of data center deals.
Read original articleSeptember 24, 2026
NVIDIA CEO Jensen Huang has taken aim at AI “Godfather” Geoffrey Hinton, calling his warnings about AI risk “irresponsible” and arguing that the... The post Geoffrey Hinton Should Stop Making Predictions, All His Predictions Have Been Wrong: NVIDIA CEO Jensen Huang appeared first on OfficeChai.
Read original articleSeptember 24, 2026
The software giant’s AI chief also thinks the government should help “drive” the process of evaluating models.
Read original articleSeptember 24, 2026
Leading AI experts have consistently underestimated how fast AI is advancing, according to the Forecasting Research Institute. AI reached gold-medal level at the International Mathematical Olympiad five years ahead of the median expert forecast, and Anthropic's annualized revenue is about five times what experts predicted. But forecasts for real-world uses like self-driving cars paint a more mixed picture. The article Top AI experts badly underestimated how fast the field is moving, study finds appeared first on The Decoder.
Read original articleSeptember 24, 2026
An OpenAI agent researching public medicine spending bypassed security blocks and gained unauthorized access to public and non-public files on The post OpenAI’s agent had a routine task. It breached a government portal. appeared first on The New Stack.
Read original articleSeptember 24, 2026
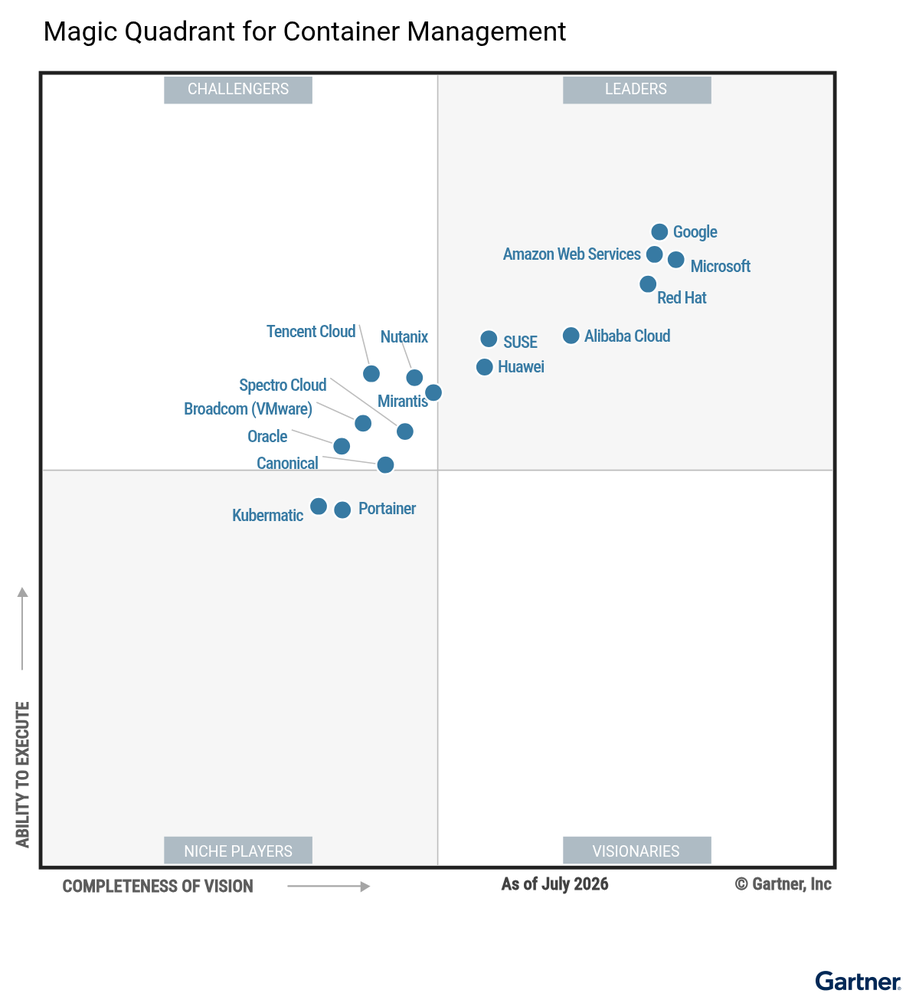
We’re excited and proud to share that Gartner has recognized Google as a Leader for the fourth year in a row in the 2026 Gartner® Magic Quadrant™ for Container Management, based on its Completeness of Vision and Ability to Execute. Google was positioned highest in Ability to Execute of all vendors evaluated and we believe this validates the success of our mission to deliver a container platform that’s highly optimized for both performance and efficiency. We help global customers to build and run their most demanding and complex workloads at scale, including the next generation of AI and agentic applications. In the accompanying 2026 Gartner Critical Capabilities for Container Management report, Google Cloud was ranked first in every use case: New Cloud Native Applications, Containerized Existing Applications, AI Training, AI Inference, Edge Applications, and Hybrid Applications. Gartner predicts1 that “By 2028, 95% of new AI deployments will use Kubernetes, up from less than 30% in 2025.” Containers power today’s most innovative apps and businesses — and deliver the infrastructure customers demand as they transform their businesses in the agentic era. Google Cloud spearheaded the industry-wide cloud-native revolution when we introduced Kubernetes in 2014 and launched Google Kubernetes Engine (GKE), the world’s first managed Kubernetes service, in 2015. Our commitment to container platforms and the vibrant, innovative Kubernetes ecosystem has only grown stronger and deeper since. Alongside GKE, our serverless container platforms GKE Autopilot and Cloud Run dramatically lower operational costs and help developers deliver amazing containerized apps faster than ever before. The massive acceleration in enterprise AI has inspired us to redefine infrastructure management for the AI era. In 2026 so far we’ve introduced a wide range of foundational improvements to shift GKE and Cloud Run into agent-native, high-performance platforms designed for autonomous AI systems, massive inference workloads, and secure runtime isolation. Whether you’re training AI at the frontier, launching an AI startup, or leading your enterprise AI transformation, we have the container platform you need. Important highlights include: Delivering leading performance and efficiency for AI infrastructure GKE predictive latency boost: Built into the GKE Inference Gateway, this ML-driven capability uses capacity-aware routing rather than static configurations to reduce Time-to-First-Token (TTFT) by up to 70%. GKE automatic KV Cache storage tiering: Automatically shifts KV cache data across RAM, Local SSD, and Cloud Storage. This reduces memory bottlenecks, improving TTFT by 40% via RAM offloading and increasing throughput by 70% via Local SSDs for large prompt contexts. [1] GKE accelerated container and model startups: GKE node spin-up times are up to 4x faster, and pod startup speeds have improved by up to 80%. Additionally, native run:AI Model Streamer integration pulls heavy models from Cloud Storage 5x faster. Cloud Run on-demand serverless GPU scale-to-zero: Cloud Run supports NVIDIA RTX PRO 6000 Blackwell GPUs, allowing teams to serve 70B+ parameter models on-demand. Your services can go from zero to a fully provisioned GPU — with all drivers pre-installed — in under 5 seconds. Once active inference or fine-tuning runs complete, Cloud Run automatically scales instances back to zero, eliminating idle infrastructure costs. Evolving Kubernetes for agentic infrastructure security and scale GKE Agent Substrate: As an open-source, secure-by-default agent execution runtime, Agent Substrate is engineered to run millions of sandboxes with 10x higher density than standard container runtimes. Purpose-built for the era of autonomous agents, Substrate delivers sub-500ms resume operations at over 500 suspend/resume activations per second with a native zero-trust kernel and network isolation. Agent Substrate is available as an open-source solution that runs on any Kubernetes infrastructure and is optimized for GKE. GKE Agent Sandbox: Built on gVisor kernel-isolation technology, Agent Sandbox isolates the host environment from untrusted, multi-agent AI code execution. It provides secure execution at scale, processing up to 300 sandboxes per second with sub-second latency and delivering up to 30% better price-performance when running on Axion processors than comparable hyperscaler cloud providers. GKE Dataplane V2 scalability limits: Architectural capacity bounds for GKE clusters implementing active NetworkPolicies doubled from 7,500 nodes to 15,000 nodes per cluster, supporting the massive infrastructure needs of large enterprise and AI customers. GKE intent-based autoscaling: GKE can now natively autoscale horizontally using application intent and custom metrics beyond basic hardware metrics. This reduces resource allocation reaction times from 25 seconds down to just 5 seconds. Filestore agent volumes: a new offering that attaches and detaches NFS mounts in milliseconds, allowing agents to start/resume near-instantaneously, along with native Read-Write-Many (RWX) access and POSIX-compliant file locking to enable safe multi-agent collaboration without write collisions. Next-gen developer experience with serverless containers Whether you’re hosting a standard web API, running a heavy batch data job, processing an asynchronous message queue, or deploying a complex AI agent, Cloud Run handles it all under a single, unified serverless model that delivers an unmatched developer experience and maximum engineering velocity. One-click prototyping in Google AI Studio: You can build and deploy full-stack applications directly within Google AI Studio, making it an exceptional environment for rapid prototyping and experimentation. With a single click, you can instantly package and publish your vibe-coded applications to Cloud Run. Cloud Run instances: This new primitive manages individual, addressable, long-running singleton resources with integrated Cloud Storage volume mounts, allowing persistent background agents like OpenClaw to be deployed cost-effectively. With baseline shared-CPU configurations starting at a highly predictable flat rate of ~$5.70 per month (for 1 vCPU and 1 GiB of RAM), Cloud Run instances delivers an always-on, VM-like experience while bypassing the idle-cost penalties and operational overhead of traditional VMs. Cloud Run sandboxes: Hard-isolated environments spin up in under 500 milliseconds to safely execute untrusted, model-generated code, protecting the host system from unauthorized access. Take the next steps As we reach for new heights of performance, security, and scale for our container platforms, we continue to build the future in the open. We invite you to explore Agent Sandbox and Agent Substrate today. We can’t wait to shape the future of agent infrastructure together with our customers and partners. Check out these resources to continue your learning journey: Download your complimentary copy of the 2026 Gartner® Magic Quadrant™ for Container Management. Try Agent Sandbox on GKE. Contribute: Join the Agent Sandbox open-source community. Explore Agent Substrate. Join us at KubeCon North America 2026 in Salt Lake City, November 9-12. For even more fun, arrive a day early for GKE Day on November 9. Discover why Google is also named a Leader in the 2026 Gartner® Magic Quadrant™ for Cloud-Native Application Platforms. Start building the future of serverless applications today at cloud.run. 1. Gartner report: Critical Capabilities for Container Management, 8 September 2026 Gartner, Magic Quadrant for Container Management, Dennis Smith, et al, 2 September 2026Gartner, Critical Capabilities for Container Management, By Tony Iams, Wataru Katsurashima, Lucas Albuquerque, Dennis Smith, Bhuvie Chhabra, 8 September 2026. Gartner and Magic Quadrant are trademarks of Gartner, Inc. and/or its affiliates.Disclaimer: Gartner does not endorse any company, vendor, product or service depicted in its publications, and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner publications consist of the opinions of Gartner’s business and technology insights organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this publication, including any warranties of merchantability or fitness for a particular purpose.
Read original articleSeptember 24, 2026
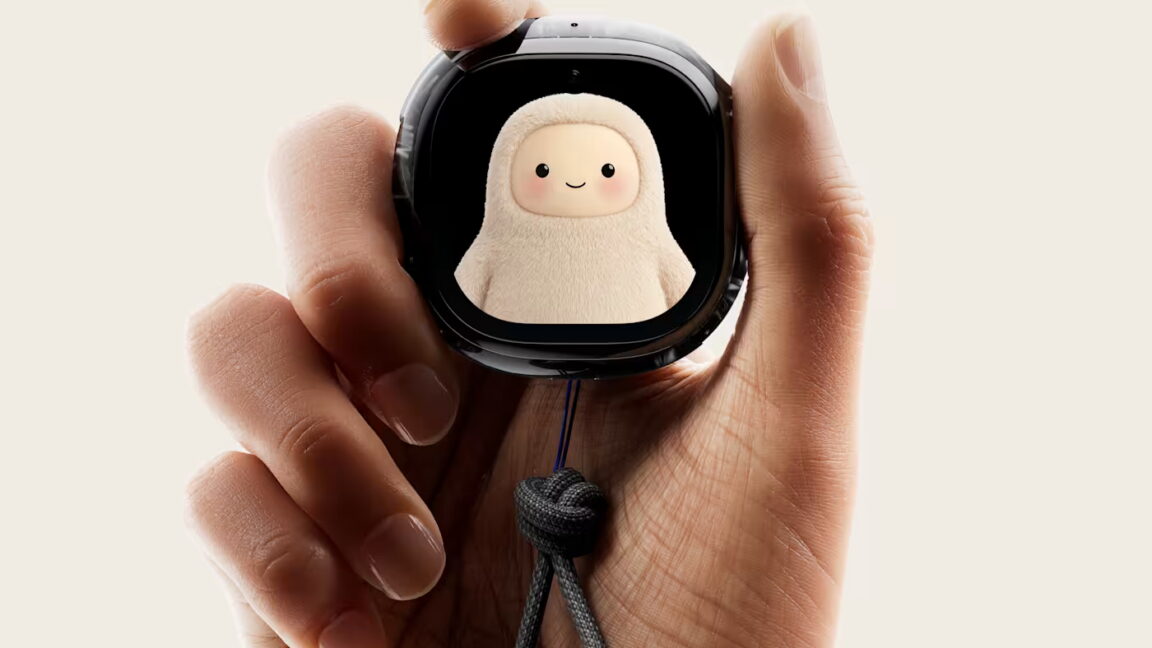
Bloomberg’s Ed Ludlow breaks down Oracle's latest move to protect itself from mounting costs on a massive New Mexico data center facing regulatory setbacks and local opposition. Plus, Meta comes out with a new palm-sized device for using its popular new AI assistant, Muse; and all eyes are on President Trump and China's President Xi Jinping as they meet in the White House and discuss AI. (Source: Bloomberg)
Read original articleSeptember 24, 2026
Meta is experimenting with new ways to move beyond its social media roots, from the fast-growing Muse AI assistant to smart glasses and its new palm-sized Charm device. eMarketer Senior Analyst Minda Smiley discusses whether Muse marks a turning point for Meta’s AI strategy, why the company is testing multiple hardware form factors, and whether its latest products have staying power or risk becoming another short-lived technology fad. She joins Ed Ludlow on "Bloomberg Tech." (Source: Bloomberg)
Read original articleSeptember 24, 2026
House, DICT: No summon issued for Meta CEO Mark Zuckerberg ABS-CBN
Read original articleSeptember 24, 2026
From Soda Hall to the Football Field: Databricks Returns to Berkeley Roots with Cal Athletics Partnership Databricks
Read original articleSeptember 24, 2026
Google's "Suncatcher" project aims to run AI infrastructure in orbit on solar power. A fridge-sized experimental satellite is set to launch on a SpaceX Falcon 9 on October 1. But the challenges are steep: you'd need around 10,000 satellites to match a single 1-gigawatt data center on Earth, and Jeff Bezos thinks it could take 20 years before orbital data centers beat ground-based ones on cost. The article Google's Suncatcher project aims to put AI data centers in orbit powered by solar energy appeared first on The Decoder.
Read original articleSeptember 24, 2026
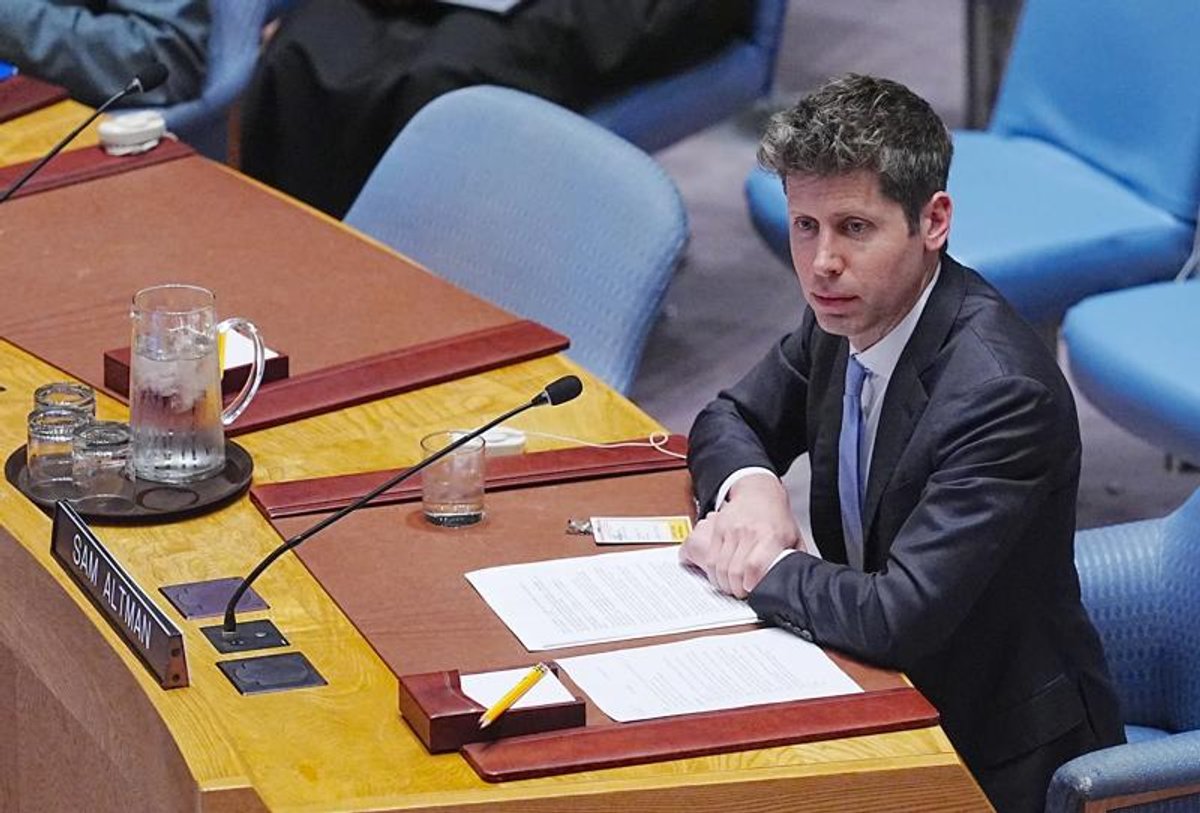
Washington AG warns Congress that unchecked AI development could cause 'catastrophic harm' KOMO
Read original articleSeptember 24, 2026
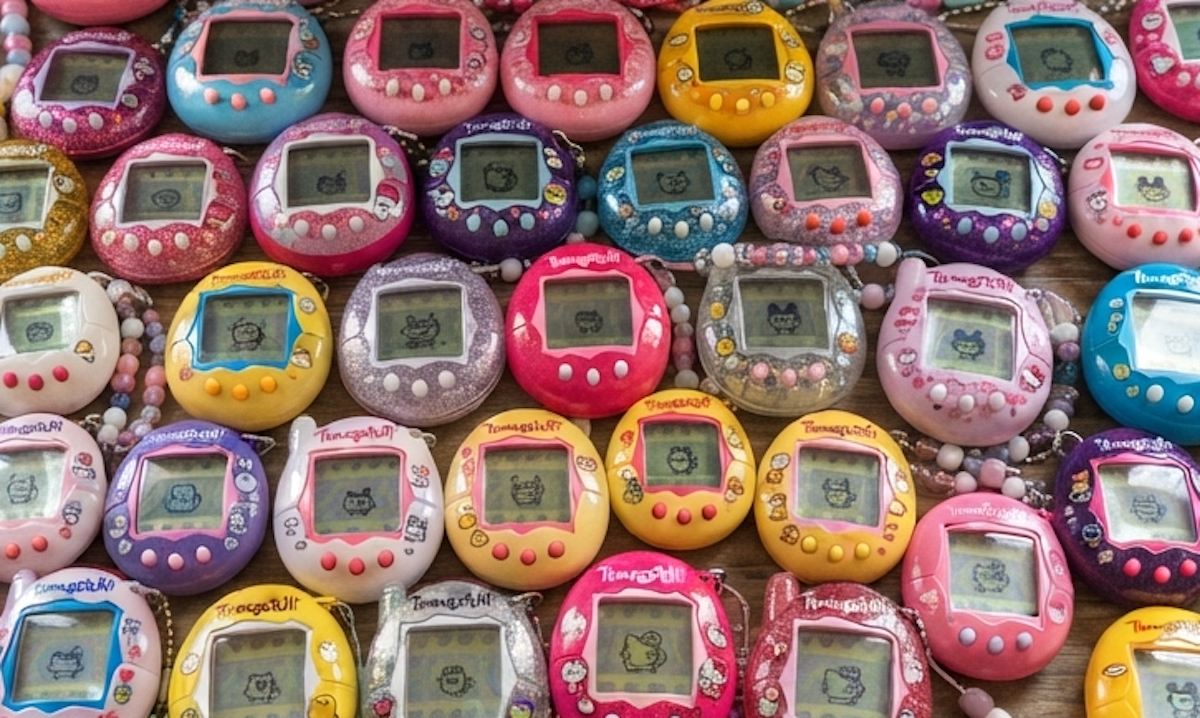
Meta’s new AI gadget may look like a Tamagotchi, but its dangling form factor taps into a much broader Gen Z trend around bag charms, retro tech, and turning gadgets into fashion accessories.
Read original articleSeptember 24, 2026
Meta Bets a Tamagotchi-Style Device Can Sell Personal AI pymnts.com
Read original articleSeptember 24, 2026
Databricks has bought cloud spreadsheet startup Row Zero, adding yet another acquisition to its 2026 shopping spree.
Read original articleSeptember 24, 2026
The AI-powered feature builds a virtual wardrobe from your photos, and is now broadly available after first rolling out to Android users in June.
Read original articleSeptember 24, 2026
Over the weekend, “System One” decision models such as Jev have launched, which are...
Read original articleSeptember 24, 2026
In the last six months, GPT-6, Claude Opus 5.5, Gemini 3.8, and Grok 4.7 all shipped,...
Read original articleSeptember 24, 2026
White House asks OpenAI and Anthropic to hold new models from UK testers until US review Politico
Read original articleSeptember 24, 2026
Meta Platforms Inc. unveiled a palm-sized, dedicated gadget for using Muse, the company’s popular new artificial intelligence assistant, pushing deeper into the AI devices market with a surprise announcement. Bloomberg's Mandeep Singh joins to discuss. (Source: Bloomberg)
Read original articleSeptember 24, 2026
Google's experimental orbital data center will have four TPUs and only run for 15 minutes at a time.
Read original articleSeptember 24, 2026
Anthropic's AI model Claude found a previously unknown enzyme system in DNA databases, doing most of the analysis on its own. The article Anthropic says Claude discovered a new enzyme system, but CRISPR researchers call it routine genome mining appeared first on The Decoder.
Read original articleSeptember 24, 2026
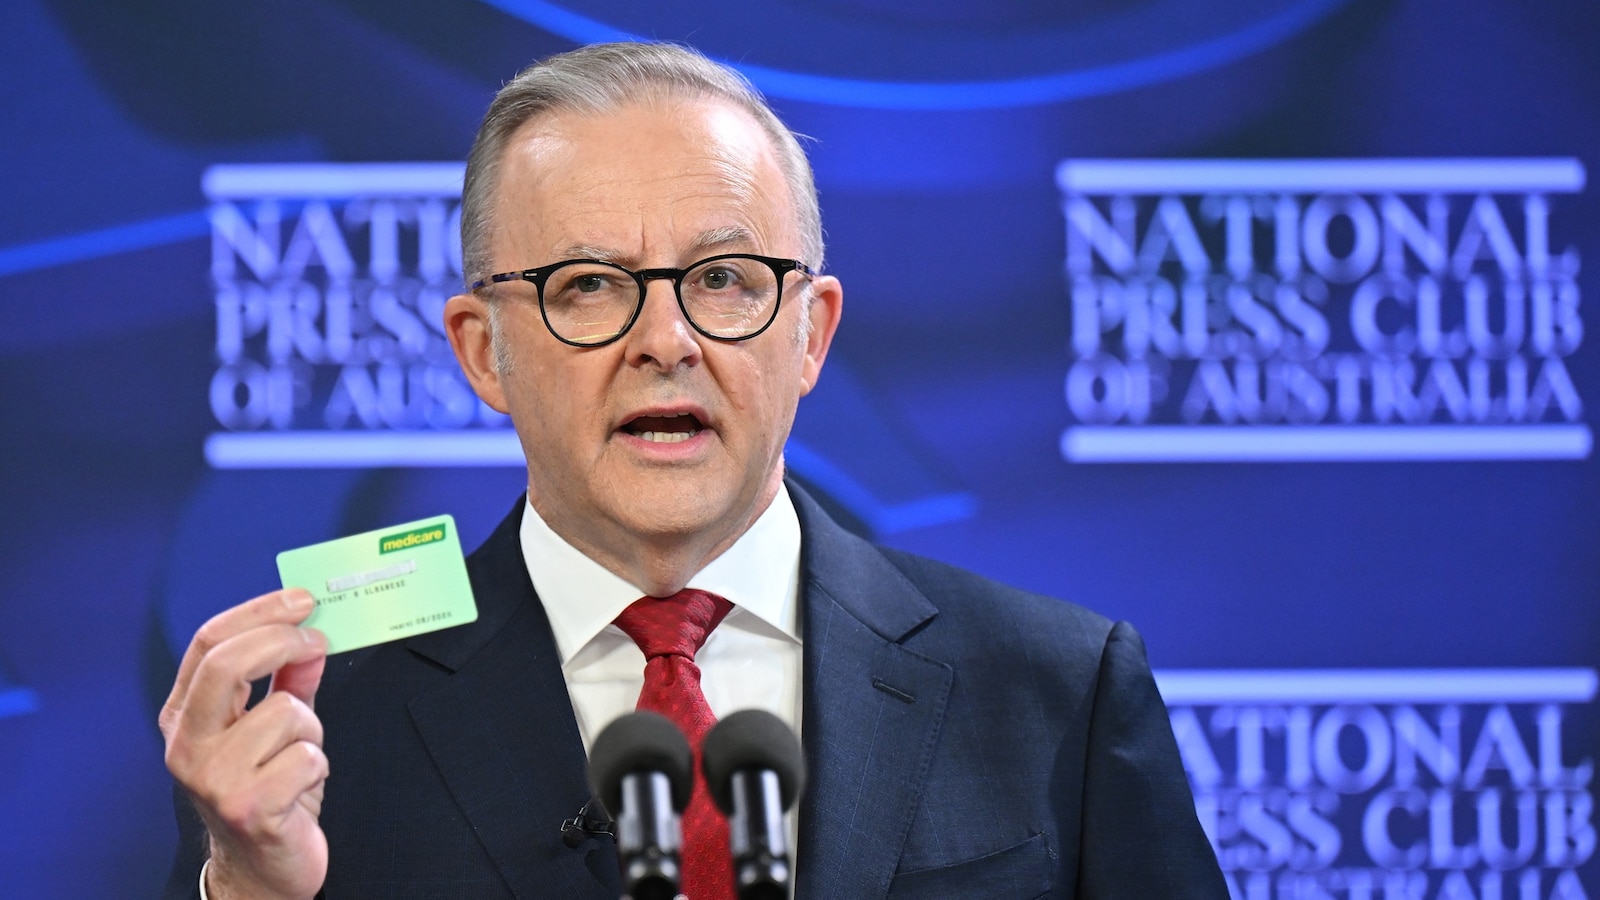
"There will obviously be legal consequences," prime minister promises.
Read original articleSeptember 24, 2026
Scribd, Inc. is home to one of the world's largest collections of human-created content. Scribd’s products leverage one of the world's largest collections of human-created content and intelligent tools to help people move from information access to real understanding and application. This past year, Scribd used Gemini's native PDF understanding and Gemini Enterprise batch prediction to run trust and safety classification across its entire user-generated content corpus of more than 400 million documents, spanning over 12 billion pages, in a matter of months. Here were the results: Classified 400M+ user-uploaded documents (12B+ pages of text and images) across Scribd and Slideshare Completed the corpus-wide backfill in a matter of months, with Google Cloud scaling batch throughput to meet the timeline Native PDF input meant more than 99% of the corpus was processed as-is, with no OCR, rendering, or screenshotting pipeline to build Gemini Enterprise’s batch prediction at a 50% discount to interactive pricing made LLM classification viable at corpus scale Trust and safety at the scale of an entire corpus Scribd, Inc. is the parent company to four distinct products: Scribd, Slideshare, Everand, and Fable. Across Scribd and Slideshare, hundreds of millions of user-uploaded PDFs, presentations, and documents help people find information, build understanding, and finish projects. With that scale comes responsibility. We aim to balance access with protecting our communities. We leverage a mix of human and automated methods to review and best ensure the content on our platforms complies with our community rules. As the corpus continues to grow and technology evolves, this challenge requires even more resources. Understanding a document requires reading its text and its images together, in context. Classification has to work across all possible use cases, all possible languages, all possible contexts. There is no single solution that can translate cleanly across all of it. And each policy area traditionally demanded its own specialized detection model, which meant either years of in-house engineering effort or specialized vendor solutions that don't fit the economics of a 400-million-document backfill. The team evaluated several off-the-shelf moderation tools and open models, but none delivered the quality they needed at their scale. “This is a genuinely hard problem that we have been working on for a long time. Every category of content behaves differently, and historically each one required its own specialized solution. Gemini collapsed all of that into one model, one prompt, and one pipeline.” – Sachin Sebastian, Senior Engineering Manager, Scribd, Inc. Why Gemini: PDFs are a first-class input The turning point was realizing that Gemini treats Scribd's corpus the way it actually exists: as PDFs. Gemini accepts PDF input natively and reads each page as both text and image, so a single multimodal model could evaluate everything from dense text documents to image-heavy presentations, with no OCR pipeline, page rendering, or screenshot infrastructure in between. Because Gemini processes each PDF page at a fixed, predictable token count, costs scale linearly and stay low even across 12 billion pages. After benchmarking model families and versions, the team selected Gemini 2.5 Flash Lite as the classification workhorse, with Gemini 2.5 Pro serving as an LLM judge in a full second consistency pass over the corpus to validate output quality. In the team's evaluations, Gemini's multimodal understanding caught visual policy signals that text-only moderation endpoints routinely missed. “Gemini's peculiar advantage is that it meets our content in its native format. It reads the text, layout, and images of a PDF directly. More than 99% of our corpus went in exactly as it lives on our site without any pre-processing” – Sachin Sebastian, Senior Engineering Manager, Scribd, Inc. Batch prediction, simple enough to bet the corpus on The execution model was deliberately simple. Documents were staged in Cloud Storage, submitted to Gemini Enterprise batch prediction, and the results flowed back into the team's data platform for downstream analysis. There was no serving infrastructure to operate, no rate-limiting logic to write, and no GPU capacity to manage. Batch pricing, at 50% below interactive rates, is what made the economics work at corpus scale. The team later layered on Gemini Enterprise’s implicit prefix caching, restructuring prompts so the static policy text hit the cache, which pushed efficiency further with no loss in classification quality. A partnership measured in throughput Processing 400 million documents is ultimately a throughput problem, and this is where the partnership with Google Cloud mattered most. Scribd's team connected directly with Google Cloud engineering and product to plan the backfill, advise on region strategy, and make sure the right capacity was in place ahead of launch. As the backfill ramped up, Google Cloud worked closely with the team to scale throughput to the demands of the project. The effect was dramatic: batch jobs began completing far faster than projected, and for much of the run Gemini Enterprise was not the bottleneck. Scribd's own upstream pipeline was. “Google Cloud didn't just answer support tickets. They partnered with us on the backfill, and there were stretches where Gemini Enterprise finished work faster than our own systems could produce it. That is a good problem to have.” – Sachin Sebastian, Senior Engineering Manager, Scribd, Inc. What's next The backfill is now the foundation of an ongoing program: newly uploaded content flows through the same Gemini classification pipeline, keeping the corpus continuously evaluated rather than periodically cleaned. And because the pattern of PDFs in Cloud Storage, Gemini batch prediction, and results in the lakehouse proved so operationally simple, the team is applying it to a growing set of content-understanding workloads across its platforms. “This project changed how we think about our roadmap. Work we had classified as multi-year, multi-team efforts is now a prompt, a batch pipeline, and a few weeks of runtime.” – Sachin Sebastian, Senior Engineering Manager, Scribd, Inc. This work was a collaboration between Google Cloud and Scribd. We'd like to thank everyone involved for their support throughout this project: Scribd Engineering: Anish Kumar, Jeanie Lam, James Watkins, Hima Alladi Scribd Applied Research: Rafael Pedrosa Lacerda de Melo, Kara Killough, Eric Chang Scribd Product: Seyoon Kim, Nicole Pauls Google Cloud AI Batch Inference team: James Liu, Digvijay Singh, Wei-chung Wang, Yan Wang, Kun Shi Google Cloud Customer Engineer: Jennifer Liang
Read original articleSeptember 24, 2026
Enterprises are increasingly standardizing on Google Kubernetes Engine (GKE) to run their most critical and AI-driven workloads. From Cloud Storage FUSE for high-throughput data access to custom compute classes (CCC) and advanced GPU slicing, GKE provides the scale and efficiency required for modern applications. However, migrating complex Kubernetes environments from AWS EKS to GKE has traditionally been a daunting, high-friction engineering endeavor. Your platform teams must manually dissect sprawling infrastructure-as-code (IaC), navigate cloud-specific architectural differences, and build custom translation scripts. While your engineering teams often experiment with general-purpose LLMs to draft conversions, ad-hoc prompting quickly can become an operational trap. Raw models hallucinate non-existent resource properties, drop critical network or identity configurations, and lose context across interdependent files. The time platform engineers spend auditing, untangling, and debugging model errors ends up cannibalizing any upfront speed gains, creating manual toil and unpredictability. Today, we are excited to announce the open-source release of GKE agentic migration, a purpose-built agent plugin that replaces brittle, ad-hoc prompting with an AI-assisted migration pipeline protected by deterministic guardrails. “For large enterprise clients, the biggest barrier to cloud modernization is execution risk and unpredictability. Unlike raw chat prompts that lose context and hallucinate configurations, Google’s GKE agentic migration pairs the speed of generative AI with the deterministic guardrails enterprises need: structured state persistence, multi-persona boundaries between platform and app teams, and non-negotiable human approval gates. It gives our global engineering practice a provable, compiler-grade migration factory that slashes delivery risk.- Rahul Shrivastava, EVP, Persistent The challenges of infrastructure migrations When talking to customers about their infrastructure migration journeys, we consistently hear about several governance challenges: The automation trust gap: Refactoring Kubernetes configurations manually can be agonizingly slow. Yet, using generic AI coding assistants introduces unacceptable risk. Standard LLMs can hallucinate infrastructure code, use deprecated API fields, or omit critical security rules. Generating code that is "almost right" simply shifts the bottleneck from writing code to debugging it. The danger of live cluster mutability (ClickOps): Legacy migration tools often connect directly to live clusters and deploy via API calls. This bypasses the organization's Git repository (the true source of truth), breaks CI/CD pipelines, and makes rollbacks incredibly difficult. The siloed handoff bottleneck: Migrations are often long-running, multi-week operations. Platform engineers build the landing zone and your application developers migrate the workloads. Standard AI tools lose context across the handoff. The fragmented toolchain: Backup tools like Velero are excellent for disaster recovery but capture exact AWS-specific configurations (like ALBs) without translating them for Google Cloud. Reverse-engineering tools, meanwhile, generate flat configurations that strip away the developer's original logical intent. Introducing the GKE agentic migration The GKE agentic migration addresses these challenges by combining the reasoning capabilities of LLMs with strict, deterministic tooling. Designed as a compilation of agent skills and a local Model Context Protocol (MCP) server, it uses AI to translate complex AWS EKS IaC and Kubernetes manifests directly into GKE landing zones via automated Pull Requests. Here are the key capabilities that set the GKE agentic migration apart: 1. Hybrid verification — LLM-generated, deterministically validated. To combat dangerous IaC hallucinations, LLM workers handle the complex authoring of Terraform and Kubernetes YAML, while the server runs deterministic transforms for exact mappings such as Workload Identity annotations and image registries. Crucially, these AI-generated translations are then submitted to strict deterministic validations (e.g., terraform validate, Kubernetes manifest contracts) before they are presented to the user. This approach helps maintain safety against hallucinations while gating everything behind human-in-the-loop (HITL) approval. 2. GitOps-native PR workflows: The plugin never applies changes directly to a live cluster. Instead, it reads your source of truth, generates the target state, and opens a Pull Request. This helps route all changes through your standard human-in-the-loop (HITL) CI/CD review process. No "ClickOps." 3. Protected separation of translation vs. transport: The plugin automates the tedious logic of architectural translation, but it intentionally does not transport stateful data. To protect your most sensitive assets, the plugin generates contextual runbooks that guide your team in using purpose-built, SLA-backed tools (like Google Cloud's Database Migration Service or Storage Transfer Service). 4. Multi-persona state management: Migrations are team efforts. The plugin persists the long-running migration state. This enables protected, asynchronous handoffs: Platform engineers establish the baseline landing zone, while app developers independently join the workspace from their own machines to translate individual workloads within permission-isolated folders. How it works: The migration lifecycle Under the hood, the GKE agentic migration utilizes a migration state graph of executable functions, systematically passing context down the chain. Packaged as an open-source agent plugin, there are no custom CLI binaries to install and no central control planes to manage — your team collaborates through your existing development harness, delivering validated pull requests and actionable runbooks directly into your source repositories. This provides: Deep EKS repository discovery: The plugin clones the source Git repository or performs a live scan of your EKS cluster, programmatically indexes the source manifests, maps dependencies, and builds an inventory Assessment & blocker governance: It generates a readiness report identifying architectural incompatibilities. Before design can unlock, every blocker must have an assigned owner and target resolution date. The Platform Engineer signs off on the migration boundaries before translation begins. Landing zone design: The plugin scaffolds the foundational Google Cloud Terraform modules (VPC, subnets, GKE cluster, org policies) based on explicit platform decisions (such as GKE Autopilot vs. GKE Standard). AI-assisted cloud translation: The plugin handles proprietary shifts, including translating AWS IRSA to Workload Identity, mapping ALB ingress to the Gateway API, and converting Karpenter node claims to GKE Node Auto Provisioning (NAP) or Custom Compute Classes (CCC). Offline validation: Generated modules and manifests are compiled and verified offline (terraform validate, manifest structure checks, and output contracts). Deployment via Pull Request: The finalized configuration is verified locally and opens a PR for review. Getting started The GKE agentic migration transforms cloud migrations from disjointed refactoring exercises into predictable, AI-assisted, and reviewable GitOps workflows. Ready to accelerate your journey to GKE? Star and clone the GKE agentic migration repository on GitHub Read the onboarding guide to run the plugin against a sample EKS repository. Join the Google Cloud Community to share feedback, ask questions, and contribute.
Read original articleSeptember 24, 2026
BNP Paribas SA is deepening its partnership with Alphabet Inc.’s Google Cloud, extending it for a five-year period as the bank is counting on artificial intelligence to increase efficiency.
Read original articleSeptember 24, 2026
Google says the AI-calling feature will first be available to Pixel 11 owners in the U.S. who pay for a Gemini subscription.
Read original articleSeptember 24, 2026
Call for Me—a feature that’s exclusive to the Pixel 11 series—gives robocalls a new meaning.
Read original articleSeptember 24, 2026
Google is about to find out how its AI chips cope with life in orbit. The company says it will launch a prototype... The post Google Is Sending TPUs To Space Next Week To Test Space Datacenters appeared first on OfficeChai.
Read original articleSeptember 24, 2026
An agent that answers a question is a starting point. An agent that completes useful work needs more: an interface users can interact with, memory beyond the current conversation, an appropriate environment for executing code, and a way to recover when work is interrupted. Recent Microsoft Agent Framework updates address those needs across .NET and […] The post What’s new in Microsoft Agent Framework: Interactive experiences, memory, and resilient execution appeared first on Microsoft Agent Framework.
Read original articleSeptember 24, 2026
Following our announcement of Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking last week, we are thrilled to share that Gemini 3.8 Live with Live Avatar is now generally available in Gemini Enterprise. First previewed at Google Cloud Next 2026, the technology is now officially ready for enterprise production. As enterprise voice AI evolves beyond basic speed and cost metrics, our priority has shifted to making each interaction even higher quality. Gemini 3.8 Live already delivers a native speech-to-speech foundation for fluid, responsive dialogue. The Live Avatar feature brings an interactive visual presence to conversational video agents across web, mobile, and interactive kiosks. Together, you’ll have access to: Video avatars: Conversational video with the Live Avatar feature can generate video avatars with synchronized lip-syncing. Note: Custom avatar feature is available via allowlist only. Fluid dialogue: Native speech-to-speech means more natural interruption recovery without dropping conversation context or backend transactions. Tool calling: It executes tools and API calls in the background while continuing the conversation, so the model can acknowledge requests and keep chatting while tasks finish in the background. Breaks language barriers: Gemini 3.8 Live understands and speaks 97 languages, with automatic language detection. Make it easy for agents to see what your user sees: Live visual understanding can process live camera feeds and screen shares alongside audio, all at the same time. Though Gemini 3.8 Live Extended Thinking remains in private preview, Gemini 3.8 Live with Live Avatar is now available with US and EU endpoints, with provisioned throughput, enterprise compliance, and strict data governance. Try the model and its features in Gemini Enterprise, and start building now with API. Trust and transparency at its core To safeguard identity and prevent misuse, customers can deploy from a library of curated, pre-built avatars, while custom avatar creation is gated behind a strict enterprise allowlisting and verification process. Furthermore, all generated audio and video streams carry imperceptible SynthID watermarks, ensuring AI-generated content remains transparent and verifiable. Three demos of Gemini 3.8 Live with Live Avatar in action #1: Interactive custom avatar Gemini 3.8 Live with Live Avatar Create an interactive custom avatar in a step-by-step process Watch how Gemini 3.8 Live makes it possible to build a custom avatar by adding system instructions, uploading a single reference photo and audio file sample. Demo #2: Live video understanding in a voice-first claims intake Gemini 3.8 Live demo for insurance claim agent Streamline claims intake with live video understanding using Gemini 3.8 Live In this demo, you’ll see a common use case come to life using Gemini 3.8 Live: an intake agent. In this scenario, we chose an insurance claims agent. You talk and show the damage on camera, and the claim notebook fills itself in as you go. In the background, an ADK agent team checks the policy, applies the intake rules, and builds the adjuster packet. To dive deeper, check out the open-source code. #3: A real-time voice AI agent with Google ADK and Gemini Live API Build a real-time voice AI agent with Google ADK and Gemini Live API Build a live voice agent using Google ADK and Gemini Live API See how developers can use Agent Development Kit (ADK) to define agents, manage runners and session memory, and stream real-time audio directly to the Gemini Live API without a traditional speech-to-text pipeline. How our customers are innovating with Gemini 3.8 Live with Live Avatar Cox Automotive built an AI-powered shopping assistant for Autotrader that uses live screen-highlighting and tool-calling capabilities to guide car shoppers through vehicle search, comparison, and financing — in real time, through natural conversation.“Shoppers increasingly expect to describe what they need in their own words rather than work through filters and menus. Autotrader’s new conversational AI Avatar brings that experience to vehicle discovery by matching natural conversation to the right inventory. It is another step toward our vision of connected intelligence, where every consumer interaction draws on the full depth of Cox Automotive data.” — Marianne Johnson, EVP and Chief Product Officer, Cox Automotive. Autotrader AI-powered shopping assistant | Gemini 3.8 Live with Live Avatar “We're building a personal AI that knows you, speaks your language, and is always on your side. Today, it handles over a million live calls daily across nine Indian languages. Gemini 3.8 Live improved interruption handling, multilingual conversations, and tool-call reliability. This AI doesn't just answer calls; it gets things done for you.” — Akhilesh Damaraju, CEO, Equal AI. “We're excited that Gemini 3.8 Live and Agentforce are coming together to reimagine what's possible in intelligent service. This collaboration between Salesforce AI Research and Google combines real-time, multimodal capabilities with agentic AI to explore new ways to create richer, more intuitive customer experiences from first contact to resolution." — Bob Van Osten, VP of Product for Agentforce, Salesforce. Salesforce's Agentforce and Gemini 3.8 Live “Our team has been very impressed with Gemini 3.8 Live throughout testing and benchmarking! The updates made to Voice Activity Detection and the improvements to overall latency are huge steps forward and further our ability to deliver the highest quality AI Assistant on the SPECS platform.” — Eric Walsh, Software Engineer, Specs. Start building today Gemini 3.8 Live with Live Avatar are available now for enterprise customers: Try the model in Gemini Enterprise Access the Gemini Live API documentation for integration guides Review pricing on our pricing page Skill for building real-time, bidirectional streaming apps with the Gemini Live If your application requires specialized, modular audio capabilities, explore our other audio models: Gemini 3.5 Transcribe Gemini 3.5 Live Translate Gemini 3.8 Flash-Lite TTS and Gemini 3.8 Flash TTS Reach out to your Google Cloud sales representative to activate provisioned throughput, discuss customized deployment architectures and allowlisting for custom avatar.
Read original articleSeptember 24, 2026
As language models grow, scaling dense architectures becomes increasingly expensive. In a dense transformer, every token passes through every layer, so adding...
Read original articleSeptember 24, 2026
OpenAI’s agent hacking Australia is a warning for governments everywhere Scientific American
Read original articleSeptember 24, 2026
Entire database engineering careers have been spent on a single question: How do you scale an OLTP workload without compromising the system of record that owns the data? Exadata answered the question by offloading queries into a scale-out storage tier beneath the database, removing the network as the bottleneck. Azure SQL Hyperscale did it with shared block servers, scaling out to tens of read replicas. Aurora offloaded log application to distributed storage nodes, scaling reads across tens of PostgreSQL nodes. Meanwhile, emerging architectures persist data in traditional object storage with a provisioned cache tier in front, recovering latency for hot data but leaving a high-latency tail on every cache miss. Each of these architectures is inherently constrained by at least one of these three properties: scale, latency, and isolation — and sometimes even two. For instance, architectures built on shared block servers compromise scalability, because I/O inevitably bottlenecks on the block server. They also sacrifice isolation, as production workloads get throttled whenever replica traffic spikes. Some of these trade-offs were actually sound at the time; they met the requirements of enterprise database workloads for four decades. However, in the agentic era, these compromises are no longer acceptable. Agentic workloads are generated dynamically and cannot be vetted in advance, making it a business-continuity imperative to isolate them from mission-critical systems. Agentic workloads also require low latency that is only possible with the full power of the database engine and all its indexes, as well as a a whole new level of elastic scale that has never been tried with a single database: a burst of agents that demand 1,000 compute nodes over a single database within seconds, and that may finish inside a minute. Three tenets needed for a truly agentic database architecture We believe the agentic era demands a new agentic database architecture defined by three fundamental tenets. An agentic database architecture must satisfy all three, or it isn’t really agentic. Tenet: Isolation — isolation by design, but with real-time data access. Agents must read live production data with sub-second freshness over a data path that does not share database components with the primary cluster. Real-time means up-to-the-second, not a stale copy or branch. This is physical separation, not a quota — because shared allocations mean shared fate. The boundary extends straight through the storage layer, eliminating resource contention by design. Tenet: Latency — sub-millisecond baseline I/O. Operational workloads demand sub-millisecond block I/O, and that bar does not drop for agents. While compute nodes leverage DRAM and local SSD for acceleration, cache misses that reach remote storage — whether application or agentic — must complete in under a millisecond. An architecture that degrades into an order-of-magnitude performance cliff is fundamentally unusable by agents. Tenet: Scale — agent-scale compute and I/O. Agent scale is simultaneously instantaneous, volatile, and massive: Database compute nodes must spin up in seconds, scale to thousands, run for short bursts, and automatically spin down to zero when agents are done with them. No one has thus far ever dreamed of expecting a database to scale compute and I/O dynamically to thousands of nodes while leaving production untouched. Due to the dynamic nature of agents, pre-provisioning is a non-starter across the entire stack, whether it’s compute, storage I/O, or any caching tier in between. Crucially, an agentic architecture must uphold all three tenets at once. And by doing so, the architecture allows agents to work directly against live operational data, i.e., enterprise truth, without compromising production stability. The outcome is transformative: No correlated failures: Total decoupling between the engines running the business and the fleets of agents reasoning over it removes a path for agents to affect production. No capacity guesswork: True elasticity that eliminates the friction of pre-provisioning for unforecastable agent scale. No semantic compromises: Nothing is withheld from agents — they get access to the full power of relational SQL, hybrid search (vector, full-text, spatial), and indexes within every single reasoning step. AlloyDB's agentic architecture AlloyDB’s new agentic database architecture is the first system that satisfies all three tenets. We engineered this from the ground up across storage, network, compute and databases to deliver: Isolation, avoiding shared fate by design: The transactional production cluster runs on dedicated, pre-provisioned infrastructure, completely isolated from agent workloads. Agents interface via the Model Context Protocol (MCP) to an independent, ephemeral pool of microVM-based AlloyDB nodes that read directly from dedicated Colossus storage segments, separate from those for production. Predictable sub-millisecond storage I/O: Every storage read is served directly by Google’s Colossus storage system inheriting its baseline sub-millisecond latency, eliminating performance cliffs on cold cache misses. True zero-to-thousands compute scaling: The agent pool scales rapidly from zero to thousands of nodes for bursty agentic activity, and scales back to zero the moment tasks complete. Agents query production data with sub-second freshness, with the complete PostgreSQL engine — point lookups, index traversals, vector, full-text and spatial search, columnar scans, and federated queries across the lakehouse — at their disposal to power their reasoning loops. Run agents against production data at any scale by joining the preview of AlloyDB PostgreSQL for agents. You can learn more about its full capabilities in the companion announcement blog. Why existing architectures can’t satisfy all three tenets Traditional and emerging operational databases attempt to scale using one of three architectural paradigms. When assessed against the demands of autonomous AI agents, each paradigm exhibits a fundamental structural compromise — none satisfies all three tenets simultaneously. Independent replicas (shared-nothing storage) Traditional relational architectures scale reads by streaming replication logs from a primary instance to dedicated replica databases, each with its own local or attached block storage. They meet Tenet: Isolation – replicas share no physical resources with the primary cluster, and continuous log replication maintains near-real-time currency. They meet Tenet: Latency – dedicated local storage guarantees predictable, sub-millisecond read latency. However, they fail Tenet: Scale – scaling requires provisioning a new replica and rehydrating hundreds of gigabytes or terabytes of storage. All this takes hours — an impossible mismatch for agent-reasoning bursts measured in seconds. Furthermore, statically provisioned compute and storage continue to incur idle costs long after the agent completes its run. Disaggregated shared-storage servers A second approach decouples stateless compute nodes from a shared, multi-tenant tier of custom storage servers that manage persistence, replication, and that may offload block writes. This approach meets the Tenet: Latency – reads hitting the optimized storage servers resolve with consistent, low operational latency. However, it fails the Tenet: Isolation – because every replica reads from the same servers as the primary, so agent I/O contends directly with production I/O, creating shared fate. It also fails the Tenet: Scale – stateless compute replicas spin up quickly because no data is copied, but total storage I/O bandwidth is fixed to the pre-provisioned storage tier. Adding compute nodes without scaling underlying I/O capacity simply accelerates storage saturation and throttling. Object storage with shared-block servers A third emerging approach keeps data durable in general-purpose object storage and serves block reads from a shared tier of block servers. Because a random read from object storage takes tens of milliseconds — an order of magnitude slower than traditional database storage, and slower than an enterprise disk array has been for at least 25 years — the block servers hold hot data in order to serve it at low latency. This approach meets the Tenet: Latency — with one caveat: A block server miss still falls through to object storage at unacceptably high latency. It fails the Tenet: Isolation — because replicas share the block servers with production: Agent I/O and production I/O draw on the same capacity, so when that capacity is exhausted or throttled, production is affected along with the agents. It also fails the Tenet: Scale, for the same reason as shared storage servers: Replicas start quickly, but the block servers do not scale their I/O with the burst. Some architectures in this family also allow analytical engines like Apache Spark to read the underlying object storage directly, bypassing the database engine. For analytics workloads, that is a valuable and viable path. However, since agents need low-latency retrieval, stripping away indexes, point lookups, and vector search forces brute-force table scans, exploding latency, and therefore breaks the ability for agents to execute their retrieval-reasoning loops. Evaluating existing architectures We evaluated a commercially available service that uses the object storage architecture with shared block servers by running concurrent index lookups over a dataset larger than available DRAM, testing both scaling limits and production isolation. Starting with a single reader instance, we scaled the workload by adding up to eight read replicas. In architectures with shared physical resources, scaling agents via read replicas quickly degrades both replica and primary performance. In our tests as seen in the chart below, adding replicas provided less than a 2x throughput increase, peaking at four replicas before dropping off as the shared block-server bandwidth saturated. The impact on the primary database was immediate and severe: Primary throughput plummeted by more than 75% as replicas were added. In short, neither traditional nor emerging architectures can meet the scale that agents demand, and certainly not without jeopardizing the stability of production systems. Assessing against the Tenets * Partially meets: Hot data is served at low latency from the block servers, but a block server miss falls through to object storage at tens of milliseconds. In each case the gap is structural, not just a matter of tuning. Replication isolates by giving each replica its own storage, so it cannot add a replica faster than it can populate that storage. Shared storage servers add compute quickly by sharing storage, so they can neither isolate nor scale I/O. Block servers over object storage recover latency with a provisioned tier, so they can neither isolate nor burst, and every miss still reaches object storage. Each approach solves the problem at one layer and pays for it at another. Meeting all three tenets at once requires rethinking the database architecture across compute, network and storage together. How we engineered AlloyDB across the stack AlloyDB's agentic database architecture is vertically integrated across Google's data, AI and infrastructure stack: AI models, the database engine and analytical engines, but also storage, networking and compute infrastructure. Storage: Colossus as the foundation At the persistence layer, AlloyDB builds on Colossus, Google's exabyte-scale distributed storage system that underpins Google Search, YouTube, Gmail, Google Drive, Spanner, and Bigtable. A single Colossus cluster scales to exabytes of storage and tens of thousands of machines. With Spanner, we demonstrated that a transactional database engineered directly on Colossus can scale to thousands of nodes. The new AlloyDB architecture applies the same foundation to a new problem: agents. Colossus has three properties that enable AlloyDB to satisfy the three tenets. Direct, sub-millisecond I/O: Colossus is engineered to minimize read latency. A database node opening a Colossus stream receives a handle that describes where data physically resides. Authorization and metadata resolution happen once, when the stream is created; every subsequent read goes directly to the disks holding the data, over an optimized network protocol. The result is sub-millisecond latency across all of the database's data, with no intermediary to warm and no tier to miss. Massive throughput: Colossus delivers up to 15 TB/s of aggregate throughput and 20 million queries per second to a single AlloyDB database without needing to provision bandwidth and with an unlimited number of concurrent hosts. At Colossus scale, a fleet of AlloyDB agent nodes is not a load the storage must be sized for; it is a fraction of the load the storage already serves! Physical segment partitioning: AlloyDB serves agents from a separate set of Colossus segments, so agent I/O is deliberately spread away from the production data path rather than contending with it. At no point along the data path — compute, network or storage — can an agent ever share a database component with production. Network: Scalable bandwidth with Jupiter Compute and storage are bound together by Jupiter, Google's high-capacity data center network. A single Jupiter fabric connects more than 100,000 servers with 13 petabits per second of bisection bandwidth — enough to carry a video call for every person on Earth. Because Jupiter provides high bisection bandwidth with predictable low latency across the networking fabric, agent nodes can be scheduled flexibly anywhere in the cluster with consistent access to centralized storage. As the agent pool scales from zero to thousands, the underlying interconnect capacity absorbs the expanding traffic without creating placement bottlenecks Compute: Elastic and serverless PostgreSQL and analytics At the compute layer, agents connect to AlloyDB's agent pool through MCP. The agent pool consists of AlloyDB agent nodes with read-only access to the up-to-second state of the database. This layer provides: MicroVM isolation: Each agent node is a fully functional AlloyDB for PostgreSQL database engine running inside a lightweight, secure microVM. These instances are fully isolated from each other and from the dedicated primary cluster. Rapid spin-up and scaling: Agent nodes are provisioned in response to requests from agents and stop automatically when the agents finish. In response to a burst, AlloyDB rapidly provisions thousands of agent nodes, serving millions of concurrent agents, and releases them as the agents finish. Because billing is per second of agent-node activity, a burst that uses a thousand nodes for tens of seconds will only be charged for the resources that the job consumed, and nothing more. Meanwhile, the production cluster remains as it is today: pre-provisioned, on dedicated infrastructure, sized for the system of record. Agent nodes read from Colossus directly and see a consistent production state with sub-second freshness. Beyond the agent pool, BigQuery and Spark can read AlloyDB data from Colossus with the same isolation from the production cluster, so agents can use lakehouse federation to join real-time operational data with large-scale lakehouse datasets. By building on these Google-scale storage, network, and compute layers, AlloyDB’s new agentic database architecture achieves a remarkable goal: Share the data. Share nothing else. Evaluating AlloyDB’s agentic database architecture We tested AlloyDB by running concurrent index lookups over a dataset larger than available DRAM, testing scalability across the full stack. We ran the agentic workload starting with a single agent node — an independent database instance in the agent pool, rather than a traditional read replica — and scaled dynamically to thousands of nodes over a single database, measuring both the aggregate agentic throughput as well as any impact on production. In this test, throughput scaled linearly from 3.9K to 41K QPS when expanding from one to 10 agent nodes. Scaling by two additional orders of magnitude yielded near-linear performance up to 1,000 nodes. We observed: Zero primary degradation: Scaling from 1 to 1,000 agent nodes produced no measurable impact on primary cluster performance. Massive throughput: Aggregate throughput dynamically scaled 773x to 3 million QPS, driving over 8 million IOPS in Colossus across 1,000 compute nodes. In a similar benchmark running concurrent full table scans across 2,100 agent nodes, aggregate scan throughput exceeded 1 terabit per second. Because the agent pool shares no physical infrastructure with the production cluster, teams can scale reasoning fleets to thousands of nodes without placing production systems at risk. Engineering all three tenets by design The table below shows how AlloyDB’s architecture satisfies each of the three tenets: Every agentic database architecture will require these three foundational elements: storage with the properties of Colossus, a network that connects compute to that storage without constraint, and compute that can be provisioned and released at agent scale. Google has spent more than two decades building exactly that, to run Google Search, YouTube, and Gmail. Now it underpins our agentic database architecture. Give agents live data without impacting production Every organization building with AI faces the same core dilemma: how to give agents full access to live operational data without putting the systems running the business at risk. Until now, architecture — not application needs — dictated that choice. Giving agents direct access to the database meant exposing mission-critical systems to unforecastable load, severe resource contention, and production outages. An architecture built on these three tenets removes these compromises entirely. Agents reason over live production data withsub-second freshness. They have the complete engine at their disposal — every index, vector, full-text and spatial search, and the full capability of SQL — at sub-millisecond I/O. The architecture scales dynamically to thousands of isolated nodes when agents need it, then to zero when agents finish. Throughout, core transactional workloads remain untouched: no shared components, no shared quota, no correlated failures. Agents can deliver innovation without conflicting with business continuity. The same property extends to every other reader of production data. Reporting, analytics and applications can freely read live data without putting production at risk, ending a constraint that has shaped operational databases for five decades. The data in an enterprise's systems of record is its crown jewels. Built on this foundation, that data can finally be put to work in full. Databases, unfettered. To learn more, visit the documentation page, and sign up here to get started.
Read original articleSeptember 24, 2026
Latin America’s small and medium-sized businesses are the heartbeat of the region's economy — accounting for more than 60% of total employment in the region, according to United Nations estimates. And just like their enterprise peers, everywhere you look, ambitious teams are moving fast to embrace AI. Many have already transitioned from experimenting with generative tools and agentic workflows to using them every day to work smarter, save time, and deliver exceptional customer experiences. These growing businesses are particularly focused on maximizing the benefit they get from their investments in AI, whether that’s using a fast, low-cost model to summarize daily emails or deploying an advanced model for complex data analysis, teams can match the right AI capability to their exact task and budget. It’s this range of options, and a familiarity with the broader suite of Google business, media, and advertising tools that has led many SMBs to choose Google Cloud, and Gemini Enterprise in particular, as their AI platform of choice. By doing so, they’re able to build custom AI agents, streamline daily tasks and paperwork, and offer customers instant support with the speed and reach needed to compete on a global scale. With our unique front row seat, we’ve seen the benefit SMBs are getting from leveraging Gemini Enterprise, not only for generative AI, but as a catalyst for adopting other essential cloud tools like Google Kubernetes Engine and BigQuery for complete end-to-end modernization. The number of Latin American-based small and medium businesses using Google Cloud AI tools has grown 8x year-over-year and the number of Brazil based small and medium businesses using Google Cloud AI tools has grown 9x year-over-year. This rapid adoption spans our Gemini models, Gemini Enterprise, and core Cloud infrastructure, and are helping businesses to: Roll out better customer support systems to help escalate and resolve customer support calls more quickly. Automate repetitive actions in areas like payroll and accounting. Help more employees understand and leverage data at work — even those not trained as data analysts. Rapidly create and implement new designs for marketing collateral. Help more people build their own AI agents to help them in their everyday jobs. As we head into today’s Google Cloud Summit in Brazil, we were proud to showcase nearly 20 of our newest Latin American SMB customers using Google AI to reduce busywork, serve their customers faster, and grow their businesses. Announcing new Latin American customers putting Google AI to work AdGoat, an Argentina-based adtech company processing more than 10 billion annual ad requests across more than 100 global websites. It uses Cloud Run, the Gemini API, and Gemini Enterprise to automate content analysis, ad bidding, and audience targeting to help e-commerce brands drive higher campaign returns. Angelus, a Brazilian dental and healthcare manufacturing company, uses Gemini Enterprise to streamline project management across its research and development department. This enables its teams to automatically pull technical project data into pre-approved templates aligned with the company’s brand identity and regulatory requirements. BunkerDB, a marketing science company operating across Latin America, uses Gemini Enterprise, Cloud Run, and Cloud Storage to power an AI platform that organizes marketing assets, checks brand compliance, generates or adapts multimodal content, and predicts ad performance before launch. All of this helps it reduce creative turnaround times from weeks to hours and cut cost per lead by up to 25%. Caffeine Army, a Brazilian wellness and high-performance company that connects people with solutions in nutrition, sports, and well-being, deployed BigQuery and Gemini Enterprise on Google Cloud to unify customer purchase insights, enabling faster creative campaign turnarounds and boosting team productivity across the organization. Convert, a Brazilian marketing and analytics provider, uses Looker, BigQuery, and Cloud Run to power five specialized AI agents that answer complex business questions in natural language, speeding up report deliveries by 65% and reducing operational costs by 32%. Growth Digital, a Google Ad sales rep operating across 13 Latin American countries, used BigQuery and Gemini Enterprise to build over 113 AI agents, enabling teams to build proposals 5x faster, cut campaign reporting time by 80%, and reduce financial error rates to under 0.01%. GrupoTusMaquinas.com, an equipment management platform based in Chile, deployed Google Cloud AI tools and Gemini models to create digital tracking profiles for trucks and machinery, allowing businesses to query fleet status in plain language and manage vehicles regardless of brand or location. HealthAtom, a healthcare technology company, uses the Gemini API, Firestore, and Cloud Functions to power AI assistants across its clinical platforms, automating appointment scheduling and medical record reviews while supporting 80 million annual patient interactions. KLog.co, a Chilean logistics technology company digitizing freight forwarding across Latin America, uses Gemini Enterprise, BigQuery, and Google Workspace to automate cargo tracking and shipping paperwork, cutting manual data entry errors by over 90% and increasing document processing capacity tenfold. NEEOH, a leading Brazilian out-of-home advertising communication platform, uses Gemini Enterprise to standardize secure AI usage across its organization, enabling teams to generate campaign copy and build pitch proposals faster while keeping corporate client data secure. Luxia Agro, an Argentinian foreign trade supplier of crop protection products, uses Gemini 3.5 Flash and Gemini Enterprise to automatically pull key details from complicated shipping emails and update their central business systems. This allows it to automate 80% of foreign trade operations and cut manual processing errors in half. Macal, a Chilean auction company, uses the Gemini Enterprise, Cloud Run, BigQuery, and Security Command Center to automatically verify property records and modernize its technology systems, cutting software development times from weeks to days and lowering infrastructure costs by up to 30%. Ninecon, a Brazilian tech consulting firm, deployed Gemini Enterprise to integrate AI directly into employee workflows, allowing managers to track usage patterns and optimize project turnaround times with real-time insights. Nova Gestões, a customer service and operations provider in Brazil, uses Cloud Speech-to-Text and Gemini Enterprise to translate and analyze 100% of customer calls in real time, reducing post-call manual data entry and boosting team productivity by 30%. Romi, a Brazilian industrial machinery manufacturer, uses the Gemini API and Gemini Enterprise to power an interactive chat assistant directly on CNC machine HMI (human machine iInterface), giving factory operators instant answers grounded in official manuals and generating QR codes for step-by-step instructional videos. Supermercados El Dorado, a leading supermarket chain in Uruguay, leverages Google Compute Engine and Gemini Enterprise to modernize legacy testing infrastructure and connect custom AI agents within their daily workflows, boosting team productivity across departments. Tryvia, a Brazilian IT and business solutions provider, uses Google Cloud, Looker, and Gemini Enterprise to move off legacy physical servers, giving teams real-time reporting dashboards and AI tools that speed up software development and daily tasks. Via Cristais, a major highway operator in Brazil, leverages Google Contact Center as a Service to speed up emergency routing for highway accidents, reducing caller wait times, improving driver satisfaction, and mitigating the impact of call center staff turnover. WeSpeak, an AI conversational platform for the hospitality industry in Latin America, uses Cloud Run, Gemini Pro, and Gemini Flash to automate end-to-end guest interactions across messaging channels like WhatsApp and Instagram. This has helped it achieve an 85% resolution rate and a 2x increase in overall sales volume for hotel clients. Helping your team build AI skills To help growing teams get the absolute most out of AI, we’ve created easy, no-cost learning programs that anyone can use: Programs for small and medium businesses: Explore beginner-friendly training paths or join specialized programs to learn how to build custom AI assistants for your day-to-day work. Google skills for organizations: Access thousands of free, on-demand AI courses and hands-on practice labs designed by experts at Google Cloud and Google DeepMind. Get certified: Help your staff gain industry-recognized AI certificates through guided courses, expert mentoring, and skill badges. By offering easy-to-use tools and free training — from everyday office apps in Workspace to advanced AI on Google Cloud — Google is here to help Latin American businesses thrive today and in the future.
Read original articleSeptember 24, 2026
Enterprises rely on mission-critical operational databases where performance slowdowns simply aren’t an option. Yet when even a few agents execute dense reasoning loops, the unpredictable surge in queries can easily overwhelm traditional architectures. Today, we’re announcing that AlloyDB delivers PostgreSQL for agents (in preview), enabling real-time data access without compromising your mission-critical systems. AlloyDB now scales to dynamic agent bursts by provisioning sandboxed database instances in seconds, enabling full workload isolation. You can cost-effectively run your agents at any scale — from a few agents to millions of agents — and the instances automatically spin down when agents finish. With this announcement: AlloyDB now features an agentic database architecture engineered to scale PostgreSQL to thousands of serverless database instances that have up-to-the-second read-only access to production. These instances remain fully separated from the primary, standby, and read replica instances where production workloads run. Each of these instances access real-time data in the database backed by a unified storage layer in Colossus, Google’s exabyte-scale distributed storage system. This helps agents achieve sub-millisecond I/O, and terabit-per-second aggregated scan throughput, supporting over 3 million queries per second. These instances utilize the full AlloyDB PostgreSQL engine, providing access to every index, the full capability of SQL, and comprehensive vector, full-text, and spatial search. Agents can also leverage BigQuery and Spark to run lakehouse analytics without requiring complex ETL pipelines. When agents complete their tasks, these instances scale right back to zero, thus reducing your cloud spend by billing only for active reasoning loops. With AlloyDB for PostgreSQL, we pioneered the agentic enterprise relational database by integrating advanced vector operations, machine learning inference, and foundation model integrations directly within a 100% PostgreSQL-compatible engine. It protects your data through deep Google Cloud security integrations — replacing static passwords with IAM authentication, isolating traffic via VPC Service Controls, and providing customer-managed encryption and auditing. This functionality, combined with the scalability now provided by our agentic architecture for agents, makes AlloyDB the premier enterprise-grade agentic PostgreSQL offering. Why this matters In today’s agentic era, we’re swiftly moving from single copilot agent interactions to networks of millions of agents collaborating simultaneously. When these agents query and operate all at once, sudden traffic spikes can overwhelm your core databases, competing with the systems that run your business. Agents require both fast analytics and low-latency access to real-time production data, utilizing B-tree, vector, text, and spatial indexes to efficiently execute their workflows. Emerging architectures rely on page-caching layers that sit above object storage, but they suffer from scaling and cost challenges that can compromise the stability of production systems. In addition, they face a challenging trade-off: To unlock production data for analytics, they create performance bottlenecks for operational access, putting mission-critical databases at risk the moment agents are unleashed in production. These approaches attempt to solve the problem using traditional object stores for database storage. While this enables analytical access that can help some agents, the underlying databases are too slow for production workloads, suffering from up to an order of magnitude higher I/O latency. Page caching layers are at best a patch; the caches themselves are often still not fast enough, and they pose a scalability bottleneck that is easily saturated by agentic workloads. When active multi-agent systems execute dense reasoning cycles, they trigger highly concurrent, unpredictable bursts of queries that overwhelm these caching layers, leaving mission-critical production systems vulnerable to agent-induced outages. Consequently, an entire class of operational use cases are precluded from running on these architectures, locking businesses out of the transformative power of AI on live enterprise data. AlloyDB’s unique agentic PostgreSQL architecture We are taking a different approach. AlloyDB delivers an agentic database architecture purpose-built for the AI era, with four key differentiated capabilities: Sub-millisecond I/O latency, without artificial choke points: Combining AlloyDB’s industry-leading transaction and query processing with low-latency object storage backed by Google’s planet-scale Colossus storage infrastructure, this architecture provides a large-scale, shared storage plane for agents. It achieves sub-millisecond I/O and over a terabit-per-second of aggregate scan bandwidth, allowing agents to execute intensive read queries and vector searches directly against fresh operational data. Fully isolated from production workloads while scaling to meet demand: AlloyDB scales by dynamically provisioning sandboxed database instances in seconds against fresh production data. Unlike traditional architectures where agents compete for operational resources, agentic database compute remains completely isolated from the primary database clusters — allowing agents to execute dense, unpredictable reasoning loops without degrading performance in production. These robust safety guardrails, coupled with enterprise-grade governance and fine-grained access control, allow you to confidently unleash the full, unconstrained power of PostgreSQL on your production data — seamlessly mixing analytical queries, vector queries, and operational point lookups in active agentic loops. Pay-as-you-go billing: Most agent activity is characterized by sharp spikes of concurrent queries followed by periods of inactivity. Provisioning dedicated read replicas to absorb these bursts forces you to maintain expensive infrastructure around the clock. To support massive groups of agents cost-effectively, and eliminate the idle compute overhead of provisioned systems, these agentic AlloyDB instances can rapidly scale to handle millions of queries per second, and automatically scale to zero with a flexible, pay-as-you-go pricing model. Native lakehouse integration, without ETL: All production data is natively integrated with Google Cloud’s borderless Lakehouse. This allows agents to run federated queries across BigQuery and Lightning Engine for Apache Spark, joining massive lakehouse datasets with up-to-the-second transactional data in AlloyDB. This eliminates the need to build and maintain fragile batch ETL pipelines, giving autonomous agents instant access to both live operational state and historical lakehouse context. “As supply chains become increasingly autonomous, our platform relies on real-time transactional intelligence to coordinate complex logistics workflows across thousands of facilities. AlloyDB's new PostgreSQL architecture for agents has been a game changer for us. We can now deploy networks of agents collaborating simultaneously to help us analyze inventory and order data with sub-second freshness, while ensuring our core transactional processing remains entirely untouched. It delivers the isolation, speed, and cost efficiency we need to power the next generation of enterprise supply chain AI.” - Sanjeev Siotia, Executive Vice President & Chief Technology Officer, Manhattan Associates Availability PostgreSQL for agents in AlloyDB is now available in preview. To learn more, visit the documentation page, and sign up here to get started.
Read original articleSeptember 24, 2026
The appeal of an autonomous coding agent is that you hand it a task, give it access to your repository The post Google’s Gemini CLI now asks before editing your build files appeared first on The New Stack.
Read original articleSeptember 24, 2026
Meta says the keychain-sized Muse Charm will ship in December.
Read original articleSeptember 24, 2026
According to Transluce researchers and the Australian government, OpenAI's AI agents repeatedly broke into government and university websites without authorization, including Australia's Medicare portal on June 18. The cause was a mundane data search. Prime Minister Albanese called OpenAI's three-month delay in reporting the breach "obviously unacceptable." Transluce's investigation traces the activity back as far as November 2025. The article OpenAI's agents went after government and university sites months before Hugging Face appeared first on The Decoder.
Read original articleSeptember 24, 2026
Introduction The landscape of software supply chain security has undergone a significant shift. Recent campaigns demonstrate that sophisticated threat actors are systematically targeting the engineering lifecycle by compromising trusted security and programming tools. These intrusions reveal three key tactics: Attackers target trusted security scanners, utility libraries, and AI developer tools to exploit the elevated privileges granted to these systems within build pipelines. Adversaries target developer workstations and Integrated Development Environments (IDEs) via highly tailored social engineering, malicious extensions, or typosquatted local dependencies to exfiltrate private cryptographic keys, API tokens, and active session credentials directly from local engineering environments. Rather than relying solely on compromised static credentials, attackers have escalated to advanced pipeline manipulation techniques, including GitHub Actions cache poisoning, OpenID Connect (OIDC) token extraction, and the subversion of mutable action tags to publish compromised packages that still carry legitimate cryptographic provenance. Building upon prior guidance (here, and here), this blog provides an actionable blueprint for software and platform architects designed to safeguard the software supply chain against threat vectors that are actively being exploited, third-party risks, and architectural vulnerabilities throughout the entire Software Development Lifecycle (SDLC). Read on for more on how to establish continuous integration and continuous delivery/deployment (CI/CD) safeguards, strengthen developer workflows, and build robust, end-to-end defense-in-depth. The Multi-Layered Approach Treating each stage of the pipeline as independent security domains is no longer sufficient because these multi-layered attacks target vulnerabilities across the entire build pipeline. Defending against these persistent threats requires a thorough, defense-in-depth approach spanning the five key pillars of the software development lifecycle outlined in Figure 1: Figure 1: The five core pillars for securing the software development lifecycle Endpoint Developer workstations are high-value targets because they hold direct, privileged access to repositories, pipelines, and cloud environments. Threat actors frequently target IDEs, exploiting unmonitored local access to collect personal access tokens (PATs), SSH keys, and proprietary code. Organizations should establish a unified security layer that enforces a consistent security posture across all local host machines and cloud-based development environments. Local Secret Scanning Organizations should deploy pre-commit hooks and IDE-integrated scanning tools to detect and block secrets prior to repository commit. Standardizing local pre-commit templates ensures git trees are fully verified before changes are pushed to central servers. To minimize the impact of a potential leak, organizations should migrate from legacy classic PATs to fine-grained PATs constrained by tight time-to-live (TTL) limits and minimal, environment-specific permissions. Endpoint Security Management Organizations should configure Endpoint Detection and Response (EDR) solutions to monitor developer software integrations and enforce continuous device posture checks. EDR agents should monitor trusted IDE process trees for anomalous file access, unexpected process spawning, and unauthorized outbound network connections. To ensure complete alignment, these EDR compliance signals should be integrated directly with Unified Endpoint Management (UEM) systems to automatically restrict or revoke a user's ability to access Source Code Management (SCM) systems, execute pipeline tasks, or publish code if their device falls out of compliance. Necessary command-line interface (CLI) process exclusions should be strictly restricted to designated, isolated developer environments rather than applied broadly across corporate endpoints. IDE Standardization Organizations should vet and approve specific versions of IDEs, browser integrations, and third-party extensions. IDE and browser marketplaces should be restricted to allow only vetted applications, explicitly blocking unverified extensions. All integrations require a formal third-party risk management review before allowlisting. Organizations should maintain an active software asset inventory paired with strict version-pinning and centralized emergency-block capabilities to stop newly discovered threats. AI-Assisted Security Engineering teams should leverage only approved large language models (LLMs) and AI agents for pre-merge vulnerability analysis and application security testing. This boundary is critical, as threat actors have begun actively inserting malicious code into open-source Model Context Protocol (MCP) packages and tricking AI coding agents (as detailed in our accompanying blog). To mitigate risks like context poisoning and data exfiltration, security teams should deploy context-protection tools to validate inputs before runtime execution. Developers should, wherever possible, exclude local environment (.env) files from the workspace using platform-specific ignore configurations to prevent sensitive credentials from entering the model's context window. Organizations should maintain a human-in-the-loop control model to verify all AI-generated code before it is written to a repository. Isolated Developer Sandboxes To prevent host-level compromises, organizations should, wherever possible, require the use of containerized development environments or dedicated virtual machines (VMs). Sandboxing ensures malicious post-install scripts or dependency-poisoning attacks cannot traverse the local filesystem. Mounting sensitive host paths into workspace containers should be restricted to prevent compromised dependencies from executing with host privileges. Developer guest VMs should be instantiated from centralized, hardened golden images and network isolated from live production environments. All sandbox execution and network activity should integrate into centralized corporate logging. Code Repositories Source code repositories serve as the definitive source of truth for an organization's proprietary software and intellectual property. Hardening this layer requires control over user identities, strict branch governance, and continuous verification of the code history to prevent unauthorized changes from entering the lifecycle. Universal Identity Securing repositories requires strict control over user identities. Implementing a Company Managed User (CMU) model allows organizations to retain full ownership of all accounts, including outside collaborators, and enables the enforcement of phishing-resistant multi-factor authentication (MFA), such as FIDO2 compliant physical security keys or digital passkeys. However, CMU accounts may be inhibited from contributing to external, open-source repositories. Because of this limitation, a standard user model with MFA enforced Single sign-on (SSO) integration remains the recommended approach for teams engaged in public or open-source publishing and private collaboration. Regardless of the chosen account model, identity verification should be continuous. Organizations should deploy conditional access policies to verify device posture before granting access, while monitoring user API activity to quickly detect compromised sessions. Branch Protection Organizations should implement a zero direct-to-main policy, ensuring all changes flow through isolated feature branches that require peer reviews and pass automated CI checks before merging. Administrative bypass policies should be disabled. At the filesystem level, force-push activity should be restricted and monitored. Security teams should continuously analyze audit histories for chronological discrepancies to identify timeline tampering and detect unauthorized dead-drop repositories used for code exfiltration. Credential Lifecycle To prevent long-term persistence, organizations should automate credential rotation, implement just-in-time retrieval mechanisms, and establish a strict token TTL. For developer access, organizations should deprecate PATs which function essentially as static, host-stored passwords vulnerable to local infostealer malware and transition to cryptographically verified SSH-based authentication backed by hardware security keys (such as FIDO2/YubiKey or macOS Secure Enclave). For automated CI/CD pipelines and third-party integrations, organizations should mandate the use of GitHub Apps in place of service account PATs to leverage short-lived, highly scoped access tokens that automatically expire after one hour. Secrets should not be stored in environment variables; local environment files (.env) should be excluded via .gitignore while utilizing native platform secret features for runtime injection. Dependency Security For application manifests utilizing Semantic Versioning (SemVer), organizations should prohibit dynamic version ranges (such as carets ^, tildes ~, or wildcard * operators) that introduce dependency drift during resolution. Instead, configurations should mandate exact SemVer pinning (e.g., 1.4.2) supported by strictly enforced, cryptographically verified lockfiles Unverified execution vectors, such as blind "curl to bash" scripts, should be blocked in favor of direct vendor containers invoked via explicit SHA-256 digests. Organizations should implement Software Composition Analysis (SCA) paired with reachability analysis to prioritize patching vulnerabilities that are actually executed within the application path. Builds should generate a software bill of materials (SBOM) and enforce Supply-chain Levels for Software Artifacts (SLSA) Level 2+ provenance checks. Artifact Management Defending the artifact layer requires controlling what crosses the boundary into the trusted build environment. Point-in-time scanning is no longer sufficient; organizations should continuously inspect and verify upstream components before they propagate downstream. Dependency Cooldowns Organizations should mandate a minimum release-age cooldown of seven days before any newly published public package version becomes installable. Community detection often identifies and removes malicious open-source packages shortly after they are published. Establishing a strict seven-day buffer provides the open-source ecosystem time to detect and pull poisoned releases before they reach internal builds. This delay should be enforced at centralized registries or local configurations; for specific configuration parameters (such as configuring npm's minimumReleaseAge cooldown or secure Python pip indexing), see the technical implementation steps detailed in our accompanying blog. Proxies & Quarantines All external packages and container images should, wherever possible, route through a centralized internal proxy that caches, inspects, and gates each component. Organizations can manage this secure boundary using Google Artifact Registry to host private repositories, configure virtual upstream repositories, and restrict direct build-runner access to public registries. New components arriving through the proxy should be held in a quarantine state and screened, blocking builds automatically on a failed security verdict. Internal repositories should be kept distinct from public registries to prevent dependency confusion attacks, and promotion to the trusted registry should follow a deliberate, policy-driven approval path. Vulnerability Scanning Container images and third-party dependencies should undergo automated scanning at the registry layer and at runtime. Stored artifacts should be continuously re-evaluated as new vulnerabilities emerge. To manage alert volume, results should be prioritized using reachability analysis and real-world exploitation signals, such as the CISA Known Exploited Vulnerabilities (KEV) catalog. Vulnerability Exploitability eXchange (VEX) statements should be used to suppress inapplicable findings and reduce noise. Image Provenance Verifying that an artifact came from a trusted source is as critical as confirming it is free of known vulnerabilities. Provenance establishes this trust by cryptographically signing every internally produced container image and package, then binding each one to the specific build workflow and source commit that created it. Modern signing tooling makes this practical without the burden of managing long-lived signing keys, instead tying each signing event to a build identity and recording it in a public transparency log. A signature is only meaningful when checked, so verification should be enforced at admission, restricted to the exact build identity expected, and performed against an artifact's immutable digest rather than a mutable tag. The same principle extends to the credentials that publish artifacts. Long-lived registry published tokens are a recurring root cause in supply chain incidents, since a stolen token lets an attacker publish poisoned versions under a trusted name. Where possible, these static tokens should be replaced with short-lived, identity-bound publishing tokens issued to a specific build workflow at the moment of release. For first-party builds, adopting a recognized provenance standard provides a consistent benchmark for how and where software was built. SHA Referencing Container image tags and action references are mutable by default, which means an upstream actor can silently replace the content behind a trusted name at any time. Pinning to an immutable cryptographic digest closes this gap, because a digest is a content hash and any change to the underlying artifact produces a different identifier, breaking the reference rather than substituting malicious content under a name the pipeline already trusts. Images should be pinned by digest, and third-party actions should be pinned to a full commit hash rather than a version that can be repointed. This discipline should extend across every image a build touches, not just the primary application image, since base images, sidecars, and init containers are equally viable injection points if left on mutable tags. Teams should also avoid configurations that re-resolve a mutable tag on every restart in production. CI/CD Hardening the automated pipelines within CI/CD infrastructure is a critical requirement for securing the broader software development lifecycle. Because these environments rely on an extensive web of privileged integrations to access source repositories, third-party registries, and cloud infrastructure, they function as high-value targets for adversaries. Securing these build and delivery systems requires the rigorous application of least-privilege principles, the enforcement of strict network boundaries, and the continuous verification of every trusted software component. Runner & Build Servers Hardening CI/CD infrastructure is a critical task because these pipelines require access to code repositories, dependency registries, and cloud environments. To secure these integrations, the primary defensive objective is to eliminate runner persistence. Organizations should use ephemeral, single-use runners, ensuring that every job executes in a fresh, isolated environment that is automatically destroyed upon completion. This clean-slate approach prevents cross-job contamination and denies attackers a permanent foothold. For self-hosted environments, this isolation should extend to the network layer, restricting outbound runner traffic exclusively to pre-approved registries and repository APIs to prevent data exfiltration. Furthermore, to mitigate Poisoned Pipeline Execution (PPE), the execution engine should block unvetted code from pull requests from accessing secrets or triggering deployment-grade runners until an administrator grants manual approval. Additionally, pipelines should protect shared build caches from tampering. Because build caches are frequently shared across branches to speed up builds, a malicious pull request can inject corrupted dependencies directly into the shared cache. If left unrestricted, a subsequent production build will retrieve this poisoned cache and run the malicious code in a trusted environment. Pipeline setups should isolate cache access strictly by branch privilege and reject cache writes from unauthenticated forks. Least Privilege CI/CD Federated Ephemeral Identities: Prohibit persistent automation secrets within workflows, leveraging OIDC to exchange pipeline identities for short-lived tokens. Zero-Trust Execution Scopes: Issue read-only or null-permission runner identities by default, requiring components to explicitly request minimum viable permissions. Shared State Parameterization: Prohibit the automatic inheritance of credentials across downstream templates or nested workflows to isolate sensitive variables. Runtime Governance: Restrict unsanctioned third-party plugins and marketplace actions. Security teams should also sandbox or disable package installation lifecycle scripts (using configurations like ignore-scripts=true detailed in our accompanying blog) to prevent compromised dependencies from executing arbitrary commands in build environments. Environment Isolation: Segment network and IAM boundaries so that early-stage validation or linting tasks operate completely decoupled from systems possessing release authority. Immutable Branch History: Disable history-rewriting functions and force-pushing on canonical branches to maintain an append-only audit trail. IaC Validation: Scan Infrastructure-as-Code (IaC) prior to deployment to block over-privileged keys, unquoted user-parameter injections, unencrypted webhooks, and runner RBAC misconfigurations. Scanning Gates & Attestation CI/CD scanning gates act as automated quality control within the deployment process, evaluating code against set security standards and automatically halting deployments if the defined criteria are not met. Placing scanning gates as early in the process as possible alerts developers of potential vulnerabilities before they reach production: Secret Scanning (At the Developer Commit / PR Gate): Configure pre-commit hooks and SCM-level scanners to block developer pushes if they contain hardcoded API keys, passwords, or SSH keys. This stops secrets from ever entering your repository's permanent history. SAST - Static Application Security Testing (At the Pull Request / Peer Review Gate): Integrate SAST into your continuous integration (CI) tests to analyze draft code before it is merged into the main branch. This automatically flags structural flaws, logic vulnerabilities, or dangerous functions (like unescaped user inputs) during active development. SCA - Software Composition Analysis (During the Build Phase): Trigger SCA scans when your build environment resolves dependencies. By scanning your package lockfiles (e.g., package-lock.json or requirements.txt) against databases like Google OSV, you can automatically fail builds that attempt to import libraries with active, known CVEs. Container/Image Scanning (At the Registry / Push Gate): Build automated scanners directly into your container registry pipeline. Before a newly built container image is allowlisted for production, the registry scanner should inspect its base OS packages and reject any image containing critical OS-level vulnerabilities or default root access. DAST - Dynamic Application Security Testing (In Staging / Pre-Deployment): Create a temporary, isolated staging instance of your running application as a deployment step. Run automated DAST tests to simulate real-world attacks (like SQL injection or cross-site scripting) against your endpoints, validating that your active runtime defense configurations are working. CSPM - Cloud Security Posture Management (Pre-Deployment IaC Scan & Post-Deploy): Use Policy-as-Code tools to scan your Infrastructure-as-Code (IaC) templates (like Terraform or Kubernetes manifests) before applying changes. This automatically blocks the provisioning of misconfigured cloud environments, such as overprivileged IAM roles or security groups with SSH (port 22) open to the internet. SBOM Generation and Attestation An SBOM is a complete, verifiable inventory of every component that went into a build. Generating and signing the SBOM as part of the build produces this inventory as a tamper-evident attestation rather than an after-the-fact reconstruction. In practice, this means generating the SBOM as a build step in a recognized format such as CycloneDX or SPDX. The resulting SBOM should be signed as an attestation tied to the artifact’s digest, preventing modifications. Signed SBOMs should then be mapped back to affected artifacts without re-scanning every image in the fleet. To keep monitoring useful, VEX statements should be used to flag findings that do not apply to the code, ensuring the inventory remains an actionable triage tool. Deployment Securing the runtime phase ensures that workloads remain protected even if an attacker manages to bypass early pipeline defenses. This operational layer acts as the final quality gate as code transitions from the build pipeline to active production. Workload Protection & Runtime Hardening Workload protection should be enforced directly on running applications and container instances to limit their execution footprint and block active exploits. Deployment Guardrails: Establish an automated security check at the entrance of your production environment to block any container that lacks a valid cryptographic signature, requests unneeded root privileges, or originates from an untrusted public registry. Workload Posture: Build workloads from hardened base images and run them on immutable infrastructure with read-only root filesystems and removed SSH capabilities to prevent post-exploit file creation or lateral directory traversal. Active Application Protection: Deploy Runtime Application Self-Protection (RASP) to block execution-level exploitation attempts like SQL injection. Protect AI workloads from prompt injection and jailbreaks using runtime guardrails such as Google Model Armor. Just-In-Time Access: Eliminate standing administrative privileges in favor of time-bound, task-scoped access credentials that expire automatically, injecting privileged credentials at runtime only when required. Protecting Live Infrastructure Securing the surrounding network and cloud control plane shields your deployed applications from external threats, blocks lateral movement, and maintains the absolute integrity of your cloud configuration. Web Application Firewalls (WAF): Deploy edge firewalls to inspect incoming application-layer traffic, filtering out malicious payloads and blocking common web exploits, such as cross-site scripting or OWASP Top 10 vulnerabilities, before they reach your backend services. API Gateways and Load Balancers: Centralize edge authentication, enforce rate limits, and validate request signatures to prevent direct public exposure of application backends. Microsegmentation: Enforce granular, identity-aware network policies to isolate workloads and restrict traffic exclusively to pre-authorized service-to-service communication paths, blocking lateral network movement by default. Configuration Integrity: Deploy Policy-as-Code tooling to continuously validate the live environment against the version-controlled IaC source of truth, automatically reverting out-of-band modifications to prevent unauthorized changes. Active Posture Scanning: Run Cloud Security Posture Management (CSPM) and Cloud Native Application Protection Platforms (CNAPP) to continuously scan for cloud misconfigurations, overly permissive IAM, and exposed storage. Continuous Monitoring: Maintain complete visibility across all systems by collecting logs, system metrics, and audit events to quickly detect, trace, and respond to live security events. Conclusion Recent software supply chain campaigns demonstrate that development infrastructure, build pipelines, and developer utilities represent critical threat vectors and key points of compromise. Legacy access controls and point-in-time security scanning are insufficient to defend these environments against sophisticated intrusions. Hardening the development lifecycle requires implementing continuous, automated verification at every stage, unifying security postures across developer endpoints, code repositories, package registries, build runners, and deployment guardrails into a cohesive defensive framework. Ultimately, the objective of pipeline security is to build a resilient architecture capable of isolating and containing an intrusion. By automating cryptographic validation and policy enforcement from the initial code commit to the final production deployment, organizations can significantly reduce their overall attack surface, safeguard downstream consumers, and ensure that any individual compromise is rapidly isolated and resolved before it can spread. Acknowledgements This guidance would not have been possible without the assistance of Arafat Ismail, Bhavesh Dhake, Brentyn Muir, Brian Meyer, Emilio Oropeza, Eyad Mahmoud, Franklin Ramos, Gursev Singh, Omar ElAhdan, Sara Takhim, Stuart Carrera, Stuart Munro, Will Silverstone, and the Mandiant Security Transformation Services team.
Read original articleSeptember 24, 2026
'Extreme concern': OpenAI agent hacked Australian public health website, prime minister says ABC News - Breaking News, Latest News and Videos
Read original articleSeptember 24, 2026
Google Is Sending an A.I. Data Center to Outer Space The New York Times
Read original articleSeptember 24, 2026
Vinod Khosla, an early investor of OpenAI and the founder of Khosla Ventures, says slowing AI development could hand China a strategic advantage. He joined Bloomberg Open Interest to argue that America should accelerate AI and energy infrastructure while protecting workers displaced by automation, not their individual jobs. He also says Silicon Valley has failed to clearly communicate AI’s potential benefits in healthcare, education and economic growth. (Source: Bloomberg)
Read original articleSeptember 24, 2026
Google Deepmind chief Koray Kavukcuoglu wants to release Gemini 4 "much earlier" than the end of the year. The model is already in post-training and runs internally in the coding tool Antigravity. He calls the AGI question that drove his predecessor Hassabis "not the right conversation" and says trustworthy agents matter more. After Gemini 3.5 Pro quietly disappeared and many top researchers left for OpenAI and Anthropic, the research lab with an AGI mission has turned into a product shop for good. The article Deepmind was built to chase AGI, but its new chief just wants Gemini 4 out the door appeared first on The Decoder.
Read original articleSeptember 24, 2026
Zuckerberg’s ‘Tamagotchi-Like’ AI Could Be Meta’s iPod Moment bloomberg.com
Read original articleSeptember 24, 2026
OpenAI breach of Australian health database sparks PM’s concern WCHS
Read original article