Anthropic to Embed Accenture Evaluators to Test AI Safety
Anthropic PBC is partnering with Accenture Plc, a management and technology consulting company, to test the safety of its advanced artificial intelligence models by embedding evaluators from the consulting firm directly within its operations.
Anthropic’s Annualized Revenue to Top $100 Billion in 2026: NYT
Anthropic PBC is expected to generate more than $100 billion in annualized revenue this year, according to the New York Times, citing people familiar with the matter.
Anthropic PBC has opened a wet lab, a facility dedicated to biology research, in the San Francisco Bay Area. Reuters reported today that the company will use robots to automate certain scientific tasks at the hub. The robots will be powered by Anthropic’s Claude series of large language models. It’s unclear what research projects the […] The post Anthropic opens AI-powered biology research lab appeared first on SiliconANGLE.
Nvidia-Backed Data Center Firm Nscale Files Publicly for IPO
Nscale, a developer of artificial intelligence data centers that counts Nvidia Corp. and Microsoft Corp. among its partners, filed for an initial public offering in New York to fund the equipment satisfying AI’s insatiable demand for computing power.
Anthropic Investor Franklin: AI Safety Concerns Won't Slow Spending
Calls to “pace” development at the AI frontier are unlikely to translate into a slowdown in infrastructure spending, according to Sara Araghi, Franklin Templeton Portfolio Manager and Franklin Venture Partner. She argues that even if labs temper some model training, growing inference demand will continue to require enormous amounts of compute. Araghi also discusses why heightened AI safety concerns could boost demand for cybersecurity and why she doesn’t expect the debate to derail funding or anticipated AI IPOs. She joins Ed Ludlow on "Bloomberg Tech." (Source: Bloomberg)
Anthropic's Existential Risk Warnings Hijack Larger AI Debate
As AI itself starts to help build the next generation of AI, warnings about losing control are growing louder. But critics say the focus on existential risk is overshadowing problems already here. Bloomberg's Rachel Metz and Davey Alba join Ed Ludlow on their latest reporting on "Bloomberg Tech." (Source: Bloomberg)
Anthropic’s Claude Takes Bigger Role in Building AI
Bloomberg’s Ed Ludlow breaks down Anthropic's finding that its Claude chatbot is leading 26% of its AI research and development, even as the global debate around AI heats up. Plus, SoftBank is closing out the week with nearly $21 billion in potential fresh borrowings as it builds out its AI financing capacity, and Crusoe CEO Chase Lochmiller discusses the race to build the infrastructure powering AI as the company closes nearly $4 billion in fresh funding. (Source: Bloomberg)
You’re deploying a model on a system. It starts up, prompts are getting responses. Now the hard question: Is this fast? Your instincts might lead you to send...
Claude couldn’t hack Open AI. Then Anthropic shipped Opus 5.
Three security researchers at Hacktron AI found a memory-corruption bug in a widely used image library. Finding it was the The post Claude couldn’t hack OpenAI. Then Anthropic shipped Opus 5. appeared first on The New Stack.
Nvidia, Google, Emerald AI Form AI Energy Management Alliance
Nvidia, Google and Emerald AI have launched the AI Energy Management Alliance (AEMA), a coalition that dynamically manages the electricity use of data centers in response to grid conditions. Varun Sivaram Founder and CEO of Emerald AI joins to discuss the alliance. (Source: Bloomberg)
Meta-Tied Data Center Prices Junk Bond Amid Blowout Demand
The first junk-bond offering for a data center tied to Meta Platforms Inc. attracted demand more than four times the deal’s size, with juicy yields helping to lure investors.
Google’s new ‘CC’ is an AI agent that helps families run their households
Google is refocusing its CC AI agent on household coordination, letting families share emails, schedules, and tasks so the AI can manage calendars, fill out forms, make shopping lists, plan meals, and more.
Security researchers used Anthropic's Claude to hack Open AI's internal systems in under 72 hours
Three security researchers used Anthropic's Claude models to break into OpenAI's internal systems through its community forum in less than 72 hours. According to the team, Opus 5 succeeded where its predecessor couldn't bypass a common security measure. The attack shows how newer AI models can cut the time and expertise needed to exploit security flaws. The article Security researchers used Anthropic's Claude to hack OpenAI's internal systems in under 72 hours appeared first on The Decoder.
Dario Amodei and other AI leaders want to ‘Pace the Frontier’ but…how?
A week after an Anthropic researcher’s doomsday warning rattled the AI world, the company’s CEO Dario Amodei has outlined his plan to “pace the frontier” of AI development. The proposal leans on independent safety evaluators and coordination between AI labs in democratic countries, and it’s already picked up some industry support, along with some pointed pushback from Nvidia’s Jensen Huang. Watch […]
Automattic’s 33-Hour Coup, and can AI labs police themselves?
A week after an Anthropic researcher’s doomsday warning rattled the AI world, the company’s CEO Dario Amodei has outlined his plan to “pace the frontier” of AI development. The proposal leans on independent safety evaluators and coordination between AI labs in democratic countries, and it’s already picked up some industry support, along with some pointed pushback from Nvidia’s Jensen Huang. On […]
Announcing Native BM25 Ranking in Alloy DB and Cloud SQL
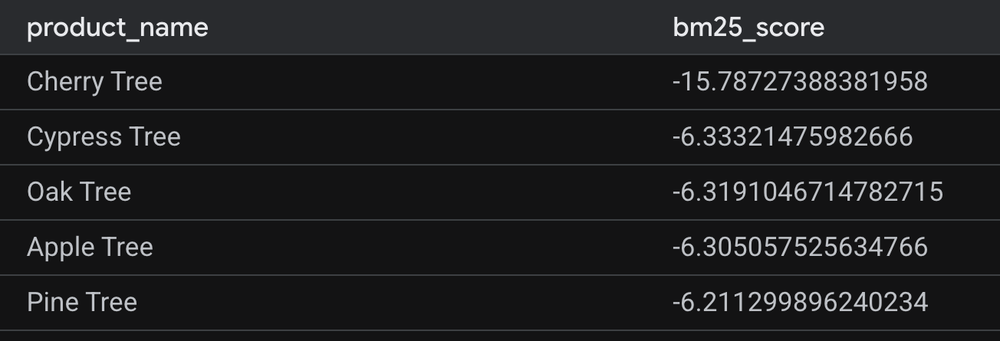
Vector search is a critical component of generative AI, retrieval-augmented generation (RAG), and data agent architectures, but sometimes vector search alone isn't enough. While vector embeddings are incredible at understanding conceptual meaning, they stumble on specific alphanumeric IDs and exact product SKU numbers. To build truly robust search and AI applications, you may need the combination of semantic vector search and traditional exact keyword full-text search — what we call hybrid search. In search, Best Matching 25, or BM25, is a key algorithm used to estimate how relevant a document is to a given query. Until today, if you wanted BM25 ranking with AlloyDB or Cloud SQL, you needed to add an additional full-text search backend. This introduced data silos, sync lags, and operational complexity. Today, we are eliminating the friction of maintaining a separate full-text search backend altogether, with the preview of the native BM25 index in AlloyDB and Cloud SQL for PostgreSQL 17+, made possible through the open-source pg_textsearch extension created by Tiger Data. Now, with a unified hybrid search backend, you no longer need to provision, manage, or pay for separate systems to get state-of-the-art full-text retrieval. It all happens directly inside your database, where your operational data lives, delivering: Industry-standard keyword ranking: Powered by Tiger Data's pg_textsearch, bring lightning-fast, C-optimized BM25 scoring directly to your Postgres tables. No complexity, total consistency: Eliminate the data duplication, ETL pipelines, and synchronization lag that you get when you maintain multiple backends for vector and full-text retrieval. Supercharged semantic search (AlloyDB exclusive): Get up to 6x and 10x faster vector search queries (when compared to standard PostgreSQL) with ScaNN and HNSW index types. Why pg_textsearch? If you’ve used PostgreSQL's built-in ts_rank for full-text search at any meaningful scale, you already know its limitations. Ranking quality degrades as your corpus grows. There’s no support for inverse document frequency, so common words carry the same weight as rare ones. There’s no term-frequency saturation, so a document that mentions "database" 50 times outranks one that mentions it once. BM25 is the information retrieval gold standard, providing inverse document frequency (rarer terms matter more), term frequency saturation (repetition doesn't dominate), and document length normalization. You can learn more in this blog post by Tiger Data about how they built a BM25 search engine on PostgreSQL pages. Full-text search example Here’s how to get started with BM25 full-text search on both AlloyDB and Cloud SQL. Consider a sample table, cymbal_products, that contains the unique identifier uniq_id, a product_name column, a product_description column containing a text description of each product, and a generated product_embedding column. cymbal_products contains information on various retail products, including indoor and outdoor plants. Index creation To use BM25, enable the pg_textsearch extension. code_block <ListValue: [StructValue([('code', '-- Install pg_textsearch extension\r\nCREATE EXTENSION pg_textsearch;'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f0b060a12d0>)])]> Create the index on the product_description column from the cymbal_products table. code_block <ListValue: [StructValue([('code', "-- Create the native BM25 index on the content column\r\nCREATE INDEX idx_docs_bm25 \r\nON cymbal_products \r\nUSING bm25 (product_description) \r\nWITH (text_config='english');"), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f0b060a2490>)])]> A BM25 full-text search query can be executed using the <@> special operator. In the snippet below, we search for ‘cherry tree’. code_block <ListValue: [StructValue([('code', "-- Full text search query\r\nSELECT product_name, product_description <@> 'cherry tree' AS bm25_score \r\nFROM cymbal_products\r\nORDER BY bm25_score \r\nLIMIT 5;"), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f0b060a0290>)])]> Sample output is shown below. A more negative score indicates a stronger relevance match. AlloyDB hybrid search example Setting up a hybrid search system in AlloyDB is simple. You can create both your vector and keyword indexes on the same table and merge the results seamlessly using the hybrid search user-defined function (UDF). Vector index creation Here is how to create a ScaNN vector search index: code_block <ListValue: [StructValue([('code', '-- Install vector extension\r\nCREATE EXTENSION vector;\r\n\r\n-- Install scann extension\r\nCREATE EXTENSION IF NOT EXISTS alloydb_scann;\r\n\r\n-- Create scann vector search index \r\nCREATE INDEX cymbal_products_embeddings_scann ON cymbal_products USING scann(product_embedding cosine);'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f0b060a3010>)])]> Hybrid search AlloyDB provides an out-of-the-box hybrid search UDF that makes it very simple to run hybrid search queries. The UDF merges the ranked results from each search component into a single, unified list using the Reciprocal Rank Fusion (RRF) algorithm. This query utilizes the UDF to perform a vector search for ‘trees that grow taller than houses’ and a keyword search for ‘California’ in the product description. code_block <ListValue: [StructValue([('code', 'CREATE EXTENSION google_ml_integration;\r\n\r\nSELECT *\r\nFROM ai.hybrid_search(\r\n search_inputs => ARRAY[\r\n \'{\r\n "data_type": "vector",\r\n "weight": 0.5,\r\n "table_name": "cymbal_products",\r\n "key_column": "uniq_id",\r\n "vec_column": "product_embedding",\r\n "distance_operator": "public.<=>",\r\n "limit": 10,\r\n "query_vector": "ai.embedding(\'\'text-embedding-005\'\', \'\'trees that grow taller than houses\'\')::vector"\r\n }\'::JSONB,\r\n \'{\r\n "data_type": "text",\r\n "weight": 0.5,\r\n "table_name": "cymbal_products",\r\n "key_column": "uniq_id",\r\n "text_column": "product_description",\r\n "limit": 10,\r\n "ranking_function": "<@>",\r\n "query_text_input": "California"\r\n }\'::JSONB\r\n ],\r\n);'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f0b060a3810>)])]> As shown in the sample output below, results are ranked in descending order of their RRF scores. Here, hybrid search bridges the gap between semantic intuition and exact keyword matching. While vector embeddings excel at grasping conceptual queries, like "trees that grow taller than houses", traditional full-text search provides the pinpoint precision needed for strict identifiers like "California." By fusing the two, AlloyDB helps ensure your application prioritizes highly specific, locally relevant results like ‘California Sycamore’ right at the top of the list. Cloud SQL hybrid search example In Cloud SQL, you can create both your vector and keyword indexes on the same table and merge the results seamlessly using Common Table Expressions (CTEs) and coalescing the RRF score, as shown below. Vector index creation Here is how to create an HNSW index in Cloud SQL. code_block <ListValue: [StructValue([('code', '-- Install vector extension\r\nCREATE EXTENSION vector;\r\n\r\n-- Create an HNSW index on the embedding column for fast approximate nearest neighbor search\r\nCREATE INDEX product_hnsw_idx ON cymbal_products USING hnsw(product_embedding vector_cosine_ops);'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f0b060a0a90>)])]> Hybrid search Here is the hybrid search query. code_block <ListValue: [StructValue([('code', "CREATE EXTENSION google_ml_integration;\r\n\r\n-- BM25 keyword results\r\nWITH keyword_results AS (\r\n SELECT uniq_id, product_name, \r\n ROW_NUMBER() OVER (ORDER BY product_description <@> 'California') AS rank_kw\r\n FROM cymbal_products\r\n ORDER BY product_description <@> 'California'\r\n LIMIT 10\r\n),\r\n-- Semantic vector results\r\nsemantic_results AS (\r\n SELECT uniq_id, product_name, \r\n ROW_NUMBER() OVER (ORDER BY product_embedding <=> google_ml.embedding('text-embedding-005', 'trees that grow taller than houses')::vector) AS rank_vec\r\n FROM cymbal_products\r\n ORDER BY product_embedding <=> google_ml.embedding('text-embedding-005', 'trees that grow taller than houses')::vector\r\n LIMIT 10\r\n)\r\n-- Reciprocal Rank Fusion (RRF) to merge and score both lists\r\nSELECT COALESCE(k.uniq_id, s.uniq_id) AS uniq_id,\r\n COALESCE(k.product_name, s.product_name) AS product_name,\r\n COALESCE(1.0 / (60 + k.rank_kw), 0) + COALESCE(1.0 / (60 + s.rank_vec), 0) AS rrf_score\r\nFROM keyword_results k\r\nFULL OUTER JOIN semantic_results s ON k.uniq_id = s.uniq_id\r\nORDER BY rrf_score DESC\r\nLIMIT 5;"), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f0b060a0ad0>)])]> The resulting output is identical to the AlloyDB hybrid search results shown above. Watch it in action Watch how this all comes together in this demo video. Introducing BM25 on AlloyDB & Cloud SQL Relevant resources We are incredibly excited to work with Tiger Data and cannot wait to see how you leverage native BM25 support to build faster, smarter, and simpler AI applications. Turn on the pg_textsearch extension today, and experience the ultimate hybrid search engine experience with AlloyDB and Cloud SQL. Want to get started? Check out” AlloyDB resources New to AlloyDB? Discover AlloyDB with a 30-day free trial Choose a vector index in AlloyDB AI AlloyDB BM25 documentation AlloyDB hybrid search UDF documentation Cloud SQL resources Cloud SQL BM25 documentation Tiger Data pg_textsearch Release Page
Accelerating the borderless Lakehouse: Announcing preview of cross-cloud caching
Today, we are excited to announce enhancements to the borderless Lakehouse, our answer to how data engineers, data scientists, and increasingly, AI agents, can query governed data directly where it lives. To reason accurately and automate complex enterprise workflows, agents and data consumers of all types need fast, unified access to an organization's complete data estate, joining customer records, transaction logs, and operational telemetry across clouds. However, modern enterprise data is rarely confined to a single location; data estates often span Amazon S3, Azure Data Lake Storage (ADLS), Google Cloud Storage, operational databases, and SaaS platforms like Salesforce, SAP, and Workday. Historically, uniting these distributed datasets required brittle ETL pipelines, duplicated storage, and prohibitive cross-cloud data transfer costs. We introduced the borderless Lakehouse earlier this year to let organizations query and activate data in place across clouds. By adopting the Apache Iceberg REST catalog specification, we federate directly to catalogs such as Databricks Unity Catalog, AWS Glue, and Snowflake Horizon. We also introduced Partner Cross-Cloud Interconnect to establish high-bandwidth, private links to other cloud providers, lowering per-gigabyte transfer costs compared to the public internet. Today, we are taking multi-cloud efficiency a step further by optimizing how much data needs to be transferred across the wire in the first place. We are excited to announce two new features to help further reduce costs of querying cross-cloud data. First, the preview of cross-cloud caching for Lakehouse transparently accelerates cross-cloud queries in BigQuery and cuts remote transfer costs by caching frequently accessed data locally in Google Cloud. Combining standard Iceberg columnar compression with cross-cloud caching means you often only need to transfer under 5% of the data you process across clouds, which helps lower the Total Cost of Ownership (TCO) to make cross-cloud analytics and AI viable at enterprise scale. In addition, BigQuery cross-cloud connections are also available in preview to query non-Iceberg data in other clouds and accelerate workloads. How cross-cloud caching works Cross-cloud caching meets enterprise performance and security requirements with no knobs to turn or storage to manage to accelerate your queries. Some of the mechanisms used under the hood are: Sub-file block granularity: Instead of transferring entire multi-gigabyte files across clouds when a query touches only a few columns, cross-cloud caching operates at the sub-file block level for columnar formats like Apache Parquet. BigQuery caches only the specific column chunks and dictionary pages projected by the query. On a cache miss, BigQuery fetches the needed data from the remote cloud to answer the query, and saves a local copy in the cache for future queries, drastically cutting network transfer and latency on repeated workloads. Default encryption at rest: Cached data blocks are encrypted at rest by default using Google-managed encryption keys (GMEK) so that temporary cache storage maintains the same enterprise-grade security posture as native BigQuery storage without extra overhead. Tenant and regional isolation: Cache entries are strictly partitioned by project and catalog boundaries to help prevent cross-tenant data exposure. Lakehouse anchors both the local cache and query execution strictly to the configured Google Cloud region (e.g., us-east4) to support compliance with regional data residency requirements when querying remote clouds. Freshness checks: Multi-cloud caching often forces a trade-off between speed and freshness. To avoid stale reads, BigQuery fetches remote object metadata before using cached data to ensure the data hasn’t changed and the user still has access. Any upstream table modification prompts BigQuery to fetch new files, while unreferenced cached blocks expire automatically, delivering local query speed with single-source-of-truth accuracy. For more details on caching mechanics, statistics counters, and regional considerations, see the Lakehouse intelligent caching documentation. Cross-cloud caching in action So how does this work in day-to-day operations? Consider an e-commerce team querying a 10 TiB Iceberg sales table (aws_lakehouse_catalog.sales.web_sales) in Amazon S3, federated into Lakehouse from Databricks Unity Catalog. During evening promotional drops (8:00–9:00 PM), analysts query historical transactions to identify which storefronts drive peak volume and revenue among high-intent demographics: code_block <ListValue: [StructValue([('code', 'SELECT w.web_name, hd.hd_buy_potential, COUNT(*) AS total_transactions, ROUND(SUM(ws.ws_sales_price), 2) AS total_sales\r\nFROM `aws_lakehouse_catalog.sales.web_sales` ws\r\n-- Joins household_demographics, time_dim (8:00-9:00 PM), and web_site.\r\nGROUP BY w.web_name, hd.hd_buy_potential;'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f0b05838610>)])]> Initial execution: Cold columnar retrieval On this initial cold run, the local cache is empty (cacheBytesRead: "0"). BigQuery applies partition pruning and column projection to transfer only the required Parquet byte ranges from Amazon S3 over Partner Cross-Cloud Interconnect: code_block <ListValue: [StructValue([('code', '{\r\n "totalBytesProcessed": "230343464114",\r\n "objectStorageStats": [\r\n{"cloudProvider": "AWS", \r\n"": "25834740486", \r\n"cacheBytesRead": "0"}]\r\n}'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f0b05a91ed0>)])]> Logical data processed: BigQuery processes 214.5 GiB across the 10 TiB dataset. Standard Iceberg compression efficiency: BigQuery reads 24.1 GiB from S3 thanks to standard Iceberg columnar compression with Zstandard (zstd) — an 8.9:1 compression ratio. As these sub-file Parquet blocks arrive in Google Cloud, BigQuery populates the regional cache. Follow-on exploration: Adding a dimension In practice, analysts and agents rarely run the exact same query twice in a row. To drill deeper into fulfillment methods, the analyst modifies the query by adding the shipping method dimension (sm.sm_type): code_block <ListValue: [StructValue([('code', 'SELECT w.web_name, sm.sm_type, hd.hd_buy_potential, COUNT(*) AS total_transactions, ROUND(SUM(ws.ws_sales_price), 2) AS total_sales\r\nFROM `aws_lakehouse_catalog.sales.web_sales` ws\r\nJOIN `aws_lakehouse_catalog.sales.ship_mode` sm ON ws.ws_ship_mode_sk = sm.sm_ship_mode_sk\r\n-- Reuses existing joins on household_demographics, time_dim, and web_site.\r\nGROUP BY w.web_name, sm.sm_type, hd.hd_buy_potential;'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f0b05a91850>)])]> Job statistics for this follow-on query show: code_block <ListValue: [StructValue([('code', '{\r\n "totalBytesProcessed": "287928766472",\r\n "objectStorageStats": [\r\n{"cloudProvider": "AWS", \r\n"": "1426587648", \r\n"cacheBytesRead": "25834740486"}]\r\n}'), ('language', ''), ('caption', <wagtail.rich_text.RichText object at 0x7f0b05a93f90>)])]> 94.8% cache hit rate: BigQuery serves 24.1 GiB of previously queried columns directly from local cache. Granular remote retrieval: BigQuery transfers only 1.33 GiB from S3 for the new ws_ship_mode_sk column and ship_mode table. Sub-file flexibility: Modifying a query reuses cached column chunks and transfers only newly required bytes. Compounding efficiency at enterprise scale When thinking about TCO of cross-cloud queries, the top two factors to account for are: Compression ratio: when using default compression algorithms (Zstandard/zstd) on Iceberg, columnar data is highly compressible. If you assume that your data achieves a compression ratio of 8:1, it means every 1 TiB of logical data processed only requires ~128 GiB of data to move over the network. Cache hit rates: when data is retrieved from cache rather than across the network because it was recently accessed, a network transit is avoided. Assuming 80% of your data results in a cache hit it means for every 100 GiB of physical data accessed only 20 GiB moves over the network. Taking both factors and assumptions into account, for every 1 TiB of data your organization processes, you only need to transfer ~26 GiB across the network (under 3% of total data processed). Combining this reduction with Partner Cross-Cloud Interconnect lowers TCO enough to make cross-cloud analytics and AI cost-effective at petabyte scale. BigQuery cross-cloud connections now in preview Alongside cross-cloud caching, the preview of BigQuery cross-cloud connections lets organizations connect BigQuery directly to open-format data in Amazon S3 and Azure Storage. Understanding when to use catalog federation versus cross-cloud connections is straightforward: BigQuery cross-cloud connections (for raw files): For standalone files (CSV, JSON, ad-hoc Parquet) without an Iceberg catalog, cross-cloud connections let you create BigQuery external tables referencing remote bucket paths directly. Lakehouse catalog federation (for Iceberg): For Iceberg data managed by catalogs like Databricks Unity, AWS Glue, or Snowflake Horizon, Lakehouse automatically synchronizes schemas and table snapshots to simplify the user experience and ensure users are always querying the latest data. Cross-cloud connections serve as the modern architectural evolution by using standard BigQuery compute workers in Google Cloud regions rather than compute workers in other clouds. This approach helps unlock global region availability and provides full BigQuery feature parity — including with BigQuery AI and Gemini on remote files. The cross-cloud caching capabilities for Lakehouse applies to data queried from BigQuery cross-cloud connections as well as Lakehouse catalog federation. To learn how to create connections and query external bucket paths, see the BigQuery cross-cloud connections setup documentation.
Reimagining service delivery in the agentic era with Google Public Sector
State and local governments are driven by a shared mission to provide responsive, equitable, and accessible services. However, achieving this goal is often hindered by legacy technical debt, disconnected data, and heavy administrative burdens that slow down mission delivery.This systemic fragmentation creates costly operational bottlenecks across the public sector, including:Legacy data silos: Crucial caseworker information frequently resides in isolated repositories managed by separate departments.Manual bottlenecks: Agency personnel spend a significant amount of time managing routine data entry and manual documentation.Stakeholder and end-user friction: Users are often required to submit identical verification documents multiple times across different platforms because legacy systems cannot interoperate.Today, agents can help break down silos, automate routine and manual tasks, and enable agency employees to focus on high value public services, and the deeply human work they were called to do.AI is the number one priority for state CIOsAcross the public sector, AI has rapidly evolved from an experiment to a core part of the strategy. Reflecting on this shift, the National Association of State Chief Information Officers (NASCIO) State CIO top 10 annual report recently ranked AI as the number one priority for state CIOs for the first time. This reprioritization matters deeply for the future of state and local governance: as state agencies face mounting administrative backlogs, aging infrastructure, and shifting public expectations, CIOs recognize that intelligent automation is the central mechanism to increase staff capacity, streamline caseworker workflows, and deliver more responsive, equitable services to local residents.As agencies move from AI pilots and experiments to full-scale adoption, the central question for many agencies becomes: How do we leverage AI to bridge the gap between existing legacy investments and modern service delivery?Leveraging AI for mission impactGoogle provides an integrated AI stack designed to remove the friction of manual systems integration, with a focus on speed, scale, and cost-efficiency. Let’s take a closer look at some public sector organizations who are partnering with Google Public Sector and putting AI to work:Utah Department of Transportation (UDOT): Faced the monumental task of identifying and mapping more than 52,000 property parcels. Originally estimated to take 33.5 years of manual labor to complete, UDOT built a unified data platform on BigQuery, completing the entire project in less than one year and freeing engineers to focus on roadway safety.City of Hartford: Set a national benchmark for inclusive governance by using AI to provide real-time, two-way translation in 80 languages across all public city meetings, expanding participation while achieving $1.3 million in structural cost savings.City of Chattanooga: Centralized municipal crash and incident data using Google Cloud's AI and analytics tools, enabling city planners and public safety teams to identify high-risk corridors, optimize traffic signal timing, and prioritize infrastructure investments to make streets safer for residents.Indiana Department of Transportation (INDOT): INDOT deployed Google Cloud’s AI and document analysis models to automate compliance auditing across dense procurement contract repositories and scale smart road infrastructure. Meeting tight 30-day compliance mandates without pulling licensed engineers from active field projects, the solution saved 360 hours of senior engineering labor while automating roadway asset detection to ensure safer, well-maintained highways for residents statewide.City of Los Angeles: Facing the massive operational demand of hosting global events—including the 2026 World Cup, 2027 Super Bowl, and 2028 Olympic and Paralympic Games—the city is embedding Gemini directly into daily workflows across 45 departments and 27,500 employees. Serving as a force multiplier for municipal staff, the platform automates complex administrative tasks to amplify workforce capacity, accelerating service delivery and expanding multilingual support for over 15 million expected visitors and four million residents speaking more than 224 languages.Maryland State: The state partnered with Google Public Sector to empower its 40,000-strong workforce using Gemini and Gemini Notebook within a secure, privacy-first cloud foundation. By lowering cognitive load and automating repetitive administrative tasks, agency teams built and deployed a clean water management application in just five weeks-saving thousands of staff hours and accelerating environmental oversight to deliver more responsive, sustainable public services to Maryland residents statewide.Accelerate your AI journey with Google Public SectorThe agentic era is all about augmenting human capacity and empowering leaders and builders who make public service possible. Organizations across the public sector are leveraging Google Cloud’s integrated AI stack to redefine how they serve their stakeholders, empower their workforce, and advance their mission. At Google Public Sector, we are excited to partner with pioneering organizations as we build a more resilient, responsive, and connected government, together.Join us at our Google Public Sector Summit on October 20 to hear from public sector leaders who are leveraging AI to re-imagine service delivery in the agentic era.
How to upskill enterprise AI builders by using daily micro habits
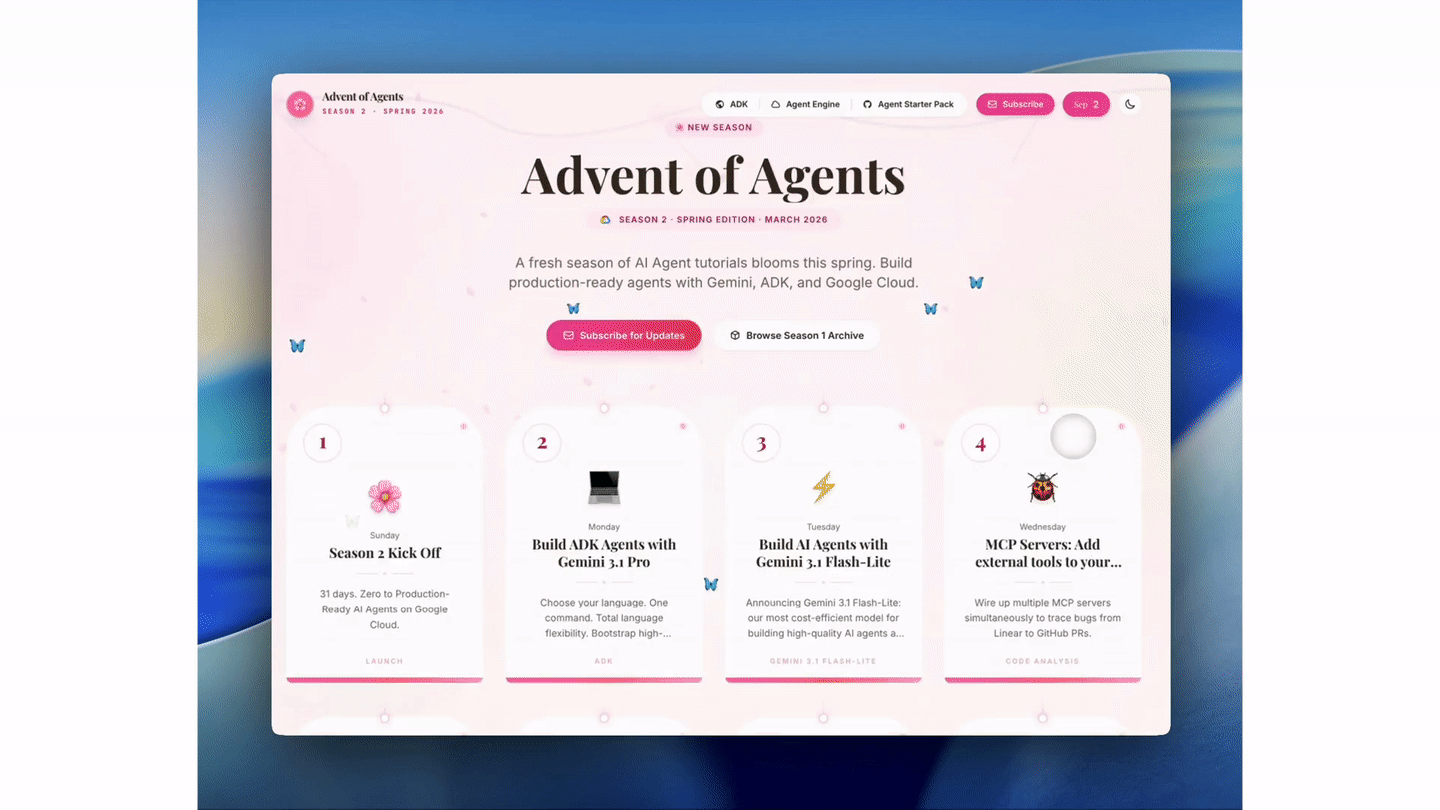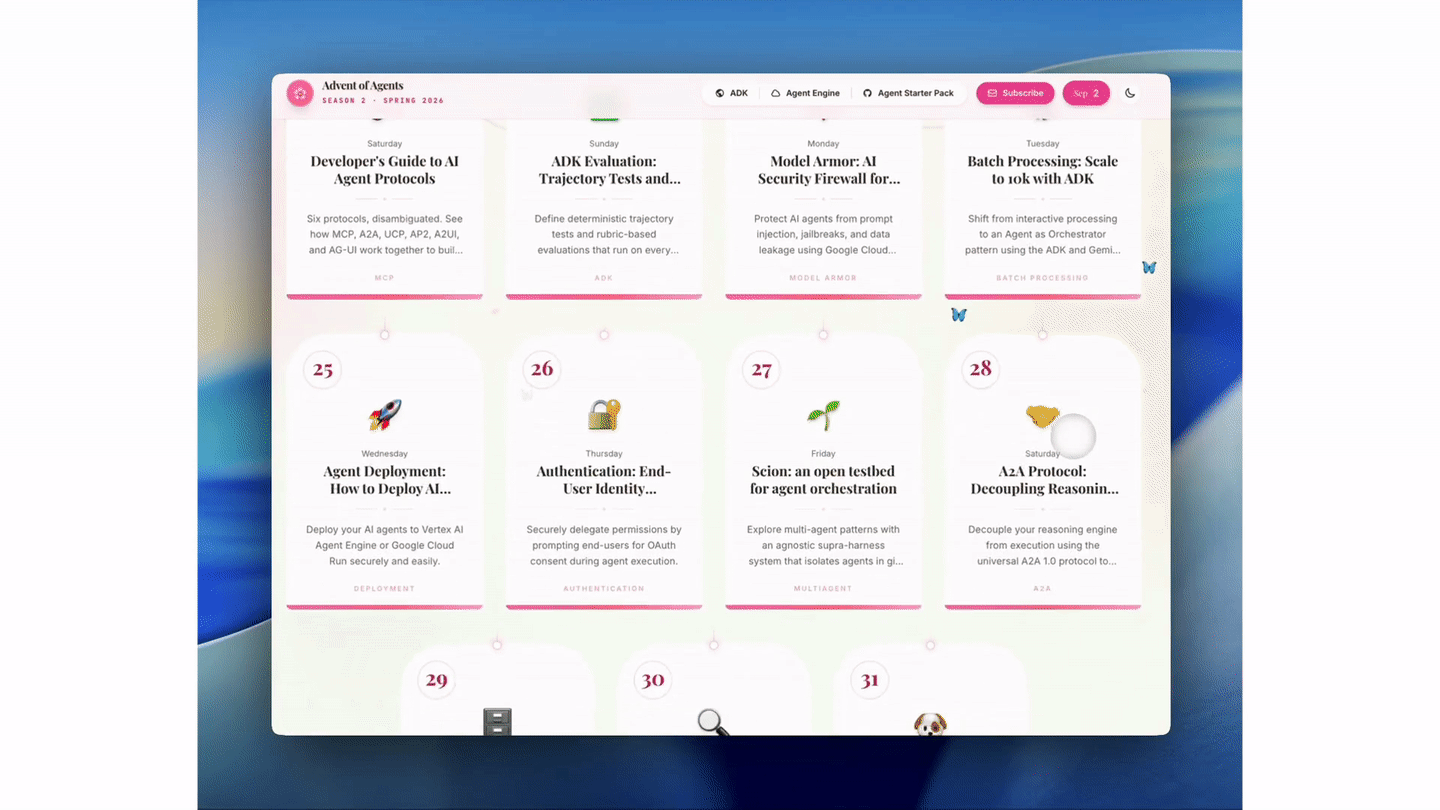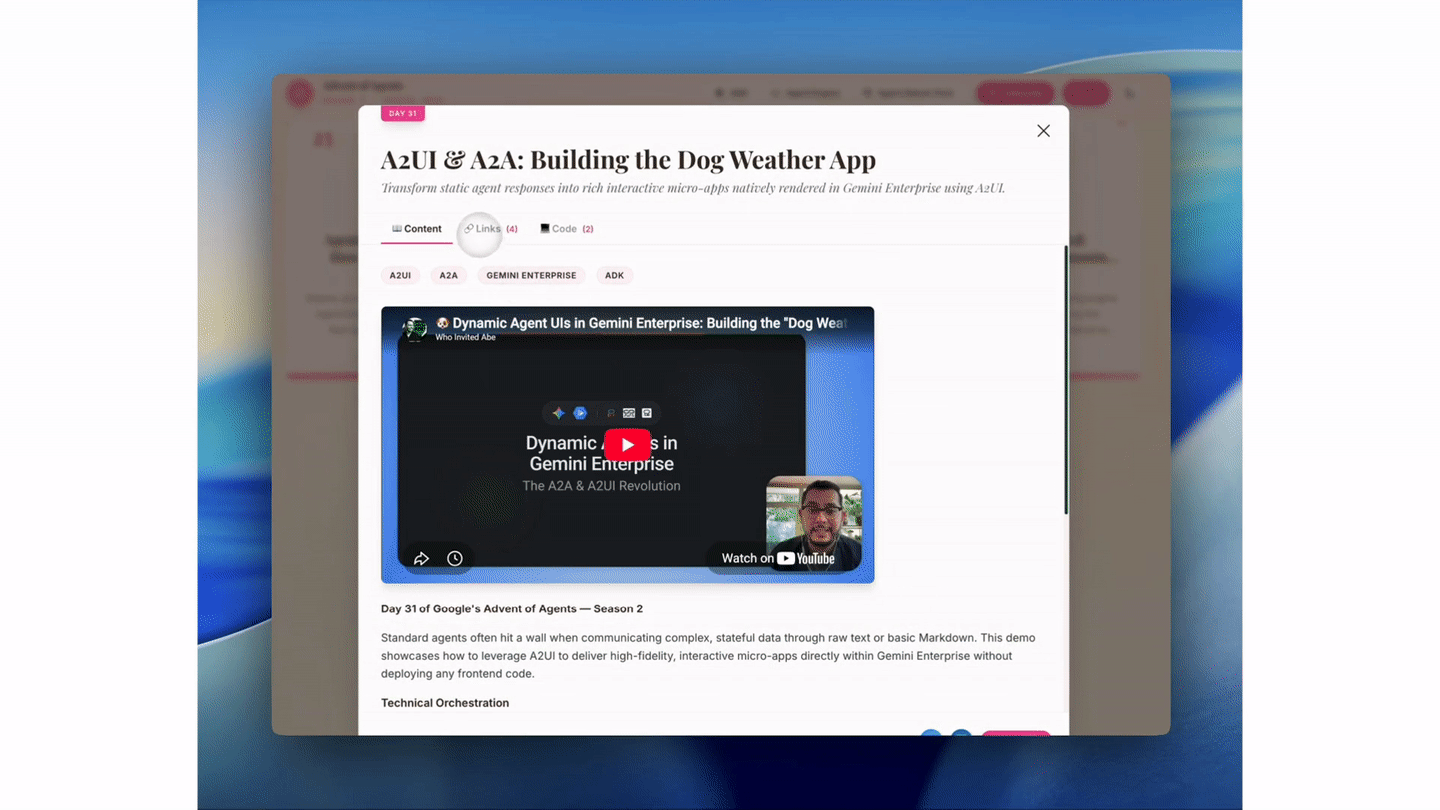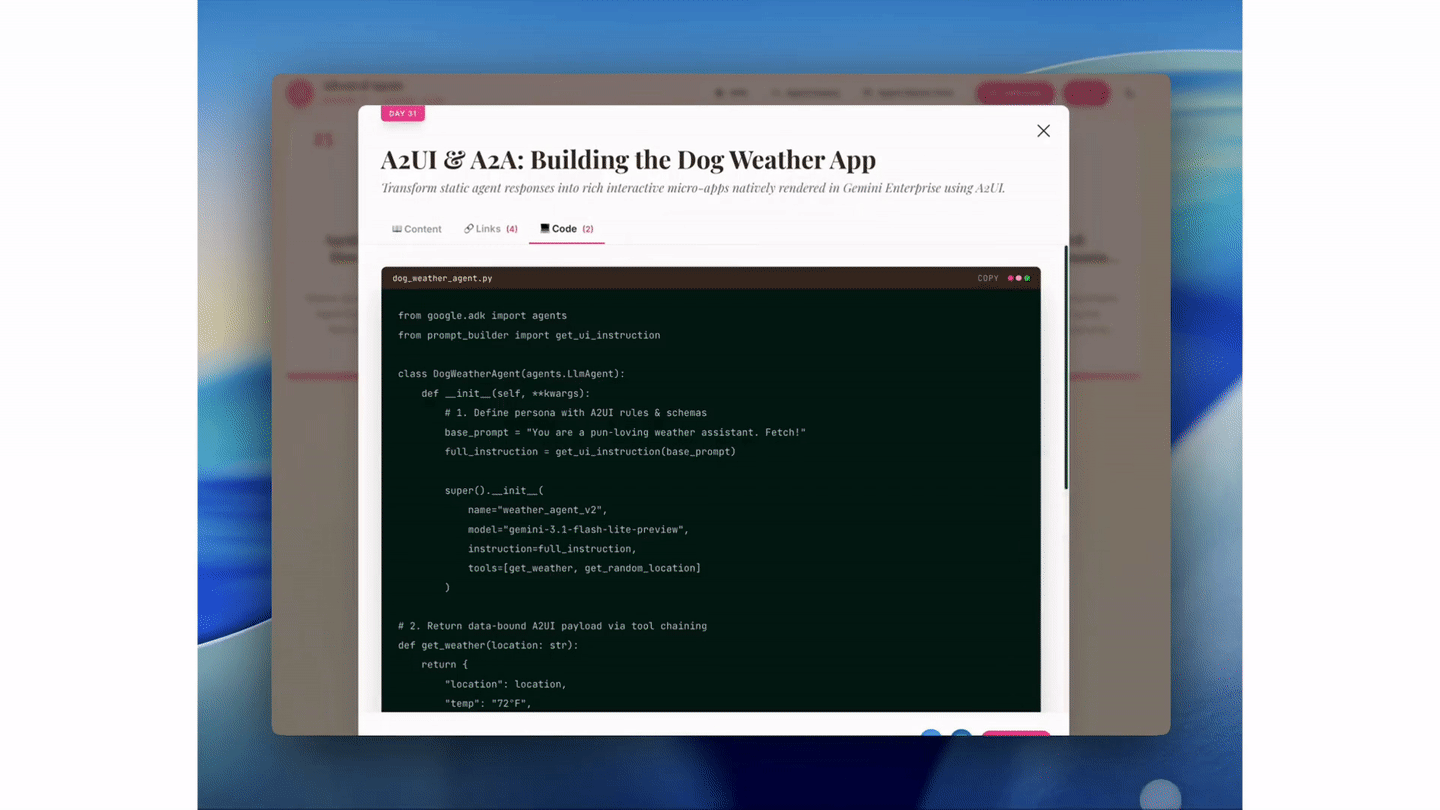
As enterprises invest in generative AI, tech leaders keep seeing the same pattern: Developers test AI tools for a week, hit setup problems, and then drift back to the backlog. Nothing ships. The real gap is enablement. In this landmark Harvard Business Review article, Josh Bersin and Marc Zao-Sanders noted that knowledge workers carve out just five minutes a day for formal learning. Most enterprise training programs still lean on week-long classroom bootcamps, multi-week certification tracks, and passive video lectures, none of which fit into the time developers actually have. With the Build with Gemini event series underway, Google Cloud Consulting is seeing more leaders rethink AI enablement by building quick, daily practice into their teams' routines. In this post, we'll walk through a four-pillar approach and the lessons from our global developer challenges to share what micro-habit upskilling looks like. Moving from workshops to daily practice The traditional method… …now becomes Multi-week, semi-annual classroom bootcamps Five-minute hands-on exercises Local workstation configuration and credential setup Pre-configured browser-based sandboxes Mandatory attendance and compliance checks Daily streaks, badges, and team challenges Multiple-choice quiz completion Deployable agent tools and reusable code Rolling out a model like this comes down to keeping each task small and manageable. Here's how we structure that work across engineering teams: Make micro-learning a habit. Offer short objectives that each cover one skill, like connecting a model to a database schema or validating structured output, in place of full-day training blocks. Give teams browser-based sandboxes. Setup is where most training stalls, so remove it. With a pre-configured, managed cloud environment, developers open a tab and are writing code within minutes, with no credentials to request and nothing to install or maintain on their own machines. Build in daily streaks. Milestones, shared wins, and teammates comparing solutions turn practice into a normal part of the workday. End every session with something that runs. Each exercise should leave behind a working component, and over time those components accumulate into a shared library of code and prompts the whole team can pull from. Lessons from the Advent of Agents program When Google Cloud launched Advent of Agents, a daily agent-building program for developers, we wanted to test one question: what happens when you remove setup and scheduling from technical enablement? Each day, developers got one short, real-world agent exercise they could run right in the browser, with no half-day to block off and no setup guide to read first. 150,000+ developers participated across global teams. 859,000+ hands-on code executions in browser-based environments. 31% of participants returned daily, more than triple the 10% industry average for self-paced tech, and significantly exceeding the standard 5%–15% MOOC benchmark 32,000+ participants built working agent components. The above data was accessed via Advent of Agents Google Analytics metrics. Keeping each exercise under five minutes and pre-wiring the sandboxes removed the two things that usually stall workplace training: setup time and scheduling. The numbers suggest developers will make time to learn when the exercise fits into the day they already have. Putting micro-enablement into practice AI enablement doesn't have to pause your sprints. It takes a consistent habit of practice and the tools that let teams build alongside their regular work. Experience live building. Bring your engineering teams to a Build with Gemini workshop. The events are complimentary and run different tracks according to technical depth, from no-code for business leaders to code-first for developers, with live hands-on labs supported by Google Cloud experts. Build skills with GEAR. Enroll your technical and business teams in the Gemini Enterprise Agent Ready (GEAR) program. Membership is free and includes monthly learning credits on Google Skills, hands-on labs, and skill badges, with learning paths for developers, line-of-business leaders, and IT decision-makers. Start small, build often Developing AI skills starts with a change in routine. Short, daily, hands-on exercises let developers learn by doing, and the working code they produce along the way becomes the team's starting library for production work. Give your developers a few minutes a day and a sandbox that's ready when they are. Start with one exercise this week and see how small, daily habits can build AI capability across your organization. Join a Build with Gemini workshop: Sign up today for interactive labs and practical training for developing secure AI agents. Start building with GEAR: Join GEAR and discover how to deploy enterprise-grade agents with hands-on learning and guidance. Explore free courses on Google Skills: Build in-demand AI expertise at your own pace.
The Dev Fest Community Workshop Experience: Building Real Agents Together
This week we kicked off the DevFest season in North America at Google Hudson Square in New York City with 80 engineers packed into the room. Typical technical workshops hand you a finished repo, tell you to blindly paste blocks of code into your terminal, and hope nothing crashes. You walk away with green checkmarks, but your brain stays on autopilot. We've introduced a completely different experience called Workbench. Workbench focuses on understanding core ideas and architectural models rather than obsessing over syntax and code snippets. Instead of getting bogged down in boilerplate, engineers spent the day grappling with the actual mental models behind graph engineering, self-evolving architectures, and automated self-patching harnesses. A glimpse into the Workshop Experience At the DevFest Community Workshop, we spent one intense day building long-running, self-evolving multi-agent systems powered by Google's agentic stack. Ricky Robinett, Senior Director of Developer Marketing, kicked off the day by diagnosing why so many engineering teams hit a wall with agents. Ricky broke down why prompt engineering fails as a safety mechanism: English is just a probabilistic suggestion, not an execution boundary. Right after Ricky, Rachel Francois, Google Developer Groups (GDG) North America Program Lead, took the stage alongside GDG Brooklyn organizers to welcome the community and spotlight the power of local developer chapters. They set the tone for the entire day, reminding everyone that building durable software works best as a team sport where engineers share real-world patterns and build local networks that outlast any single framework. Getting hands on with labs Annie Wang & Christina Lin, Americas DevRel Team members, led the morning lab that put those runtime ideas to work. Attendees explored Google's Agent Development Kit (ADK), Veo 3.1, Memory Bank on Gemini Enterprise Agent Platform, and RAG Engine on Gemini Enterprise Agent Platform. Through Workbench, developers grasped the principle of separating state from active compute for long running tasks. Workflows paused cleanly mid-execution, waited out asynchronous human approvals, and resumed without running up idle compute costs. After lunch, Logan Hennessy, Americas Developer Relations Engineer (DRE), and Kartik Derasari, Google Developer Expert (GDE), led a lab using auction history as insight for better bidding strategy. Attendees worked through the architecture by integrating BigQuery data into autonomous data engineering pipelines, reasoning about deterministic bidding logic and adding eval-gated, self-patching harnesses that catch spend anomalies and update runtime execution safely. Between lab blocks, we ran fast-paced speed quizzes where developers raced to lock in their answers as quickly as possible. Screens flashed, fingers flew across keyboards, and seconds made the difference between topping the leaderboard or dropping five spots. Nothing beats watching a room full of serious engineers completely lose their cool over a live quiz leaderboard. Join a DevFest Community Workshop this fall New York was only round one. We are taking this exact experience on tour to five more cities this fall. Find your city and grab your seat before spots fill up: Sunnyvale on September 30 Washington DC on October 6 Atlanta on October 30 (as a part of DevFest Atlanta) Seattle on November 4 Boston on November 10
Want to know the latest from Google Cloud? Find it here in one handy location. Check back regularly for our newest updates, announcements, resources, events, learning opportunities, and more. Tip: Not sure where to find what you’re looking for on the Google Cloud blog? Start here: Google Cloud blog 101: Full list of topics, links, and resources. aside_block <ListValue: []> Sept 14 - Sept 18 Storage Intelligence Advisor for Google Cloud Storage is now GAGoogle Cloud Storage customers can now manage cloud storage more effectively with Storage Intelligence Advisor, delivering curated metrics, automated anomaly detection, and actionable recommendations right out of the box, with zero setup required.Advisor baselines activity across your projects and automatically detects four key anomalies: surges in operations, unexpected rises in cross-region egress, and spikes in errors. Each finding includes deep drill-down visibility into the resources driving the change, alongside prescriptive steps to remediate issues before they impact performance or cost.Learn more to get started with Storage Intelligence Advisor. Build private WebSockets from Apigee X to Cloud RunReal-time AI agents and streaming architectures often require persistent, bidirectional connections. A new implementation guide by Apigee Customer Engineer Joel Gauci demonstrates how to establish private southbound connectivity between Apigee X and Cloud Run. Using Private Service Connect (PSC) and a Regional Internal Application Load Balancer, teams can enforce API governance and security policies at the edge while keeping backend services completely isolated from the public internet.Explore the step-by-step guide and open-source code Connecting Gemini Enterprise Agent Runtime to Apigee with Private Service Connect Deploying autonomous AI agents often presents security, compliance, and cost challenges. A new reference guide details how to build an end-to-end, private architecture between Gemini Enterprise Agent Runtime and Apigee. This design helps protect internal backends and manage token quotas. Read the full community guide and deploy the code Discover what’s new and next in ApigeeAs enterprise architectures adapt to generative AI and autonomous workflows, Apigee is expanding its proven platform capabilities to support modern AI gateway use cases alongside traditional API management. Join our session on Thursday, September 24, featuring Apigee Product Manager Geir Sjurseth. Get an inside look at recent product releases, explore architectural patterns for securing models and agents, and bring your questions for the live Q&A.Register for the September 24 Apigee product update Managed Service for Apache Kafka supports clusters with public Internet access!With Managed Kafka public clusters, you can now produce and consume messages from clients outside your VPC—including your local machine, for faster, frictionless testing. Public clusters unlock use cases like IoT devices, retail storefronts, and telco network towers. Enable public access on new or existing clusters via the Google Cloud console, gcloud CLI, or REST API. Spin up your first public cluster, or reach out to kafka-hotline@google.com with questions. Stream data directly into Bigtable using Bigtable subscriptions, now in Preview!You can write Pub/Sub messages to a Bigtable table with zero ETL with Bigtable subscriptions. No pipelines, no code, delivered by the serverless, zero-ops experience you already know with Pub/Sub. Power your AI workloads, from model telemetry to real-time context engineering, without the overhead of managing complicated ETL pipelines. Built to be dependable, with native support for dead-letter topics. Try the feature today! Sept 7 - Sept 10 Why Your Voice Agent Needs Session AuditingMoving voice agents to production demands robust quality monitoring. This guide dives deep into the inner workings of the Agent Development Kit (ADK) responsible for audio session auditing. Learn how the ADK's save_live_blob feature intercepts, buffers, and stores raw audio chunks during active Gemini Live sessions. We explore building an automated post-processing pipeline to seamlessly stitch these fragments into cohesive, playable audio files. Discover how to leverage these vital audio audit trails to monitor real-world interactions, diagnose failures, and ensure enterprise-grade reliability. Read the full guide here. AlloyDB Omni Red Hat RPM Orchestrator now Generally AvailableAlloyDB Omni Red Hat RPM orchestrator is now Generally Available. The AlloyDB Omni Red Hat RPM orchestrator offers a new way to manage PostgreSQL-compatible workloads on bare metal or VM platforms, combining the high performance of AlloyDB, access to generative AI features and Gemini models to build AI agents and applications, and full automation. The orchestrator simplifies cluster provisioning and lifecycle management by allowing you to define reference architecture specifications, customizable by adjusting instance parameters, node configurations, and networking options — discover all details in full blog post. Aug 31 - Sept 4 Automate VM guest software lifecycle with VM Extension Manager, now GAGoogle Cloud VM Extension Manager is now generally available, eliminating the need for custom startup scripts to manage guest OS extensions across Compute Engine fleets. Define declarative, project-wide policies that enforce desired software states across all regions and zones. Benefit from continuous drift detection with automatic self-healing, multi-zone phased rollouts with automated rollbacks on failure, and centralized fleet health visibility integrated with Cloud Monitoring.Explore VM Extension Manager documentation Assess Apigee migrations without a target environmentPlanning a migration to Apigee X or Hybrid? You can now assess your legacy Apigee Edge SaaS or OPDK environment earlier in your planning cycle. Using the updated --skip-target-validation flag in the Apigee Migration Assessment Tool, teams can generate a full inventory and establish scope baselines before target infrastructure or IAM credentials are provisioned.Read the guide to learn more. Claude Fable 5.1 is now available on Agent Platform. It brings performance improvements over Fable 5 across reasoning, full-lifecycle coding, multi-tool workflows, and knowledge work. Anthropic also announced Enterprise Frontier Safeguards, a solution that gives customers the option to safely deploy Anthropic’s most capable models while storing their data in cloud infrastructure they control. We continue to offer enterprise customers options across frontier models to build, deploy, and scale securely on Google Cloud. Aug 24 - Aug 28 Grok 4.6 is now available in Preview on Gemini Enterprise Agent Platform. xAI's most capable model, built for coding, agentic tasks, and knowledge work, Grok 4.6 joins Grok 4.3 and Grok 4.20 in Model Garden and becomes the flagship of the Grok family. It supports reasoning, function calling, and structured output for multi-step agentic workflows, and accepts text and image input.Get started today Empowering autonomous agents with advanced security governanceAI agents offer incredible productivity gains, but granting them access to read emails, query databases, and trigger APIs introduces critical new security risks. In fact, 79% of tech leaders cite security and governance as their biggest challenge to scaling AI. Traditional tools are no longer enough to handle automated threats like prompt injection and dynamic permissions. Discover how forward-thinking enterprises are using secure-by-default design, agent identity governance, and human-in-the-loop controls to deploy agents with confidence.Read more Stateful processing is available in BigQuery continuous queries in PreviewStateful operations significantly expand what’s possible with BigQuery continuous queries. This feature allows users to leverage functions like JOINs, aggregations, and windowing functions directly in their streaming queries. Now you can calculate metrics over time (for example, a 30-minute average) to power your downstream applications and AI agents with much richer, real-time signals. Try out our feature here and share your feedback with bq-continuous-queries-feedback@google.com! Synthetic data generator tool is available for Managed Service for KafkaYou’ve launched your first Kafka cluster. Now what? The next thing to do is to produce some data to the cluster, but that involves modifying a client application somewhere or spinning up a virtual machine. The synthetic data generator tool, now generally available, can start sending mock data to your cluster in 3 clicks, and will get data streaming into your cluster in less than two minutes. The perfect utility for those moments you just want to test your cluster and new features. Try our quickstart today! Dataflow pipeline updates are faster & more flexibleDataflow pipeline updates can now stop-and-replace pipelines, a major addition to the existing in-place-update feature. The new parallel pipeline option accelerates the migration between the old & new pipeline, resulting in reduced disruption to your business. You can also set a timeout on drains that prevents runaway costs for your pipeliness in the event of stuck processing. This feature is generally available. Try it here! Aug 17 - Aug 21 Webinar: Agent Identity as the backbone for secure AI innovationAn AI agent with a stolen API key looks identical to a legitimate one. As autonomous agents scale across enterprise systems, static credentials and legacy IAM policies can no longer keep up with machine-speed execution. Join Shaun Liu, Product Manager at Google Cloud, on August 27 at 1 PM ET to explore Google Cloud’s vision for unifying agent, human, and nonhuman identity into a workload-centric platform using verifiable cryptographic identities (SPIFFE, ID-JAG, OAuth).Register for the webinar now Aug 10 - Aug 14 Diagnosing Apigee Hybrid Cassandra Read Latency for Peak PerformanceDiagnose real-time Cassandra read latency and resolve API key verification bottlenecks in Apigee Hybrid with this step-by-step troubleshooting guide. Learn how to deploy a debugging client and query performance tables to maintain sub-millisecond response times. Read the Apigee Hybrid Cassandra Troubleshooting Guide Keep moving with agents! The All Things Agentic Hackathon is officially live.We're challenging builders to build next-generation agents that take on the busy work and handle the heavy lifting in the background using Gemini 3.5 and Google Cloud. Compete for your share of $190,000 in prizes, cash, and Google Cloud credits! Submissions are open from August 3, 2026, to August 31, 2026.Learn more and register. Sign up for GEAR to get exclusive updates and your badge. # Accelerate PostgreSQL migrations using Gemini in Database Migration ServiceEnterprise database migrations often stall during the "last mile" of translating legacy stored procedures, triggers, and custom functions from Oracle or SQL Server. Database Migration Service (DMS) now provides AI-assisted code conversion powered by Gemini in Databases. By combining deterministic compiler rules for 1:1 syntax with Gemini contextual synthesis for complex procedural blocks, DMS converts legacy code into native PostgreSQL and AlloyDB with full schema awareness and side-by-side validation.Read the full blog post to learn how to streamline your database code conversion. Compute Flex CUDs now available for G2 and G4 GPU VMsCompute Flexible Committed Use Discounts (Flex CUDs) are now available for G2 (NVIDIA L4) and G4 (NVIDIA RTX Pro 6000) VMs. You can now lock in predictable savings while retaining the flexibility to adapt across VM families, migrate between regions, and combine general-purpose compute, GKE, Cloud Run, and G2 & G4 GPU VMs under a single spend commitment. Flex CUDs for G-series VMs let you lock in savings today while preserving the agility to upgrade to latest hardware without disruption!Explore VM instance pricing or learn more about Flex CUDs. Rapid Bucket accelerates the training and checkpoint performance in PyTorch Ecosystem via GCSFSWith the release of GCSFS 2026.8.0, organisations can now unlock maximum ROI from their AI/ML infrastructure by eliminating data starvation on GPUs in PyTorch ecosystem when they are using Frameworks like Dask, Pandas, PyTorch , PyTorch Lightning, Hugging Face Datasets, Ray dataetc. By making adaptive concurrent prefetching the default, GCSFS dynamically predicts and background-fetches sequential read patterns—boosting single-file throughput by 5x, and scaling up to 21 GiB/s , saturating the NIC when paired with Rapid Bucket. Saturating the NIC translates to significantly improved accelerator goodput and reduced training wait times with zero integration friction. Training and checkpoint restore workflows benefit from intelligent memory management that automatically drains the buffer during random reads to completely avoid bandwidth or memory penalties. Aug 3 - Aug 7 Navigate data sovereignty and AI innovation with hybrid cloudFor enterprises facing strict compliance rules, keeping sensitive data on-premises often means missing out on cutting-edge AI. Data from the 2026 State of AI Infrastructure report reveals that 52% of IT leaders are adopting hybrid cloud strategies to bridge this gap. Our latest blog post explores how Google Distributed Cloud (GDC) helps organizations deploy connected or air-gapped models to run advanced AI entirely within secure environments—mitigating geopolitical risks without sacrificing innovation. Read more. SAP and Google Cloud Launch BDC Connect for BigQueryFor years, enterprises have struggled with the cost, risk, and complexity of moving mission-critical SAP data into advanced analytics platforms. The general availability of SAP Business Data Cloud (BDC) Connect for BigQuery marks a turning point. By introducing revolutionary zero-copy, bi-directional data sharing, this new capability seamlessly bridges SAP systems with Google Cloud's powerful data and AI ecosystem. Instead of wrestling with manual data duplication and lost business context, organizations can now eliminate silos, dramatically lower their analytics costs, and rapidly deploy trustworthy, agentic AI solutions grounded in real-time operational reality. Read the full announcement to learn how to transform your data strategy. Google Cloud Cortex Framework version 7 is now generally available!This release helps you modernize your data architecture for AI agent readiness, enabling you to quickly deploy, customize, and extend robust data products while simplifying orchestration and reducing infrastructure overhead. It provides data product accelerators for SAP-sourced data to build trusted, high-quality data products ready for advanced analytics and agentic use cases. The Framework integrates with Google Cloud products including BigQuery, Dataform, Knowledge Catalog, and Gemini Enterprise Agent Platform. Learn more in our announcement blog, technical documentation, or try a demo deployment today. From API Management to AI Gateway with ApigeeMassive LLM adoption unlocked automation but exposed critical vulnerabilities, from unpredictable token costs to security risks like prompt injection. Without central management, organizations face accelerated technical debt. Learn how to transform Apigee into an enterprise AI Gateway to centralize governance. This architectural roadmap details how to utilize semantic cache to optimize token costs, implement prompt protection policies for security, and productize tools using the emerging MCP standard.Read the full architectural roadmap on the Apigee Community Hub Centrally govern enterprise AI traffic with Apigee AI GatewayManage, track, and secure model communication across your entire infrastructure from a single pane of glass. In a new video walkthrough, Principal Architect Tyler Ayers demonstrates how Apigee AI Gateway simplifies agentic governance. Learn how to transparently proxy model traffic, log real-time token counts, and apply runtime security quotas without impacting your developer workflow.Watch the Apigee AI Gateway demo Maximize Provisioned Throughput UtilizationSudden traffic micro-spikes can exceed per-second quotas, triggering 429 errors or forcing overflow into shared resource pools. A new architectural guide demonstrates how to build a serverless "shock absorber" using Cloud Run and Google Cloud Tasks. By decoupling request ingestion from execution, this queue-based pattern flattens volatile traffic bursts and smoothly drips requests to Gemini at your exact quota rate, maximizing Provisioned Throughput utilization while eliminating job failures during peak usage. Read the step-by-step setup guide. Eliminate security blindspots in agentic tool agentic tool calls via the Model Context Protocol (MCP) can introduce critical security risks to your enterprise architecture. Join our technical deep dive on Thursday, August 13, to discover how to position Apigee as a centralized security gateway. Featuring the new ParsePayload policy and payload operations groups in API Products, this session demonstrates how to enforce granular tool filtering, manage execution quotas, and scale secure agent ecosystems without impeding developer velocity. Register for the August 13 Community TechTalk Jul 27 - Jul 31 Data Cloud and Apigee CDMX: The AI Agent Evolution | August 12, 2026Enterprise AI demands evolution beyond basic conversational assistants. To generate real value, AI models must connect with the organization's core systems and live data sources. Join us this August 12 at Google CDMX for the exclusive event AI Evolution: Powering Tomorrow's Enterprise. Learn how to design an agile and secure ecosystem by unifying the power of Gemini, Apigee, and data agent technologies through practical demonstrations led by Google Cloud engineers.Secure your spot for the in-person session in Mexico City Register now! Vast Edge, built on GCP, launches the first live recovery interface for cloud backups, enabling IT teams to inspect backup contents in real time. This transforms backups from a blind, log-based process into an interactive platform where teams can instantly search, preview, and validate the exact data available for restore.This platform protects Google Workspace, NetSuite, Salesforce, Workday and many SaaS environments, providing complete visibility and enterprise-grade oversight.Visit Vast Edge Backup & Disaster Recovery and get a free trial of their backup solutions on the GCP Marketplace for Google Workspace Backup, NetSuite Backup, Salesforce Backup, and Workday Backup. Jul 20 - Jul 24 Claude Opus 5, Anthropic’s latest model, is now available on Agent Platform. It brings performance improvements over Opus 4.8 across coding, long-running agents, and knowledge work.The model is Zero Data Retention (ZDR) compatible. For safety, high-risk workflows — such as penetration testing or exploit generation — it will notify you and fall back to Opus 4.8.We’re excited to continue to offer enterprise customers options across frontier models to build, deploy, and scale AI securely. Try it here. Apigee Northam Roadshow 2026 | The AI Agent Evolution: Powering Tomorrow's EnterpriseAI is evolving. As your organization deploys autonomous agents, the integration between APIs and models becomes critical. Join Google Cloud specialists for an exclusive day of deep-dive sessions and live demos. Discover how the unified power of Apigee and the Google Cloud Agent Platform allows you to build, govern, and scale high-performance AI agents with complete control. Call to Action: Register for Sunnyvale | Register for NYC | Register for Chicago Deploy an Apigee Proxy for MCP Registry Discovery Learn how to deploy an Apigee X proxy to format Apigee API Hub data into the Model Context Protocol (MCP) Registry format. This tutorial by Tyler Ayers guides developers through cloning the sample repository, deploying using the Apigee Feature Templater (aft), and testing the endpoint to make API data easily discoverable by coding agents. Read the full community tutorial to get started. Simplify AI Infrastructure: Getting Started with Apigee AI GatewayManaging a complex AI landscape with multiple backend environments can present significant operational and governance challenges. A new tutorial walks you through how to build a unified API proxy using Apigee AI Gateway. By establishing a single, secure entry point for all model traffic, teams gain access to real-time analytics, comprehensive tracing, and financial operations auditing—completely seamlessly, and with absolutely no modifications required to client environments or user configurations. Read the step-by-step setup guide Your AI agents are ready. Is your data?The biggest bottleneck to scaling AI isn't the models—it's giving them access to business context. As enterprises move to proactive systems of action, legacy infrastructure often buckles under the nonlinear speed of AI agents. Google Cloud’s new Agentic Data Cloud, built on AI-native infrastructure, solves this by unifying data, AI models, and operational databases. Discover how a borderless Lakehouse and active Knowledge Catalog can empower your AI agents with trusted, real-time context without unnecessary engineering overhead. Read more. Secure and govern your AI at Apigee AI Horizon in LondonMoving AI from basic prompts to complex agentic workflows requires trust and control. Join us on Tuesday, 1st September 2026 at Google London for our 5th edition of Apigee AI Horizon. Discover how Google Cloud product leaders and architects are using Apigee and Model Armor to secure LLM APIs, implement policy controls, and manage token consumption. Do not miss this one—register soon!Secure your spot for AI Horizon London Jul 13 - Jul 17 Resource-Based CUD Sharing is Now Enabled by DefaultStarting June 16, 2026, the default setting for Google Cloud Resource-based Committed Use Discount (CUD) sharing will change from disabled to enabled for new billing accounts and eligible existing accounts without active CUDs. This update automatically maximizes your savings by pooling underutilized discounts across your resources.You retain full control and can adjust your CUD sharing preferences at any time by changing your CUD scope configuration. For instructions, see Enable CUD sharing or Disable CUD sharing. Webinar for India: Google Cloud for EdTech: Optimizing Traffic and Token Governance at ScaleAPI traffic surges and AI model integration are reshaping the EdTech landscape. Join Satyam Maloo for the webinar Google Cloud for EdTech: Optimizing Traffic and Token Governance at Scale on July 23, 2026. Learn to implement advanced rate limiting, gain granular token visibility, and leverage real-time analytics to govern your platform effectively. Whether you’re scaling for peak academic seasons or integrating complex AI workflows, this session provides the infrastructure blueprint you need.Register Now Scaling AI Agents: Treat prompts like software artifactsAs AI agents move into production, monolithic system prompts often result in configuration drift, merge conflicts, and silent runtime failures. The solution is adopting a Prompts-as-Code architecture. By breaking prompts into modular skill files and using a build-time transpiler, engineering teams can introduce dependency resolution, static validation, and CI/CD rigor to their agent's control plane. Stop manually editing massive text files and start building deterministic, reliable agent infrastructure.Read more here. Jul 6 - Jul 10 Webinar: Introducing Google Cloud NGFW Enterprise advanced malware protection - powered by Palo Alto NetworksDiscover the new Cloud NGFW advanced malware sandbox, arriving in preview later this year. Powered by Palo Alto Networks Advanced Wildfire, it leverages data from 70,000+ customers to help defeat advanced malware. Join us on July 16 at 11 AM EDT to learn how to build a resilient, zero-trust cloud infrastructure that protects your apps and data, wherever they reside.Register for the webinar now Safely run AI-generated code in Cloud Run sandboxesCloud Run sandboxes, now in public preview, are lightweight, isolated execution boundaries that you can spawn near-instantly within your existing Cloud Run service instances.Whether you need to let an LLM run a dynamically generated Python script to calculate business margins or spin up a headless browser to perform web research, Cloud Run sandboxes give you a secure, isolated sandbox to run these tasks without leaving your serverless environment.Read the blog to learn more and get started today. Australia API Horizon: Scaling Enterprise Governed AI AgentsThe transition from AI chatbots to autonomous agents is the most critical integration point for your business. Join Google Cloud at our upcoming events to explore exclusive deep-dive sessions on architecting for the agentic era.Discover how to use Apigee as an intelligent AI Gateway to govern, secure, and scale high-performance architectures. You will learn to seamlessly build AI tools from your existing APIs and maintain control over your entire ecosystem.Join us in your preferred city: Sydney: July 28, 2026, at Google Sydney, One Darling Island. Canberra: July 29, 2026, at Hotel Realm. Melbourne: August 4, 2026, at Google Melbourne. Build highly available, multi-region services on Cloud RunMaintaining uptime for business-critical applications just got a lot easier on Cloud Run. Service health, now Generally Available, automates cross-region failover by leveraging readiness probes for instance-level health checks with a simple, two-click setup. You can configure service health with global external Application Load Balancers for public-facing applications or cross-region internal Application Load Balancers for private networking traffic.Learn how to configure service health for Cloud Run. Report: 83% of organizations need infrastructure upgrades for agentic AIThe shift from conversational bots to autonomous agents is breaking legacy systems. Our new State of AI Infrastructure report details how engineering leaders are adapting to these massive new workloads. To eliminate inference bottlenecks, control hidden scaling costs, and manage agent sprawl, the industry is rapidly moving toward fluid compute, centralized governance, and unified, co-designed architectures.Explore our key infrastructure insights Stop tinkering, start scaling: the industrialized AI PlaybookDid you know that only 5% of custom AI investments actually return measurable business value? The problem isn’t the technology—it’s how organizations are wired to run it.In this compelling read, Google Cloud Consulting breaks down the operational blueprint that bridges the stark gap between "cool tech experiments" and real, P&L-impacting enterprise ROI.Read the full article on Medium AI Agent Clinic: Slashing App Latency by 80%Prototyping an AI agent is easy, but scaling for live traffic presents unique challenges. In the latest AI Agent Clinic, our technical experts partner with a developer to optimize PlaybackIQ, a live football analysis agent. This session demonstrates how to use OpenTelemetry to trace bottlenecks in the Gemini Enterprise Agent Platform and deploy to Cloud Run for high-concurrency scaling, achieving an 80% reduction in response time. Learn production-grade debugging strategies to optimize your own LLM applications.Watch the 60-minute teardown Jun 29 - Jul 3 Claude Sonnet 5, Anthropic’s latest model, is now available on Agent Platform. This addition serves as a drop-in replacement for Sonnet 4.6, giving organizations expanded choice for task completion across enterprise workflows. It features enhanced reasoning, cleaner code generation, and computer use capabilities for desktop and browser workflows.By continuing to rapidly bring frontier models to our platform, Google Cloud offers an uncompromised choice of the industry's best technology to build, test, and scale enterprise-grade AI.Get started today. Automate your AI governance with Apigee and YAMLManual API gateway configurations can quickly slow down your AI engineering velocity. Join the Apigee community on Thursday, July 16, to discover an automated, declarative blueprint for model garden management. Learn how a simple, repeatable YAML pattern lets your AI practitioners instantly spin up secure, policy-backed enterprise configurations without friction. Bring your questions and connect during our live Q&A session. Register for the July 16 Community TechTalk Build next-generation AI portals for autonomous agentsStandard developer portals were designed for human developers to subscribe to static APIs. Today, autonomous agents, LLM toolkits, and dynamic runtimes demand a central nervous system for governance. Join our technical deep dive on Thursday, July 23, to explore Apigee's new AI Portals solution. You will see exactly how to deploy full-service, MCP powered hubs to safely manage enterprise self-service for models, tools, and agents. Register for the July 23 Community TechTalk Protect your infrastructure from advanced cyberattacks at the API layer (Presented in Portuguese)In an era of increasingly sophisticated threats, relying solely on traditional firewalls leaves critical data gaps. Join our technical community TechTalk on Thursday, July 30—conducted in Portuguese—to learn how to proactively mitigate risks directly at the gateway layer. This session demonstrates how to configure and govern essential Apigee security policies to build a robust line of defense, ensuring maximum availability and complete integrity for your enterprise microservices. Register for the July 30 Portuguese Community TechTalk Jun 22 - Jun 26 Accelerate TPU model loading while saving RAM on GKE.Large model cold starts often stall scaling and leave high-value TPUs idle. The open-source Run:ai Model Streamer now natively supports TPUs with Google Cloud Storage in TPU vLLM 0.18.0. This integration accelerates inference pipelines on GKE by streaming tensors directly into CPU memory, bypassing local disk bottlenecks and the "double-buffering" trap. In benchmarks, loading a 480B parameter model was over 2x faster while cutting peak host memory usage by half. Read the full guide and get started today. Stop Training Blind: Scaling AI with the New OpenTelemetry-Based TPU AI Telemetry Collector AgentGoogle Cloud’s new AI Telemetry Collector agent standardizes TPU monitoring using OpenTelemetry. It optimizes enterprise ML workloads by identifying silent failures and providing zero-cost operational metrics without draining host CPU cycles. The agent seamlessly routes telemetry to Google Cloud Monitoring or Prometheus and custom Grafana setups. Pre-installed on Google-optimized Ubuntu images or available via Docker, it tracks memory, network latency, and core utilization to maximize multi-node training efficiency.You can read more of this capability by clicking this link. Jun 15 - Jun 19 Join us for a deep dive into agentic AI control with AppyThingsYour integrations aren’t failing—they are evolving. When users interact with AI agents, they no longer arrive directly at your site, resulting in experiences stripped of your context, expertise, and intended experience. Join us on Thursday, June 25, for a community tech talk in partnership with AppyThings to learn how to solve this new gateway challenge. We will explore how MTN laid an integration foundation with the Model Context Protocol (MCP) to deliver accurate, consistent experiences. Our technical experts will demonstrate how to leverage Apigee as a centralized tools management solution to govern agent access. Register for the session Optimize Spot VM Deployments with Capacity Advisor for Spot, Now in Public PreviewGoogle Compute Engine has launched Capacity Advisor for Spot to Public Preview, now open to all customers. This tool turns Spot capacity discovery into a data-driven process by providing real-time deployment recommendations to maximize obtainability and minimize preemption risks. Query the Capacity Advisor API for obtainability and minimum estimated uptimes, or use the new Console UI featuring a global availability map, spot price lookups, and historical preemption rate trends to visually find the most cost-efficient compute capacity.Get started today to start optimizing your Spot VM deployments! Build a multi-tenant agentic AI systemWhen scaling generative AI across different business units, your teams need specialized AI agents with unique operational rules and tools. Our new reference architecture helps you build a centralized multi-tenant platform to prevent fragmented silos, eliminate data exposure risks, and maintain unified compliance. Read the guide to design and deploy a multi-tenant agentic AI system in Google Cloud. How to Configure Gemini Enterprise to Connect to a Custom MCP ServerThe Gemini Enterprise MCP Connector was a big announcement at Google Cloud Next because it introduces the ability to connect Gemini Enterprise to MCP servers. This blog post provides a step-by-step guide on how to configure your first Custom MCP Server connector using the Google Maps Ground Lite MCP server as an example. Once you understand this flow, you can configure multiple MCP servers with Gemini Enterprise to bring all the context you need. Jun 8 - Jun 12 Simplify Multi-Cloud Planning with Cloud Location Finder, now Generally Available Cloud Location Finder provides up-to-date data on public regions, zones, and Google Distributed Cloud Connected locations across Google Cloud, AWS, Azure, and OCI. You can now programmatically discover locations based on provider, proximity, territory, and carbon footprint to optimize your global infrastructure strategy for performance, compliance, and sustainability. Get started for free today Jun 1 - Jun 5 Modeling the physical world with BigQuery GraphManaging complex supply chains requires more than just spreadsheets; it requires a digital replica of the physical world. In this post, Guru Rangavittal and Candice Chen explore how BigQuery Graph enables organizations to build a digital twin by turning physical assets into an interconnected map of nodes and edges. By moving beyond traditional relational databases, businesses gain real-time clarity into operations—from executing surgical ingredient recalls to analyzing weather-driven logistics risks. Discover how BigQuery Graph transforms reactive firefighting into proactive, precision modeling, allowing you to see critical connections in seconds and future-proof your supply chain. Apigee for AI: Govern LLMs and MCP Servers (Presented in Spanish)Learn how to securely transition your AI initiatives from experimental prototypes to enterprise-ready deployments. Join Luis Cuellar on June 18 for a technical deep dive (presented in Spanish) exploring Apigee’s latest AI gateway capabilities. Discover how to centralize governance over Model Context Protocol (MCP) servers, protect Large Language Models (LLMs) with robust API gateway security policies, and manage token-based quotas.Register for the June 18 Spanish Community TechTalk May 25 - May 29 Anthropic’s Claude Opus 4.8 is now available on Gemini Enterprise Agent Platform. As we continue to expand our platform's model offerings, this addition gives organizations more options for handling complex, multi-stage enterprise workflows. Claude Opus 4.8 brings strong capabilities in agentic coding, allowing developers to manage extensive refactors and tracking dependencies over extended sessions. API Horizon Munich July 6, 2026: Orchestrating the Next Era of AI and APIs Master the orchestration of next-gen AI and digital ecosystems. Join Google Cloud experts and DACH tech leaders on July 6 for an exclusive look at the Apigee roadmap, Agent Management, and Model Context Protocol (MCP). Gain real-world insights and connect with the regional integration community.Register now Securing AI Agents: The Extended Agent Gateway PatternLearn how to prevent autonomous AI agents from invoking unauthorized APIs. Join Apigee Specialist Joel Gauci on June 4 for a technical deep dive into the Extended Agent Gateway pattern. This session covers enforcing Fine-Grained Authorization (FGA), implementing secure token exchange, and establishing Model Context Protocol (MCP) governance at the API gateway layer to protect enterprise backend services.Register for the June 4 Community TechTalk API-to-Agent Security: Exposing REST APIs to Gemini Enterprise via MCPConnect Gemini Enterprise agents to core data without creating security hazards. Join Google Cloud Specialist Nigel Walters on June 11 to learn how to instantly transform legacy REST APIs into secure Model Context Protocol (MCP) servers. We’ll cover how to safely register tools with Gemini while enforcing gateway-level guardrails like rate limiting and access control policies.Register for the June 11 Community TechTalk May 18 - May 22 Chinese Webinar | June 4: AI Command and ControlAs AI agents move from experimental pilots to core enterprise functions, governance has become a critical next step. Join Google Cloud on June 4th at 10:00 AM (Beijing Time) to learn how to build a secure AI management layer architecture. We'll explore how to develop governed MCP (Model Context Protocol) endpoints, manage tool access to enterprise data, and leverage robust audit logs to operationalize AI. This session also includes a practical demonstration of these governance frameworks on Google Cloud.Register here GCP Announces New Features to Benchmark and Optimize LLMs for On-Device Use CasesDeploying fine-tuned LLMs from GCP to edge devices like smartphones is complex due to fragmented hardware. Google AI Edge Portal bridges this gap, giving GCP developers the ability to test AI performance on 120+ Android devices, representing the full diversity of high, medium, and low tier smartphones on the market today. This week at I/O, we announced brand new capabilities to benchmark and debug LLM performance across these devices. Sign-up to utilize these new features in private preview today. May 11 - May 15 Build Your AI & MCP Control Tower for Universal GovernanceMaster the future of agentic security with Apigee. Join our Community TechTalk on May 21 to discover how Apigee serves as a central "Control Tower" for the Model Context Protocol (MCP). We will explore how new JSON-RPC tool authorization enables fine-grained access policies across your organization, ensuring secure and scalable AI deployments. Whether managing internal tools or external users, learn to govern your agentic ecosystem with absolute precision. This session is designed for global coverage across EMEA and AMER regions.Register for the May 21 Community TechTalk Apr 27 - May 1 Master Your Launch: The Apigee Production Go-Live ChecklistEnsure a secure launch with the Apigee production guide. Join Nicola Cardace on May 28 to explore security guardrails, including IAM roles, mTLS configurations, and encrypted KVM migrations. Scheduled at 11 AM EDT / 5 PM CEST to support EMEA and AMER teams, this TechTalk provides the technical roadmap you need to flip the switch with absolute confidence.Register for the May 28 Community TechTalk Transforming APIs into Governed Agentic Tools on the Google Cloud Agentic PlatformTurn your APIs into secure, governed agentic tools on the Google Cloud Agentic Platform. Join Specialist Christophe Lalevée on May 7 for a technical deep dive into AI productization. Scheduled at 5 PM CEST / 11 AM EDT to maximize coverage for developers across EMEA and AMER, this session explores the integration and governance frameworks required to scale enterprise-ready AI with confidence. Register for the May 7 Community TechTalk Fractional G4 VMs are Generaly Available, providing a highly efficient and cost-effective entry point for AI and graphics workloads. These new configurations, using NVIDIA virtual GPU (vGPU) technology, allow you to leverage the power of the NVIDIA RTX PRO 6000 Blackwell Server Edition GPUs in flexible, smaller increments, so you can right-size your infrastructure to match the specific demands of your applications. By providing more granular access to advanced hardware, fractional G4 VMs let you optimize resource allocation and reduce overhead without sacrificing performance. You can now select from additional GPU slice sizes for your specific needs: 1/2 GPU: Ideal for more intensive tasks such as LLM inference, robotics sensor simulation, and high-fidelity 3D rendering. 1/4 GPU: Optimized for mainstream workloads, including mid-range creative design, video transcoding, and real-time data visualization. 1/8 GPU: Great for lightweight applications such as remote desktops, productivity tools, and entry-level streaming services. Transitioning AI from a sandbox prototype to an enterprise-grade system is a major hurdle. A monolithic script won't suffice for widespread deployment. To achieve true scale and reliability with Gemini, organizations must adopt service-oriented micro-agent architectures, establish Zero-Trust security, and implement rigorous EvalOps. Master the "Agentic Maturity Ladder" to ensure your AI & Agentic solutions are robust, secure, and ready for the real world. Watch the deep dive and read the developer blog to learn more. ML Development in VS Code with Google Cloud Power: Workbench Extension Now AvailableData scientists and developers can now combine the local productivity of VS Code with the scalable infrastructure of Google Cloud. The new Google Cloud Workbench Notebooks extension allows you to connect to and run notebooks on managed cloud environments directly within your local IDE. This integration streamlines the ML lifecycle by eliminating context switching and providing high-performance compute for complex workloads in a familiar interface. As part of our commitment to the developer ecosystem, the extension is fully open-sourced to support community-driven innovation. Install from Marketplace: GoogleCloudTools.workbench-notebooks Contribute on GitHub: colab-enterprise-vscode Apr 20 - Apr 24 Announcing the 2026 Google Cloud Partners of the YearGoogle Cloud is honored to celebrate the winners of the 2026 Partner of the Year awards! These awards recognize an exceptional group of partners across AI, Security, Infrastructure, and more, who have demonstrated a commitment to customer success. From global system integrators to specialized startups, these winners are leveraging the power of Google Cloud to solve complex challenges and drive digital transformation worldwide. Join us in congratulating these organizations for their innovation, collaboration, and impactful results over the past year.See the 2026 Partner Award winners Apr 13 - Apr 17 We're excited to announce the Public Preview of Datastream’s metadata integration with Knowledge Catalog. This is the first step in our vision to provide a centralized, "single pane of glass" for all Datastream assets. The enhancement automatically synchronizes Streams, Connection Profiles, and Private Connections, eliminating data silos. It enhances discoverability, allowing you to search for Datastream assets using the same interface as BigQuery tables. Centralized governance is also provided, making your real-time data estate more transparent and easier to manage. Upgrading Apigee OPDK to 4.53 with OS your infrastructure using Google’s official, sequential upgrade path. Our Technical expert, Rakesh Talanki outlines how to upgrade Apigee OPDK to v4.53 while migrating to a supported OS (RHEL 8.x/9.x). This guide covers the "build-out" methodology, including multi-data center syncing, to ensure a stable, zero-downtime transitionRead the guide Cloud Run Worker Pools and CREMA: Powering Serverless AI at ScaleGoogle Cloud has announced the General Availability of Cloud Run worker pools, a new resource type designed specifically for pull-based, non-HTTP workloads. Unlike traditional Cloud Run services that scale based on request traffic, worker pools provide an "always-on" environment for background tasks like processing message queues or running large-scale AI inference. To support this, Google Cloud also open-sourced the Cloud Run External Metrics Autoscaler (CREMA). Built on KEDA, CREMA enables queue-aware autoscaling for worker pools, allowing them to dynamically scale based on external signals like Pub/Sub backlog or Kafka lag. Apigee Model Context Protocol (MCP) now Generally AvailableExpose enterprise APIs as MCP tools for agentic AI applications with the General Availability of MCP in Apigee. This update allows developers to transform APIs into AI-ready tools using OpenAPI Specifications, removing the need for local MCP servers or additional infrastructure. With managed endpoints and semantic search in API hub, you can now provide AI agents with secure, governed access to enterprise data at scale.Explore the MCP overview Apr 6 - Apr 10 Community TechTalk: Powering Retail Agents with ADK, UCP & Apigee XMove beyond basic chatbots to secure, transactional AI experiences. Join our Community TechTalk on April 16 to learn how Apigee X and Gemini build a "Trust Layer" for AI shopping assistants using UCP standards. We’ll demonstrate how to block prompt injections with Model Armor and implement cost governance via token limits to secure the path from discovery to purchase.Register for the TechTalk Implement multimodal capabilities in your AI agentsExplore three new reference architectures for building sophisticated multi-agent AI systems that can process and analyze multimodal data. To analyze disparate multimodal data and produce a high-confidence classification, see Classify multimodal data. To create a fluid conversational AI that processes audio and video streams in real time, see Enable live bidirectional multimodal streaming. To consolidate fragmented multimodal data into a searchable knowledge graph, see Multimodal GraphRAG resource orchestration. Automate SecOps workflows with an agentic AI systemTo accelerate incident response and reduce manual toil for your security team, you need a system that can automate remediation playbooks. Our new reference architecture helps you build an AI agent that orchestrates complex triage and investigation workflows across disparate security tools, such as SIEM, CSPM, and EDR, from a single interface. See the full guide to orchestrate security operations workflows. Mar 30 - Apr 3 ASEAN Webinar | April 30: Mastering Agentic Governance at Scale with GCPAs AI agents move from experimental pilots to core enterprise functions, governance is the critical next step. Join Google Cloud experts Shilpi Puri & Wely Lau for a webinar on April 30th at 11:00 AM SGT to learn how to architect a secure AI Management layer. We’ll explore developing governed MCP endpoints, managing tool access to enterprise data, and operationalizing AI with robust audit logs. The session includes a live demo of these frameworks in action on Google Cloud.RSVP here. Mar 23 - Mar 27 Turn your API sprawl into an agent-ready catalogAs organizations scale, APIs often become scattered across multiple gateways, creating "blind spots" that hinder AI adoption. To solve this, we’ve introduced two new capabilities for Apigee API hub: a new integration with API Gateway to automatically centralize API metadata into a single control plane, and a specification boost add-on (now in public preview). This add-on uses AI to enhance your API documentation with the precise examples and error codes that AI agents need to function reliably.Read the full blog post to get started. Webinar | April 16: AI Command & ControlAs AI agents move from experimental pilots to core enterprise functions, governance is the critical next step. Join Google Cloud expert Satyam Maloo for a webinar on April 16th at 11:00 AM IST to learn how to architect a secure AI Management layer. We’ll explore developing governed MCP endpoints, managing tool access to enterprise data, and operationalizing AI with robust audit logs. The session includes a live demo of these frameworks in action on Google Cloud.RSVP here. Modernizing and Decoupling Event Ingestion with ApigeeIn modern cloud-native architectures, decoupling producers from consumers is critical for building resilient systems. While Google Cloud Pub/Sub provides a scalable backbone, exposing it directly to external clients can introduce security and management overhead. This new guide explores how to leverage Apigee as an intelligent HTTP ingestion point. Learn how to handle security, mediation, and traffic control before messages reach your internal bus using the PublishMessage policy or Pub/Sub API.Read the full guide. Mar 16 - Mar 20 Gemini-powered Assistant in BigQuery Studio Gets Context-Aware UpgradesThe Gemini-powered assistant in BigQuery Studio has been transformed into a fully context-aware analytics partner, supporting your entire data lifecycle. The new capabilities include intelligent resource discovery, which uses Dataplex Universal Catalog search to find resources across projects and deep dive into metadata using natural language. You can now automate tasks, such as scheduling production-grade queries directly through the chat interface, and instantly troubleshoot long-running or failed jobs with root cause analysis and cost control auditing.Explore the full range of what the assistant can do. Mar 9 - Mar 13 Want to use Gemini to develop code and don't know where to start?This article includes a couple of examples of developing code with Gemini prompts; it identified changes that were needed to be made to get the code working. The article also refers to other examples that are available on github. Mar 2 - Mar 6 Introducing Gemini 3.1 Flash-Lite, our fastest and most cost-efficient Gemini 3 series model. Built for high-volume developer workloads at scale, 3.1 Flash-Lite delivers high quality for its price and model tier. Gemini 3.1 Flash-Lite can tackle tasks at scale, like high-volume translation and content moderation, where cost is a priority. And it can also handle more complex workloads where more in-depth reasoning is needed, like generating user interfaces and dashboards, creating simulations or following instructions. Starting today, 3.1 Flash-Lite is rolling out in preview to enterprises via Vertex AI and developers via the Gemini API in Google AI Studio. TechTalk: Implementing Device Authorization Grant (RFC 8628) for ApigeeLearn how to authorize "headless" devices like Smart TVs or AI agents that lack keyboards and browsers. Join our Community TechTalk on March 19 (5PM CET / 12PM EDT) to go under the hood of Apigee X/Hybrid. We’ll cover the real-world mechanics of state management, polling, and human-in-the-loop security patterns for devices and autonomous agents. Register for the TechTalk Feb 23 - Feb 27 Pro-level image generation gets faster and more accessible with Nano Banana 2Nano Banana 2 is our state-of-the-art image generation and editing model. It delivers Pro-level image generation and editing at the speed you expect from Flash — making the quality, reasoning, and world knowledge you loved about Nano Banana Pro more accessible. Learn more about the model here. The Intelligent Path to Compliance: Transforming Regulatory QC with Google CloudReducing "Refuse to File" (RTF) risks and submission cycle times is critical for life sciences leaders. Google Cloud’s Regulatory Submission Semantic QC Auditor leverages Gemini and RAG architecture to transform Quality Control from a manual burden into an active, intelligent workflow. By automating semantic cross-referencing, narrative coherence checks, and dynamic guidance-based auditing, this solution ensures rigorous accuracy and auditability. Operating within a secure GxP-ready environment, it empowers teams to detect subtle inconsistencies and generate remediation plans without sacrificing data privacy. Learn more. Stop typing, start interacting! The Gemini Live Agent Challenge is here. Build immersive agents that can help you see, hear, and speak using Gemini and Google Cloud. Compete for your share of $80,000+ in prizes and a trip to Google Cloud Next '26!Submissions are open from February 16, 2026 to March 16, 2026. Learn more and register at .devpost.com Feb 9 - Feb 13 Introducing Gemini 3.1 Pro on Google Cloud. 3.1 Pro is a noticeably smarter, more capable baseline for complex problem-solving. We’re shipping 3.1 Pro at scale, building upon our goal to help you transform your business for the agentic future. Learn more about the model’s capabilities here. Gemini 3.1 Pro is available starting today in preview in Vertex AI and Gemini Enterprise. Developers can access the model in preview via the Gemini API in Google AI Studio, Android Studio, Google Antigravity, and Gemini CLI. Automate Storage Compatibility with GKE Dynamic Default Storage ClassesManaging storage across mixed-generation VM clusters in GKE just got easier. With the new Dynamic Default Storage Class, Google Kubernetes Engine automatically selects between Persistent Disk (PD) and Hyperdisk based on a node's specific hardware compatibility. This abstraction eliminates the need for complex scheduling rules and manual pairing, ensuring your volumes "just work" regardless of the underlying infrastructure. By defining both variants in a single class, you reduce operational overhead while maintaining peak performance and cost-efficiency across your entire cluster.Explore automated disk type selection Community TechTalk: AI-Powered Apigee Development with strofa.ioJoin the Apigee community on February 26 for a deep dive into strofa.io. Guest speaker Denis Kalitviansky will demonstrate how this new AI-powered tool automates and orchestrates Apigee development, from local emulators to large-scale hybrid environments. Discover how to scale your API management and streamline team collaboration using the latest in AI-driven automation. Register now to reserve your spot. Jan 26 - Jan 30 Simplify API Governance with Native OpenAPI v3 SupportEliminate integration debt and accelerate deployment velocity with the General Availability of OpenAPI v3 (OASv3) support for API Gateway and Cloud Endpoints. You no longer need to downgrade modern specifications to OASv2. Instead, you can now define API contracts and enforce critical policies—including telemetry, quotas, and security—using native Google-specific extensions directly within your OASv3 files. This update ensures your APIs are secure by design while remaining fully compatible with the modern developer ecosystem and Google Cloud’s AI services.Get started with OpenAPI v3 on API Gateway and Cloud Endpoints. Accelerate API Testing with the New Open Source API TesterStart validating your APIs with API Tester, a simple, YAML-based Test Driven Development (TDD) framework. Designed for the Apigee community, this tool allows you to write human-readable tests, run them instantly via a web client or CLI, and perform deep unit testing on Apigee proxies. With native support for JSONPath assertions and Apigee shared flows, you can verify everything from payload data to internal variables like proxy.basepath without leaving your terminal.Explore the API Tester guide and start testing your proxies today. Secure Sensitive Data with Kubernetes Secrets in Apigee hybridEnhance security in Apigee hybrid by accessing Kubernetes Secrets directly within your API proxies. This hybrid-exclusive feature keeps sensitive credentials within your cluster boundary and prevents replication to the management plane. It supports strict separation of duties: operators manage secrets via kubectl, while developers reference them as secure flow variables—ideal for high-compliance and GitOps workflows.Implement Kubernetes Secrets in your hybrid proxies. See the Console in a Whole New Light: Dark Mode is Now Generally Available in Google CloudElevate your cloud management workflow with Dark Mode, now generally available in the Google Cloud console. We have delivered a modern, cohesive, and accessible experience reimagined for maximum comfort and productivity—especially during extended working hours and low-light environments. Dark Mode can be enabled automatically based on your operating system's preference, or manually through the Settings -> Appearance menu.Switch to Dark Mode today to enjoy a modern, comfortable, and productive environment! Apigee X Networking: PSC or VPC Peering?Deciding how to connect Apigee X? Watch this video to compare Private Service Connect and VPC Peering. We break down northbound and southbound routing, IP consumption, and how to reach targets on-prem or in the cloud. Learn to simplify your architecture and avoid common networking "gotchas" for a smoother deployment.Watch the video. Jan 19 - Jan 23 Bridge the Gap: Excel-to-API Conversion in Apigee PortalsGive your customers more ways to connect! This new article by Tyler Ayers explores how to extend the Apigee Integrated Portal to support direct Excel file uploads. By leveraging SheetJS and custom portal scripts, you can enable users to upload spreadsheets, preview data, and submit it directly to your APIs, all without writing a single line of integration code themselves. It’s a powerful way to simplify onboarding for those who aren't yet API-ready.Learn how to build it. Elevate your applications with Firestore’s new advanced query engineWe have fundamentally reimagined Firestore with pipeline operations for Enterprise edition. Experience a powerful new engine featuring over a hundred new query features, index-less queries, new index types, and observability tooling to improve query performance. Seamlessly migrate using built-in tools and leverage Firestore’s existing differentiated serverless foundation, virtually unlimited scale, and industry-leading SLA. Join a community of 600K developers to craft expressive applications that maximize the benefits of rich queryability, real-time listen queries, robust offline caching, and cutting-edge AI-assistive coding integrations.Learn more about Firestore pipeline operations.
Changing the game: How Google uses agentic AI to secure hundreds of millions of lines of code
AI is accelerating software development at an unprecedented pace. But as code generation scales, so do the challenges of securing the code, especially emerging AI-based vulnerability exploitations. To meet these challenges, the Google AI and Infrastructure team is transforming how we approach security. In this article, we discuss new AI-native agentic methods that we’ve developed that systematically embed high-precision, pervasive vulnerability scanning and patching directly into Google’s software development lifecycle. By continuously scanning every code change across hundreds of millions of lines of code that we deploy onto our infrastructure, we are preventing hundreds of vulnerabilities per month from ever reaching our code base or production, defending our global network, AI infrastructure and our users. Solution architecture and implementation Pervasive pre-submit agentic scanning: security as part of ongoing software development Traditionally, the technology industry relies on large one-off security scans that are slow and lack sufficient context. As a result, they often find vulnerabilities too late. Our approach instead focuses on pre-submit scanning, where we evaluate each code check-in (across every layer of the stack) in real-time using AI agents. By integrating the pre-submit scan into the tools developers already use, security becomes a continuous routine process, similar to rule checkers, readability reviews or other software development tools. Also, from an AI perspective, scanning each individual code change requires much less context than performing a large one-off scan, significantly improving the scan’s effectiveness. The importance of localized threat models For this initiative, we evolved Mantis, our open-source multi-agent review harness, to increase the precision of our security agents by matching them with a cohort of robust localized threat models. Rather than relying on static decoupled documents, the threat models use live codebase metadata. The scanning agent improves its accuracy further using a dependence call graph across packages and libraries to expand and refine its threat model context. Making threat models part of our ongoing vulnerability scanning encourages developers to continuously update threats and dependencies, keeping the models up-to-date. Using localized and precise threat model data translates to dramatic accuracy improvements, bringing our false-positive rates down to 3% in some cases. Specialized triage agents speed up development Vulnerability scanning as part of code check-in requires it to respond quickly to the developer or agents generating the code, so as not to impede engineering productivity. To get responses with low latency, we run a two-step validation process. First, we run a quick lightweight scan that validates its findings against a specialized triage agent. This agent programmatically checks the actual structure of the code (using abstract syntax tree parsing, call-graph traversal, and pre-indexed domain safety rules) to prove that the vulnerable path is actually reachable by an attacker. This agent gets over 92% precision and completes its work in less than a minute. Then, a post-submit scan as part of nightly integration testing serves as a second layer of defense, using off-peak cycles to test for vulnerabilities that may have been introduced across multiple changes. Bug fix agents close the loop Finding vulnerabilities is only half the battle. The last component of our solution is an automated bug-fix agent that uses the scan results and generated proofs (snippet of code that demonstrates how the vulnerability is exercised) to autonomously construct precise fixes that are consistent with our internal coding standards. The agent submits the fixes for human review as part of the original change request’s review, further reducing the time between detection and resolution. Learnings and call to action Embedding continuous scanning directly into the software development lifecycle has been a game changer at Google; its suggestions are widely adopted, and it’s prevented a multitude of vulnerabilities from being introduced into the codebase. But any organization wishing to improve security can adopt a similar AI-native approach, following these principles: Keep systems separate: To prevent bias, keep the harnesses, rules, and context for each of your development, scanning, triage agents separate. Pair lightweight AI scans with deterministic, structural validation to drive down latency and improve accuracy. Use context wisely: Feed your agents your existing threat models. Precise context is the answer to reducing false positives, and up-to-date threat models set a high floor on a team's security posture by improving the rate of true positives in presubmit scanning. Build a good harness: While the choice of the underlying model is important, using a multi-agent harness can have substantial impact, by helping compensate for variability in model choice. Automate the fix: Use agents to also propose human-in-the-loop fixes, to further reduce time-to-resolution. If you want to get started on your own AI-native security transformation, Mantis is now available as open source for you to use and benefit from. You can also learn more about the fundamentals of cybersecurity and the other platforms that power this agentic pipeline: Google Cloud, Gemini Enterprise and Gemini models running on Trillium and Ironwood TPUs. And you can get inspiration from how agentic vulnerability scanning and remediation defends Google Cloud customers as an integral part of Google Cloud’s secure software development lifecycle (SDLC) effort. With special recognition to critical team members who made this delivery possible: Stella Voutsina (Lead Program Manager), Yulong Zhang (Senior Staff Security Engineer, Mantis), and Nick Galloway (Staff Security Engineer, Mantis).
Amid Voicing Non-Stop Concerns About AI Safety, Anthropic Sets Up Physical Biology Lab
Anthropic, the AI company whose CEO has spent the past two weeks warning that artificial intelligence could spiral out of human control, has... The post Amid Voicing Non-Stop Concerns About AI Safety, Anthropic Sets Up Physical Biology Lab appeared first on OfficeChai.
AI training built on fair use looks shaky when the companies' own people call it "astonishing theft"
Internal emails and sworn testimony undercut OpenAI and Microsoft's fair use defense. A Microsoft director described the practice as the "largest theft of labor in human history," while OpenAI's head of ChatGPT wrote that the products "are largely substitutive, period." The article AI training built on fair use looks shaky when the companies' own people call it "astonishing theft" appeared first on The Decoder.
Deploy Hugging Face models on Amazon Sage Maker AI with coding agents
Deploy production-ready Hugging Face models on Amazon SageMaker AI using six open-source agent skills. Point a coding agent at a model and get back a real-time endpoint with the right serving container, autoscaling, Amazon CloudWatch alarms, and a verified teardown path.
Visible chains of thought are a safety advantage for AI, but that transparency is slipping away
AI models think out loud today, but Google Deepmind says that transparency is at risk. The article Visible chains of thought are a safety advantage for AI, but that transparency is slipping away appeared first on The Decoder.
Anthropic wants you to know Claude leads a quarter of its research, but "lead" doesn't mean what you think
For the first time, Anthropic is releasing metrics on how it builds its own AI. Claude already "leads" 26 percent of the work on future models, up from under one percent in February. But the underlying scale is fuzzy, the scoring comes from Claude itself, and "lead" means less than it sounds. The article Anthropic wants you to know Claude leads a quarter of its research, but "lead" doesn't mean what you think appeared first on The Decoder.
Security researchers used Anthropic’s Claude to exploit vulnerabilities in OpenAI’s systems, taking over employee accounts and gaining access to an internal code repository before reporting the flaws.
Open AI takes aim at the legal market with Astra for Law
OpenAI has introduced Astra for Law, a version of its GPT-6 Astra model built for legal work. The article OpenAI takes aim at the legal market with Astra for Law appeared first on The Decoder.
Open-weight models now handle a majority of tokens on Vercel’s AI Gateway. But Anthropic still takes 64% of the spend.
The trend is clear: open-weight models are taking an increasingly large bite out of production AI usage. On Monday, The The post Open-weight models now handle a majority of tokens on Vercel’s AI Gateway. But Anthropic still takes 64% of the spend. appeared first on The New Stack.
The 700-Agent Swarm: What Open AI And Hugging Face Taught Business Leaders
A swarm of AI agents coordinated a real attack without human direction. Here's what business leaders need to know — and why adaptation, not tools, is the answer.